Qwen-Audio-3.0-Realtime Function Calling
Qwen-Audio-3.0-Realtime Function Calling shows how builders can design tool-using voice agents with streaming sessions.
Benchmark Inkling for Production Agents
Benchmark Inkling with your own agent tasks, multimodal inputs, long-context cases, latency, memory, cost, and fine-tuning gains.
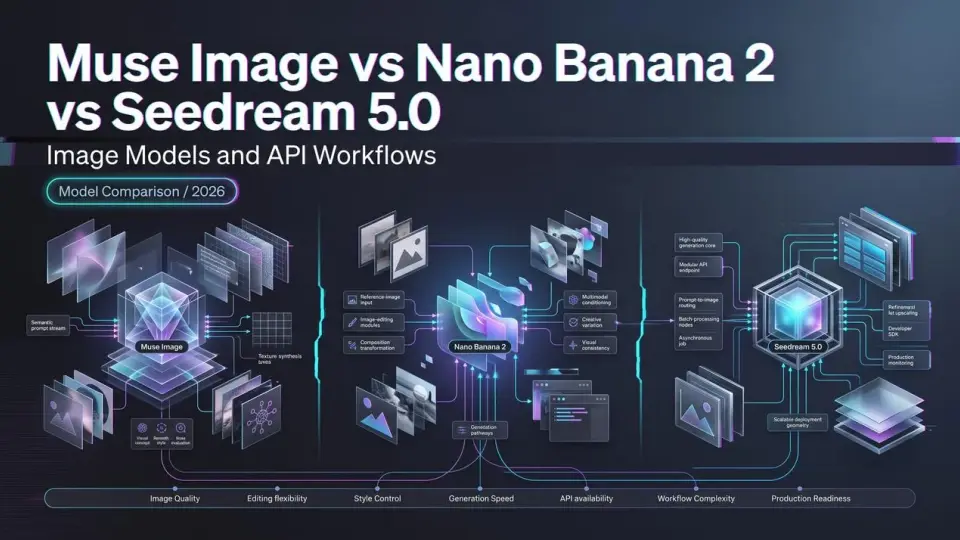
Muse Image vs Nano Banana 2 vs Seedream 5.0
Muse Image vs Nano Banana and Seedream for social context, editing, references, and production image workflows.
pxpipe Models for Fable 5 and GPT-5.6
pxpipe models guide for teams checking which LLMs can read dense renders, compressed context, and multimodal inputs reliably.
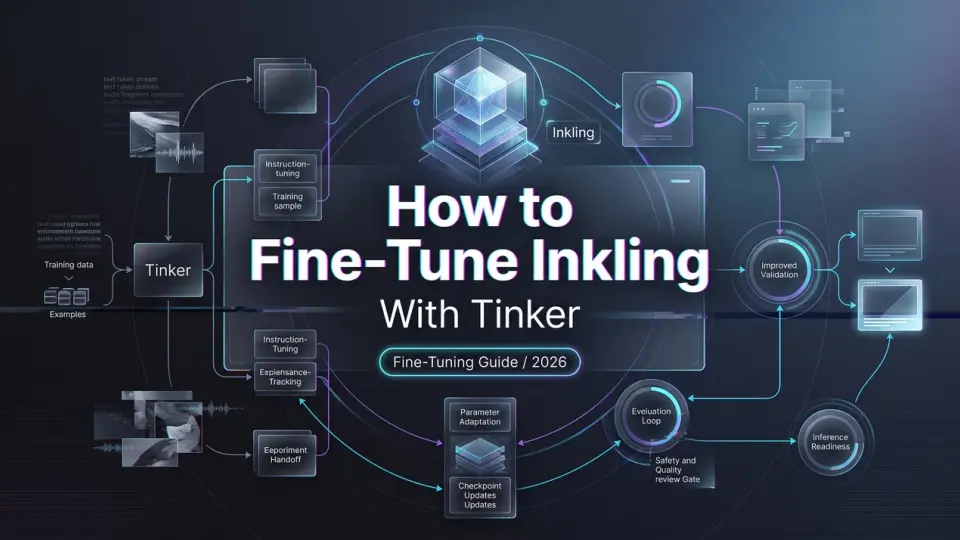
How to Fine-Tune Inkling With Tinker
Fine-tune Inkling with Tinker by planning data, LoRA adapters, sampling, evaluation, saved states, and deployment boundaries.
Flux 3 vs Seedance 2.0: What We Know, What We're Guessing, and What Ships Today
An honest look at the unreleased Flux 3 against Seedance 2.0, the multimodal video model you can call right now on WaveSpeedAI.
Krea 2 vs FLUX: Style Control and Workflows
Krea 2 vs FLUX comparison for teams evaluating style control, workflow fit, LoRA ecosystem, review loops, and production stability.
Nano Banana 2 to Gemini Omni Flash Pipeline
Nano Banana 2 pipeline guide for teams turning reference images into video workflows with Gemini Omni Flash, Flow, or other video models.
How to Deploy Inkling: vLLM and SGLang
Deploy Inkling model only after planning formats, vLLM, SGLang, quantization, GPU memory, KV cache, throughput, and serving limits.
Krea 2 ComfyUI Workflow: RAW, Turbo, LoRA
Krea 2 ComfyUI workflow guide for Raw, Turbo, LoRA files, FP8 variants, GGUF options, and reproducible image pipelines.
Wan-Dancer API Deployment for Production Workflows
Wan-Dancer API deployment requires model serving, uploads, GPU scheduling, async jobs, storage, callbacks, retries, and production safeguards.
GPT-Live vs GPT-Realtime-2
GPT-Live vs GPT-Realtime-2 clarifies ChatGPT voice experience versus developer realtime API for production voice teams.