Avatar Lipsync Models
WaveSpeedAI's AI Avatars delivers lifelike virtual characters with advanced lip sync and realistic expressions.
Our selection
bytedance/seedance-2.5/talking-avatar
Seedance 2.5 Talking Avatar animates a portrait image from an audio recording to generate natural talking-avatar videos in 480P or 720P, processing up to the first 120 seconds of audio for digital human, presenter, dubbing, and avatar workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
All models
49 models
bytedance/seedance-2.5/talking-avatar
Seedance 2.5 Talking Avatar animates a portrait image from an audio recording to generate natural talking-avatar videos in 480P or 720P, processing up to the first 120 seconds of audio for digital human, presenter, dubbing, and avatar workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk/multi
InfiniteTalk Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk
InfiniteTalk Image-to-Video converts a single photo and audio track into long-form audio-driven talking or singing avatar videos, supporting up to 10 minutes, 720P output, natural lip sync, expressive motion, and digital human video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
heygen/avatar-v/digital-twin
HeyGen Avatar V Digital Twin is a fast AI avatar video generation model that creates natural digital twin videos from text or audio with lip-sync, optional captions, background removal, and MP4/WebM output. Ready-to-use REST inference API for digital humans, virtual presenters, product explainers, marketing videos, training content, social media clips, and professional avatar video workflows with simple integration, no coldstarts, and affordable pricing.
heygen/avatar-v
HeyGen Avatar V creates high-quality talking-avatar videos from a selected avatar and speech audio, with optional backgrounds and up to 4K output for presentations, training videos, product introductions, marketing content, and digital human workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
heygen/avatar-iv
HeyGen Avatar IV turns portrait images and speech recordings into expressive talking-avatar videos with expression control, optional backgrounds, and up to 1080P output for digital humans, virtual presenters, personalized content, and avatar video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
pruna-ai/p-video-2-pro/avatar
Pruna P-Video-2-Pro Avatar creates talking-avatar videos from a portrait image and uploaded speech audio, making it suitable for digital humans, presenters, dubbing, and avatar video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
pruna-ai/p-video/avatar
Pruna AI P-Video Avatar is a fast AI avatar video generation model that creates high-quality avatar videos for digital humans, talking characters, social media content, marketing creatives, virtual presenters, and AI video workflows. Ready-to-use REST inference API with simple integration, no coldstarts, and affordable pricing.
wavespeed-ai/music-video-generator
AI Music Video Generator transforms audio + a single photo into a full music video with cinematic camera angles, smooth transitions, and perfect lip sync. Up to 10 minutes, 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk/video-to-video
Audio-driven InfiniteTalk turns one video plus audio into realistic talking or singing videos with lip-sync in 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-3/avatar
Sync Lipsync 3 Avatar turns a single still image and an input audio track into a lip-synced talking character video, with natural mouth movement, facial animation, and stable avatar performance. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/longcat-avatar-1.5/multi
LongCat Avatar 1.5 Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p, capped at 64 seconds per clip. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/longcat-avatar-1.5
LongCat Avatar 1.5 is the upgraded LongCat Avatar with sharper lip sync and faster generation. Converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), capped at 64 seconds per clip, 720p tier $0.40/5s. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast
InfiniteTalk fast converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), up to 10 minutes. Ready-to-use REST API, no coldstarts, affordable pricing.
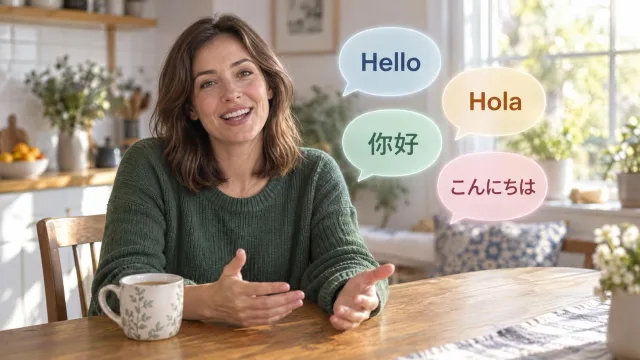
wavespeed-ai/ai-video-editor/video-translator
AI Video Translator dubs any video into 28 languages: every speaker keeps a voice that matches their own, the original music and sound effects stay under the dub, and the timing follows the picture. Translated subtitles come as an SRT file with every result. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/ai-video-editor/talking-head
AI Video Editor Talking Head cleans up a talking-to-camera video: it removes filler words, false starts, repeats and dead air, keeps the speaker framed, and burns in accurate word-timed captions. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

kwaivgi/kling-lipsync/audio-to-video
Kling LipSync converts audio into talking head video by generating lifelike lip movements perfectly synced to the input audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v2-ai-avatar-standard
Kling AI Avatar generates high-quality AI avatar videos for profiles, intros, and social content, delivering clean detail and cinematic motion with reliable prompt adherence. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast/multi
InfiniteTalk fast multi converts a single image and two audio inputs into multi-character talking or singing videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/infinitetalk/video-to-video-multi
InfiniteTalk Video-to-Video Multi converts a video and two audio inputs into multi-character talking or singing videos at up to 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v2-ai-avatar-pro
Kling V2 AI Avatar Pro generates high-quality AI avatar videos with clean detail, stable motion, and strong identity consistency—ideal for profiles, intros, and social content. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast/video-to-video
Audio-driven infinitetalk-fast turns one video plus audio into realistic talking or singing videos with lip-sync. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v1-ai-avatar-standard
Kling AI Avatar produces stunning AI-generated video avatars for digital identity and content creation, with on-demand video billed at $0.25 per 5 seconds. Ready-to-use REST API, no coldstarts, affordable pricing.

wavespeed-ai/infinitetalk-fast/video-to-video-multi
InfiniteTalk fast video-to-video multi converts a video and two audio inputs into multi-character talking or singing videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v1-ai-avatar-pro
Kling AI Avatar Pro converts audio into talking video portraits; pricing is $1 for the first 5s then $0.20/s up to 600s. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
veed/lipsync-v2
VEED Lipsync V2 generates production-quality lip-synced videos from a source video and a replacement audio track, matching mouth movements to the new audio for dubbing, localization, creator content, and talking-video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/omni-human-2.0
OmniHuman 2.0 Talking Avatar turns a portrait image and audio recording into a lifelike talking-avatar video, making it suitable for digital humans, virtual presenters, dubbing, social content, and avatar video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/longcat-avatar
LongCat Avatar produces super-realistic, lip-synchronized long video generation with natural dynamics and consistent identity. Converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), up to 2 minutes, 720p tier $0.40/5s. Ready-to-use REST API, no coldstarts, affordable pricing.
bytedance/latentsync
LatentSync combines Stable Diffusion and TREPA for high-res end-to-end lip-sync, delivering precise, realistic mouth motions in generated videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/soulx-flashhead
SoulX FlashHead enables real-time streaming talking head video generation from portrait image and audio with ultra-fast 96 FPS performance. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/skyreels-v3/talking-avatar
SkyReels V3 Talking Avatar is a 19B-parameter multimodal model that generates talking avatars from portrait and audio with precise lip sync, supporting up to 20 seconds at 720p resolution. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/ltx-2.3/lipsync
LTX-2.3 Lipsync generates talking head videos from audio with synchronized lip movements and natural facial expressions. Built on DiT-based architecture with improved audio-visual alignment quality. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
heygen/video-translate
HeyGen Video Translate: translate videos into 70+ languages and 175+ dialects with voice preservation and lip sync. Choose Speed at $0.04/sec or Precision at $0.08/sec. Supports videos up to 120 seconds.
sync/react-1
Sync React-1 is a production-grade video-to-video lip-sync model. It maps any speech track to a target face, producing phoneme-accurate visemes and smooth timing while preserving identity, head pose, lighting, and background. Supports emotion and intensity control, multilingual speech, and long takes for talking-head content. Built for stable production use with a ready-to-use REST API, no cold starts, and predictable pricing.
wavespeed-ai/hunyuan-avatar
Hunyuan Avatar creates audio-driven talking or singing videos from one image + audio, in 480p/720p up to 120s (starts at $0.15/5s). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/multitalk
MultiTalk converts one image and audio into audio-driven talking/singing videos (Image-to-Video), supporting up to 10 minutes. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
veed/lipsync
Generate realistic lip-sync animations from audio with high-quality synchronization using Veed LipSync; $0.15 per 5s of video. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

pixverse/lipsync
PixVerse LipSync converts audio into realistic lip-sync animations with advanced algorithms for precise mouth movements and timing for video avatars. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/ltx-2-19b/lipsync
LTX-2 Lipsync generates synchronized talking head videos from a reference image and audio input. Powered by the 19B DiT architecture, it produces high-fidelity lip-synced videos with natural head movements. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-3
Sync Lipsync 3 synchronizes lip movements in any video to supplied audio using zero-shot lip-sync technology. Supports multiple sync modes for handling duration mismatches, works with live-action, 3D characters, and AI-generated avatars. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

bytedance/avatar-omni-human-1.5
OmniHuman 1.5 converts audio and visual cues into lifelike avatar animations for virtual humans, storytelling, and interactive agents. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/latentsync
LatentSync synchronizes video and audio inputs to generate seamless synchronized content. Perfect for lip-syncing, audio dubbing, and video-audio alignment tasks.
sync/lipsync-2
Sync Lipsync-2 synchronizes lip movements in any video to supplied audio, enabling realistic mouth alignment for films, podcasts, games, or animations. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-2-pro
Lipsync-2-pro creates studio-grade lip synchronization for video-to-video editing in minutes, not weeks. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/wan-2.2/speech-to-video
Wan-2.2-S2V turns images and speech into high-fidelity videos with realistic face and body motion; supports up to 10-minute clips in 480p, from $0.15/5s. Ready-to-use REST API, no coldstarts, affordable pricing.

wavespeed-ai/wan-2.1/multitalk
MultiTalk (WAN 2.1) is an audio-driven AI that turns a single image and audio into talking or singing conversational videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
veed/fabric-1.0
VEED Fabric 1.0 turns one image into dynamic, talking videos and AI avatars in 480p or 720p (starts at $0.35/5s 480p, $0.7/5s 720p). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/lipsync/audio-to-video
LipSync turns audio into lifelike talking videos by generating precise lip movements fully synced to input audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/avatar-omni-human
OmniHuman turns a single portrait photo into avatar video with lifelike motion and expressions ($0.12/sec). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Avatar Lipsync Models API — pricing & performance
Run any model in the Avatar Lipsync Models collection through a single REST API. Pay per generation — no subscriptions, no minimums — with industry-leading latency on a 99.9% uptime infrastructure.
Why run Avatar Lipsync Models on WaveSpeedAI
Transparent pricing
Per-call pricing for every Avatar Lipsync Models model. The price is listed on each model page — no platform fees on top.
Optimized for low latency
Most Avatar Lipsync Models image models complete in under 2 seconds. Video and 3D models run several times faster than self-hosted alternatives.
99.9% uptime
Multi-region failover and automatic retries keep your production traffic online — even during provider outages.
Frequently asked questions
How much does the Avatar Lipsync Models API cost?+
Each model has its own per-call price listed on the model page. We bill per successful generation, with no subscription fees or minimums.
How fast are Avatar Lipsync Models models on WaveSpeedAI?+
Image models in this collection typically complete in under 2 seconds. Video and 3D models depend on duration and resolution but are usually several times faster than self-hosted runs.
Can I try the API without a credit card?+
Eligible new accounts may receive $1 in promotional credits to try Avatar Lipsync Models models without a credit card. Trial credits are not guaranteed for every signup; check your account balance before generating.
Are there rate limits?+
Standard accounts have generous concurrent-job limits. Enterprise plans offer custom RPM, higher concurrency, and dedicated capacity — contact sales for details.