MiniMax H3 API
MiniMax H3 API 支持电影感的文生视频、图生视频和参考生视频,具备原生立体声音频、出色的运动质量、主体一致性和场景连贯性。可在 WaveSpeed 基础设施上运行开放权重版本,或通过同一个 WaveSpeedAI API 调用 MiniMax 官方端点。
根据文本提示词、静态图像或视觉参考生成电影感 AI 视频。推荐的开放权重部署(wavespeed-ai/minimax-h3)运行在 WaveSpeed 基础设施上,可输出连贯的 480p/540p/768p/1080p 视频,带原生立体声音频,时长 3-15 秒,按秒计费,价格实惠;同一系列中也提供 MiniMax 官方端点。
概览
关于 MiniMax H3 API
MiniMax H3 能做什么、它在 MiniMax 模型阵容中的定位,以及团队选择它的原因。
MiniMax H3 是 MiniMax 推出的视频生成模型,可通过 WaveSpeedAI REST API 使用。MiniMax H3 API 支持电影感的文生视频、图生视频和参考生视频,具备原生立体声音频、出色的运动质量、主体一致性和场景连贯性。可在 WaveSpeed 基础设施上运行开放权重版本,或通过同一个 WaveSpeedAI API 调用 MiniMax 官方端点。
根据文本提示词、静态图像或视觉参考生成电影感 AI 视频。推荐的开放权重部署(wavespeed-ai/minimax-h3)运行在 WaveSpeed 基础设施上,可输出连贯的 480p/540p/768p/1080p 视频,带原生立体声音频,时长 3-15 秒,按秒计费,价格实惠;同一系列中也提供 MiniMax 官方端点。
WaveSpeedAI 上的 MiniMax H3 系列提供 20 个 REST 端点,涵盖 Motion-Control, Image-To-Video, Reference-To-Video, Image-To-Image, Text-To-Image, Video-To-Video, Video-Extend, Text-To-Video 个工作流。每个变体都有各自的定价、参数选项和示例输出——请选择与你的输入模态和生产约束相匹配的那一个,或使用同一个 API 密钥调用多个变体,组合成多步骤流水线。
使用与 WaveSpeedAI 上其他 1,000 多个 AI 模型相同的 API 密钥、账单账户和速率限制来运行 MiniMax H3。无需单独对接供应商,无需各家 SDK,也无需应对各家不同的速率限制——一次集成即可覆盖从文生图、文生视频到音频合成、3D 生成、放大和编辑的全部能力。
规格
MiniMax H3 API 的能力与发布状态
开发者在选择 API 之前会搜索的模型细节:可用性、预期输出时长、参考素材支持情况,以及当前可用的在线替代方案。
文生视频
提示词驱动生成
使用 wavespeed-ai/minimax-h3/text-to-video,把书面创意说明变成连贯的 480p/540p/768p/1080p 视频,带原生立体声音频,时长 3-15 秒,画幅比例灵活。
图生视频
让静态图像动起来
使用 wavespeed-ai/minimax-h3/image-to-video,将首帧图像(可选尾帧)制作成连贯的视频,带原生立体声音频,并把主体、构图和美术风格延续到动态中。
参考生视频
引导身份与风格
当主体、角色身份或风格必须保持一致时,使用 wavespeed-ai/minimax-h3/reference-to-video,最多可用 9 张参考图像、3 段参考视频和 3 段参考音频来引导生成。
API 集成
统一的 WaveSpeedAI 工作流
使用 WaveSpeedAI API 密钥提交 H3 预测,通过标准预测生命周期跟踪每个请求,并从结果响应中获取生成的视频——WaveSpeed 托管端点和 MiniMax 官方端点的工作流完全相同。
端点
全部 MiniMax H3 API 端点
WaveSpeedAI 现已提供 20 个 MiniMax H3 端点——请选择适合你工作流的变体。
Minimax H3 Controlnet Union
MiniMax H3 Open Weights ControlNet Union generates a new video that follows the motion and composition of a source video. Pose, depth, edges, lines, scribble or grayscale structure is extracted from the source automatically and guides the output, optionally with reference images for the subject or style, with native stereo audio generated in the same pass. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Singularity Image To Video Lora
MiniMax H3 Singularity Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Singularity Image To Video
MiniMax H3 Singularity Open Weights Image-to-Video animates a first-frame image, with optional last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Singularity Reference To Video Lora
MiniMax H3 Singularity Open Weights Reference to Video with custom LoRA support generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
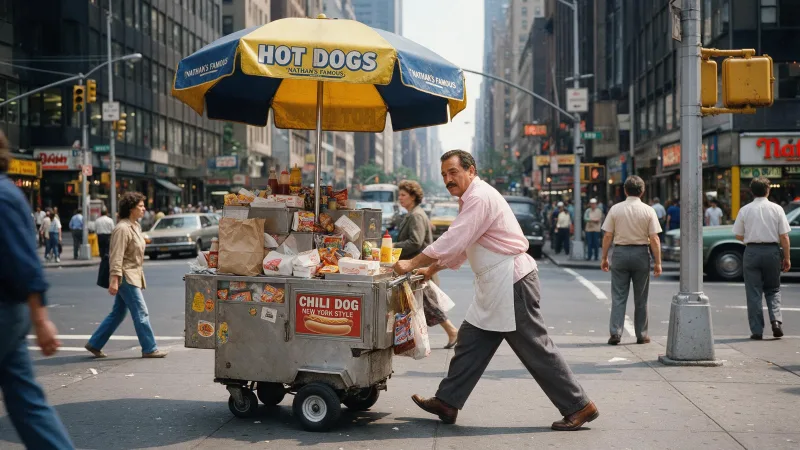
Minimax H3 Singularity Reference To Video
MiniMax H3 Singularity Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation on WaveSpeedAI infrastructure. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
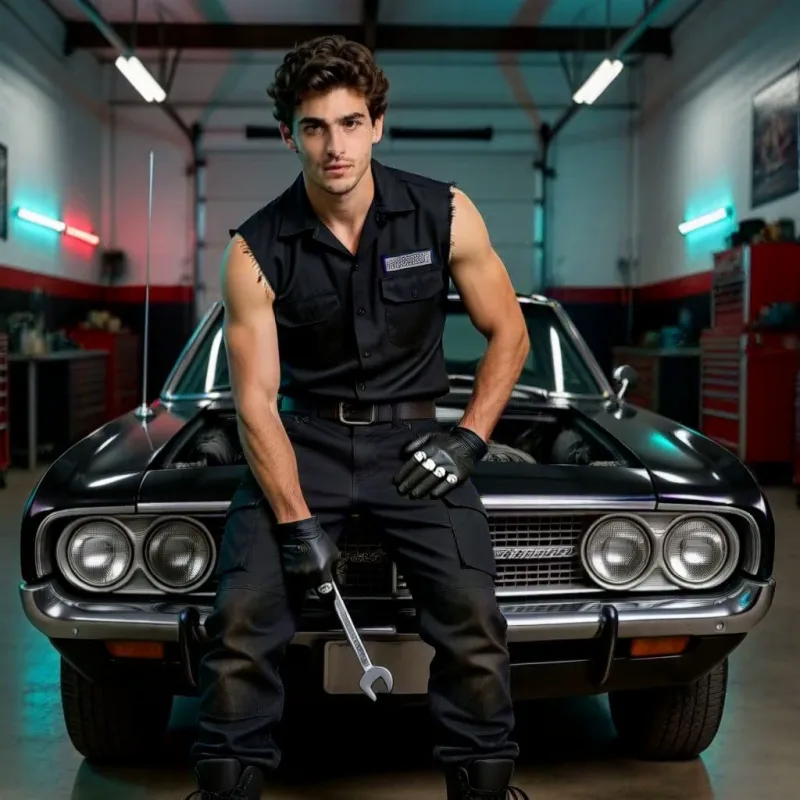
Minimax H3 Image Edit Lora
MiniMax H3 Open Weights Image Edit re-renders a subject from up to 9 reference images into a new scene, outfit or style from a text instruction, preserving identity at 1K or 2K resolution. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
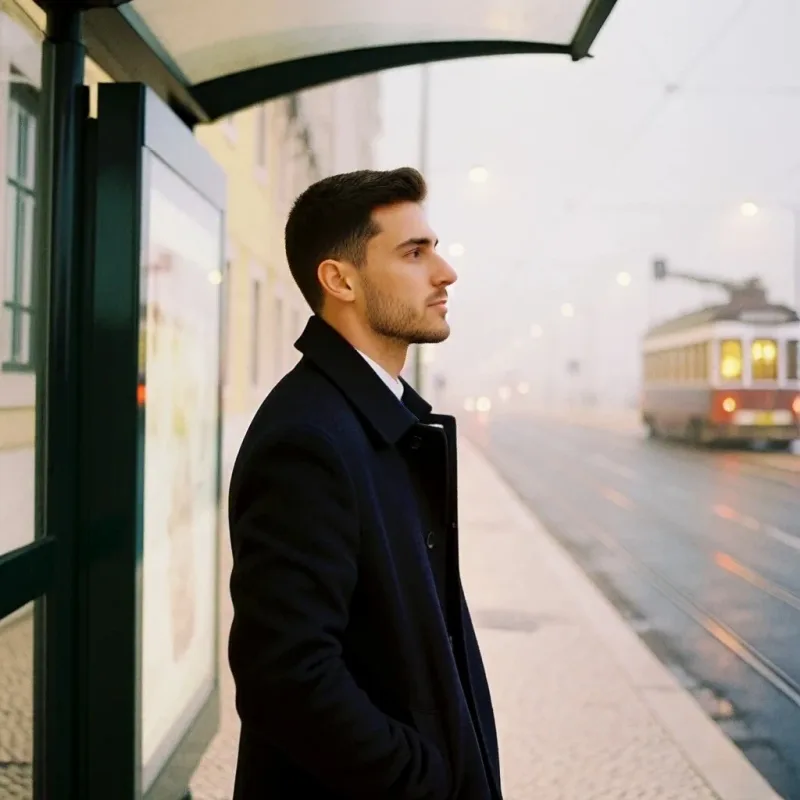
Minimax H3 Text To Image Lora
MiniMax H3 Open Weights Text-to-Image generates photorealistic, cinema-grade stills from a text prompt at 1K or 2K resolution with fifteen aspect ratios. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
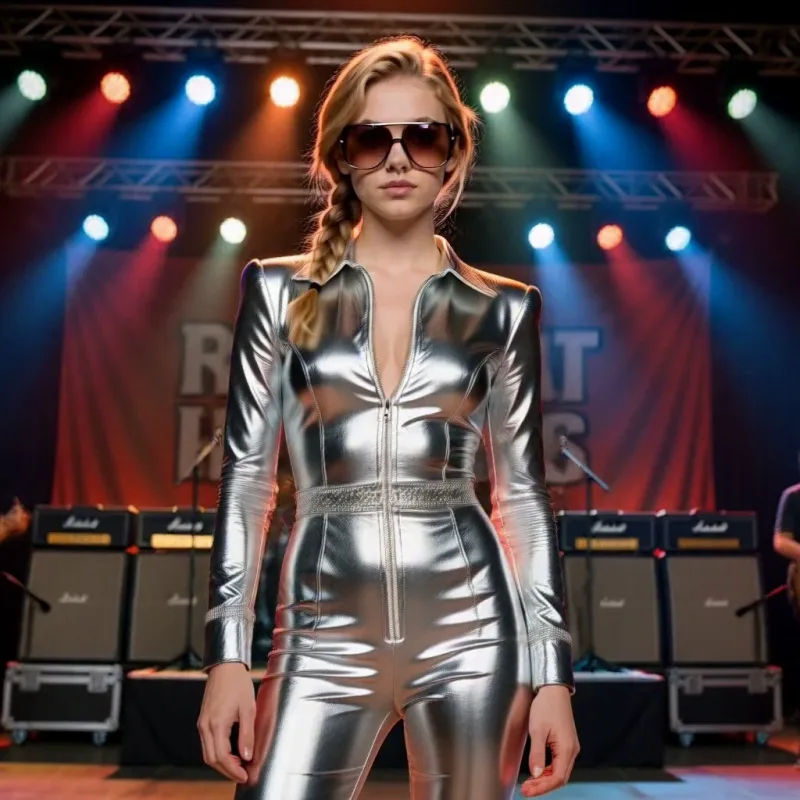
Minimax H3 Image Edit
MiniMax H3 Open Weights Image Edit re-renders a subject from up to 9 reference images into a new scene, outfit or style from a text instruction, preserving identity at 1K or 2K resolution. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Minimax H3 Text To Image
MiniMax H3 Open Weights Text-to-Image generates photorealistic, cinema-grade stills from a text prompt at 1K or 2K resolution with fifteen aspect ratios. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Minimax H3 Video Edit
MiniMax H3 Open Weights Video-Edit edits an input video from a natural-language prompt. The input video drives subject identity, composition, and motion while the model rewrites lighting, style, weather, environment, or specific elements as instructed, with native stereo audio generated in the same pass. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Video Extend
MiniMax H3 Open Weights Video-Extend appends a new cinematic continuation to an existing video. A fresh segment with native stereo audio is generated from the input video's last frame and a natural-language prompt, then the original and new segment are concatenated into a single output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Reference To Video Lora
MiniMax H3 Open Weights Reference to Video with custom LoRA support generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Reference To Video
MiniMax H3 Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation on WaveSpeedAI infrastructure. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
H3 Reference To Video
MiniMax H3 Reference to Video generates coherent 2K videos from natural-language prompts and multimodal references, including images, videos, and audio, guiding subject consistency, motion, timing, visual style, and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
H3 Image To Video
MiniMax H3 Image to Video animates a first-frame image into a coherent 2K video, with natural-language motion instructions and optional last-frame control for consistent motion, scene continuity, and cinematic video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
H3 Text To Video
MiniMax H3 Text to Video generates coherent 2K videos from text prompts, with flexible 5-15 second duration and adaptive or custom aspect ratios for cinematic scenes, creative videos, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
示例
看看 MiniMax H3 的实际效果
由 MiniMax H3 API 生成的真实输出。悬停在任意视频上即可预览,点击可打开全尺寸查看器。
使用方法
如何使用 MiniMax H3 API
从注册到完成一次生成,只需四步。完整的 Python、Node.js 和 cURL 示例见下方的 API 部分。
- 01
获取 API 密钥
注册 WaveSpeedAI 账号,并从控制台复制你的 API 密钥。新账号附带免费体验额度——足够在开始计费前把 Playground 运行几十次。
- 02
提交预测
把你的输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video。端点会立即返回预测 ID——生成是异步的,因此推理期间你无需保持连接。
- 03
轮询完成状态
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result。状态为 completed 时返回输出;状态为 failed、cancelled、timeout 或 deleted 时以错误终止;其他任何状态都继续轮询。
- 04
读取输出 URL
状态变为 "completed" 后,从 data.outputs[0] 读取 URL。该 URL 指向 WaveSpeedAI CDN 上你生成的媒体——具体是图片、视频、音频还是 3D 文件,取决于你调用的 MiniMax H3 变体。
应用场景
用 MiniMax H3 可以构建什么
开发者和创作者使用 MiniMax H3 API 的常见工作流。
文生视频,实现原创构想
用 wavespeed-ai/minimax-h3/text-to-video 把提示词变成原创的电影感场景——输出连贯的 480p/540p/768p/1080p 视频,带原生立体声音频,画幅比例灵活。适用于概念可视化、故事讲述、活动创意,以及无需从现有素材起步的镜头。
图生视频,用于产品展示
为产品摄影、活动静态图、主视觉或角色图像添加动态,同时保留素材的视觉风格。适合产品亮相、社交广告和以动态为先的落地页内容。
参考生视频,保持主体一致
最多可使用 9 张参考图像、3 段参考视频和 3 段参考音频,来引导角色身份、主体外观、场景设计或风格。参考生视频是 H3 中用于系列角色、品牌视觉和关联创意素材的工作流。
社交媒体与广告创意
为营销活动、新品发布、社交信息流和效果营销生成短视频创意。无论从文本、成品静态图还是已确认的视觉参考出发,都无需更换 API 平台。
角色场景与视觉叙事
根据素材类型选择合适的端点,创作以角色为主的场景、故事节点、氛围短片和预演画面:新场景用文本,动画化用图像,需要更强连贯性时用参考素材。
可扩展的 AI 视频生成流水线
通过 WaveSpeedAI 将 MiniMax H3 集成到应用和自动化创意工作流中。H3 的三种生成模式使用同一个 API 密钥和一致的预测生命周期。
技巧
MiniMax H3 提示词技巧
让 MiniMax H3 输出更好结果的实用建议——总结自生产流水线中各类视频模型都适用的做法。
- 01
根据素材选择端点
原创提示词用文生视频,为单张源图像添加动态用图生视频,需要用视觉参考引导身份、主体外观、场景设计或风格时用参考生视频。
- 02
把运动描述成一个序列
按时间顺序写出起始状态、动作、环境反应、镜头运动和结束状态。清晰的演进过程比一串互不相关的视觉形容词,更能让 H3 形成强有力的运动规划。
- 03
构图已确认时使用图生视频
如果主体、产品、取景或美术方向已在静态图中确定,请直接用图生视频,而不要用文字重建场景。让提示词聚焦于运动和镜头行为。
- 04
让每个参考只承担一项明确的任务
使用参考生视频时,说明参考应控制什么:角色身份、产品外观、视觉风格、环境或构图。避免让同一个参考同时定义镜头的多个相互冲突的方面。
- 05
每个短场景只安排一个主要动作
专注的单个动作比一连串互不相关的事件更容易渲染得连贯。为不同的故事节点分别生成镜头,在概念需要更大叙事范围时再通过剪辑组合起来。
定价
MiniMax H3 API 定价
按输出计费。最终费用会随你在各变体 Playground 中设置的参数(分辨率、时长、输出数量、参考素材)而变化。
API
调用 MiniMax H3 API
在 wavespeed.ai/accesskey 注册并获取 API 密钥,然后通过 REST 提交预测。Playground 可以为任意输入组合生成可直接粘贴的示例代码。
POSThttps://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "480p",
    "duration": 5
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "480p",
"duration": 5
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "480p",
"duration": 5
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)对比
MiniMax H3 与其他方案对比
在 WaveSpeedAI 上,何时应选择 MiniMax H3 而不是同类模型。
MiniMax H3 对比 Hailuo 2.3
Hailuo 2.3 提供 Standard、Pro、Fast 和 Fast Pro 分档的文生视频与图生视频端点。MiniMax H3 采用精简的三端点组合,并把参考生视频作为一等工作流,用于视觉引导和主体一致性。
MiniMax H3 对比 Seedance 2.0
Seedance 2.0 是覆盖面广的生产级系列,提供文生视频、图生视频、视频编辑、视频延长、原生音频和多个性能档位。如果工作流主要围绕文本、源图像或视觉参考来生成,MiniMax H3 是更简单的选择。
MiniMax H3 对比 Kling 3.0
Kling 3.0 强调分档的输出质量和专门的运动控制端点。MiniMax H3 的 API 按素材类型组织,其中包含专门的参考生视频路径,用于身份、主体和风格引导的生成。
常见问题
MiniMax H3 API — 常见问题
定价、许可、集成——关于在 WaveSpeedAI 上运行 MiniMax H3 的常见问题。
什么是 MiniMax H3 API?
MiniMax H3 API 是 WaveSpeedAI 上由三个模型组成的 AI 视频生成套件,支持用于提示词驱动场景的文生视频、用于让静态图像动起来的图生视频,以及由视觉参考引导生成的参考生视频。
应该使用哪个 MiniMax H3 API 端点?
建议先使用 WaveSpeed 基础设施上推荐的开放权重部署:从提示词开始用 wavespeed-ai/minimax-h3/text-to-video,为源图像添加动态用 wavespeed-ai/minimax-h3/image-to-video,需要用视觉参考引导主体身份、外观或风格时用 wavespeed-ai/minimax-h3/reference-to-video。同一系列中也提供 minimax/h3 官方端点。
MiniMax H3 支持图生视频吗?
支持。wavespeed-ai/minimax-h3/image-to-video 端点可将首帧图像(可选尾帧)制作成带原生立体声音频的连贯视频,适合让产品照片、活动素材、角色图像、概念帧等现有视觉素材动起来。
什么是 MiniMax H3 参考生视频?
MiniMax H3 参考生视频会根据最多 9 张参考图像、3 段参考视频和 3 段参考音频生成新视频,用它们来引导主体、角色身份、风格或场景语言。对于系列角色和品牌一致的创意工作流,它是首选的 H3 端点。
如何在 WaveSpeedAI 上使用 MiniMax H3 API?
选择与素材相匹配的 H3 端点,用 WaveSpeedAI API 密钥认证,以 JSON 提交模型输入,再通过返回的预测 ID 或结果 URL 获取生成的视频。本页的端点卡片和代码示例展示了当前的请求结构。
MiniMax H3 API 是什么?
MiniMax H3 是 MiniMax 的视频生成模型,在 WaveSpeedAI 上以 REST API 形式提供。MiniMax H3 API 支持电影感的文生视频、图生视频和参考生视频,具备原生立体声音频、出色的运动质量、主体一致性和场景连贯性。可在 WaveSpeed 基础设施上运行开放权重版本,或通过同一个 WaveSpeedAI API 调用 MiniMax 官方端点。你可以通过编程方式调用它,也可以在上方链接的 Playground 中试用。
如何调用 MiniMax H3 API?
注册 WaveSpeedAI 账号,从 /accesskey 复制你的 API 密钥,然后把输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/text-to-video。端点会返回预测 ID。从大约每 2 秒一次开始轮询结果端点,长耗时任务可适当拉长间隔,并在任何终止状态时停止。上方有面向生产环境的 Python / Node.js / cURL 示例。
MiniMax H3 API 的费用是多少?
MiniMax H3 每次调用 $0.02 起。实际费用会随你设置的参数(分辨率、时长、输出数量、参考素材)而变化。Playground 中“生成”按钮旁的实时费用预览会显示你当前输入对应的准确价格。
有哪些 MiniMax H3 变体可用?
WaveSpeedAI 托管了 20 个已上线的 MiniMax H3 端点:wavespeed-ai/minimax-h3/controlnet-union, wavespeed-ai/minimax-h3-singularity/image-to-video-lora, wavespeed-ai/minimax-h3-singularity/image-to-video, wavespeed-ai/minimax-h3-singularity/reference-to-video-lora, wavespeed-ai/minimax-h3-singularity/reference-to-video, wavespeed-ai/minimax-h3/image-edit-lora, wavespeed-ai/minimax-h3/text-to-image-lora, wavespeed-ai/minimax-h3/image-edit等。每个变体都有自己的 Playground 页面和定价。
MiniMax H3 的输出可以商用吗?
商用权利遵循 MiniMax 的模型许可。大多数 MiniMax 模型允许商用输出;具体许可摘要请查看各模型的 Playground 页面,平台层面的条件请参阅 WaveSpeedAI 的服务条款。
为什么要在 WaveSpeedAI 上使用 MiniMax H3,而不是直接对接?
一个 API 密钥、一个账单账户,即可使用 MiniMax H3 以及来自其他提供方的 1,000 多个 AI 模型。无需逐家配置 SDK,无需应对各自独立的速率限制,也无需为每家重写集成代码。价格通常与 MiniMax 直接提供的 API 持平或更低。
提供方
关于 MiniMax
MiniMax H3 及 WaveSpeedAI 上 MiniMax 更多模型背后的团队。
MiniMax 是中国的 AI 实验室,以 Hailuo 视频生成和语音模型而闻名。Hailuo 2.3 提供物理感知的文生视频和图生视频,分 Standard、Pro 和 Fast 档位——主打 2.5 倍的效率和出色的复杂指令准确率,面向创作者和营销工作流。
在 WaveSpeedAI 上用 MiniMax H3 开始构建
注册即送免费体验额度。一个 API 密钥,即可使用来自 MiniMax 及其他所有提供方的 1,000 多个 AI 模型。