MiniMax H3 Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation on WaveSpeedAI infrastructure. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.125per run·~80 / $10
ExamplesView all
The woman from <Picture 1> leans out of the car window, lowers her sunglasses and says playfully to the camera: "Get in. We're late for the beach." Golden hour, light city traffic sounds.
Related Models
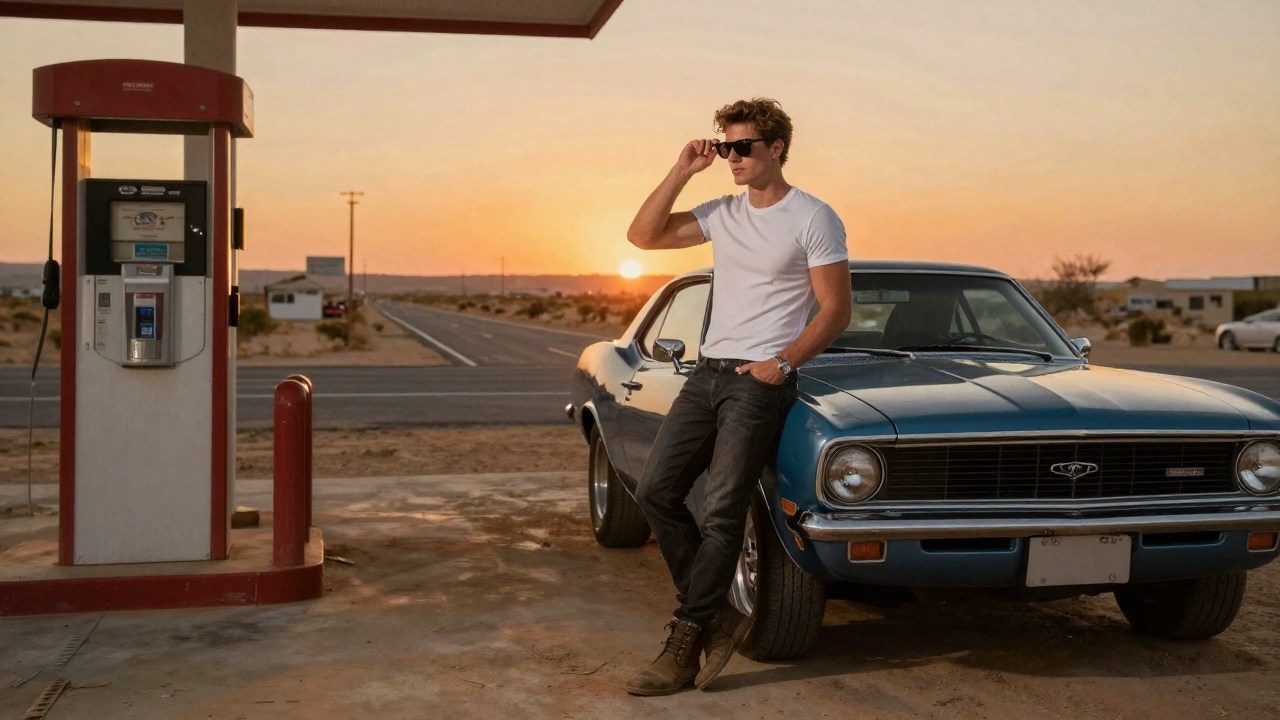
README
MiniMax H3 Reference-to-Video (Open Weights)
Run the open-weights edition of MiniMax H3 on WaveSpeedAI's own GPU infrastructure. This endpoint is separate from the official minimax/h3 API: same model family, independently hosted, with its own 480p/540p/768p/1080p resolutions and per-second pricing.
MiniMax H3 is an omni-modal video model that generates picture and native stereo audio in a single pass. In reference-to-video mode you guide the generation with up to 9 reference images, 3 reference videos, and 3 reference audio tracks, then tell the model — in the prompt — what each reference is for.
How to Use References
Refer to every input in the prompt with an angle-bracket tag: <Picture 1>, <Video 1>, <Audio 1>, and so on. The tags must be written exactly like that, with the brackets — plain text such as Picture 1 is treated as ordinary words, not a reference.
Assign a job to each reference. Explicit assignments work far better than leaving the model to guess:
"Use the character from
<Picture 1>, place them in the setting from<Picture 2>, and match the camera motion of<Video 1>."
Numbering
- Tags are numbered per type, in the order the inputs are provided: images are
<Picture 1>…<Picture 9>, standalone audios are<Audio 1>…, videos are<Video 1>…<Video 3>. - A reference video's own soundtrack is used automatically and occupies the earliest
<Audio …>slots; any standalonereference_audiosyou provide are numbered after the video soundtracks. If you only need the video's audio, refer to it via its<Video …>tag.
Rules
- At least one reference image or video is required. Audio cannot be provided alone.
reference_videosworks at any output resolution. References are always conformed to a 480p pixel budget internally (they carry identity and motion, not output detail), so a 768p render with references stays practical.- Reference video soundtracks are picked up automatically; total reference-video duration shares a 15-second budget and longer inputs are trimmed fairly.
How to Write a Great Prompt
Write the prompt as a timeline with a schedule, and weave the reference tags into it:
- Style & references — establish the look and say which reference drives identity, style, motion, or voice.
- Timeline — timestamped beats: "[0s-3s]
<Picture 1>stands on the balcony from<Picture 2>… [3s-6s] turns toward camera and smiles …". - Camera — explicit movement, including when to hold: "slow orbit, no cuts".
- Audio — an
Audio:line with entrance cues; reference an input voice or track by tag if you want it matched. - On-screen text — spell out readable words in quotes and add "no subtitles, do not add other text."
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Desired video with references addressed as <Picture 1>, <Video 1>, <Audio 1>, plus an Audio: line for the soundtrack. |
| reference_images | No | Up to 9 reference image URLs. |
| reference_videos | No | Up to 3 reference video URLs, usable at any output resolution. Their soundtracks are used automatically. |
| reference_audios | No | Up to 3 standalone reference audio URLs (each trimmed to 15s). |
| aspect_ratio | No | 16:9, 9:16, 1:1, 4:3, 3:4, 21:9, or 9:21. Default: 16:9. |
| resolution | No | 480p (faster, lower cost), 540p (1.5x the 480p price), 768p (native canvas), or 1080p (full HD, 2x the 768p price). Default: 480p. |
| duration | No | Output length in seconds, 3–15. Default: 5. |
| seed | No | Fixed seed for reproducible output. |
At least one of reference_images, reference_videos, or reference_audios is required.
Specifications
| Item | Detail |
|---|---|
| Output | MP4 with native stereo audio |
| Frame rate | 24 fps |
| Resolution | 480p, 540p, 768p, or 1080p |
| Duration | 3–15 seconds (snaps to the model's frame grid, so a 5s request lands at ~5.2s) |
| Reference images | Up to 9 |
| Reference videos | Up to 3, any output resolution, 15s total budget |
| Reference audio | Up to 3, trimmed to 15s each |
| Seed | Supported |
Pricing
Output video is billed per generated second, plus per-reference charges:
| Item | Price |
|---|---|
| Output video (480p) | $0.05 / second |
| Output video (540p) | $0.075 / second |
| Output video (768p) | $0.125 / second |
| Output video (1080p) | $0.25 / second |
| Reference image | $0.02 each |
| Reference audio | $0.02 each |
| Reference video (480p output) | $0.05 / second |
| Reference video (540p output) | $0.075 / second |
| Reference video (768p output) | $0.125 / second |
| Reference video (1080p output) | $0.25 / second |
Example: a 10s 480p video with 2 reference images and a 5s reference video costs 10 × $0.05 + 2 × $0.02 + 5 × $0.05 = $0.79.
Explore the MiniMax H3 Open Weights Family
- MiniMax H3 Text-to-Video Open Weights — Generate video with native stereo audio directly from a text prompt.
- MiniMax H3 Image-to-Video Open Weights — Animate a first-frame image with prompt-guided motion and audio.
- MiniMax H3 Reference-to-Video Open Weights — Generate video from image, video, or audio references with prompt guidance.
Minimax H3 Reference To Video API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/reference-to-video with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Minimax H3 Reference To Video below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "480p",
    "duration": 5
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/reference-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/reference-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "aspect_ratio": "16:9",
        "resolution": "480p",
        "duration": 5
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "480p",
    "duration": 5
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/wavespeed-ai/minimax-h3/reference-to-video", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Minimax H3 Reference To Video API — Frequently asked questions
What is the Minimax H3 Reference To Video API?
Minimax H3 Reference To Video is a WaveSpeedAI model for video generation from images, exposed as a REST API on WaveSpeedAI. MiniMax H3 Open Weights Reference to Video generates coherent 480P / 540P / 768P videos from prompts and multimodal references, guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with native stereo audio and flexible reference-based video generation on WaveSpeedAI infrastructure. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Minimax H3 Reference To Video API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/wavespeed-ai/minimax-h3-reference-to-video.
How much does Minimax H3 Reference To Video cost per run?
Minimax H3 Reference To Video starts at $0.125 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Minimax H3 Reference To Video accept?
Key inputs: `prompt`, `aspect_ratio`, `resolution`, `duration`, `seed`, `reference_images`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/wavespeed-ai/minimax-h3-reference-to-video.
How long does Minimax H3 Reference To Video take to generate?
Reported generation time on WaveSpeedAI is around 150 seconds per request. This is an estimate, not a latency guarantee; queue time and input settings can change the total wait. live status is visible in the prediction record.
Can I use Minimax H3 Reference To Video outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (WaveSpeedAI). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.