MOSS Image Text-to-Image generates images from long text prompts, with sharp Chinese and English text rendering, 1K, 1.5K or 2K output and flexible aspect ratios. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.02per run·~50 / $1
ExamplesView all
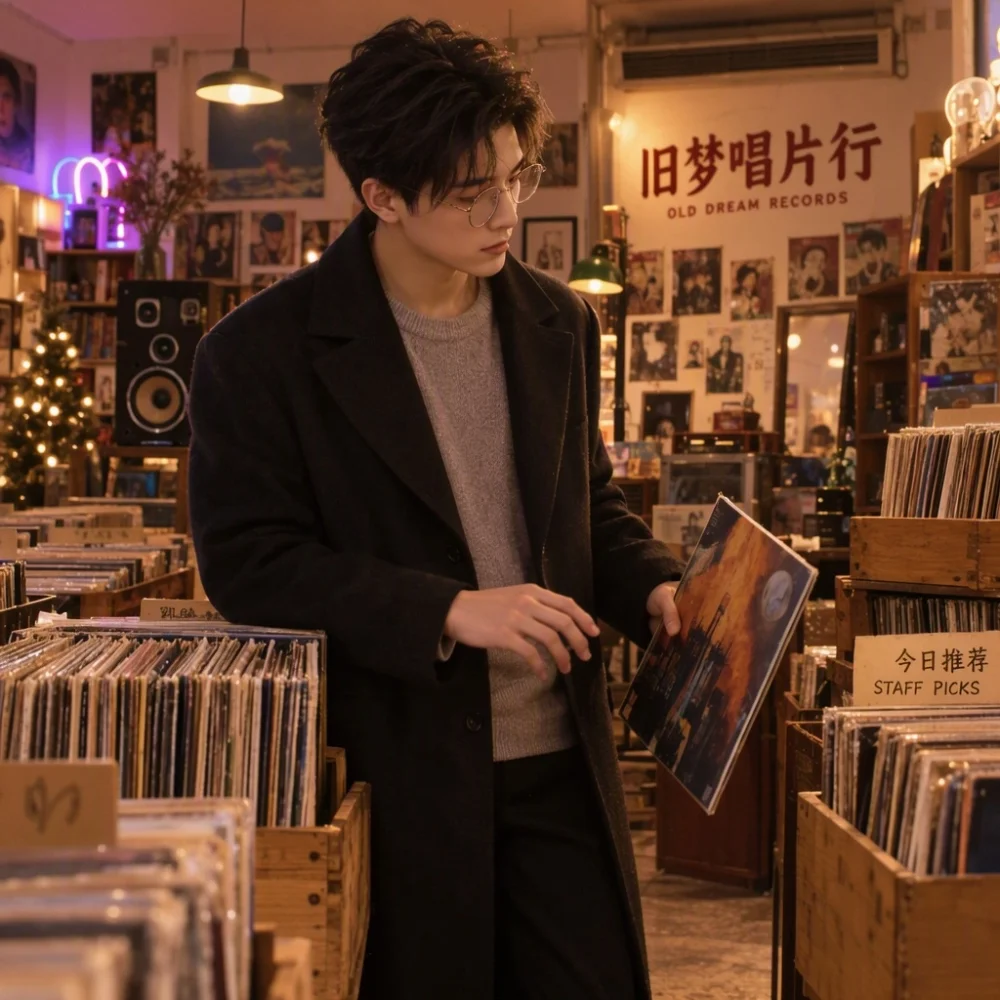
A handsome young man browsing vinyl records inside a warm vintage record shop, wearing a dark coat and round glasses, holding a record sleeve in one hand. Wooden crates, retro speakers, posters, and neon accents fill the shop. A large wall sign clearly reads "旧梦唱片行" with "OLD DREAM RECORDS" underneath. A small handwritten sign on a shelf reads "今日推荐" and below it "STAFF PICKS". Cozy cinematic lighting, nostalgic atmosphere, rich detail, clearly legible Chinese and English text.
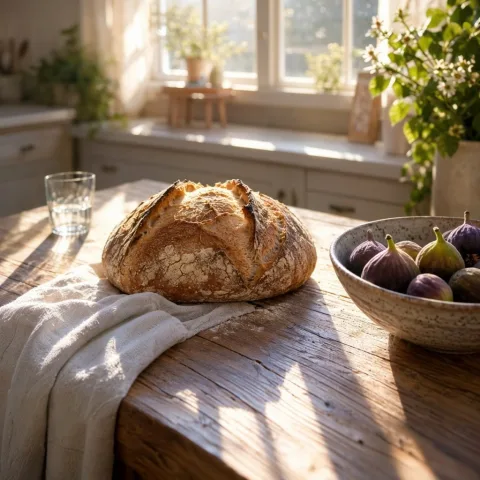
A rustic wooden kitchen table by a window with a freshly baked sourdough loaf, a ceramic bowl of ripe figs and a glass of water, warm morning sunlight casting long soft shadows, shallow depth of field, natural film photography look.
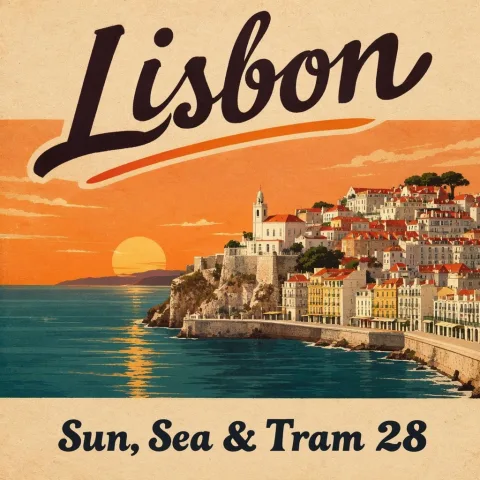
A vintage travel poster of a seaside town at sunset, bold hand-lettered title "Lisbon" at the top and the line "Sun, Sea & Tram 28" at the bottom, flat colours, textured paper, balanced layout.
Related Models
README
MOSS Image Text-to-Image
MOSS Image Text-to-Image generates images from detailed text prompts with strong support for Chinese and English text rendering. Describe the subject, composition, environment, lighting, and any text you want to appear, then choose the resolution and aspect ratio for the final image.
Why Choose This?
- Detailed prompt understanding — Use rich scene descriptions to control composition, subject, background, lighting, and visual style.
- Chinese and English text rendering — Create posters, signs, packaging, infographics, and other text-heavy visuals.
- 1K, 1.5K, and 2K output — Choose
1k,1.5k, or2kdepending on your quality requirements. - 15 aspect ratios — Generate images for a wide range of layouts and placements.
- Multiple output formats — Export as
jpeg,png, orwebp.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Text description of the image to generate. Detailed prompts are recommended. |
| resolution | No | Output resolution: 1k, 1.5k, or 2k. Default: 1k. |
| aspect_ratio | No | Output aspect ratio. Default: 1:1. |
| output_format | No | Output format: jpeg, png, or webp. Default: jpeg. |
| seed | No | Random seed. Use -1 for automatic random selection. |
How to Use
- Write a prompt — Describe the subject, composition, background, lighting, and visual style. Put any text you want rendered in quotation marks.
- Choose a resolution — Select
1k,1.5k, or2k. - Choose an aspect ratio optional — Select the framing that fits your target layout.
- Choose an output format optional — Use
jpeg,png, orwebp. - Set a seed optional — Use a fixed seed for repeatable results or
-1for random generation. - Submit — Generate and retrieve the finished image.
Pricing
| Resolution | Price per Image |
|---|---|
| 1K | $0.020 |
| 1.5K | $0.040 |
| 2K | $0.080 |
Aspect ratio, output format, and seed do not add separate charges.
Best Use Cases
- Posters and promotional graphics — Generate visuals with Chinese or English text.
- Packaging concepts — Create product packaging and label designs.
- Infographics — Combine visual elements with readable text.
- Advertising creatives — Produce campaign and marketing concepts.
- Editorial imagery — Generate detailed compositions for publishing and social content.
- Creative image generation — Explore illustrations, photography, and stylized concepts from long-form prompts.
Pro Tips
- Describe the subject, composition, environment, lighting, and style clearly.
- Put text that should appear in the image inside quotation marks.
- Use detailed prompts when precise scene structure matters.
- Choose
2kwhen higher output detail is needed. - Use a fixed seed when comparing prompt or parameter changes.
Notes
promptis required.resolutiondefaults to1k.aspect_ratiodefaults to1:1.output_formatdefaults tojpeg.- Use
seed=-1for random seed selection. - Both Chinese and English text can be included in prompts and rendered in generated images.
Moss Image Text To Image API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/wavespeed-ai/moss-image/text-to-image with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Moss Image Text To Image below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "1k",
    "output_format": "jpeg"
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/wavespeed-ai/moss-image/text-to-image" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/wavespeed-ai/moss-image/text-to-image";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "aspect_ratio": "1:1",
        "resolution": "1k",
        "output_format": "jpeg"
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "1k",
    "output_format": "jpeg"
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/wavespeed-ai/moss-image/text-to-image", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Moss Image Text To Image API — Frequently asked questions
What is the Moss Image Text To Image API?
Moss Image Text To Image is a WaveSpeedAI model for image generation, exposed as a REST API on WaveSpeedAI. MOSS Image Text-to-Image generates images from long text prompts, with sharp Chinese and English text rendering, 1K, 1.5K or 2K output and flexible aspect ratios. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Moss Image Text To Image API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/wavespeed-ai/moss-image-text-to-image.
How much does Moss Image Text To Image cost per run?
Moss Image Text To Image starts at $0.02 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Moss Image Text To Image accept?
Key inputs: `prompt`, `aspect_ratio`, `resolution`, `seed`, `enable_base64_output`, `enable_sync_mode`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/wavespeed-ai/moss-image-text-to-image.
How do I get started with the Moss Image Text To Image API?
Sign up for a free WaveSpeedAI account to claim starter credits, copy your API key from /accesskey, then call the endpoint shown in the API tab of the playground. The playground also auto-generates a code sample in Python, JavaScript, or cURL for the parameters you've set.
Can I use Moss Image Text To Image outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (WaveSpeedAI). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from WaveSpeed
View all- wavespeed-ai/ace-stepAI Music Generation
- wavespeed-ai/ace-step-1.5AI Music Generation
- wavespeed-ai/ace-step/audio-inpaintMusic Editing
- wavespeed-ai/ace-step/audio-outpaintMusic Editing
- wavespeed-ai/ace-step/audio-to-audioMusic Editing
- wavespeed-ai/ace-step/prompt-to-audioAI Music Generation
- wavespeed-ai/ai-age-filterImage Effects
- wavespeed-ai/ai-breast-expansionImage Effects
More Text to Image models
View all- bytedance/seedream-v5.0-proText to Image
- openai/gpt-image-2/text-to-imageText to Image
- google/nano-banana-pro/text-to-imageText to Image
- google/nano-banana-2/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- bytedance/seedream-v4.5Text to Image
- alibaba/wan-2.7/text-to-imageText to Image
- alibaba/qwen-image-3.0/text-to-imageText to Image