Krea V3 Text-to-Image generates images from text prompts with selectable quality and speed variants, custom dimensions, and seed control for flexible creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.03per run·~33 / $1
ExamplesView all
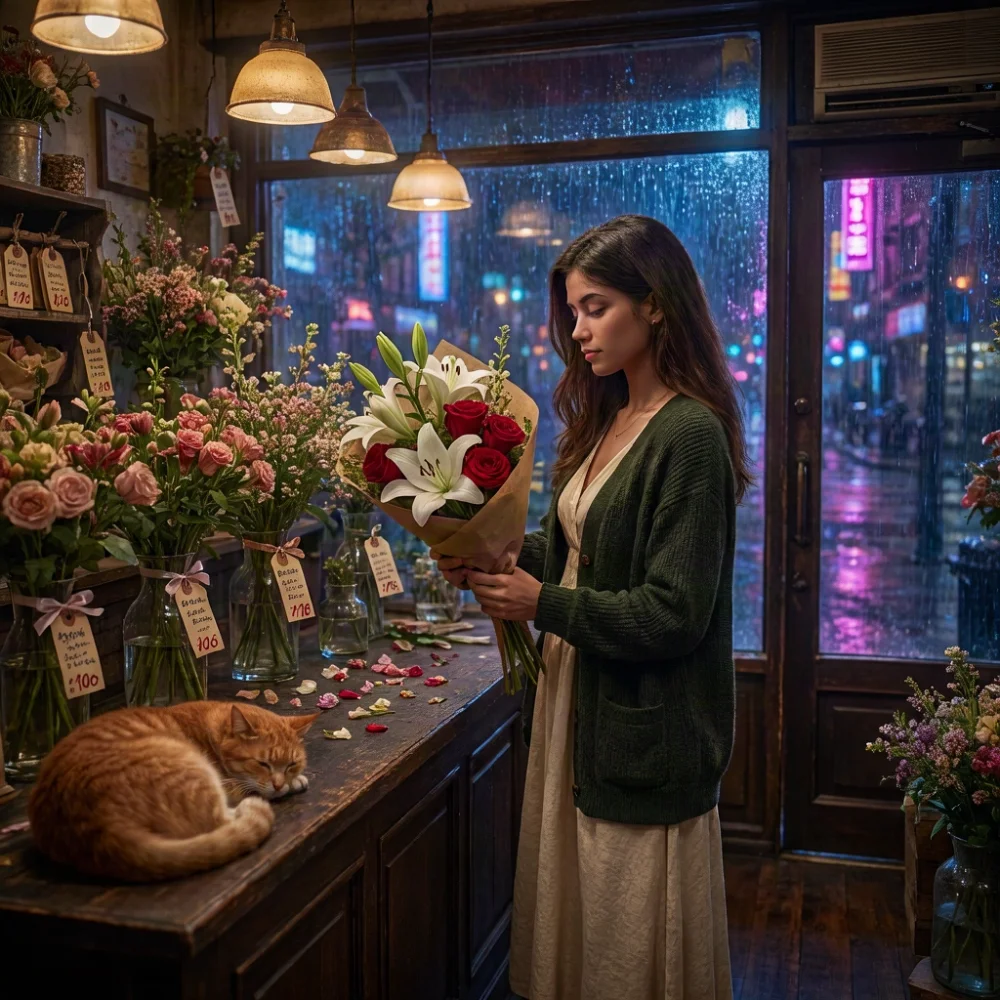
A beautiful young woman standing alone inside a small flower shop late at night, wearing a dark green cardigan over a cream dress, gently wrapping a bouquet of white lilies and deep red roses in brown paper. Warm hanging lamps illuminate glass vases, scattered petals, handwritten price tags, ribbons, and a sleepy orange cat curled on the counter. Outside the window, light rain reflects city neon. Cinematic realism, rich small details, soft warm lighting, elegant storytelling atmosphere.
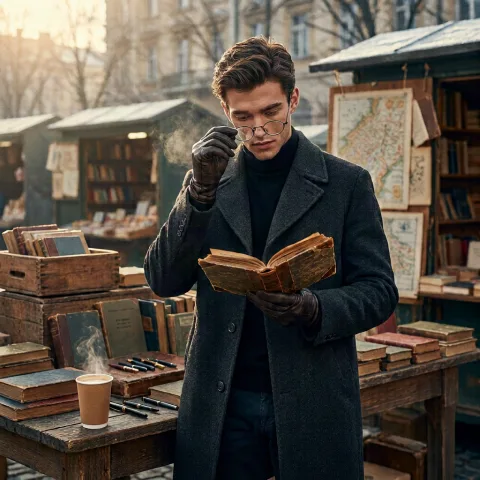
A handsome young man browsing an old outdoor book market in the early morning, wearing a charcoal wool coat, black turtleneck, and leather gloves. He holds an antique book open in one hand while the other hand lifts his round glasses slightly. Around him are weathered books, stacked wooden crates, yellowing maps, fountain pens, and a steaming paper cup of coffee on the table. Soft winter sunlight, cinematic realism, refined details, intellectual and slightly mysterious mood.
Related Models
README
Krea V3 Text-to-Image
Krea V3 Text-to-Image generates images from text prompts with custom output dimensions and two generation variants. Use berry for quality-focused generation or jam for faster results.
Why Choose This?
- Two generation variants — Choose
berryfor quality orjamfor speed. - Custom image sizes — Set the output width and height for different layouts.
- Negative prompt support — Use negative prompts with Berry to reduce unwanted elements.
- Reasoning control — Choose between
lowandmediumreasoning levels. - Seed support — Use a fixed seed for more reproducible results.
- PNG and JPEG output — Choose the format that fits your workflow.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Text description of the image to generate. |
| model | No | berry for quality-focused generation or jam for faster generation. Default: berry. |
| negative_prompt | No | Optional content to avoid. Used only by berry. |
| size | No | Output dimensions in width*height format. Default: 1024*1024. |
| reasoning_level | No | low or medium. Default: low. |
| output_format | No | png or jpeg. Default: png. |
| seed | No | Optional integer seed for reproducible generation. |
How to Use
- Write a prompt — Describe the image you want to generate.
- Choose a model — Select
berryorjam. - Set image size optional — Enter the desired output dimensions.
- Configure optional settings — Add a negative prompt, reasoning level, output format, or seed.
- Submit — Generate and retrieve the final image.
Pricing
Pricing is based on the requested output size at $0.03 per megapixel.
| Output Size | Price |
|---|---|
| 1024 × 1024 | $0.03 |
| 1024 × 1536 | $0.045 |
| 2048 × 2048 | $0.12 |
berry and jam use the same pricing. Other generation settings do not add separate charges.
Best Use Cases
- Creative image generation — Generate photography, illustrations, and visual concepts.
- Advertising visuals — Create campaign and promotional imagery.
- Product concepts — Explore products, materials, and presentation styles.
- Editorial content — Generate images for articles, covers, and publishing.
- Custom-format images — Create outputs sized for specific layouts or placements.
Pro Tips
- Describe the subject, composition, lighting, and visual style clearly.
- Use
berrywhen quality is the priority. - Use
jamwhen faster iteration is preferred. - Use
negative_promptwith Berry when specific elements should be avoided. - Set a fixed
seedwhen comparing prompt changes.
Notes
promptis required.modeldefaults toberry.sizedefaults to1024*1024.- Supported dimensions range from
256to4096pixels per side. negative_promptis used only by Berry.- Custom output dimensions are subject to a maximum total pixel count of 4,220,160 pixels. Some width-and-height combinations may be unavailable even when both dimensions are individually within the supported range.
Related Models
- Krea V3 Text-to-Image — Generate images from text with custom dimensions.
- Krea V3 Edit — Edit existing images with Krea V3.
v3 Text To Image API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/krea/v3/text-to-image with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for v3 Text To Image below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "1024*1024",
    "reasoning_level": "low",
    "model": "berry",
    "output_format": "png"
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/krea/v3/text-to-image" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/krea/v3/text-to-image";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "size": "1024*1024",
        "reasoning_level": "low",
        "model": "berry",
        "output_format": "png"
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "1024*1024",
    "reasoning_level": "low",
    "model": "berry",
    "output_format": "png"
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/krea/v3/text-to-image", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
v3 Text To Image API — Frequently asked questions
What is the v3 Text To Image API?
v3 Text To Image is a Krea model for image generation, exposed as a REST API on WaveSpeedAI. Krea V3 Text-to-Image generates images from text prompts with selectable quality and speed variants, custom dimensions, and seed control for flexible creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the v3 Text To Image API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/krea/krea-v3-text-to-image.
How much does v3 Text To Image cost per run?
v3 Text To Image starts at $0.03 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does v3 Text To Image accept?
Key inputs: `prompt`, `size`, `seed`, `negative_prompt`, `model`, `output_format`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/krea/krea-v3-text-to-image.
How do I get started with the v3 Text To Image API?
Sign up for a free WaveSpeedAI account to claim starter credits, copy your API key from /accesskey, then call the endpoint shown in the API tab of the playground. The playground also auto-generates a code sample in Python, JavaScript, or cURL for the parameters you've set.
Can I use v3 Text To Image outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (Krea). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from Krea
View allMore Text to Image models
View all- bytedance/seedream-v5.0-proText to Image
- openai/gpt-image-2/text-to-imageText to Image
- google/nano-banana-pro/text-to-imageText to Image
- google/nano-banana-2/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- bytedance/seedream-v4.5Text to Image
- alibaba/wan-2.7/text-to-imageText to Image
- alibaba/qwen-image-3.0/text-to-imageText to Image