Qwen Image API
Alibaba の Qwen-Image は、20B MMDiT の次世代テキストから画像・編集ツールキットで、中国語/英語のバイリンガル対応、複数画像の編集、LoRAによるカスタマイズ、レイヤー合成、96ポーズのカメラアングルシステムを備えています。
テキストから画像は、基本、強化版の2512、2.0-pro のバリアントがあります。編集エンドポイントには、Edit、Edit-Plus(複数画像、ControlNet)、Edit-LoRA、Edit-Multiple-Angles(96ポーズのカメラシステム)、Layered(プロンプトによる分解)があります。Qwen Image 2.0 ファミリーのバリアントも、同じプレフィックスのもとに含まれています。
概要
Qwen Image APIについて
Qwen Imageでできること、Alibabaのモデルラインナップにおける位置づけ、そして多くのチームに選ばれる理由。
Qwen ImageはAlibabaの画像生成・編集モデルで、WaveSpeedAIのREST APIから利用できます。Alibaba の Qwen-Image は、20B MMDiT の次世代テキストから画像・編集ツールキットで、中国語/英語のバイリンガル対応、複数画像の編集、LoRAによるカスタマイズ、レイヤー合成、96ポーズのカメラアングルシステムを備えています。
テキストから画像は、基本、強化版の2512、2.0-pro のバリアントがあります。編集エンドポイントには、Edit、Edit-Plus(複数画像、ControlNet)、Edit-LoRA、Edit-Multiple-Angles(96ポーズのカメラシステム)、Layered(プロンプトによる分解)があります。Qwen Image 2.0 ファミリーのバリアントも、同じプレフィックスのもとに含まれています。
WaveSpeedAIのQwen Imageファミリーには、Image-To-Image, Text-To-Image, Trainingのワークフローをカバーする21個のRESTエンドポイントがあります。各バリアントには、それぞれ独自の料金、パラメーター、作例があります。入力の種類と本番環境の制約に合うものを選ぶか、同じAPIキーで複数を呼び出して、多段階のパイプラインを組み立ててください。
WaveSpeedAIの他の1,000以上のAIモデルと同じAPIキー、請求アカウント、レート制限の枠組みでQwen Imageを実行できます。ベンダーごとの設定も、プロバイダーごとのSDKも、ベンダーごとのレート制限も不要です。1つの連携で、テキストから画像、テキストから動画から、音声合成、3D生成、高画質化、編集まで、すべてカバーできます。
エンドポイント
Qwen ImageのAPIエンドポイント一覧
WaveSpeedAIで現在利用可能なQwen Imageのエンドポイントは21個です。ワークフローに合ったバリアントを選んでください。
Qwen Image 2.0 Edit
Qwen Image 2.0 Edit is an advanced image-editing model with improved quality and better understanding of instructions. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 2.0 Pro Edit
Qwen Image 2.0 Pro Edit is a professional-grade image editing model with superior quality and advanced instruction understanding. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 2.0 Text To Image
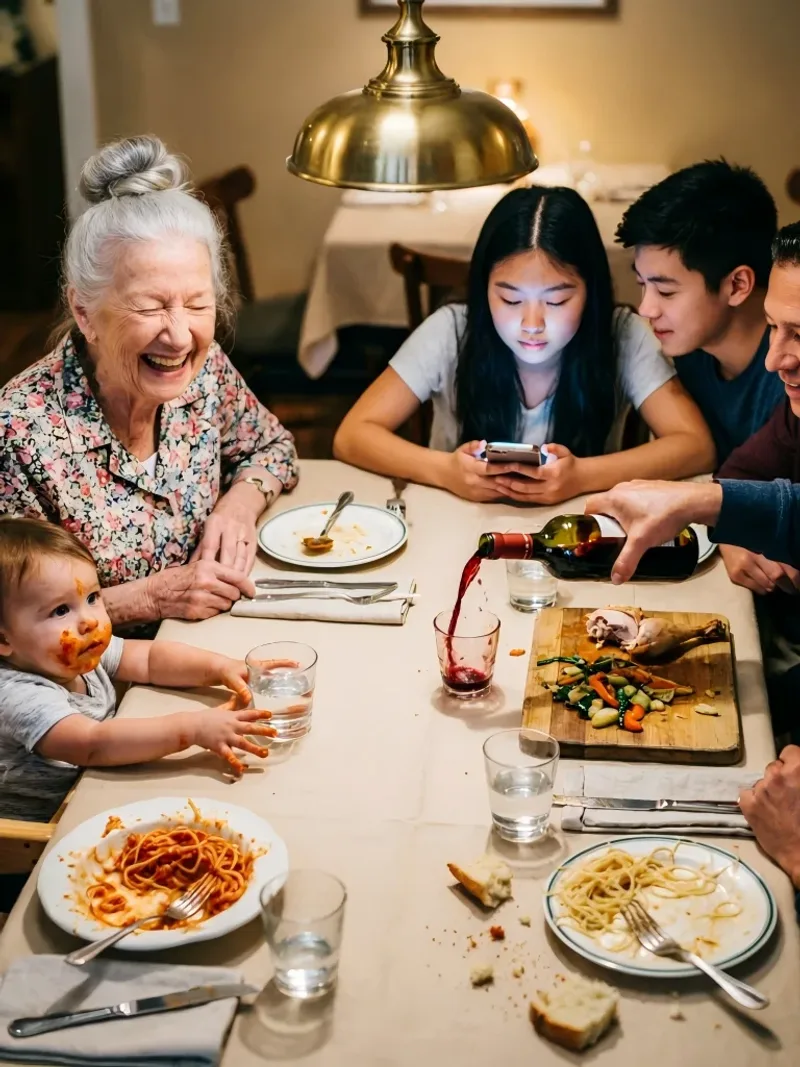
Qwen Image 2.0 is an advanced text-to-image model with enhanced image quality and improved prompt understanding. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 2.0 Pro Text To Image
Qwen Image 2.0 Pro is a professional-grade text-to-image model with superior quality and advanced prompt understanding. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Edit 2509 Multiple Angles
Qwen Image Edit 2509 Multiple Angles is an AI image editing model that generates multiple-angle views of objects or scenes from a single image. Transform perspectives and create diverse viewpoints with text prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Max Edit
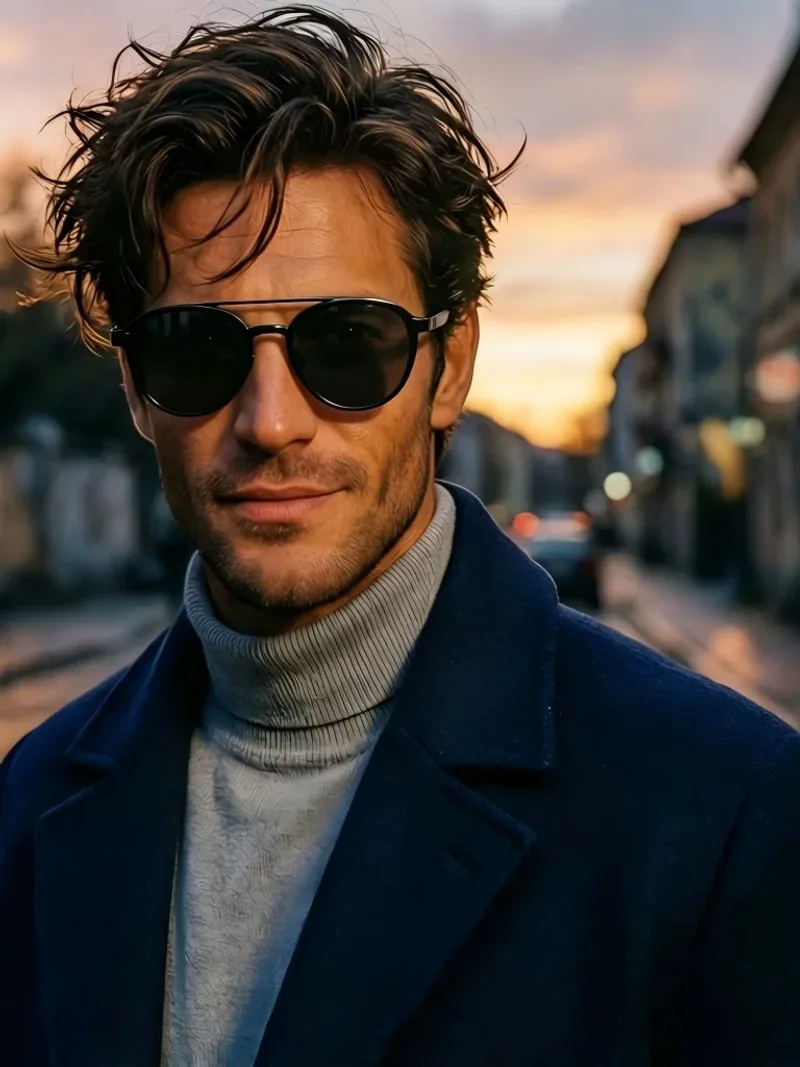
Qwen Image Max Edit is an AI model for image editing with text prompts, supporting both Chinese and English languages. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Max Text To Image
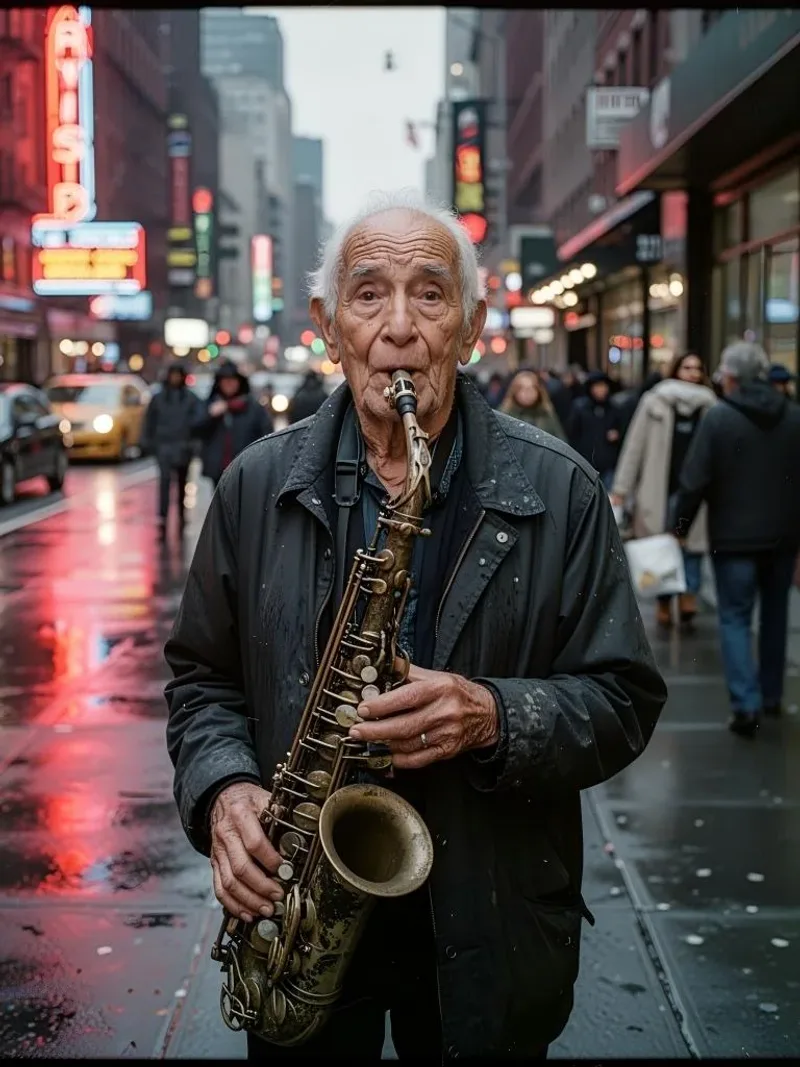
Qwen Image Max is a text-to-image model with high-quality image generation supporting Chinese and English prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
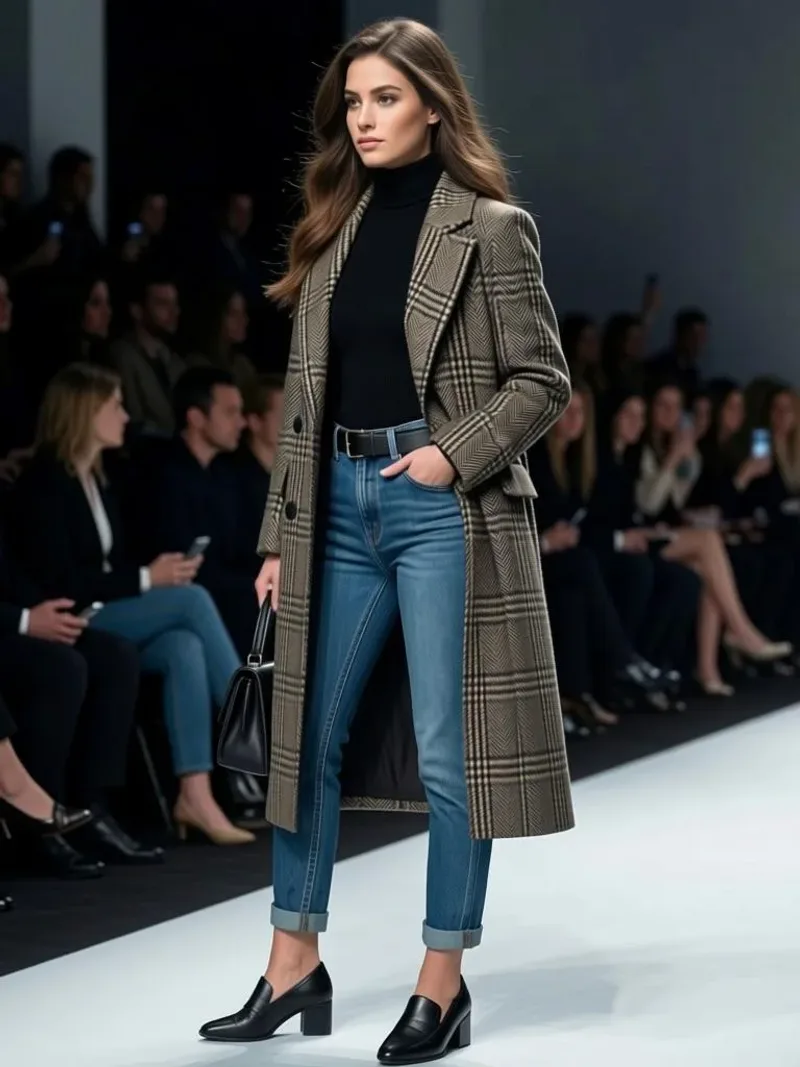
Qwen Image Edit Multiple Angles
Generate specific camera angles from a single image using a 96-pose camera system. Control horizontal rotation, vertical tilt, and zoom to create front, side, back views and more. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 2512 Lora Trainer
Qwen-Image-2512 LoRA Trainer lets you train custom LoRA models 10x faster with style, character, and object training. From concept to model in minutes, not hours—upload a ZIP file containing images to start. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
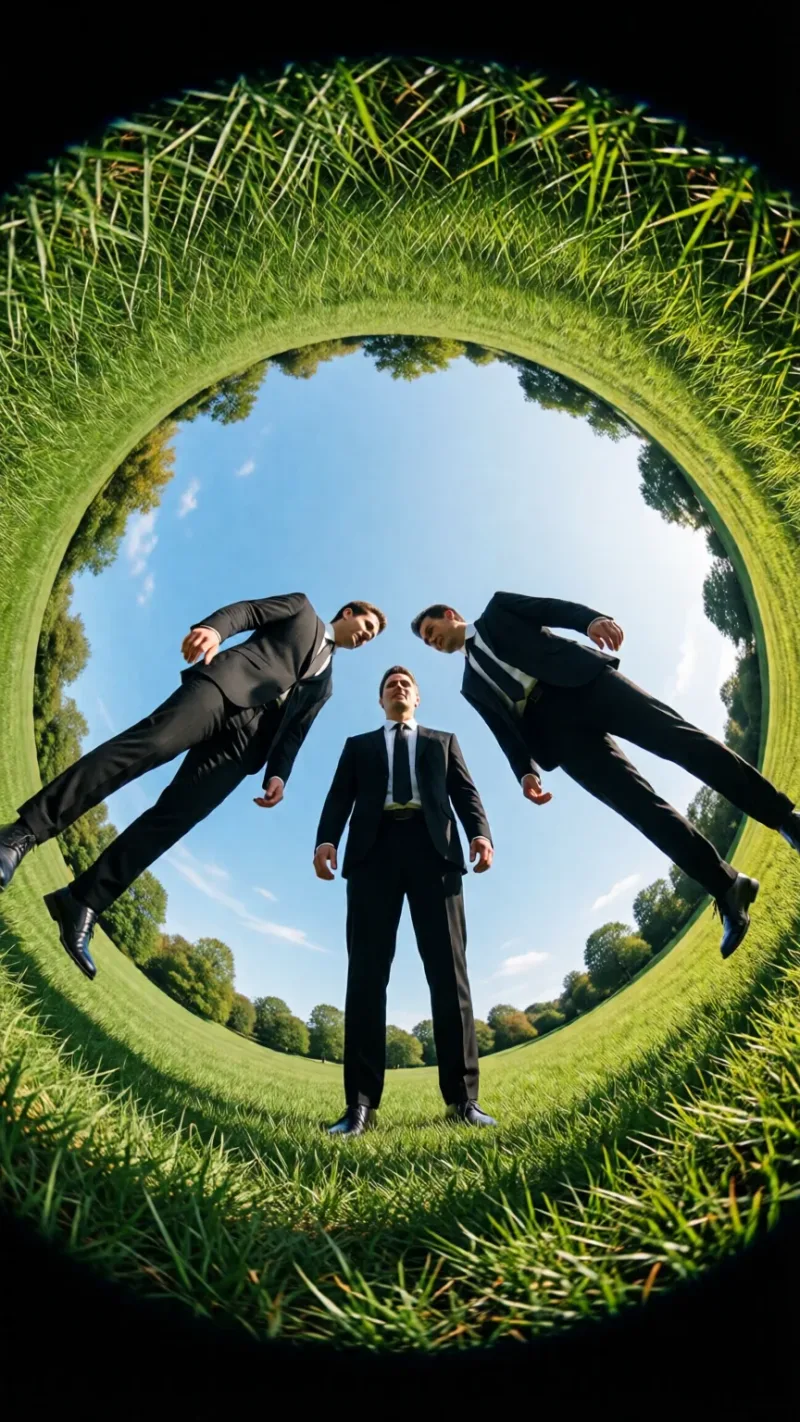
Qwen Image Text To Image 2512 Lora
Qwen-Image-2512 LoRA is an enhanced 20B MMDiT text-to-image model with LoRA support for fast customization and refined image generation. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
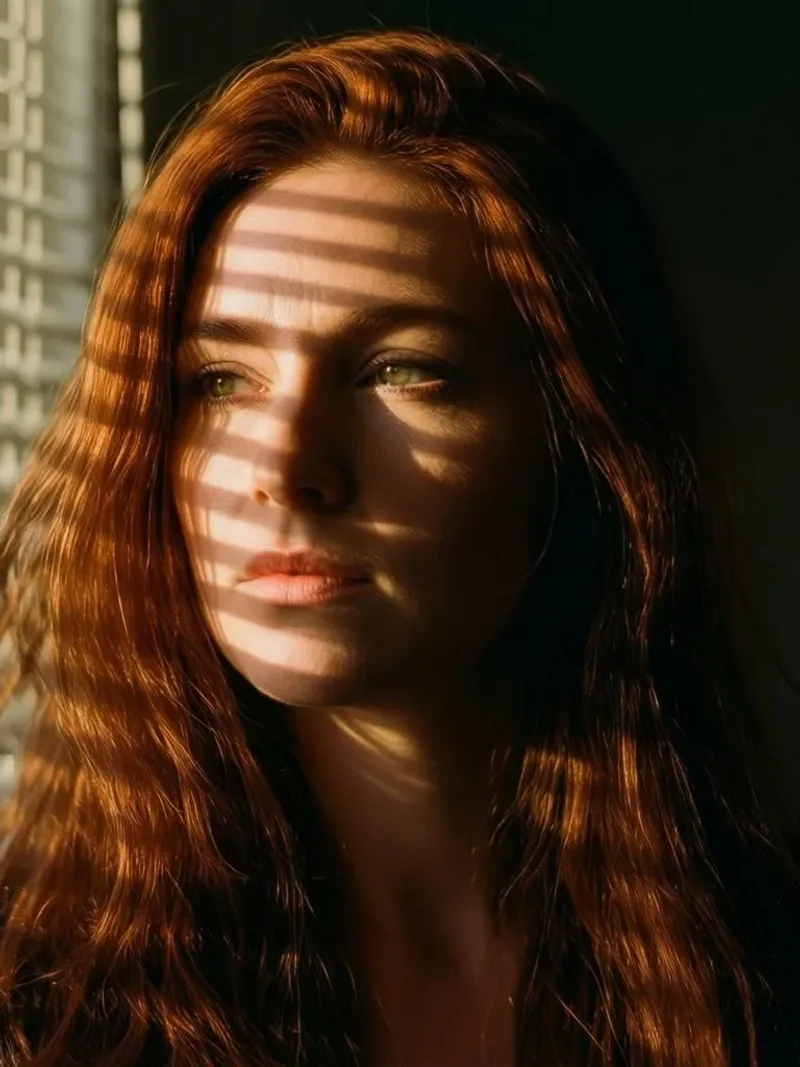
Qwen Image Text To Image 2512
Qwen Image 2512 is Qwen's latest text-to-image model with enhanced prompt understanding, superior text rendering, and versatile aspect ratio support. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Qwen Image Edit 2511 Lora
Qwen Image Edit 2511 LoRA is an enhanced version with custom LoRA support for personalized styles. It delivers stronger edit consistency, robust multi-person identity/pose consistency, custom LoRA styles, enhanced industrial/product design, and improved geometric reasoning for structure-preserving edits. Built for stable production use with a ready-to-use REST API, no cold starts, and predictable pricing.
Qwen Image Edit 2511
Qwen Image Edit 2511 is a major upgrade over 2509 for real-world image editing and design. It delivers stronger edit consistency, robust multi-person identity/pose consistency, built-in LoRA styles, enhanced industrial/product design, and improved geometric reasoning for structure-preserving edits. Built for stable production use with a ready-to-use REST API, no cold starts, and predictable pricing.
Qwen Image Layered
Qwen-Image Layered is a unified image-layer decomposition model for prompt-guided compositing. Provide points, boxes, or rough masks to isolate subjects and regions, and the model splits a single image into multiple RGBA layers with clean alpha, soft edges, and correct occlusion order. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
Qwen Image Edit Plus Lora
Qwen-Image-Edit-Plus (2509) is 20B MMDiT image-to-image editor supporting multi-image edits, single-image consistency, and native ControlNet. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Edit Plus
Qwen-Image-Edit-Plus (2509) is a 20B MMDiT image editor with multi-image editing, single-image consistency and native ControlNet support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Edit Lora
Qwen-Image-Edit LoRA (20B) enables bilingual Chinese/English image-to-image editing with style preservation and semantic and appearance edits. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Qwen Image Edit
Qwen-Image-Edit is a 20B MMDiT image-to-image model offering precise bilingual (Chinese & English) text edits while preserving style. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Lora Trainer
Train custom Qwen-Image LoRA models 10x faster. Style training, character training, object training. From concept to model in minutes, not hours. Upload a ZIP file containing images to start!

Qwen Image Text To Image Lora
Qwen-Image LoRA is a 20B MMDiT next-gen text-to-image model with LoRA support for fast customization and refined image generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image Text To Image
Qwen-Image is a 20B MMDiT next-gen text-to-image model that generates images from text prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
作例
Qwen Imageの実力を見る
Qwen Image APIで実際に生成された出力です。動画にカーソルを合わせるとプレビュー、クリックすると原寸のビューアで開きます。
使い方
Qwen Image APIの使い方
登録から生成完了まで4ステップ。Python、Node.js、cURLの完全なサンプルは、下のAPIセクションにあります。
- 01
APIキーを取得
WaveSpeedAIのアカウントに登録し、ダッシュボードからAPIキーをコピーします。新規アカウントには無料のスタータークレジットが付くので、課金が始まる前にプレイグラウンドを数十回実行できます。
- 02
予測を送信
入力をJSONとしてhttps://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-imageにPOSTします。エンドポイントはすぐに予測IDを返します。生成は非同期なので、推論中に接続を開いたままにする必要はありません。
- 03
完了までポーリング
https://api.wavespeed.ai/api/v3/predictions/{request_id}/resultにGETします。completedなら出力を返し、failed、cancelled、timeout、deletedならエラーで停止し、それ以外のステータスの間はポーリングを続けます。
- 04
出力URLを読み取る
ステータスが"completed"になったら、data.outputs[0]からURLを読み取ります。URLは、WaveSpeedAIのCDN上にある生成されたメディアを指します。呼び出したQwen Imageのバリアントに応じて、画像、動画、音声、3Dファイルのいずれかです。
活用例
Qwen Imageで作れるもの
開発者やクリエイターがQwen Image APIでよく使うワークフロー。
20B MMDiT のテキストから画像
wavespeed-ai/qwen-image/text-to-image は、テキストプロンプトから画像を生成する、20B MMDiT の次世代テキストから画像モデルです。Qwen Image ファミリーの基本の生成エンドポイントです。
優れた文字描画の強化版 2512
wavespeed-ai/qwen-image/text-to-image-2512 は、カタログによると、強化されたプロンプトの理解、優れた文字描画、多様なアスペクト比のサポートを備えた、Qwen の最新のテキストから画像モデルです。
Edit-Plus による複数画像の編集
wavespeed-ai/qwen-image/edit-plus は、複数画像の編集、単一画像の一貫性、ネイティブな ControlNet に対応した、20B MMDiT のエディターです。複数の元画像を参照する、複雑な編集に便利です。
96ポーズのカメラアングル制御
wavespeed-ai/qwen-image/edit-multiple-angles は、96ポーズのカメラシステムを使い、1枚の画像から特定のカメラアングルを生成します。水平方向の回転、垂直方向のチルト、ズームを制御して、正面、側面、背面などのビューを作れます。
レイヤー合成のための分解
wavespeed-ai/qwen-image/layered は、プロンプトによる合成のための、統合型の画像レイヤー分解モデルです。点、ボックス、大まかなマスクを指定して被写体を切り出し、1枚の画像をレイヤーに分割できます。
LoRAによるカスタマイズ
LoRA対応のバリアント(text-to-image-2512-lora、edit-lora、edit-plus-lora)で、高速なカスタマイズと洗練された生成ができます。スタイル、キャラクター、ブランドの一貫性のために、LoRAチェックポイントを学習・適用できます。
コツ
Qwen Imageのプロンプトのコツ
Qwen Imageからより良い出力を得るための実践的なアドバイス。本番のパイプラインで画像モデル全般に通用するパターンに基づいています。
- 01
最新の文字描画には 2512 を使う
text-to-image-2512 は、優れた文字描画とプロンプトの理解を備えた強化版のバリアントです。タイポグラフィが重要なときは、基本の text-to-image より、こちらを選んでください。
- 02
商品のビューには Edit-Multiple-Angles
edit-multiple-angles は、1枚の商品写真から、正面、側面、背面、任意のカメラアングルを生成します。複数台のカメラでの撮影なしに、ECのカタログを作るのに便利です。
- 03
複数画像の参照には Edit-Plus
編集が複数の元画像に依存する場合は、単一画像の編集ではなく、ネイティブな ControlNet に対応した edit-plus を使ってください。
- 04
合成のワークフローには Layered
layered を使うと、画像を、プロンプトで導かれたレイヤーに分解できます。点、ボックス、大まかなマスクで被写体を切り出し、後工程の合成に使えます。
- 05
ブランドの一貫性には LoRA バリアント
text-to-image-2512-lora や edit-plus-lora で、学習済みの LoRA チェックポイントを適用し、生成をまたいでスタイル、キャラクター、ブランドのアイデンティティを一貫させます。
- 06
中国語/英語のバイリンガル編集
Edit と Edit-LoRA は、スタイルを保った、中国語/英語のバイリンガルの画像から画像への編集に対応しています。ローカライズのワークフローに便利です。
料金
Qwen Image APIの料金
料金は出力ごとです。最終的な請求額は、各バリアントのプレイグラウンドで設定するパラメーター(解像度、長さ、出力数、参照入力)に応じて変わります。
API
Qwen Image APIを呼び出す
wavespeed.ai/accesskeyでAPIキーに登録し、RESTで予測を送信します。プレイグラウンドでは、入力の組み合わせに応じて、そのまま貼り付けられるサンプルが生成されます。
POSThttps://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-image
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-image" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "1024*1024",
    "output_format": "jpeg"
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-image";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"size": "1024*1024",
"output_format": "jpeg"
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"size": "1024*1024",
"output_format": "jpeg"
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-image", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)比較
Qwen Imageと他モデルの比較
WaveSpeedAI上の類似モデルではなくQwen Imageを選ぶべきケース。
Qwen Image vs Seedream 4.5
Seedream 4.5 は、タイポグラフィを重視し、複数画像のアイデンティティを固定する Sequential バリアントを備えています。Qwen Image は、Edit-Plus、マルチアングル、レイヤー合成、中国語/英語のバイリンガルの編集といった、より幅広い編集機能をカバーします。
Qwen Image vs GPT Image 2
GPT Image 2 には、明示的な品質階層と、参照画像を使う編集ワークフローがあります。Qwen Image は、ネイティブな ControlNet、96ポーズのカメラアングル、レイヤー分解を備え、異なる編集機能を、より低い1回あたりのコストで提供します。
Qwen Image vs Nano Banana 2
Nano Banana 2 は、複数キャラクターの一貫性(最大5人)とウェブ検索に基づく生成を備えています。Qwen Image は、複数画像の Edit-Plus、カメラアングルの生成、プロンプトによるレイヤー分解といった、編集の深さで優位に立ちます。
FAQ
Qwen Image API — よくある質問
料金、ライセンス、連携など、WaveSpeedAIでQwen Imageを実行する際のよくある質問。
Qwen Image APIとは何ですか?
Qwen Imageは、Alibabaの画像生成モデルで、WaveSpeedAI上でREST APIとして提供されています。Alibaba の Qwen-Image は、20B MMDiT の次世代テキストから画像・編集ツールキットで、中国語/英語のバイリンガル対応、複数画像の編集、LoRAによるカスタマイズ、レイヤー合成、96ポーズのカメラアングルシステムを備えています。プログラムから呼び出すことも、上にリンクされたプレイグラウンドで試すこともできます。
Qwen Image APIはどう呼び出しますか?
WaveSpeedAIのアカウントに登録し、/accesskeyからAPIキーをコピーして、入力をJSONとしてhttps://api.wavespeed.ai/api/v3/wavespeed-ai/qwen-image/text-to-imageにPOSTします。エンドポイントは予測IDを返します。結果のエンドポイントを約2秒ごとにポーリングし、長時間かかるタスクでは間隔を広げ、終端ステータスになったら停止してください。本番運用向けのPython / Node.js / cURLのサンプルは上にあります。
Qwen Image APIの料金はいくらですか?
Qwen Imageは1回あたり$0.02からです。実際の料金は、設定するパラメーター(解像度、長さ、出力数、参照入力)に応じて変わります。プレイグラウンドの「生成」ボタンの横に表示されるリアルタイムの料金プレビューで、現在の入力での正確な料金を確認できます。
Qwen Imageにはどのバリアントがありますか?
WaveSpeedAIでは、21個のQwen Imageエンドポイントが利用可能です:wavespeed-ai/qwen-image-2.0/edit, wavespeed-ai/qwen-image-2.0-pro/edit, wavespeed-ai/qwen-image-2.0/text-to-image, wavespeed-ai/qwen-image-2.0-pro/text-to-image, wavespeed-ai/qwen-image/edit-2509-multiple-angles, wavespeed-ai/qwen-image-max/edit, wavespeed-ai/qwen-image-max/text-to-image, wavespeed-ai/qwen-image/edit-multiple-anglesほか。各バリアントには、専用のプレイグラウンドページと料金があります。
Qwen Imageの出力を商用利用できますか?
商用利用の権利は、Alibabaのモデルライセンスに従います。Alibabaのほとんどのモデルは出力の商用利用を認めています。具体的なライセンスの概要は各モデルのプレイグラウンドページで、プラットフォーム全体の条件はWaveSpeedAIの利用規約でご確認ください。
なぜ直接ではなくWaveSpeedAIでQwen Imageを使うのですか?
Qwen Imageと、他のプロバイダーの1,000以上のAIモデルを、1つのAPIキー、1つの請求アカウントで利用できます。ベンダーごとのSDK設定も、個別のレート制限も、ベンダーごとの連携コードの書き直しも不要です。料金は、通常Alibabaの直接のAPIと同等かそれ以下です。
提供元
Alibabaについて
WaveSpeedAIにおけるQwen Imageと、Alibabaのモデルラインナップ全体を手がけるチーム。
Alibaba の Tongyi Lab は、動画モデルの Wan ファミリーと、LLM の Qwen ファミリーを開発しています。Wan は、オープンウェイトで公開されていること、幅広いバリアント(テキストから動画、画像から動画、リファレンスから動画、video-edit、video-extend、image-edit、text-to-image)を網羅していること、多言語のプロンプトにわたってモーションの安定性とプロンプトへの追従性に一貫して強みがあることが特長です。
WaveSpeedAIでQwen Imageを使った開発を始めよう
登録時に無料のスタータークレジットを進呈。Alibabaをはじめ、あらゆるプロバイダーの1,000以上のAIモデルを、1つのAPIキーで。