FLUX 3 Text-to-Image generates high-quality images from text prompts with detailed composition, strong typography, and flexible 1K / 2K / 4K output for creative visuals, marketing assets, product imagery, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.05per run·~20 / $1
ExamplesView all
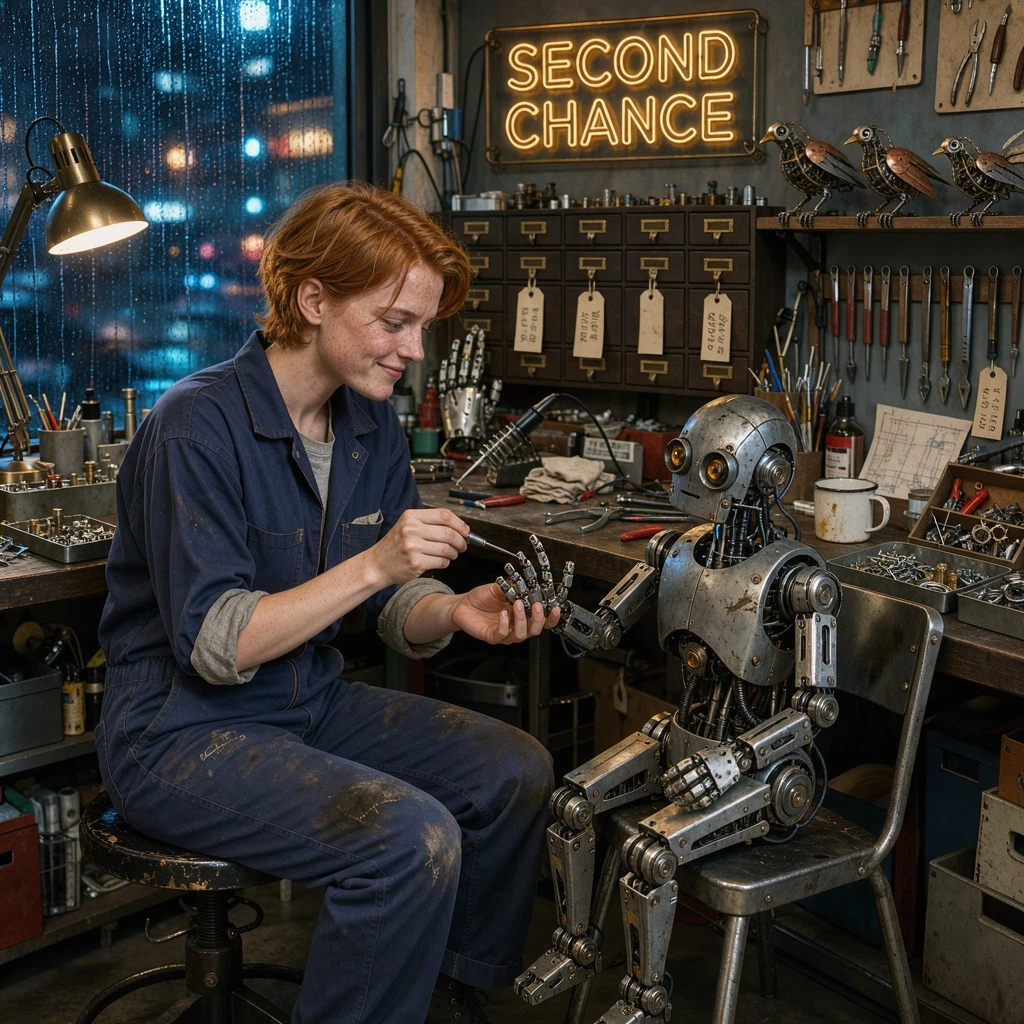
A cinematic editorial photograph inside a tiny robot repair shop on a rainy night. A young female mechanic with short copper hair, freckles, and rolled-up navy coveralls sits at her cluttered workbench, carefully repairing the delicate mechanical hand of a small robot seated opposite her. She has a focused expression with a faint, reassuring smile. The robot watches her with curious amber eyes. Behind them, a warm neon sign clearly reads “SECOND CHANCE”. Drawers of tiny components, handwritten repair tags, polished tools, and half-finished mechanical birds fill the workshop. Rain streaks the front window, reflecting cool city lights against the warm desk lamp. Natural human anatomy, intricate mechanical joints, convincing worn metal and fabric textures, intimate cinematic atmosphere.
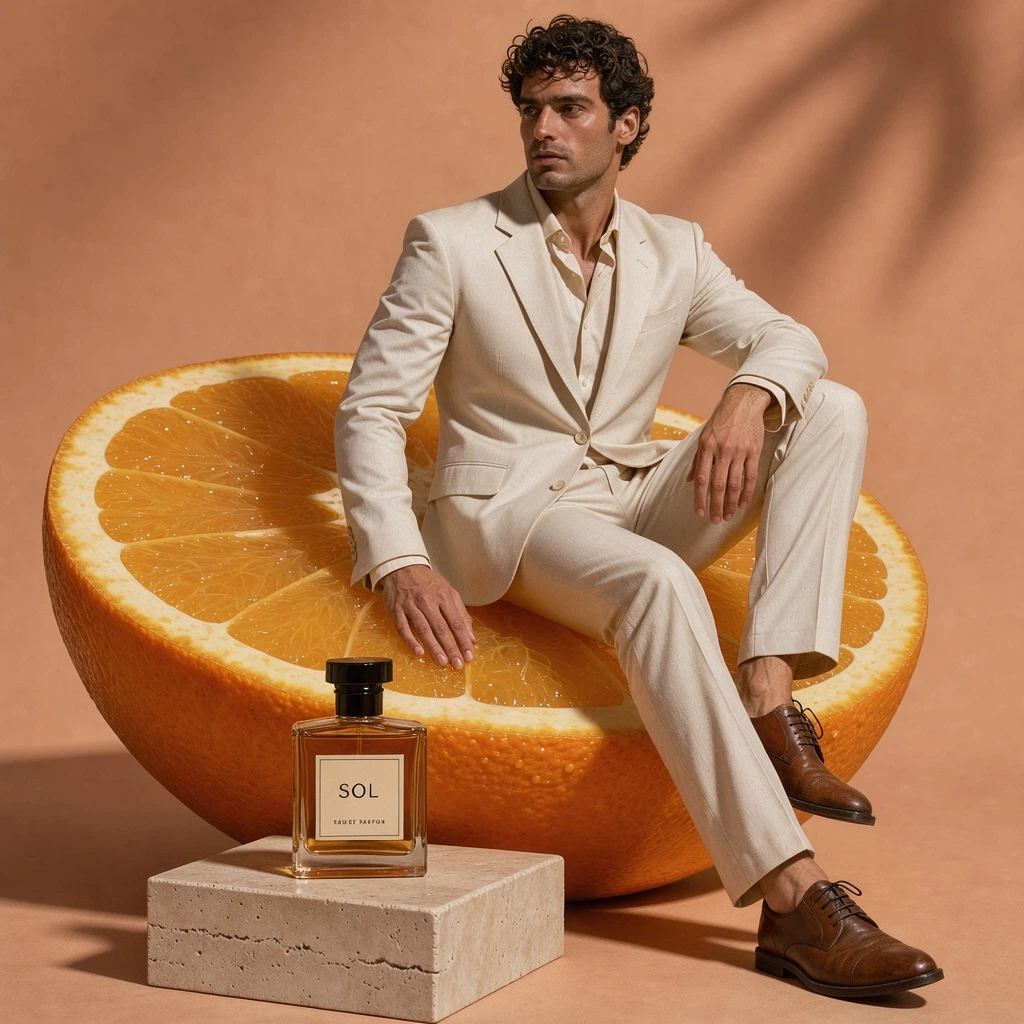
A surreal luxury fragrance campaign photographed like a real fashion editorial. A stylish male model with curly dark hair and a sharply tailored cream suit sits casually on the curved peel of an enormous freshly cut orange. His posture is relaxed and confident, one hand resting beside him, his gaze directed just past the camera. On a small travertine pedestal in the foreground stands an amber glass perfume bottle with a crisp minimalist label reading “SOL” and smaller text reading “EAU DE PARFUM”. The giant orange reveals translucent citrus pulp, tiny droplets, and richly textured peel. Soft botanical shadows fall across a pale terracotta studio background. Warm side lighting, elegant negative space, realistic skin texture, subtle film grain, sophisticated commercial art direction.
Related Models
README
FLUX 3 Text-to-Image
FLUX 3 Text-to-Image generates detailed images directly from text prompts with strong composition control, typography support, and output resolutions up to 4K. Describe the subject, layout, lighting, materials, visual style, and any text that should appear in the image, then choose the aspect ratio and resolution that fit your workflow.
It is designed for advertising concepts, product visuals, posters, editorial artwork, social content, and other image-generation tasks where composition and text placement matter.
Why Choose This?
-
Detailed text-to-image generation
Create high-quality images directly from natural-language descriptions. -
Up to 4K output
Choose1K,2K, or4Kdepending on your quality and production requirements. -
Typography and layout control
Describe exact text, placement, hierarchy, and surrounding composition in the prompt. -
Flexible aspect ratios
Generate square, portrait, landscape, widescreen, and ultrawide compositions. -
Prompt expansion
Enable automatic prompt expansion when you want additional interpretation while preserving the intended content. -
JPEG and PNG output
Choose the output format that fits your publishing or editing workflow.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Text description of the image to generate. Must not be empty. |
| aspect_ratio | No | Output aspect ratio: 21:9, 2:1, 16:9, 3:2, 7:5, 4:3, 5:4, 1:1, 4:5, 3:4, 5:7, 2:3, 9:16, or 1:2. Default: 1:1. |
| resolution | No | Output resolution tier: 1k, 2k, or 4k. Default: 1k. |
| enable_prompt_expansion | No | Expand the prompt while preserving the intended content. Default: false. |
| output_format | No | Output image format: jpeg or png. Default: jpeg. |
How to Use
- Write a prompt — Describe the subject, scene, composition, lighting, materials, and visual style.
- Specify text optional — Put exact words in quotation marks and describe where they should appear.
- Choose aspect ratio — Select the layout that fits your target composition.
- Choose resolution — Use
1k,2k, or4k. - Configure prompt expansion optional — Enable it when you want the prompt expanded automatically.
- Choose output format — Select
jpegorpng. - Submit — Generate the image and retrieve the result.
Pricing
Pricing is based only on the selected resolution.
| Resolution | Price per Image |
|---|---|
| 1K | $0.05 |
| 2K | $0.12 |
| 4K | $0.65 |
Best Use Cases
- Advertising creatives — Generate campaign concepts, key visuals, and promotional imagery.
- Product imagery — Create product concepts, presentation visuals, and packaging ideas.
- Poster design — Generate compositions with integrated text, hierarchy, and strong visual layout.
- Editorial artwork — Create illustrations, covers, and publication visuals.
- Social media content — Produce square, vertical, landscape, and widescreen creative assets.
- Typography-heavy concepts — Generate images where text placement and visual composition are important.
- High-resolution artwork — Use
2Kor4Kwhen additional detail is needed for final production.
Pro Tips
- Put exact image text in quotation marks.
- Describe where text should appear relative to the subject and other visual elements.
- Start with the main subject and composition before adding stylistic details.
- Describe lighting, materials, color palette, and environment when they matter.
- Use
1Kfor lower-cost concept iteration before moving to higher resolutions. - Use
4Kwhen final output detail is more important than generation cost. - Enable prompt expansion when a short prompt needs more descriptive interpretation.
- Choose
pngwhen you want to avoid additional JPEG compression.
Related Models
- FLUX 3 Text-to-Image — Generate images from text prompts with flexible composition and resolutions up to 4K.
- FLUX 3 Edit — Edit and combine input images with natural-language instructions.
Flux 3 Text To Image API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/black-forest-labs/flux-3/text-to-image with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Flux 3 Text To Image below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "1k",
    "output_format": "jpeg",
    "enable_prompt_expansion": false
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/black-forest-labs/flux-3/text-to-image" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/black-forest-labs/flux-3/text-to-image";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "aspect_ratio": "1:1",
        "resolution": "1k",
        "output_format": "jpeg",
        "enable_prompt_expansion": false
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "1k",
    "output_format": "jpeg",
    "enable_prompt_expansion": False
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/black-forest-labs/flux-3/text-to-image", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Flux 3 Text To Image API — Frequently asked questions
What is the Flux 3 Text To Image API?
Flux 3 Text To Image is a Black Forest Labs model for image generation, exposed as a REST API on WaveSpeedAI. FLUX 3 Text-to-Image generates high-quality images from text prompts with detailed composition, strong typography, and flexible 1K / 2K / 4K output for creative visuals, marketing assets, product imagery, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Flux 3 Text To Image API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/black-forest-labs/black-forest-labs-flux-3-text-to-image.
How much does Flux 3 Text To Image cost per run?
Flux 3 Text To Image starts at $0.05 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Flux 3 Text To Image accept?
Key inputs: `prompt`, `aspect_ratio`, `resolution`, `enable_prompt_expansion`, `output_format`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/black-forest-labs/black-forest-labs-flux-3-text-to-image.
How do I get started with the Flux 3 Text To Image API?
Sign up for a free WaveSpeedAI account to claim starter credits, copy your API key from /accesskey, then call the endpoint shown in the API tab of the playground. The playground also auto-generates a code sample in Python, JavaScript, or cURL for the parameters you've set.
Can I use Flux 3 Text To Image outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (Black Forest Labs). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from Black Forest Labs
View all- black-forest-labs/flux-3/editImage to Image
- black-forest-labs/flux-3/image-to-videoImage to Video
- black-forest-labs/flux-3/image-to-video-draftImage to Video
- black-forest-labs/flux-3/start-end-to-videoImage to Video
- black-forest-labs/flux-3/start-end-to-video-draftImage to Video
- black-forest-labs/flux-3/text-to-videoText to Video
- black-forest-labs/flux-3/text-to-video-draftText to Video
- black-forest-labs/flux-3/video-editVideo to Video
More Text to Image models
View all- bytedance/seedream-v5.0-proText to Image
- openai/gpt-image-2/text-to-imageText to Image
- google/nano-banana-pro/text-to-imageText to Image
- google/nano-banana-2/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- bytedance/seedream-v4.5Text to Image
- alibaba/wan-2.7/text-to-imageText to Image
- alibaba/qwen-image-3.0/text-to-imageText to Image