Avatar Lipsync Models
WaveSpeedAI's AI Avatars delivers lifelike virtual characters with advanced lip sync and realistic expressions.
我們的選擇
bytedance/seedance-2.5/talking-avatar
Seedance 2.5 Talking Avatar animates a portrait image from an audio recording to generate natural talking-avatar videos in 480P or 720P, processing up to the first 120 seconds of audio for digital human, presenter, dubbing, and avatar workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
所有模型
51 個模型
bytedance/seedance-2.5/talking-avatar
Seedance 2.5 Talking Avatar animates a portrait image from an audio recording to generate natural talking-avatar videos in 480P or 720P, processing up to the first 120 seconds of audio for digital human, presenter, dubbing, and avatar workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/wan-2.2/animate-2
Wan 2.2 Animate 2 is the next-generation Wan character animation model: an end-to-end DiT that makes the character in a reference image perform the motion of a driving video, with no pose extraction, prompt-controlled background, and strong identity preservation; generates 480p/720p videos up to 120s. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk/multi
InfiniteTalk Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk
InfiniteTalk Image-to-Video converts a single photo and audio track into long-form audio-driven talking or singing avatar videos, supporting up to 10 minutes, 720P output, natural lip sync, expressive motion, and digital human video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
pruna-ai/p-video/avatar
Pruna AI P-Video Avatar is a fast AI avatar video generation model that creates high-quality avatar videos for digital humans, talking characters, social media content, marketing creatives, virtual presenters, and AI video workflows. Ready-to-use REST inference API with simple integration, no coldstarts, and affordable pricing.
heygen/avatar-v/digital-twin
HeyGen Avatar V Digital Twin is a fast AI avatar video generation model that creates natural digital twin videos from text or audio with lip-sync, optional captions, background removal, and MP4/WebM output. Ready-to-use REST inference API for digital humans, virtual presenters, product explainers, marketing videos, training content, social media clips, and professional avatar video workflows with simple integration, no coldstarts, and affordable pricing.
wavespeed-ai/music-video-generator
AI Music Video Generator transforms audio + a single photo into a full music video with cinematic camera angles, smooth transitions, and perfect lip sync. Up to 10 minutes, 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk/video-to-video
Audio-driven InfiniteTalk turns one video plus audio into realistic talking or singing videos with lip-sync in 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-3/avatar
Sync Lipsync 3 Avatar turns a single still image and an input audio track into a lip-synced talking character video, with natural mouth movement, facial animation, and stable avatar performance. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/longcat-avatar-1.5/multi
LongCat Avatar 1.5 Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p, capped at 64 seconds per clip. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/longcat-avatar-1.5
LongCat Avatar 1.5 is the upgraded LongCat Avatar with sharper lip sync and faster generation. Converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), capped at 64 seconds per clip, 720p tier $0.40/5s. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast
InfiniteTalk fast converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), up to 10 minutes. Ready-to-use REST API, no coldstarts, affordable pricing.
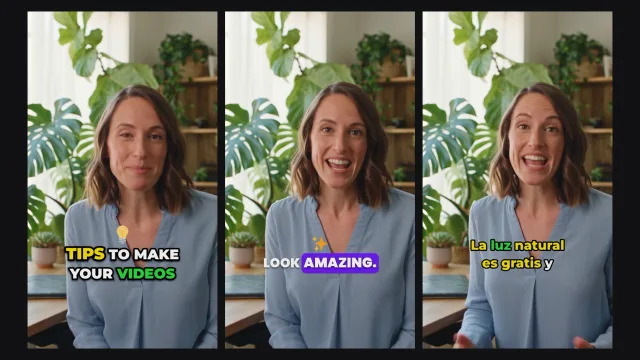
wavespeed-ai/ai-video-editor/video-captioner
AI Video Captioner adds animated, word-by-word captions to any talking video: 12 caption styles, AI keyword highlights, matching emoji, optional silence and filler removal, about 100 languages with translation, plus an SRT subtitle file. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/ai-video-editor/talking-head
AI Video Editor Talking Head cleans up a talking-to-camera video: it removes filler words, false starts, repeats and dead air, keeps the speaker framed, and burns in accurate word-timed captions. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

kwaivgi/kling-lipsync/audio-to-video
Kling LipSync converts audio into talking head video by generating lifelike lip movements perfectly synced to the input audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-lipsync/text-to-video
Kling TextToVideo by Kwaivgi creates videos with lifelike lip movements that precisely sync to input text for natural speaking visuals. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v2-ai-avatar-standard
Kling AI Avatar generates high-quality AI avatar videos for profiles, intros, and social content, delivering clean detail and cinematic motion with reliable prompt adherence. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast/multi
InfiniteTalk fast multi converts a single image and two audio inputs into multi-character talking or singing videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/infinitetalk/video-to-video-multi
InfiniteTalk Video-to-Video Multi converts a video and two audio inputs into multi-character talking or singing videos at up to 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v2-ai-avatar-pro
Kling V2 AI Avatar Pro generates high-quality AI avatar videos with clean detail, stable motion, and strong identity consistency—ideal for profiles, intros, and social content. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v1-ai-avatar-standard
Kling AI Avatar produces stunning AI-generated video avatars for digital identity and content creation, with on-demand video billed at $0.25 per 5 seconds. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/infinitetalk-fast/video-to-video
Audio-driven infinitetalk-fast turns one video plus audio into realistic talking or singing videos with lip-sync. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v1-ai-avatar-pro
Kling AI Avatar Pro converts audio into talking video portraits; pricing is $1 for the first 5s then $0.20/s up to 600s. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/infinitetalk-fast/video-to-video-multi
InfiniteTalk fast video-to-video multi converts a video and two audio inputs into multi-character talking or singing videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
veed/lipsync-v2
VEED Lipsync V2 generates production-quality lip-synced videos from a source video and a replacement audio track, matching mouth movements to the new audio for dubbing, localization, creator content, and talking-video workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

bytedance/avatar-omni-human-1.5
OmniHuman 1.5 converts audio and visual cues into lifelike avatar animations for virtual humans, storytelling, and interactive agents. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
veed/lipsync
Generate realistic lip-sync animations from audio with high-quality synchronization using Veed LipSync; $0.15 per 5s of video. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

wavespeed-ai/latentsync
LatentSync synchronizes video and audio inputs to generate seamless synchronized content. Perfect for lip-syncing, audio dubbing, and video-audio alignment tasks.
veed/fabric-1.0
VEED Fabric 1.0 turns one image into dynamic, talking videos and AI avatars in 480p or 720p (starts at $0.35/5s 480p, $0.7/5s 720p). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/wan-2.2/animate
Wan2.2-Animate unified character animation & replacement model replicating movement and expression; generates 720p videos up to 120s. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/steady-dancer
SteadyDancer is a 14B-parameter human image animation framework that transforms static images into coherent dance videos. Features first-frame preservation, robust identity consistency, and temporal coherence for realistic motion generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/react-1
Sync React-1 is a production-grade video-to-video lip-sync model. It maps any speech track to a target face, producing phoneme-accurate visemes and smooth timing while preserving identity, head pose, lighting, and background. Supports emotion and intensity control, multilingual speech, and long takes for talking-head content. Built for stable production use with a ready-to-use REST API, no cold starts, and predictable pricing.

wavespeed-ai/longcat-avatar
LongCat Avatar produces super-realistic, lip-synchronized long video generation with natural dynamics and consistent identity. Converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), up to 2 minutes, 720p tier $0.40/5s. Ready-to-use REST API, no coldstarts, affordable pricing.
wavespeed-ai/ltx-2-19b/lipsync
LTX-2 Lipsync generates synchronized talking head videos from a reference image and audio input. Powered by the 19B DiT architecture, it produces high-fidelity lip-synced videos with natural head movements. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/soulx-flashhead
SoulX FlashHead enables real-time streaming talking head video generation from portrait image and audio with ultra-fast 96 FPS performance. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/skyreels-v3/talking-avatar
SkyReels V3 Talking Avatar is a 19B-parameter multimodal model that generates talking avatars from portrait and audio with precise lip sync, supporting up to 20 seconds at 720p resolution. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/ltx-2.3/lipsync
LTX-2.3 Lipsync generates talking head videos from audio with synchronized lip movements and natural facial expressions. Built on DiT-based architecture with improved audio-visual alignment quality. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
heygen/video-translate
HeyGen Video Translate: translate videos into 70+ languages and 175+ dialects with voice preservation and lip sync. Choose Speed at $0.04/sec or Precision at $0.08/sec. Supports videos up to 120 seconds.
wavespeed-ai/wan-2.1/mocha
Wan 2.1 MoCha Video-to-Video Character Swap replaces a video's character using reference images, preserving identity and motion without per-frame pose or depth maps for character replacement, avatar edits, creative videos, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-3
Sync Lipsync 3 synchronizes lip movements in any video to supplied audio using zero-shot lip-sync technology. Supports multiple sync modes for handling duration mismatches, works with live-action, 3D characters, and AI-generated avatars. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

pixverse/lipsync
PixVerse LipSync converts audio into realistic lip-sync animations with advanced algorithms for precise mouth movements and timing for video avatars. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/latentsync
LatentSync combines Stable Diffusion and TREPA for high-res end-to-end lip-sync, delivering precise, realistic mouth motions in generated videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/hunyuan-avatar
Hunyuan Avatar creates audio-driven talking or singing videos from one image + audio, in 480p/720p up to 120s (starts at $0.15/5s). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/multitalk
MultiTalk converts one image and audio into audio-driven talking/singing videos (Image-to-Video), supporting up to 10 minutes. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-1.9.0-beta
Generate realistic lip-sync animations from audio using advanced algorithms for high-quality facial synchronization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-2
Sync Lipsync-2 synchronizes lip movements in any video to supplied audio, enabling realistic mouth alignment for films, podcasts, games, or animations. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
sync/lipsync-2-pro
Lipsync-2-pro creates studio-grade lip synchronization for video-to-video editing in minutes, not weeks. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/wan-2.2/speech-to-video
Wan-2.2-S2V turns images and speech into high-fidelity videos with realistic face and body motion; supports up to 10-minute clips in 480p, from $0.15/5s. Ready-to-use REST API, no coldstarts, affordable pricing.

wavespeed-ai/wan-2.1/multitalk
MultiTalk (WAN 2.1) is an audio-driven AI that turns a single image and audio into talking or singing conversational videos. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/lipsync/audio-to-video
LipSync turns audio into lifelike talking videos by generating precise lip movements fully synced to input audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bytedance/avatar-omni-human
OmniHuman turns a single portrait photo into avatar video with lifelike motion and expressions ($0.12/sec). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Avatar Lipsync Models API — 價格與效能
透過單一 REST API 執行 Avatar Lipsync Models 系列中的任何模型。按生成計費 — 無訂閱、無最低消費 — 在可用率 99.9% 的基礎架構上提供業界領先的延遲。
為什麼在 WaveSpeedAI 上執行 Avatar Lipsync Models
透明的價格
每個 Avatar Lipsync Models 模型都採按呼叫計費。價格列在每個模型的頁面上 — 不會額外加收平台費。
為低延遲最佳化
大多數 Avatar Lipsync Models 影像模型在 2 秒內完成。影片與 3D 模型比自架方案快數倍。
99.9% 可用率
多區域故障轉移與自動重試可在供應商故障期間 — 仍將您的生產流量保持線上。
常見問題
Avatar Lipsync Models API 多少錢?+
每個模型在其模型頁面上都列有自己的按呼叫價格。我們按每次成功生成計費,沒有訂閱費或最低消費。
Avatar Lipsync Models 模型在 WaveSpeedAI 上有多快?+
本系列中的影像模型通常在 2 秒內完成。影片與 3D 模型取決於長度與解析度,但通常比自架執行快數倍。
不用信用卡可以試用 API 嗎?+
符合資格的新帳戶可能獲得 $1 的推廣額度,用於無需信用卡試用 Avatar Lipsync Models 模型。並非每次註冊都會獲得試用額度,請在生成前查看帳戶餘額。
有速率限制嗎?+
標準帳戶具有充足的並行任務限制。Enterprise 方案提供自訂 RPM、更高並行性和專屬容量 — 詳情請聯繫業務。