Object Detection and Segmentation
Detect, identify, and segment objects in images and videos with AI models on WaveSpeed
我们的选择
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
所有模型
18 个模型
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
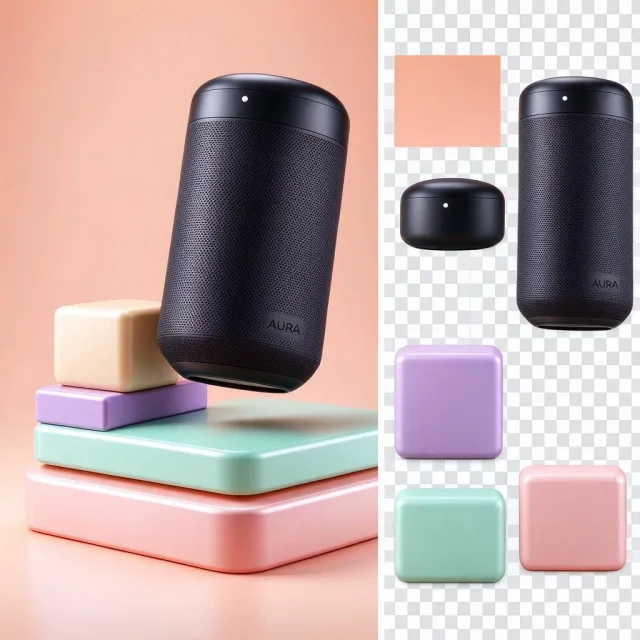
bytedance/seedream-v5.0-flash/layer-decomposition
Seedream V5.0 Flash Layer Decomposition separates a single image into a base image and transparent layers faster and at lower cost than Seedream V5.0 Pro, enabling flexible compositing, image editing, asset extraction, and layered design workflows at one price for 1K / 1.5K / 2K. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam3-video
SAM3 Video is a unified foundation model for prompt-based video segmentation. Provide text, point, box, or mask prompts and the model segments and tracks targets across frames with strong temporal consistency. Supports concept-level (“segment anything with concepts”) and multi-object masks for editing, analytics, and VFX. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
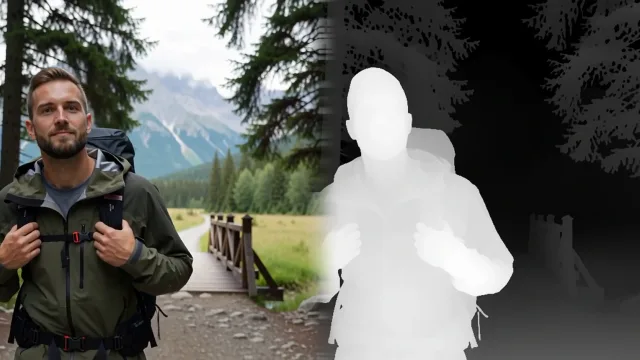
wavespeed-ai/depth-anything/video
Depth Anything Video estimates temporally consistent depth maps from video input, with stable depth across the whole clip and no flicker. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/moondream3-preview/point
Moondream3 Point finds objects in images and returns precise coordinate points for computer vision tasks, enabling accurate point localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/qwen-image/layered
Qwen-Image Layered is a unified image-layer decomposition model for prompt-guided compositing. Provide points, boxes, or rough masks to isolate subjects and regions, and the model splits a single image into multiple RGBA layers with clean alpha, soft edges, and correct occlusion order. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
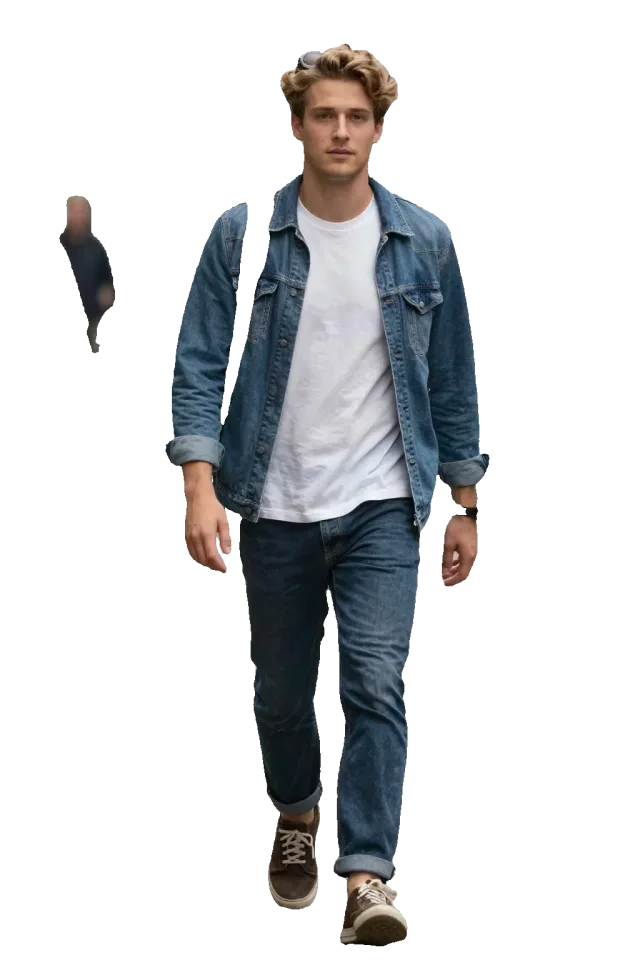
wavespeed-ai/sam3-image
SAM 3 is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
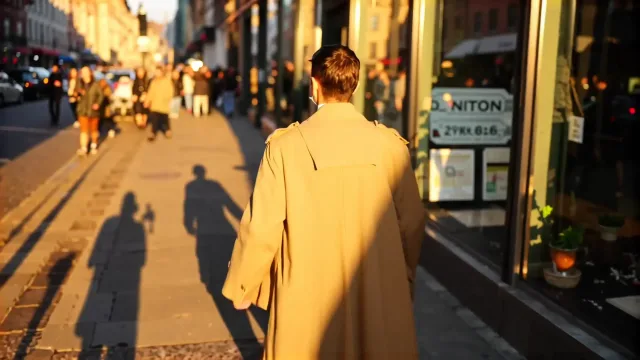
wavespeed-ai/sam3-video-rle
SAM 3 Video RLE is a unified foundation model for prompt-based segmentation in video. Track and segment objects across frames using text, points, or boxes, returning RLE encoded masks for efficient processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
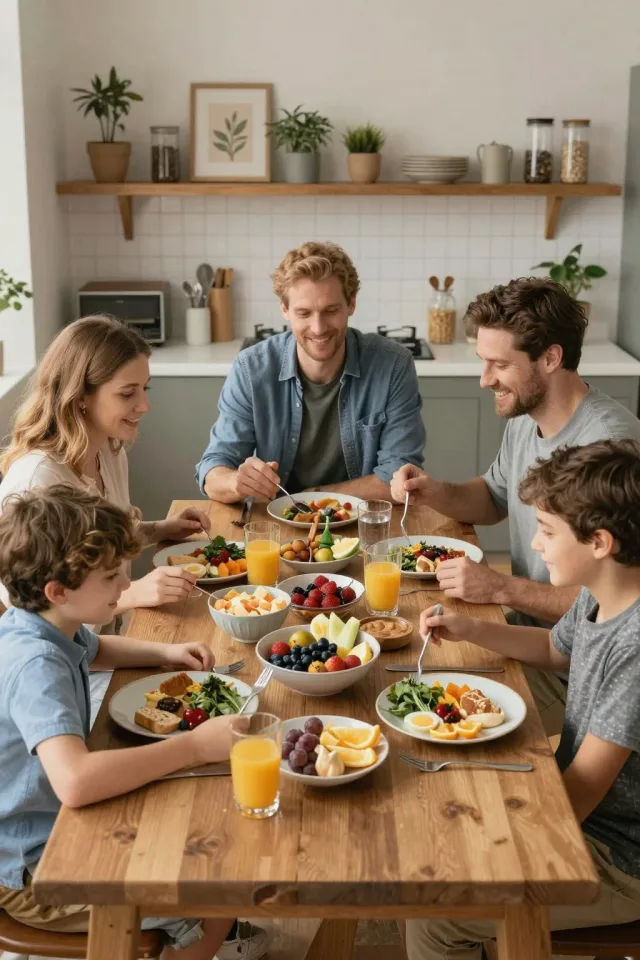
wavespeed-ai/sam3-image-rle
SAM 3 RLE is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Returns RLE (Run-Length Encoding) encoded masks for efficient storage and processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
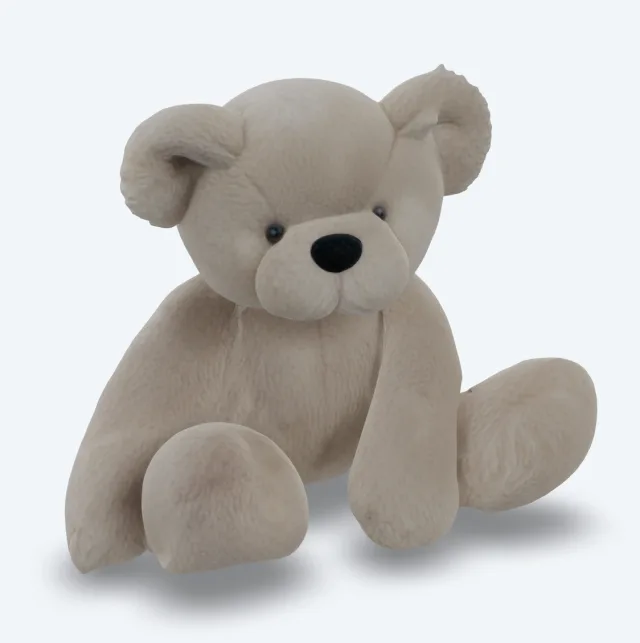
wavespeed-ai/sam-3d-objects
Advanced SAM 3D objects generation model for creating detailed 3D object models from images with text prompts and optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
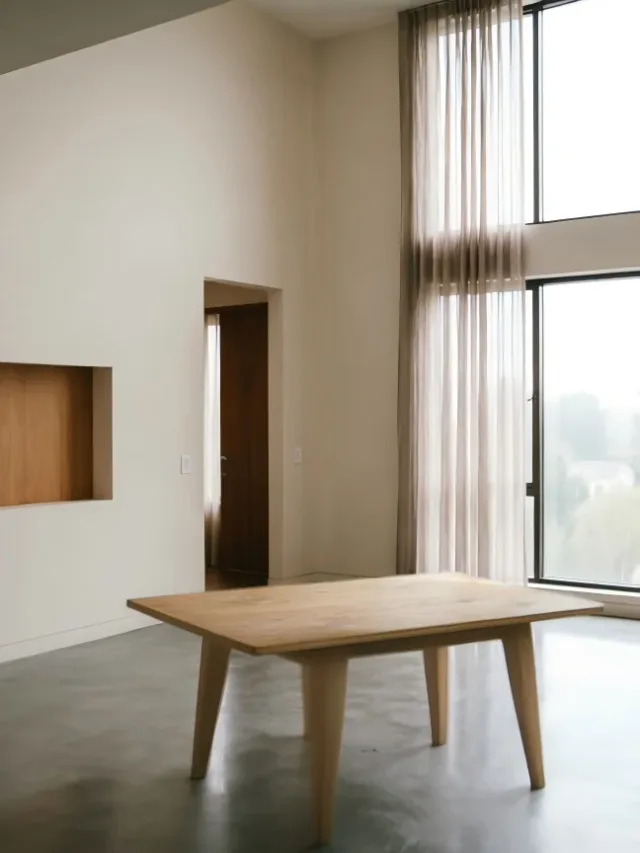
bria/embed-product
Bria Embed Product seamlessly integrates product images into scene backgrounds with natural lighting and perspective matching. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
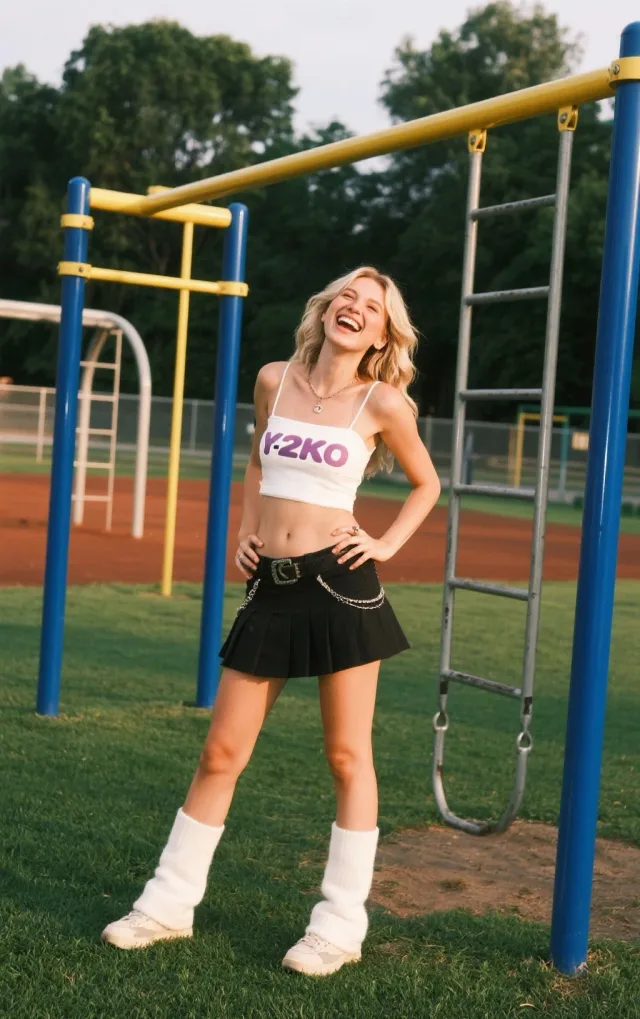
wavespeed-ai/moondream3-preview/detect
Moondream3 Detect: Precise object bounding boxes in images for accurate computer vision localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
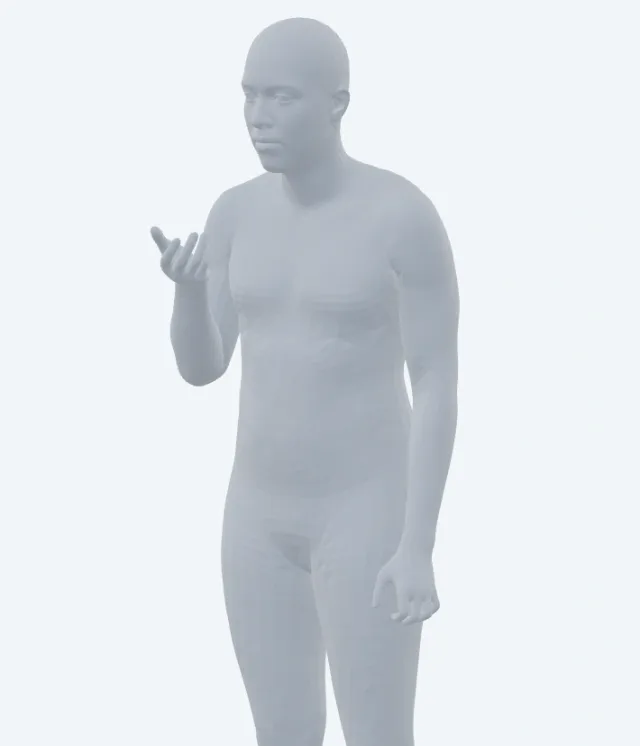
wavespeed-ai/sam-3d-body
Advanced SAM 3D body generation model for creating detailed 3D human body models from images with optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bria/ad-delayer
Bria Ad Delayer splits flat advertisement images into editable image, text, and vector layers, returning a complete structured layer document as JSON for ad editing, localization, redesign, marketing creatives, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
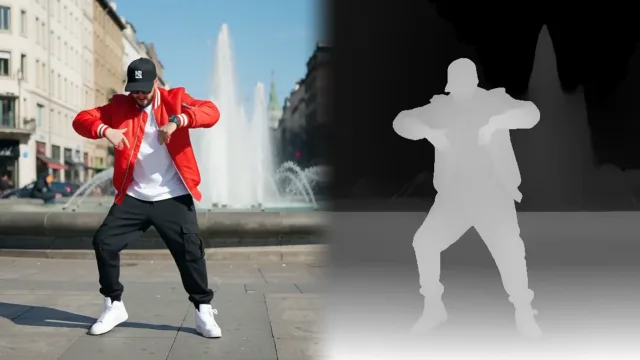
wavespeed-ai/depth-anything-v3/video
Depth Anything V3 Video turns any video into a temporally consistent depth map video with no flicker, ideal for replicating camera moves and motion with depth-controlled video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
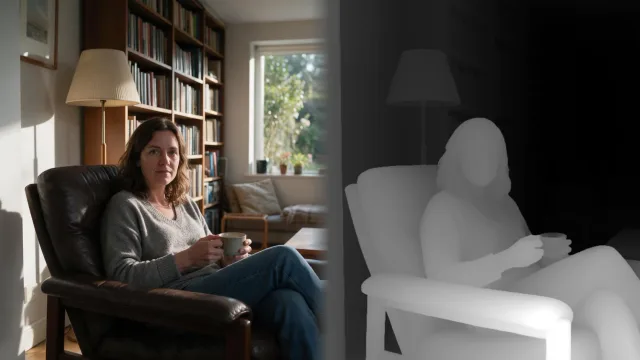
wavespeed-ai/depth-anything-v3/image
Depth Anything V3 Image estimates a sharp, detailed depth map from a single image, ready for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
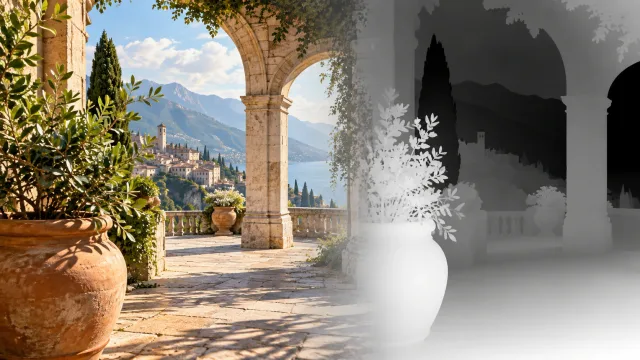
wavespeed-ai/depth-anything/image
Depth Anything Image turns a single image into a detailed grayscale depth map for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
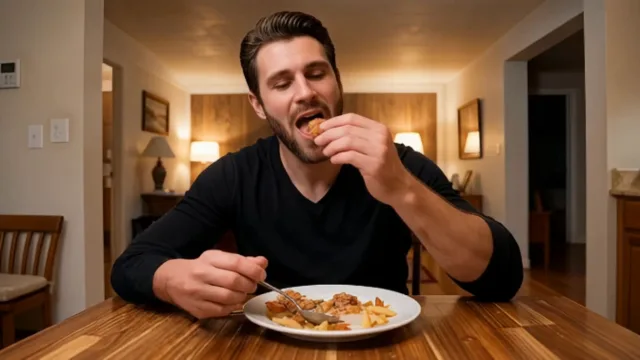
wavespeed-ai/void-video-inpainting/mask
VOID Video Inpainting removes objects from videos using mask-guided inpainting. Supports quad-mask or auto-generated SAM-3 masks, optional Pass 2 refinement for temporal consistency, adjustable denoising steps, guidance scale, and temporal window size. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Object Detection and Segmentation API — 价格与性能
通过单一 REST API 运行 Object Detection and Segmentation 系列中的任意模型。按生成计费 — 无订阅、无最低消费 — 在 99.9% 可用性的基础设施上提供行业领先的延迟。
为什么在 WaveSpeedAI 上运行 Object Detection and Segmentation
透明定价
每个 Object Detection and Segmentation 模型都有按调用计价。价格在每个模型的页面上列出 — 不收取额外的平台费。
为低延迟优化
大多数 Object Detection and Segmentation 图像模型在 2 秒内完成。视频和 3D 模型比自托管方案快数倍。
99.9% 可用性
多区域故障转移和自动重试可确保您的生产流量保持在线 — 即使在供应商故障期间。
常见问题
Object Detection and Segmentation API 多少钱?+
每个模型在其模型页面上都列有自己的按调用价格。我们按每次成功生成计费,没有订阅费或最低消费。
Object Detection and Segmentation 模型在 WaveSpeedAI 上有多快?+
本系列中的图像模型通常在 2 秒内完成。视频和 3D 模型取决于时长和分辨率,但通常比自托管运行快数倍。
不用信用卡可以试用 API 吗?+
符合条件的新账户可能获得 $1 的推广额度,用于无需信用卡试用 Object Detection and Segmentation 模型。并非每次注册都会获得试用额度,请在生成前查看账户余额。
有速率限制吗?+
标准账户有充足的并发任务限制。企业版计划提供自定义 RPM、更高并发和专用容量 — 详情请联系销售。