Object Detection and Segmentation
Detect, identify, and segment objects in images and videos with AI models on WaveSpeed
추천
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
전체 모델
18개 모델
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
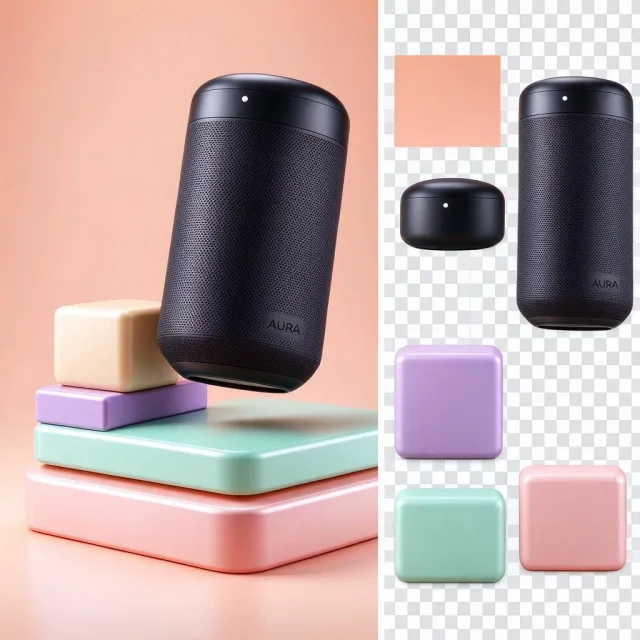
bytedance/seedream-v5.0-flash/layer-decomposition
Seedream V5.0 Flash Layer Decomposition separates a single image into a base image and transparent layers faster and at lower cost than Seedream V5.0 Pro, enabling flexible compositing, image editing, asset extraction, and layered design workflows at one price for 1K / 1.5K / 2K. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam3-video
SAM3 Video is a unified foundation model for prompt-based video segmentation. Provide text, point, box, or mask prompts and the model segments and tracks targets across frames with strong temporal consistency. Supports concept-level (“segment anything with concepts”) and multi-object masks for editing, analytics, and VFX. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
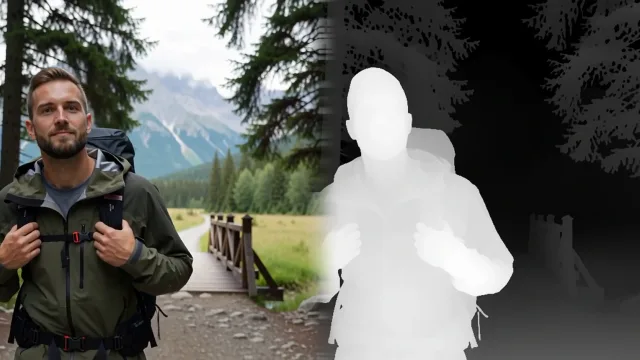
wavespeed-ai/depth-anything/video
Depth Anything Video estimates temporally consistent depth maps from video input, with stable depth across the whole clip and no flicker. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
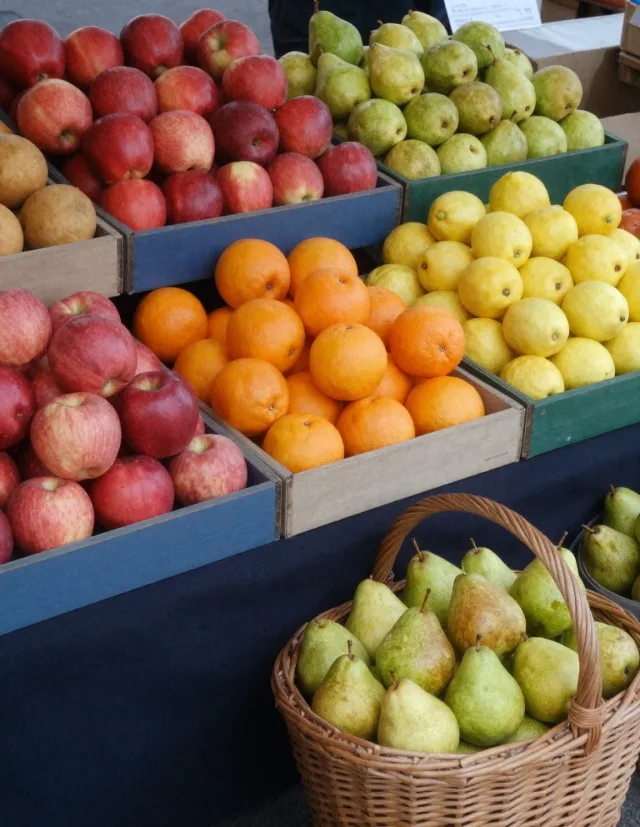
wavespeed-ai/moondream3-preview/point
Moondream3 Point finds objects in images and returns precise coordinate points for computer vision tasks, enabling accurate point localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
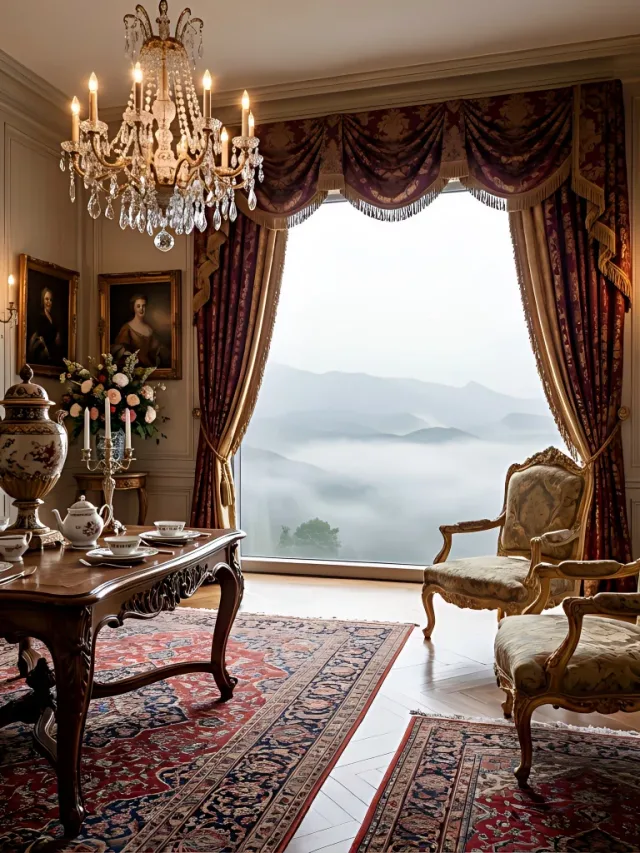
wavespeed-ai/qwen-image/layered
Qwen-Image Layered is a unified image-layer decomposition model for prompt-guided compositing. Provide points, boxes, or rough masks to isolate subjects and regions, and the model splits a single image into multiple RGBA layers with clean alpha, soft edges, and correct occlusion order. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
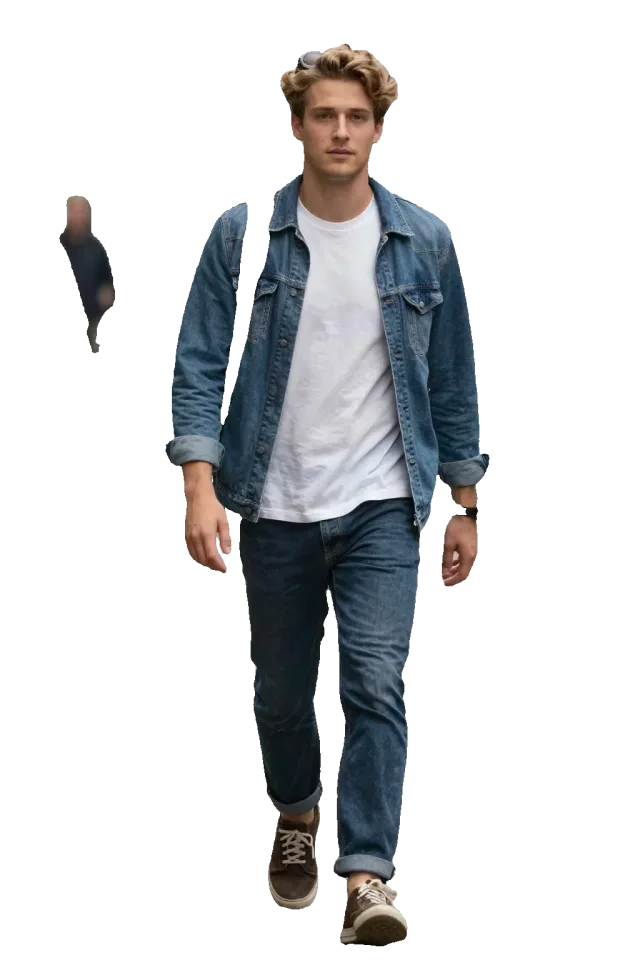
wavespeed-ai/sam3-image
SAM 3 is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
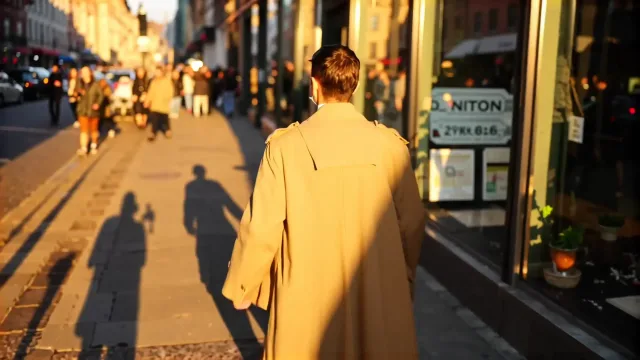
wavespeed-ai/sam3-video-rle
SAM 3 Video RLE is a unified foundation model for prompt-based segmentation in video. Track and segment objects across frames using text, points, or boxes, returning RLE encoded masks for efficient processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
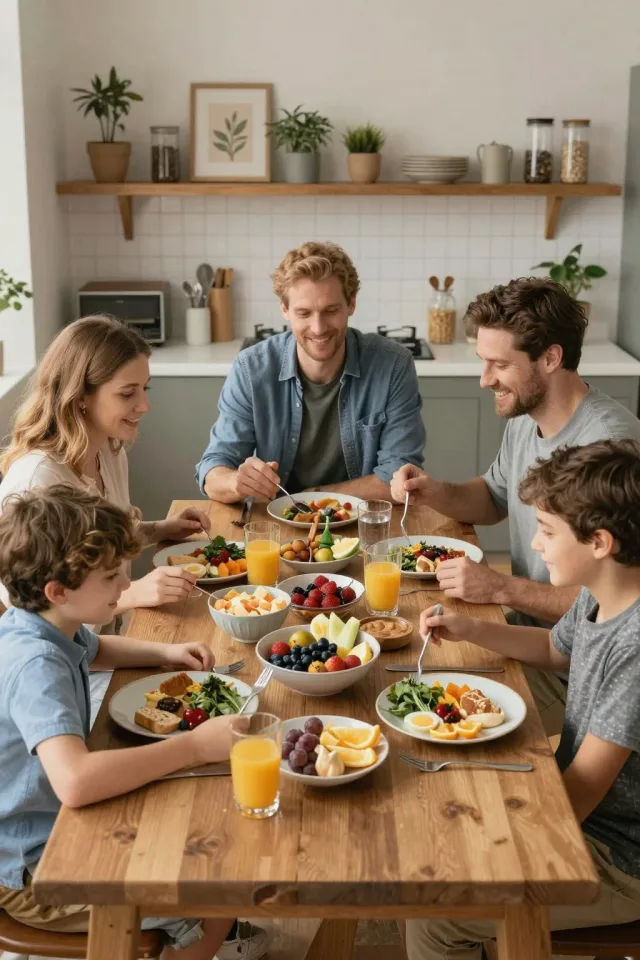
wavespeed-ai/sam3-image-rle
SAM 3 RLE is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Returns RLE (Run-Length Encoding) encoded masks for efficient storage and processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
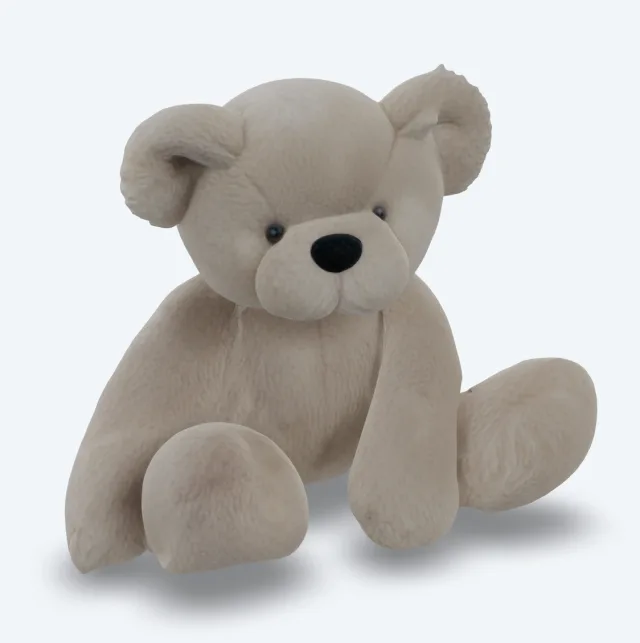
wavespeed-ai/sam-3d-objects
Advanced SAM 3D objects generation model for creating detailed 3D object models from images with text prompts and optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
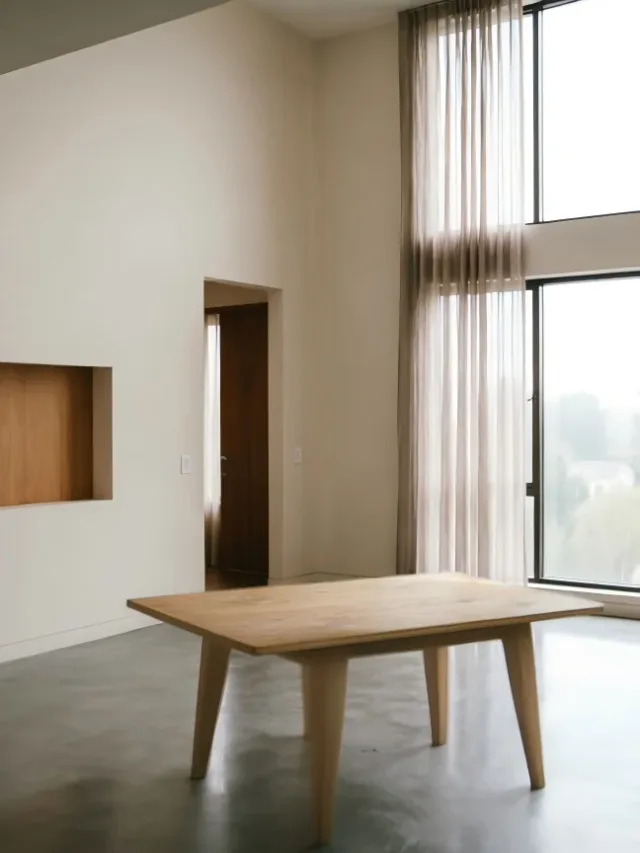
bria/embed-product
Bria Embed Product seamlessly integrates product images into scene backgrounds with natural lighting and perspective matching. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
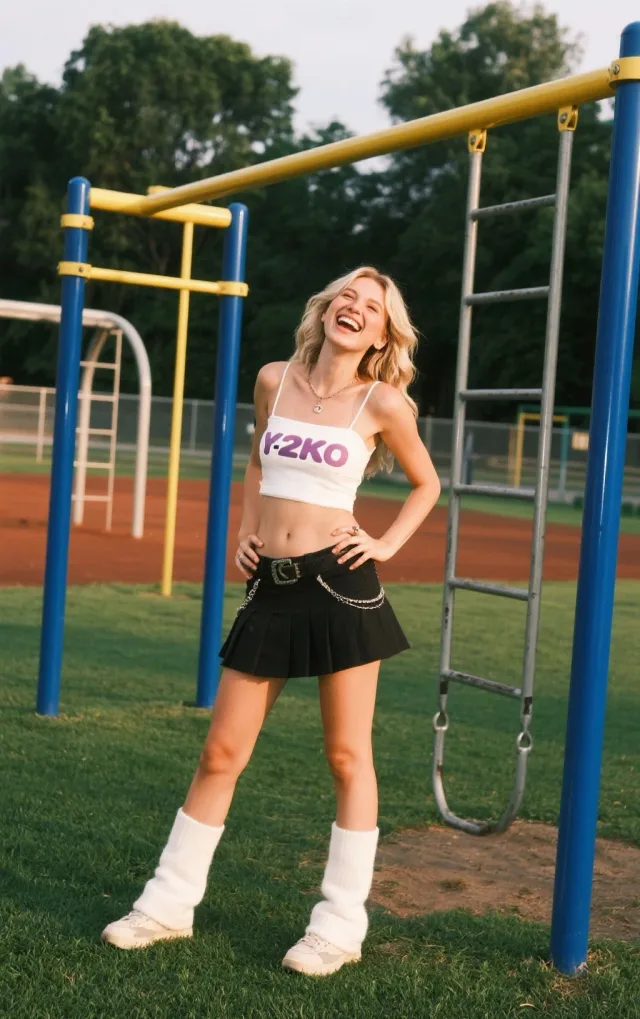
wavespeed-ai/moondream3-preview/detect
Moondream3 Detect: Precise object bounding boxes in images for accurate computer vision localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
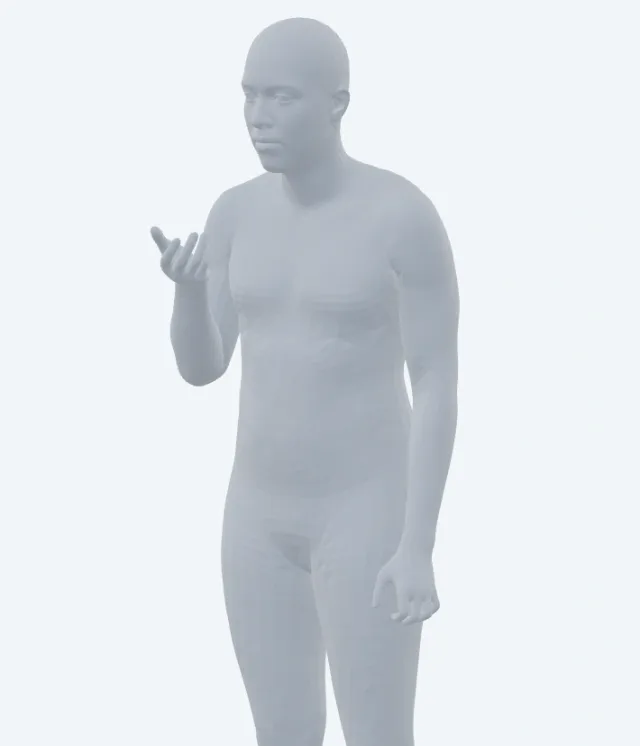
wavespeed-ai/sam-3d-body
Advanced SAM 3D body generation model for creating detailed 3D human body models from images with optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bria/ad-delayer
Bria Ad Delayer splits flat advertisement images into editable image, text, and vector layers, returning a complete structured layer document as JSON for ad editing, localization, redesign, marketing creatives, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
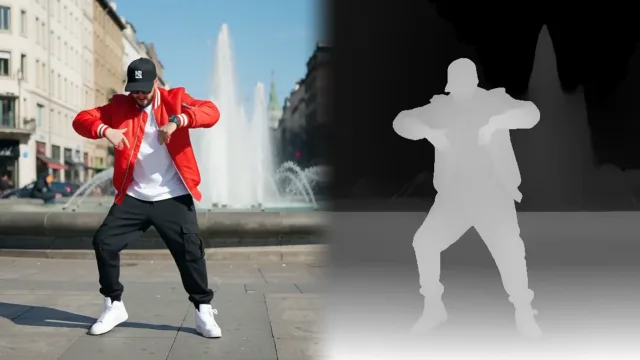
wavespeed-ai/depth-anything-v3/video
Depth Anything V3 Video turns any video into a temporally consistent depth map video with no flicker, ideal for replicating camera moves and motion with depth-controlled video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
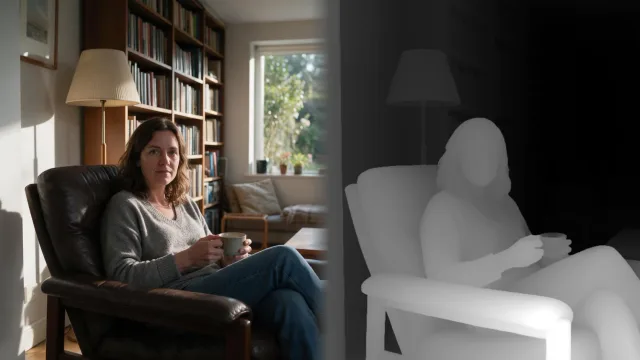
wavespeed-ai/depth-anything-v3/image
Depth Anything V3 Image estimates a sharp, detailed depth map from a single image, ready for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
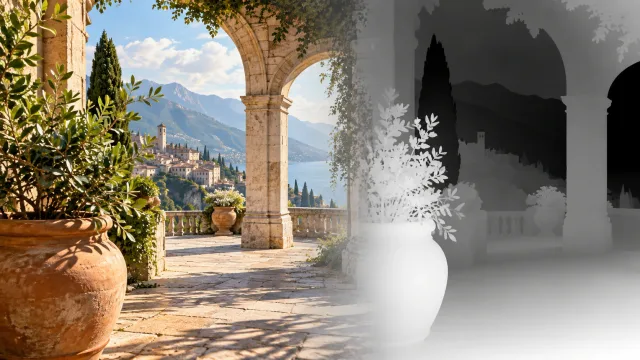
wavespeed-ai/depth-anything/image
Depth Anything Image turns a single image into a detailed grayscale depth map for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
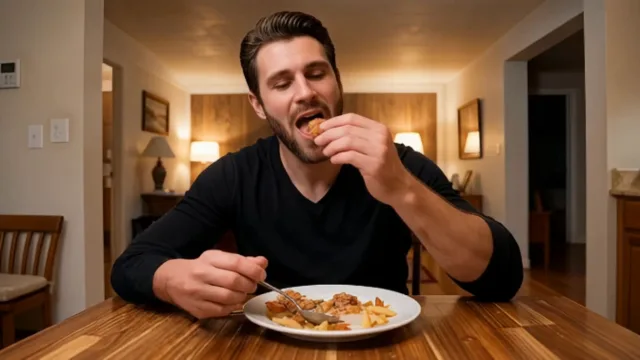
wavespeed-ai/void-video-inpainting/mask
VOID Video Inpainting removes objects from videos using mask-guided inpainting. Supports quad-mask or auto-generated SAM-3 masks, optional Pass 2 refinement for temporal consistency, adjustable denoising steps, guidance scale, and temporal window size. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Object Detection and Segmentation API — 가격 및 성능
Object Detection and Segmentation 컬렉션의 모든 모델을 단일 REST API로 실행하세요. 생성당 과금 — 구독 없음, 최소 요금 없음 — 99.9% 가동률 인프라에서 업계 최고의 지연 시간을 제공합니다.
WaveSpeedAI에서 Object Detection and Segmentation을 사용하는 이유
투명한 가격
모든 Object Detection and Segmentation 모델에 대한 호출당 가격. 가격은 각 모델 페이지에 표시되며 플랫폼 수수료는 추가되지 않습니다.
낮은 지연 시간에 최적화
대부분의 Object Detection and Segmentation 이미지 모델은 2초 이내에 완료됩니다. 비디오 및 3D 모델은 셀프 호스팅 대안보다 몇 배 더 빠릅니다.
99.9% 가동률
다중 리전 페일오버와 자동 재시도로 프로바이더 장애 중에도 운영 트래픽을 온라인 상태로 유지합니다.
자주 묻는 질문
Object Detection and Segmentation API는 얼마인가요?+
각 모델에는 모델 페이지에 호출당 자체 가격이 표시되어 있습니다. 성공한 생성 단위로 청구되며 구독 요금이나 최소 요금은 없습니다.
WaveSpeedAI에서 Object Detection and Segmentation 모델은 얼마나 빠릅니까?+
이 컬렉션의 이미지 모델은 일반적으로 2초 이내에 완료됩니다. 비디오 및 3D 모델은 길이와 해상도에 따라 다르지만 보통 셀프 호스팅 실행보다 몇 배 더 빠릅니다.
신용카드 없이 API를 시험해 볼 수 있나요?+
조건을 충족하는 신규 계정은 신용카드 없이 Object Detection and Segmentation 모델을 체험할 수 있는 $1 프로모션 크레딧을 받을 수 있습니다. 모든 가입에 체험 크레딧이 보장되지는 않으므로 생성 전에 계정 잔액을 확인하세요.
속도 제한이 있나요?+
표준 계정에는 넉넉한 동시 작업 제한이 있습니다. Enterprise 플랜은 맞춤형 RPM, 더 높은 동시성, 전용 용량을 제공합니다 — 자세한 내용은 영업팀에 문의하세요.