Object Detection and Segmentation
Detect, identify, and segment objects in images and videos with AI models on WaveSpeed
おすすめ
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
すべてのモデル
18 モデル
bytedance/seedream-v5.0-pro/layer-decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
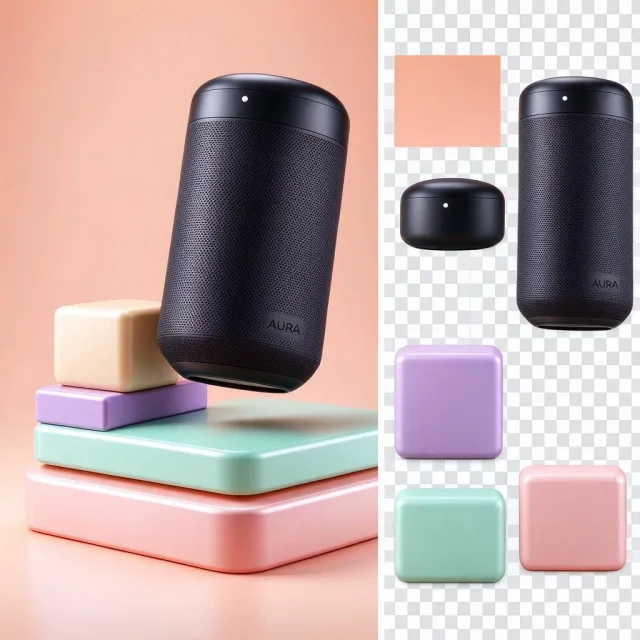
bytedance/seedream-v5.0-flash/layer-decomposition
Seedream V5.0 Flash Layer Decomposition separates a single image into a base image and transparent layers faster and at lower cost than Seedream V5.0 Pro, enabling flexible compositing, image editing, asset extraction, and layered design workflows at one price for 1K / 1.5K / 2K. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam3-video
SAM3 Video is a unified foundation model for prompt-based video segmentation. Provide text, point, box, or mask prompts and the model segments and tracks targets across frames with strong temporal consistency. Supports concept-level (“segment anything with concepts”) and multi-object masks for editing, analytics, and VFX. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
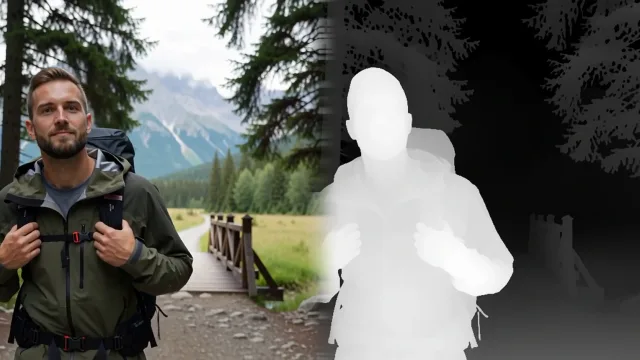
wavespeed-ai/depth-anything/video
Depth Anything Video estimates temporally consistent depth maps from video input, with stable depth across the whole clip and no flicker. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
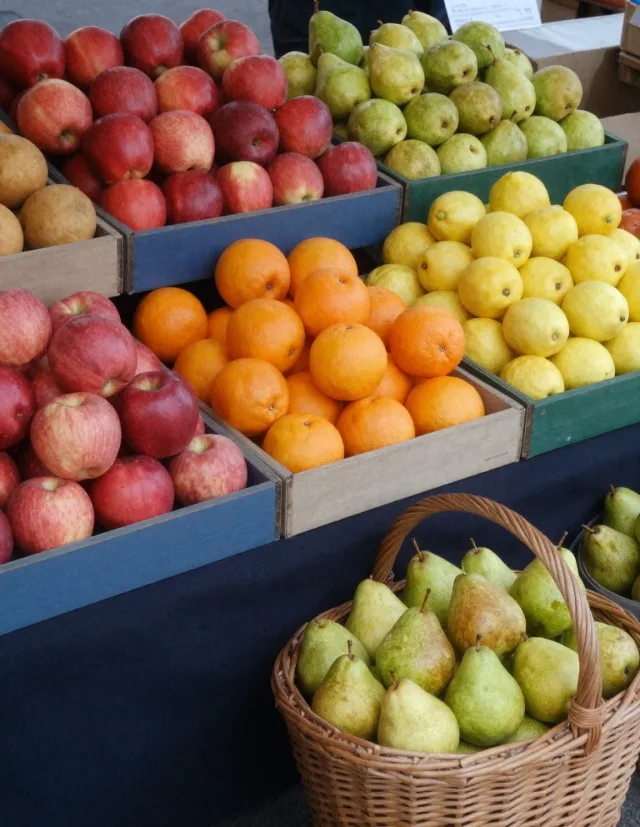
wavespeed-ai/moondream3-preview/point
Moondream3 Point finds objects in images and returns precise coordinate points for computer vision tasks, enabling accurate point localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
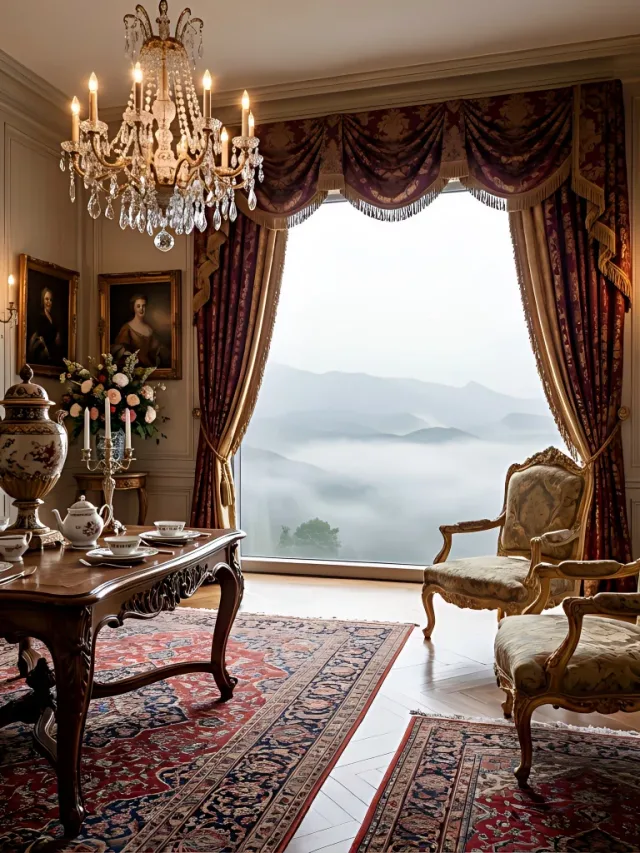
wavespeed-ai/qwen-image/layered
Qwen-Image Layered is a unified image-layer decomposition model for prompt-guided compositing. Provide points, boxes, or rough masks to isolate subjects and regions, and the model splits a single image into multiple RGBA layers with clean alpha, soft edges, and correct occlusion order. Ready-to-use REST inference API with fast response, no cold starts, and affordable pricing.
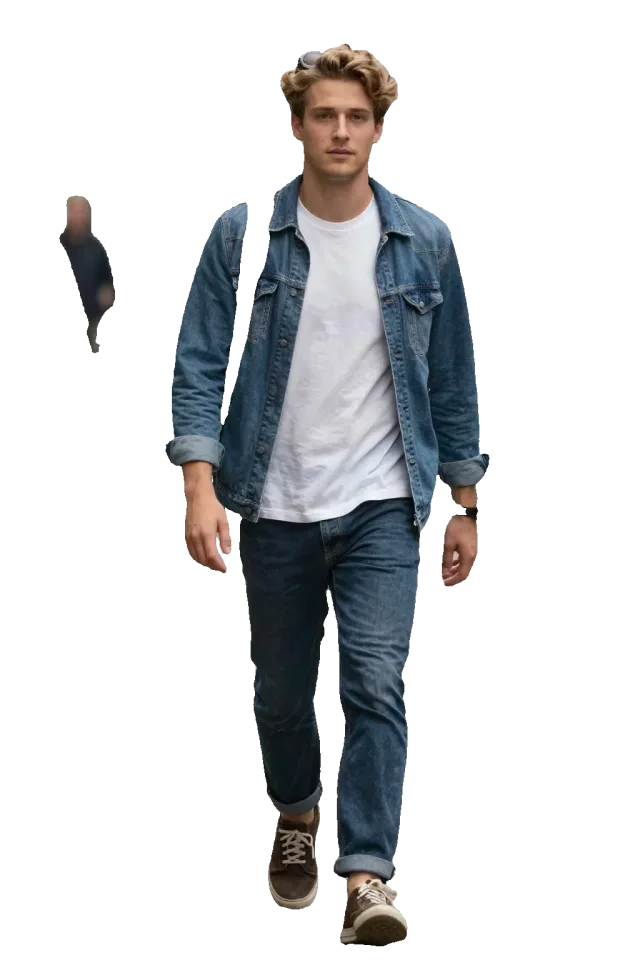
wavespeed-ai/sam3-image
SAM 3 is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam3-video-rle
SAM 3 Video RLE is a unified foundation model for prompt-based segmentation in video. Track and segment objects across frames using text, points, or boxes, returning RLE encoded masks for efficient processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam3-image-rle
SAM 3 RLE is a unified foundation model for promptable image segmentation using text, points, or boxes to detect and segment objects. Returns RLE (Run-Length Encoding) encoded masks for efficient storage and processing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam-3d-objects
Advanced SAM 3D objects generation model for creating detailed 3D object models from images with text prompts and optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bria/embed-product
Bria Embed Product seamlessly integrates product images into scene backgrounds with natural lighting and perspective matching. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/moondream3-preview/detect
Moondream3 Detect: Precise object bounding boxes in images for accurate computer vision localization. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
wavespeed-ai/sam-3d-body
Advanced SAM 3D body generation model for creating detailed 3D human body models from images with optional mask-based segmentation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
bria/ad-delayer
Bria Ad Delayer splits flat advertisement images into editable image, text, and vector layers, returning a complete structured layer document as JSON for ad editing, localization, redesign, marketing creatives, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
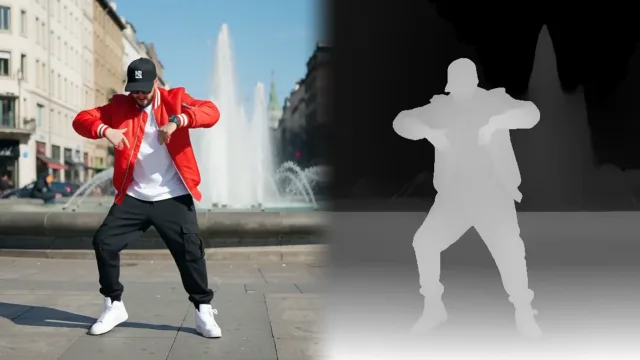
wavespeed-ai/depth-anything-v3/video
Depth Anything V3 Video turns any video into a temporally consistent depth map video with no flicker, ideal for replicating camera moves and motion with depth-controlled video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
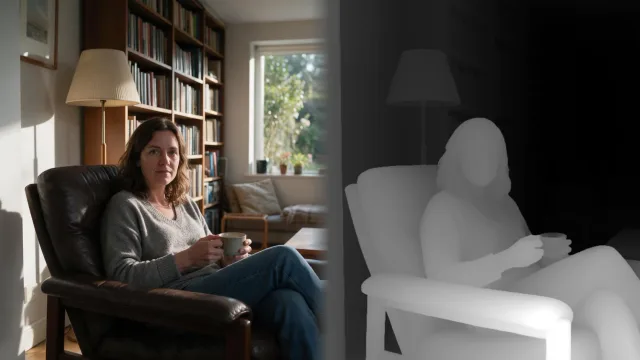
wavespeed-ai/depth-anything-v3/image
Depth Anything V3 Image estimates a sharp, detailed depth map from a single image, ready for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
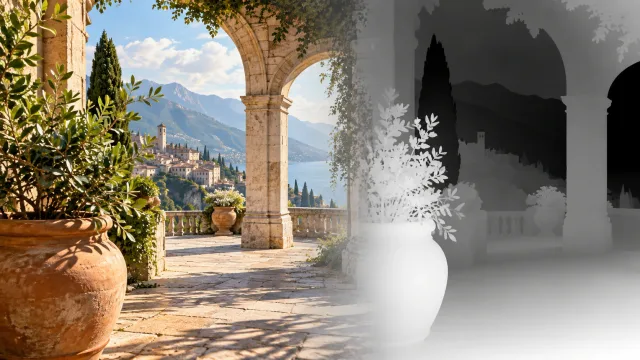
wavespeed-ai/depth-anything/image
Depth Anything Image turns a single image into a detailed grayscale depth map for depth-conditioned generation, relighting, 3D and compositing workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
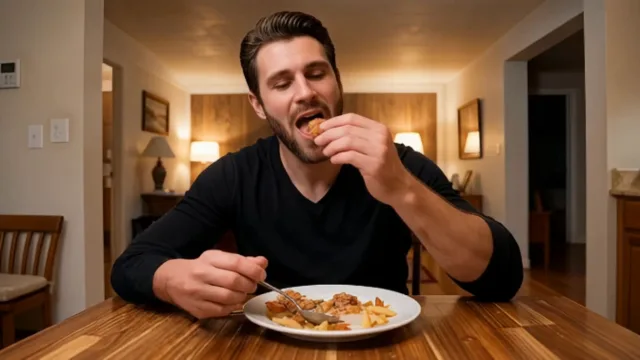
wavespeed-ai/void-video-inpainting/mask
VOID Video Inpainting removes objects from videos using mask-guided inpainting. Supports quad-mask or auto-generated SAM-3 masks, optional Pass 2 refinement for temporal consistency, adjustable denoising steps, guidance scale, and temporal window size. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Object Detection and Segmentation API — 料金とパフォーマンス
Object Detection and Segmentation コレクションのすべてのモデルを単一の REST API で実行できます。生成ごとに課金 — サブスクなし、最低料金なし — で、稼働率 99.9% のインフラ上の業界トップクラスのレイテンシを提供します。
WaveSpeedAI で Object Detection and Segmentation を使う理由
透明な料金体系
各 Object Detection and Segmentation モデルにコールごとの料金が設定されています。料金は各モデルのページに表示され、プラットフォーム手数料はかかりません。
低レイテンシに最適化
ほとんどの Object Detection and Segmentation 画像モデルは 2 秒以内に完了します。動画や 3D モデルはセルフホスト構成より数倍高速です。
稼働率 99.9%
マルチリージョンのフェイルオーバーと自動リトライで、プロバイダー障害時にも本番トラフィックを維持します。
よくある質問
Object Detection and Segmentation API の料金はいくらですか?+
各モデルにはモデルページ上にコール単価が記載されています。成功した生成ごとに課金され、サブスクリプション料金や最低料金はありません。
WaveSpeedAI 上の Object Detection and Segmentation モデルはどのくらい高速ですか?+
このコレクションの画像モデルは通常 2 秒以内に完了します。動画や 3D モデルは長さや解像度に依存しますが、セルフホスト実行より数倍高速なことが多いです。
クレジットカードなしで API を試せますか?+
条件を満たす新規アカウントは、クレジットカードなしで Object Detection and Segmentation モデルを試すためのプロモーションクレジット 1 ドル分を受け取れる場合があります。すべての登録で付与されるわけではありません。生成前にアカウント残高をご確認ください。
レート制限はありますか?+
標準アカウントには十分な同時実行ジョブ枠があります。Enterprise プランではカスタム RPM、より高い同時実行性、専用キャパシティを提供します — 詳細は営業へお問い合わせください。