
Hunyuan Image 3.0 Complete Guide: Tencent's 80B Parameter AI Model
Complete guide to Hunyuan Image 3.0 by Tencent. Learn about the 80B parameter model, text rendering, and API access via WaveSpeedAI.
Tencent’s Hunyuan Image 3.0 is an 80-billion-parameter image generation model with a particular focus on understanding detailed prompts and rendering text within images. Its open weights make it interesting to developers, while hosted access gives creators a way to try it without managing a multi-GPU setup.
The original version of this guide described Hunyuan Image 3.0 as #8 on LM Arena, with a score of 1152 and over 97,000 votes. Those figures had no dated leaderboard snapshot attached, so they should not be presented as its current standing. This guide focuses instead on the architecture, supported workflows, and checks you can repeat on your own images.
Introduction to Hunyuan Image 3.0
Hunyuan Image 3.0 is Tencent’s open-weight image generation model. Its documented strengths include:
- Multilingual text rendering: Generating Chinese and English text within images
- Large-scale architecture: Over 80 billion total parameters in a Mixture-of-Experts (MoE) design, with about 13 billion active per token
- Detailed prompt handling: Interpreting subjects, relationships, styles, and text instructions
- Available weights and inference code: Supporting research and self-hosted workflows under Tencent’s community license
- Visual range: Generating photorealistic and artistic images
The standard HunyuanImage-3.0 checkpoint is for text-to-image generation. HunyuanImage-3.0-Instruct, released later, adds instruction-based image editing and image-to-image workflows. That distinction matters when choosing a download or API endpoint. Tencent lists both in its official repository.
Tencent’s AI Development Journey
Tencent has invested in AI research through the Hunyuan series. For someone choosing a model today, the relevant progression is from earlier image generators toward a larger, unified multimodal approach.
Evolution of Hunyuan Models
- Earlier Hunyuan image models: Established Tencent’s text-to-image work.
- Hunyuan Image 3.0: Introduced the 80B MoE-based generation checkpoint covered here.
- Hunyuan Image 3.0 Instruct: Added instruction reasoning and image editing to the 3.0 family in January 2026.
This is a workflow distinction rather than a claim that each numbered release is a simple quality upgrade. If you only need a new image from text, start with the base text-to-image route. If you need to change an existing photo, check the Instruct route.
Research Philosophy
Tencent’s published work emphasizes:
- Multilingual data and prompts, particularly Chinese and English
- Large-scale model development paired with inference optimizations
- Available code and weights for outside experimentation
- Prompt understanding alongside visual quality
Those are useful design priorities. They do not, by themselves, establish that one model will outperform another on every brief.
Architecture and Parameters
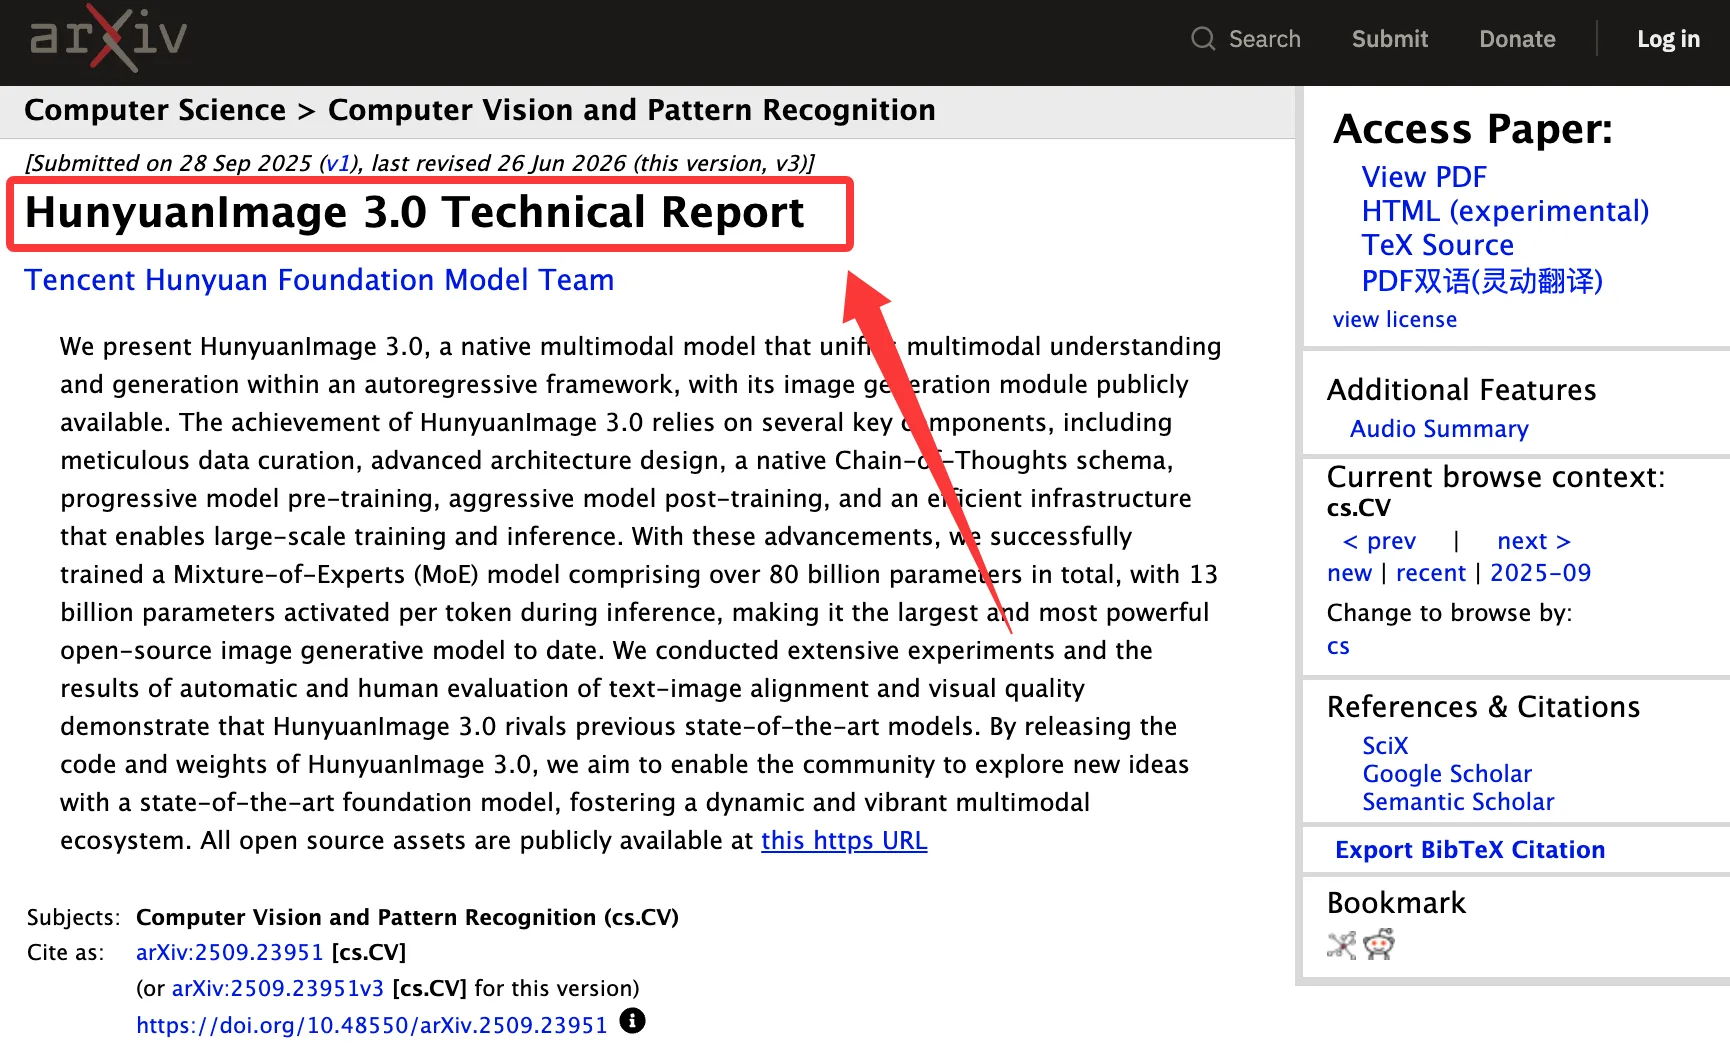
Hunyuan Image 3.0 combines language-style autoregressive modeling with image generation. The technical report describes it as a native multimodal model that unifies understanding and generation within an autoregressive framework; diffusion-based modeling is incorporated for image features.
Mixture-of-Experts Design
The published architecture includes:
- Total parameters: Over 80 billion
- Expert modules: 64
- Active parameters: About 13 billion per token
- Routing mechanism: Selects experts as the model processes each token
Computational efficiency: Activating 13B parameters per token is different from using all 80B for every token. It does not mean the complete weights fit in 13B-sized GPU memory: the model still has to store or move its full weights and other inference data.
Specialized capacity: The expert structure gives the model more capacity without activating every expert for every token. The original claim that individual experts are specifically assigned to “text rendering,” “photorealism,” or object categories was not supported by the cited architecture description.
Scalability: MoE is one part of the design. Actual deployment cost also depends on precision, model parallelism, resolution, and the inference implementation.
Diffusion Model Foundation
It is easy to mistake Hunyuan Image 3.0 for a conventional standalone diffusion model. Tencent describes a more specific combination:
- Autoregressive framework: Text and image information are modeled within a unified multimodal system.
- Image features: A vision encoder and VAE help represent visual information.
- Diffusion-based image modeling: The generation process operates on image features within that broader framework.
- Conditional generation: The prompt guides the image that is produced.
That distinction explains why “it is an 80B diffusion model” is an incomplete description of the architecture.
Text Encoding System
The model is trained for detailed, bilingual descriptions. Its research report discusses Chinese and English captioning data, image understanding, and prompt reasoning. For practical use, the main question is whether the generated image follows the relationships and exact text in your prompt.
The original draft claimed separate Chinese and English text-encoder pathways and a fixed “1000+ character” input limit. Neither should be treated as a general API specification without an endpoint-specific source.
Key Features and Capabilities
Hunyuan Image 3.0 addresses a range of image generation needs. The exact controls available to you depend on whether you run Tencent’s checkpoint locally or use a hosted service.
Resolution and Aspect Ratios
- Local workflow: Tencent’s command-line examples accept an image size such as
1024x1024,1280x768, or an aspect ratio such as16:9. - Hosted workflow: Check the chosen provider’s request schema before sending a size. WaveSpeedAI’s current Hunyuan Image 3 text-to-image parameter table lists
sizeas awidth*heightstring with dimensions in its documented range. - Practical check: Generate at the size you intend to use and inspect small text, edges, and cropping at full resolution.
The original “2048×2048 and beyond” wording was too broad for every route. A model-family capability and a hosted endpoint’s accepted values are not interchangeable.
Generation Speed and Efficiency
Despite its parameter count, Hunyuan Image 3.0 can be accessed through optimized inference stacks or hosted services. Generation time still varies with the checkpoint, output size, queue, and hardware.
- Sampling steps: Tencent’s local examples document a recommended setting for the base checkpoint. The later Instruct-Distil checkpoint recommends eight steps; that number should not be applied to every Hunyuan Image 3.0 model.
- Batch processing: Multiple prompts can be submitted, subject to the provider’s rate and concurrency limits.
- Timing: Record submission time, completion time, size, endpoint, and checkpoint when assessing speed.
The original 15–30-second figure was not tied to recorded tests or one endpoint configuration, so it is not used as a general benchmark.
Stylistic Range
The model can be prompted for different visual treatments:
- Photorealism: Camera-like images, lighting, and materials
- Artistic styles: Oil painting, watercolor, digital art, and anime-inspired work
- 3D rendering: Product and concept-render aesthetics
- Concept art: Atmospheric game or film ideas
Style words help set direction. Check the output before assuming that a named style will be rendered consistently across a batch.
Content Understanding
Useful things to inspect in a generated result include:
- Object relationships: Whether objects appear in the requested positions
- Scene composition: Whether the subject, background, and camera view agree with the prompt
- Lighting: Whether shadows and atmosphere fit the described scene
- Cultural context: Whether architecture, clothing, signage, and other details are represented appropriately
Text Rendering in Chinese and English
One of Hunyuan Image 3.0’s most interesting use cases is text inside an image, especially Chinese signage, posters, and packaging. Tencent’s published examples support exploring this capability; they do not guarantee that every character will be correct on the first attempt.
Why Text Rendering is Difficult
Text in a generated image presents specific challenges:
- Structural precision: A character or letter must have the right shape.
- Small details: Fine strokes disappear or merge at small sizes.
- Chinese glyph complexity: Many characters have dense, distinct stroke patterns.
- Scene integration: Text must still fit the surface, perspective, lighting, and layout.
Chinese Text Excellence
Hunyuan Image 3.0 can generate Chinese text in visual contexts. Check each of these separately when reviewing an output:
Character accuracy: Are all requested characters present and in the right order?
Stroke quality: Are the characters readable at the final display size?
Typography: Does the style suit the prompt without changing the wording?
Integration: Does the sign or label belong naturally in the scene?
Example prompts demonstrating Chinese text use cases:
"A traditional Chinese bookstore with wooden shelves,
with a sign reading '书香门第' in elegant calligraphy"

"A red Chinese New Year poster with '恭喜发财'
in golden characters, decorated with lanterns and clouds"

"A modern Chinese café with a menu board showing
'今日特饮:茉莉花茶' in clean sans-serif font"
These are prompts to try, not recorded test results. The original “correctly renders complex characters” claim was too absolute without an output set and a scoring method.
English Text Performance
English text can be tested in the same way:
- Spelling: Check every letter rather than judging from a thumbnail.
- Font style: Ask for serif, sans-serif, handwritten, or decorative treatment.
- Context: Place text on a poster, sign, or package.
- Length: Start with a short phrase before attempting a longer passage.
Mixed Language Support
You can ask for both languages in one image:
"A bilingual street sign in Hong Kong showing
'Central Station' and '中环站' in English and Chinese"
Review the English and Chinese independently. One language looking correct does not prove the other is accurate.
Text Rendering Best Practices
To improve your chances of getting usable text:
- Be explicit: Put the requested words in quotes.
- Describe style: Specify the font or lettering treatment.
- Provide context: Say where the text appears.
- Keep it short: Use a short headline or label before asking for paragraphs.
- Specify language: State “in Chinese” or “in English” where needed.
Same-Prompt Check: Chinese and English Text on One Product
Here is a repeatable way to decide whether Hunyuan Image 3.0 suits a bilingual product graphic. This is a test plan, not a claim that I generated or scored its outputs.
Use the same checkpoint, size, and seed for each run. Keep the product and layout fixed; change only the requested text:
Base scene:
"A front-facing green tea bottle on a clean white studio background.
Keep the bottle shape, label placement, camera angle, and soft side lighting
the same. Place a large, clearly readable label at the center."

Run A: Label text reads "GREEN TEA".
Run B: Label text reads "绿茶".
Run C: Label text reads "GREEN TEA 绿茶".
Save each prompt, seed, endpoint, output size, and image. Then check:
| Check | What counts as a problem |
|---|---|
| Text | Missing, substituted, reordered, or unreadable characters |
| Product | Bottle shape, cap, color, or label area changes between runs |
| Layout | Text moves, clips, or becomes too small |
| Usability | The image needs more correction than your workflow allows |
For an existing approved product image, use HunyuanImage-3.0-Instruct or a hosted Instruct Edit endpoint with the source image. The base HunyuanImage-3.0 text-to-image route generates a new image from text; it is not the same editing workflow. Tencent’s Instruct model page documents that distinction. If packaging copy must be exact, verify it manually and replace the text in a design tool when necessary.
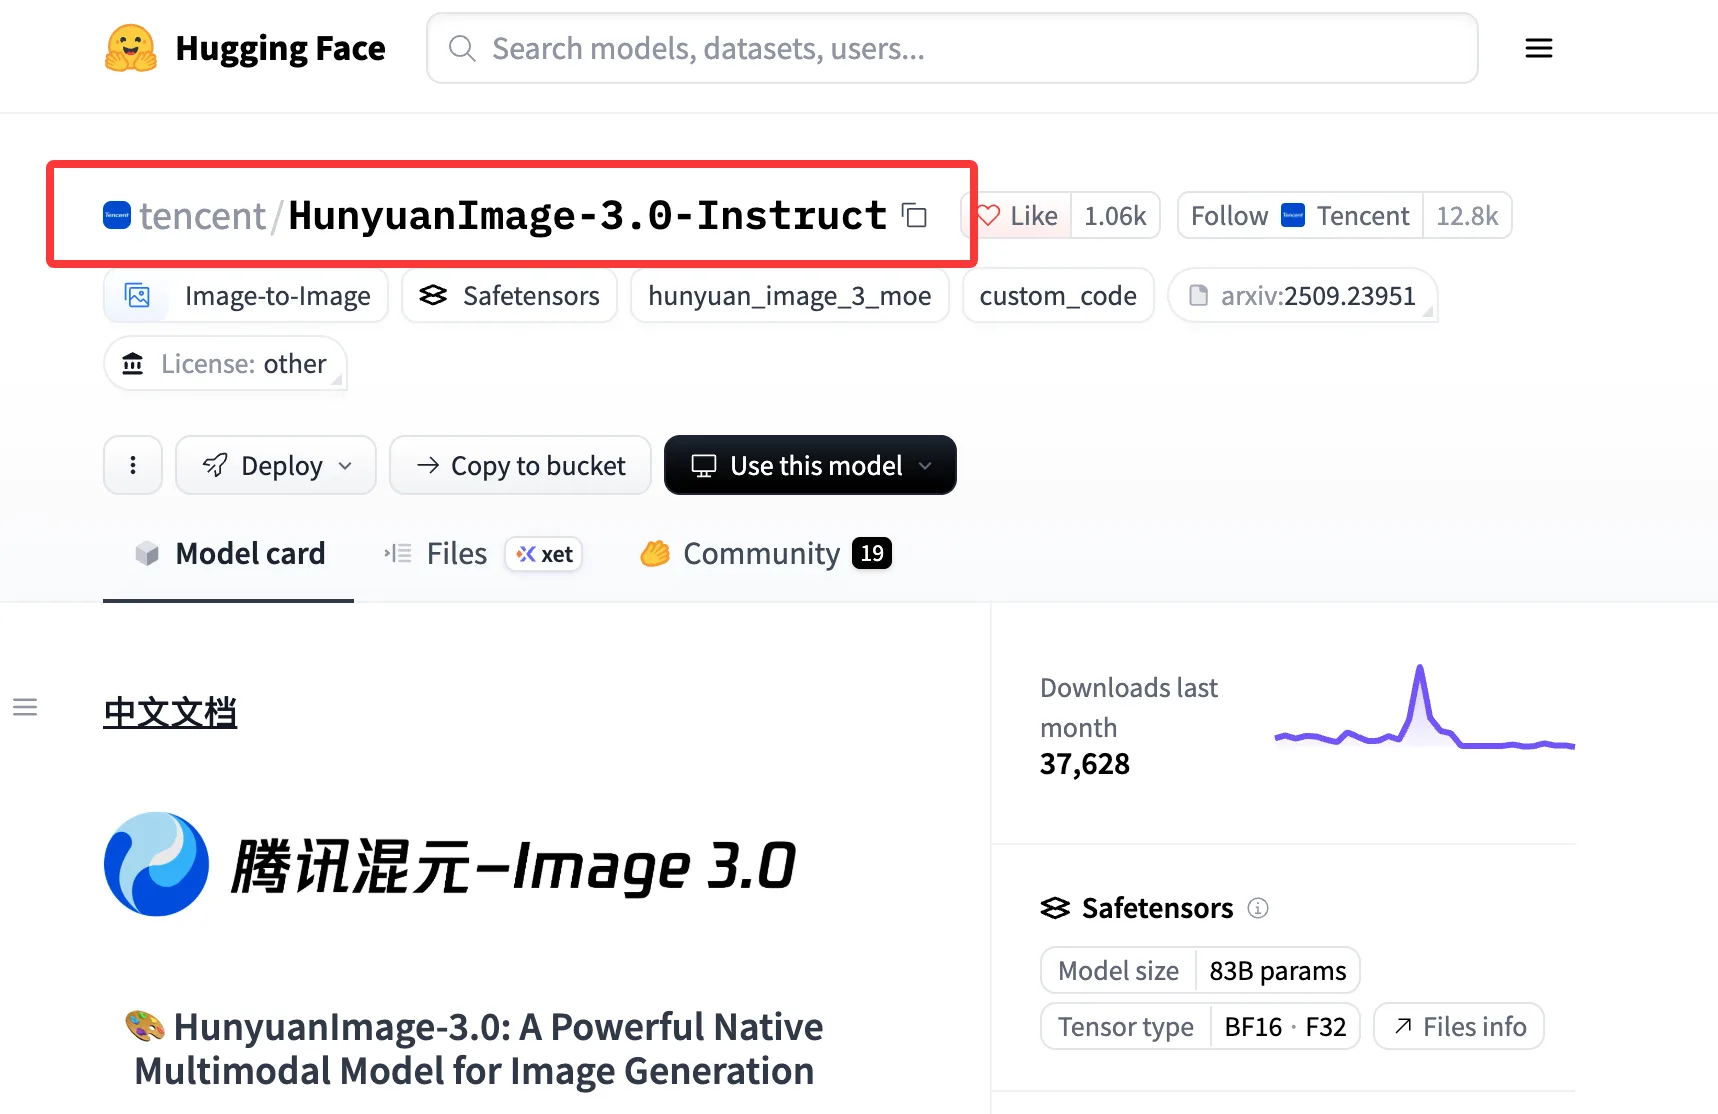
Image Quality and Style
Hunyuan Image 3.0 can produce detailed images in both photographic and artistic directions. Quality claims are most useful when tied to a particular prompt and output.
Visual Fidelity
Look closely at:
Detail preservation: Fabric, skin, packaging, and other small surface details
Color: Whether the requested palette appears and remains usable
Lighting: Shadows and reflections that fit the scene
Depth and dimension: Perspective and separation between foreground and background
Artistic Coherence
Generated images should be reviewed for:
- Style uniformity: Do elements share the requested visual treatment?
- Tonal harmony: Do colors and values fit together?
- Compositional balance: Is the intended subject clear?
- Narrative clarity: Are there contradictory objects or details?
Common Output Characteristics
The original draft described a consistent “Asian aesthetic bias,” enhanced colors, and high contrast as model-wide traits. Without a documented sample, those are not dependable generalizations. If a particular output leans toward an unwanted look, name the intended location, people, design references, and lighting more precisely in the next prompt.
Quality Comparison
Against another image model, use the same brief and compare:
- Exact text accuracy
- Object count and spatial relationships
- Material and lighting details
- Time and cost per accepted image
A different result on one prompt can guide your workflow; it cannot establish a universal model ranking.
Prompt Engineering Tips
Effective prompting gives Hunyuan Image 3.0 more specific visual instructions. The following structure and examples from the original guide remain useful.
Prompt Structure
A well-structured prompt typically includes:
[Main Subject] + [Action/Pose] + [Environment/Setting] +
[Lighting] + [Style] + [Text Content]Example:
A young Chinese woman reading a book in a cozy café,
warm afternoon sunlight streaming through large windows,
photorealistic style, shallow depth of field,
café sign reading '云间书屋' visible in background
Specificity Guidelines
Be descriptive but concise: Include essential details without overwhelming the model.
Use visual language: Describe what should be visible.
Specify quantities: “Three red apples” is clearer than “some apples.”
Define spatial relationships: “Book on the table, cup beside it.”
Effective Modifiers
Lighting descriptors:
- Golden hour, blue hour, overcast, studio lighting
- Rim light, backlighting, side lighting, soft diffused light
- Dramatic shadows, high contrast, even illumination
Quality descriptors:
- Fine detail, sharp focus, clear subject
- Product photography or editorial photography where relevant
- The output size you actually need, set through the supported parameter rather than by writing “8K” in the prompt
Style specifications:
- Photorealistic, digital painting, oil painting, watercolor
- Cinematic or editorial photography
- Anime-inspired or concept art
Chinese Prompt Support
Hunyuan Image 3.0 accepts Chinese prompts:
一个传统中式庭院,红色灯笼挂在屋檐下,
石桌上放着茶具,竹林背景,水墨画风
Use Chinese when it lets you describe the subject or written text more precisely. Compare outputs before assuming that one prompt language is always better.
Advanced Techniques
Negative prompting: Use a separate negative-prompt field only if your chosen endpoint documents one.
Emphasis: Put important constraints clearly in the main prompt; repetition is not a substitute for testing.
Multi-step descriptions: Break complex scenes into subject, setting, lighting, and text.
Reference images: Use an editing-capable checkpoint and endpoint when the task requires an existing image.
Common Pitfalls to Avoid
- Conflicting instructions: “Photorealistic anime” can pull in different directions.
- Impossible physics: An impossible scene may need a more explicit artistic brief.
- Overloading: Too many competing elements reduce clarity.
- Vague abstractions: “Beautiful scene” gives little visual direction.
API Access via WaveSpeedAI
WaveSpeedAI hosts a Hunyuan Image 3 text-to-image route. Hosted access removes the need to provision Tencent’s recommended local multi-GPU setup, but the provider’s API parameters and limits must be read separately from Tencent’s local command-line options.
Why Use WaveSpeedAI
Unified interface: One API pattern for multiple supported models.
Published endpoint: A model-specific route for Hunyuan Image 3 text-to-image generation.
Developer access: REST requests can be made from Python or another HTTP client.
Separate editing route: Instruct Edit is a different endpoint for requests that include source images.
The original assertions of unrestricted global availability, a particular uptime level, and universal pricing advantages were not established for this endpoint and have been removed.
Getting Started
- Create an account and obtain an API key.
- Read the model schema for the exact route you intend to use.
- Choose a supported size and write a prompt.
- Submit once, save the returned prediction ID, and query its result.
- Inspect the generated image, particularly any text or product details.
The WaveSpeedAI Hunyuan Image 3 API reference currently shows the text-to-image route, request parameters, task response, and result query.
Authentication
API requests use a bearer token:
Authorization: Bearer ${WAVESPEED_API_KEY}Keep the key in an environment variable rather than publishing it in a script or article.
Rate Limits and Quotas
Check your current account limits before submitting many concurrent jobs. The original free, paid, and enterprise quota descriptions were too specific without a dated account-policy source.
Code Examples
These examples use the documented wavespeed-ai/hunyuan-image-3 REST route. The original tencent/hunyuan-image-3.0 route and wavespeed.run(...) response assumption did not match the endpoint documentation checked for this revision.
Python Example
Install requests and set WAVESPEED_API_KEY first.
import os
import time
import requests

BASE_URL = "https://api.wavespeed.ai/api/v3"
HEADERS = {
    "Authorization": f"Bearer {os.environ['WAVESPEED_API_KEY']}",
    "Content-Type": "application/json",
}

def generate_image(prompt, size="1024*1024", seed=-1):
    response = requests.post(
        f"{BASE_URL}/wavespeed-ai/hunyuan-image-3",
        headers=HEADERS,
        json={"prompt": prompt, "size": size, "seed": seed},
        timeout=60,
    )
    response.raise_for_status()
    task_id = response.json()["data"]["id"]

    for _ in range(120):
        response = requests.get(
            f"{BASE_URL}/predictions/{task_id}/result",
            headers=HEADERS,
            timeout=30,
        )
        response.raise_for_status()
        result = response.json()["data"]

        if result["status"] == "completed":
            return result["outputs"]
        if result["status"] in {"failed", "cancelled", "timeout", "deleted"}:
            raise RuntimeError(f"Task {task_id}: {result.get('error')}")
        time.sleep(2)

    raise TimeoutError(f"Task {task_id} is still running; keep its ID.")

prompt = (
    "A modern Chinese bookstore interior, warm lighting, wooden "
    "bookshelves filled with books, a reading area with comfortable "
    "chairs, storefront sign in elegant calligraphy, cozy atmosphere, "
    "photorealistic, high detail"
)

image_url = generate_image(prompt, "1024*1024", 42)[0]
print(f"Generated image URL: {image_url}")
If a submission fails with an unclear network outcome, check whether a task was created before sending the POST again. Retrying an existing result query is different from submitting a second billable job.
Python with Requests
The helper above already uses requests. This example keeps the original Beijing poster prompt and adds the download step:
prompt = """
A vintage travel poster for Beijing, featuring the Temple of Heaven,
bold text reading "Visit Beijing" at the top, art deco style,
vibrant colors, 1930s aesthetic, high quality illustration
"""

image_url = generate_image(prompt.strip(), "1024*1536", 12345)[0]
download = requests.get(image_url, timeout=60)
download.raise_for_status()

with open("hunyuan_poster.png", "wb") as file:
    file.write(download.content)

print("Image generated successfully!")
Read “Visit Beijing” in the saved image before using it as a finished poster.
Python Example
For quick testing after defining generate_image:
output = generate_image(
    "A Chinese dragon flying through clouds, traditional ink "
    "painting style, dynamic composition, black and white with "
    "red accents"
)
print(output[0])
Batch Generation Example
Generate variations using the original tea-ceremony brief:
base_prompt = "A Chinese tea ceremony, elegant porcelain teapot and cups"
variations = [
    "morning light, minimal composition",
    "evening light, traditional setting with bamboo",
    "dramatic side lighting, close-up view",
    "overhead view, flat lay photography style",
]

for index, variation in enumerate(variations, start=1):
    full_prompt = f"{base_prompt}, {variation}"
    try:
        output = generate_image(full_prompt, "1024*1024")
        print(f"Generated variation {index}: {output[0]}")
    except (requests.RequestException, RuntimeError, TimeoutError) as error:
        print(f"Variation {index} needs review: {error}")
This version sends requests sequentially. Add concurrency only after checking your account limits and deciding how you will store and recover prediction IDs.
Comparison with Competitors
Model selection depends on the exact task. The original comparisons assigned quality winners and star scores without a shared prompt set, dated output samples, or scoring method. Keep the comparison questions; test the answers with your own brief.
Hunyuan Image 3.0 vs. DALL-E 3
For Chinese signage or bilingual packaging, compare every requested character and the overall layout. For an English-only concept, compare prompt adherence and the amount of manual correction needed.
Best use cases to test:
- Hunyuan: Chinese text, bilingual visuals, and an open-weight workflow
- DALL-E 3: Your existing generation workflow and creative briefs
Hunyuan Image 3.0 vs. Midjourney v6
If the task is exploratory art direction, compare the images themselves. If you are building an application, also compare the available integration paths and terms.
Best use cases to test:
- Hunyuan: Programmatic generation, Chinese text, and self-hosting needs
- Midjourney: Visual exploration within its supported workflow
Hunyuan Image 3.0 vs. Stable Diffusion XL
These models have different local hardware demands and tooling ecosystems. For a self-hosted decision, compare more than output quality: include the memory needed, available controls, and your maintenance time.
Best use cases to test:
- Hunyuan: Projects that need its multilingual and prompt-following capabilities
- SDXL: Workflows already built around its local tools and adaptations
Hunyuan Image 3.0 vs. FLUX.1
Use the same prompt and final image size when comparing text, photorealism, and composition. Parameter counts alone do not determine which output is more usable.
Best use cases to test:
- Hunyuan: Chinese and bilingual visual tasks
- FLUX.1: Workflows where its particular output or tooling fits the brief
Feature Comparison Matrix
| Decision question | What to check |
|---|---|
| Chinese text | Exact characters, order, and readability |
| English text | Spelling, layout, and small-text errors |
| Photorealism | Materials, hands, lighting, and perspective |
| Artistic style | Match to the brief across several prompts |
| API access | Exact model route, parameters, and result handling |
| Local deployment | License, checkpoint size, GPU requirement |
| Cost | Price per accepted image, including retries and editing |
This replaces the original unsupported star ratings with checks a reader can apply to the same set of prompts.
Open-Source Licensing
Hunyuan Image 3.0’s available weights make it accessible for research and development, but its Tencent Hunyuan Community License Agreement has conditions. “Open-weight” is a more precise description than “unrestricted open source.”
License Type
The published agreement grants specified rights to use and modify the model within its defined territory, subject to its terms and acceptable-use policy. The territory excludes the EU**, UK, and South Korea**. Distribution has notice obligations, and certain large commercial operators need a separate license. Read the current official license for the exact conditions that apply to your use.
The original draft’s blanket statement that all commercial uses were permitted with a simple attribution requirement was too broad. The agreement’s distribution notices are also different from a universal requirement to credit Tencent on every generated image.
Commercial Use
Before a commercial deployment, check:
- Whether the intended location is within the agreement’s territory
- Whether you are distributing model materials or offering a hosted service
- Whether the agreement’s additional commercial threshold applies to your organization
- Whether your product and outputs follow the acceptable-use restrictions
- Whether your API provider has separate applicable terms
For a client project, keep the checkpoint and license version with the project record.
Accessing the Model
Official channels:
- Tencent’s GitHub inference repository
- The official HunyuanImage-3.0 model page
- The separate HunyuanImage-3.0-Instruct checkpoint for editing
Third-party API access:
- WaveSpeedAI’s Hunyuan Image 3 text-to-image route
- A separate Instruct Edit route where image input is required
A hosted text-to-image endpoint does not automatically expose all features of the Instruct checkpoint.
Fine-Tuning and Customization
Available weights make experimentation possible, but the original article’s suggestion that standard LoRA training is a ready-made, uniformly supported path was too broad. Check the training tool, checkpoint compatibility, memory requirements, and license before committing to a custom training project.
Compliance Considerations
When using Hunyuan Image 3.0 commercially:
- Read the applicable license for the exact checkpoint and use.
- Check territory and distribution terms before deployment.
- Keep notices where required when sharing model materials.
- Review provider terms separately if you use a hosted API.
- Review sensitive outputs before publishing them.
FAQ
General Questions
Q: Is Hunyuan Image 3.0 completely free to use?
A: The weights are available under Tencent’s community license. Local inference still requires hardware and maintenance. Hosted API calls can have separate charges.
Q: How does Hunyuan Image 3.0 compare to DALL-E 3?
A: Test the same prompt set. Hunyuan is particularly relevant when Chinese or bilingual text and available weights matter; a general quality winner cannot be established from the original article’s unsupported comparison.
Q: Can I use Hunyuan Image 3.0 for commercial projects?
A: The license allows certain commercial uses subject to conditions, including its territory and additional commercial terms. Review the agreement and any provider terms for your specific project.
Q: What languages does Hunyuan Image 3.0 support?
A: Tencent documents Chinese and English use. For text inside a generated image, check the output character by character.
Technical Questions
Q: What hardware is needed to run Hunyuan Image 3.0 locally?
A: Tencent’s repository recommends at least 3×80GB GPUs for the base text-to-image checkpoint and at least 8×80GB GPUs for Instruct. These are the published recommendations for its official setup, not universal minimums for every experimental quantized or offloaded implementation. The original “minimum 80GB VRAM” statement understated that recommended setup.
Q: How long does image generation take?
A: It depends on the checkpoint, size, provider, queue, and hardware. The original 15–30-second estimate was not attached to a reproducible test. Record end-to-end time for your own endpoint and workload.
Q: What resolutions are supported?
A: Tencent’s local tool accepts explicit sizes and aspect-ratio inputs. Hosted providers set their own bounds. Check the route’s request schema rather than treating “2048×2048 and beyond” as universal.
Q: Can I control the random seed for reproducible results?
A: Yes, the local tool and WaveSpeedAI text-to-image endpoint expose seed control. Save the model, prompt, size, and seed together. A seed does not promise identical pixels across model or provider changes.
Usage Questions
Q: How can I improve text rendering quality?
A:
- Put the exact text in quotes.
- Keep it short at first.
- Describe font style and placement.
- Name the language when needed.
- Inspect the final-sized output and correct critical copy manually.
Q: Why do my generated images have an Asian aesthetic bias?
A: One output or prompt is not enough to establish a model-wide bias. If a result misses your intended setting or subject, specify the location, clothing, people, materials, and other relevant visual details more clearly; compare multiple prompts before drawing a general conclusion.
Q: Can I generate NSFW or violent content?
A: Check the model’s acceptable-use policy and the provider’s content policy. A request can be rejected when it conflicts with those rules.
Q: How do I generate multiple variations of the same concept?
A:
- Change the seed while holding the prompt and size fixed.
- Change one visual instruction at a time.
- Save the endpoint and model version with each output.
- Review the differences rather than assuming all variations will preserve exact text.
Troubleshooting
Q: My text is garbled or incorrect. How do I fix this?
A:
- Put the desired words in quotes.
- Shorten the text.
- Specify where it appears.
- Try another seed.
- Add exact final copy in a design tool if necessary.
The original advice to “increase steps to 40–50” is a local-checkpoint setting, not a parameter you can assume every hosted route exposes.
Q: Generated images don’t match my prompt. What’s wrong?
A:
- Remove contradictory instructions.
- Put the subject and required relationships first.
- Separate scene, style, and text requirements.
- Check whether a prompt-enhancement feature changed the wording.
- Confirm that you called the intended checkpoint.
Q: API requests are failing. What should I check?
A:
- Confirm the key and model route.
- Check the endpoint’s actual parameter names and size range.
- Store the returned prediction ID.
- Read failed task details from the result response.
- Do not repeat a submission with an unclear outcome before checking for an existing task.
Q: How do I handle Chinese characters in API requests?
A: Send UTF-8 JSON. Python’s requests library handles Unicode strings in the json= argument; inspect the stored prompt and output if characters appear corrupted elsewhere in your pipeline.
Conclusion
Hunyuan Image 3.0 is a notable open-weight image generation model, especially for teams exploring Chinese and English text within images. Its 80B-total, 13B-active MoE design is a real architectural detail; whether it is the right choice still depends on the image you need, the checkpoint you run, and the cost of reviewing the output.
Key Takeaways
Standout strengths:
- Chinese and English image-text workflows worth testing
- Over 80B total parameters with about 13B active per token
- Available weights and inference code
- Separate base and Instruct checkpoints with different tasks
- Hosted text-to-image access for users without Tencent’s recommended local GPU setup
Ideal use cases:
- Chinese-language visual content
- Bilingual marketing concepts
- Product visualization and packaging drafts
- Research into large multimodal image models
- Teams evaluating an open-weight generation workflow
Considerations:
- Confirm whether you need text-to-image or image editing.
- Check the exact local hardware recommendation or hosted endpoint schema.
- Review the community license for your location and deployment.
- Inspect written text and product details before publication.
Getting Started Recommendations
- Choose a task: New image from text, or edit to an existing image.
- Pick the matching checkpoint or endpoint: Base for text-to-image; Instruct for editing.
- Try the same-prompt check above if text accuracy matters.
- Save your settings and output so the result can be reviewed.
- Iterate on the prompt or finish exact text manually when required.
The Future of Hunyuan
Tencent has already added an Instruct checkpoint and an Instruct-Distil checkpoint after the initial 3.0 release. Future capabilities and deployment options should be checked against the official release notes rather than predicted from the model’s parameter count.
Final Thoughts
Hunyuan Image 3.0 gives developers and creators a substantial image model to evaluate, with particular interest for Chinese and bilingual visuals. The most useful next step is concrete: run one representative prompt through the route you plan to use, inspect the full-size result, and record whether it meets your own acceptance criteria.
Previous posts:
Related Articles
GPT Image 2.6: What Is Confirmed, What Is Rumor, and What to Build On Today
Seedream 5.5: What to Expect, and How to Get Ready
Connect WaveSpeed to Claude, ChatGPT and Cursor with One URL
Nano Banana 3 Pro Spotted: What the Gempix 3 Pro Leak Tells Us
GPT Image 2.5 API Guide: Flare & Sunburst on WaveSpeedAI