How Should an AI Video SaaS Price Plans When Several Generations Are Needed for One Usable Clip?
Design AI video SaaS plans around attempts per usable clip, model mix, review cost, margin targets, and retry allowances.
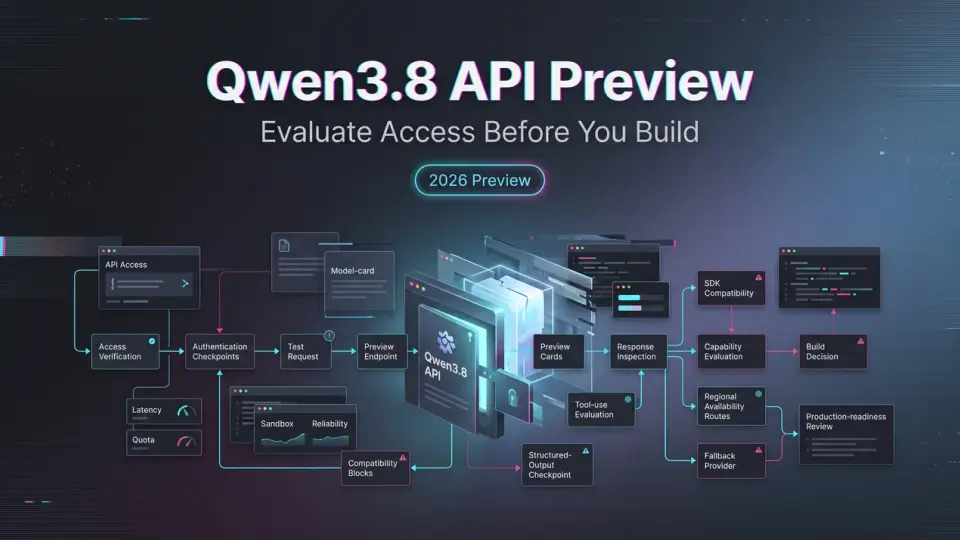
Qwen3.8 API Preview: Evaluate Access Before You Build
Evaluate Qwen3.8 API preview access, Token Plan limits, and evidence before deciding whether to test now or wait for a supported production path.
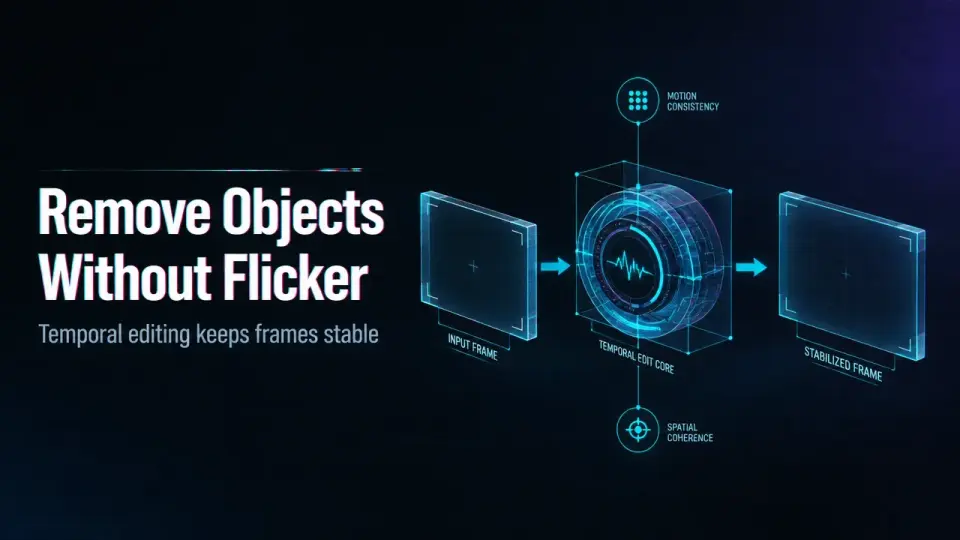
How Can I Remove an Object from Video without Introducing Frame-to-Frame Flicker?
Reduce flicker after removing an object from video with temporal editing, stable references, controlled prompts, and sequence-level QA.
How Do I Retry a Long-Running Video Generation Job without Creating Duplicate Jobs or Charges?
Retry long-running AI video jobs safely with task IDs, status checks, attempt records, and duplicate webhook protection.
How Do I Run MiniMax H3 in ComfyUI?
A practical view of running MiniMax H3 in ComfyUI: nodes, workflow templates, dependencies, and what to verify first.
Why Can the Same AI Model Perform Differently on WaveSpeedAI, fal.ai, and Replicate?
The same model name can produce different results across APIs because versions, defaults, parameters, queues, and post-processing vary.
How Do I Store and Retrieve MiniMax H3 Video Outputs?
How to store and retrieve MiniMax H3 outputs safely, since provider URLs can expire — copy to your own storage.
When Is Text-Based Video Editing More Efficient Than Regenerating a Clip from Scratch?
Decide between text-based video editing and full regeneration by comparing change scope, continuity risk, cost, and review time.
How Can I Track Generation Cost per User, Model, and Retry in an AI SaaS?
Track AI generation cost accurately with request, attempt, model, status, estimate, and billing fields for every tenant and retry.
How Do I Use the MiniMax H3 API?
A short MiniMax H3 API workflow: choose a provider, submit a task, poll or use webhooks, retrieve output, and track cost.
What Is the Difference Between Video Head Swap and Face Swap, and When Should I Use Each?
Learn how video head swap differs from face swap and choose based on hair, silhouette, motion, occlusion, identity, and consent.
Why Is a Model Listed on WaveSpeedAI but Not Available to Run Yet?
A model card does not always guarantee a runnable endpoint. Check its schema, account access, errors, capacity, and current availability.