The Together AI alternative
Open and frontier LLMs.
Every media model, too.
Fast, affordable Claude, GPT, Gemini, DeepSeek and Kimi on an OpenAI-compatible API, plus 1,062 ready-to-call image, video, audio and 3D models. One key, pay as you go, no GPUs to reserve.
Opens the playground with your message. Sign in to run it.
Why builders switch from Together AI
Fast.
Blazing-fast inference on every model. Your images and videos come back fast, in the studio and through the API.
Affordable.
Images from $0.024, videos from $0.05 per run. Pay only for what you generate, with no subscription and no monthly fee.
- Media models
- 1,062+
- Language models
- 111+
- Model makers
- 43
- GPU hours to reserve
- 0
Media is first-class, not an add-on
Seedance, Kling, Veo, Nano Banana, GPT Image, ElevenLabs, Tripo and more, each with its own endpoint, input schema, examples and a listed price per run.
Together AI: A platform built around open-source language models, with a selection of image, video and audio models on its serverless API.
Frontier and open LLMs on one key
Claude, GPT and Gemini next to DeepSeek, Kimi, Qwen and GLM, on an OpenAI-compatible API billed from the same balance as your media calls.
Together AI: An OpenAI-compatible API centered on open-source models.
Nothing to reserve or keep warm
Every model is hosted and ready. Pay per token or per output, with no endpoints to size and no hourly meter running.
Together AI: Serverless APIs, plus dedicated endpoints and GPU clusters billed per GPU hour for reserved capacity.
Studios for your whole team
Designers and marketers get image, video, audio and 3D generators, editing tools and an AI video editor in the browser, on the same account as your API.
Together AI: A developer platform with a web playground.
LLM API
Drop-in compatible
OpenAI-compatible chat completions and Responses plus an Anthropic-compatible Messages endpoint. Swap the base URL and go.
Media API
Image, video, audio and 3D
Send JSON, get a prediction id back, then poll the result or receive a webhook. One request format for every model.
Training
LoRA trainers
Train LoRAs for popular image and video models, then run them on the matching LoRA endpoints.
Agents
Ready for agents
A CLI, Agent Skill and MCP server hand coding agents every media model, with setup guides for Codex, Claude Code and more.
Media API
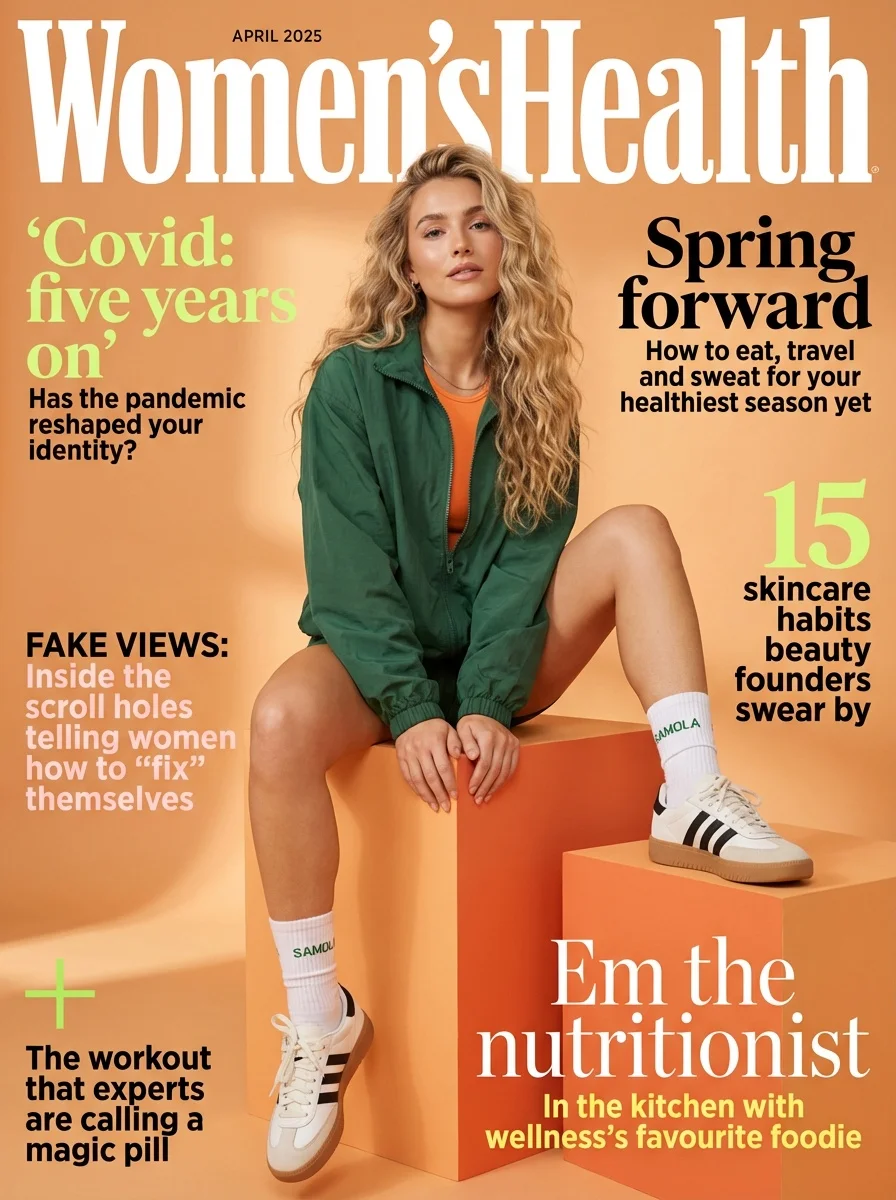
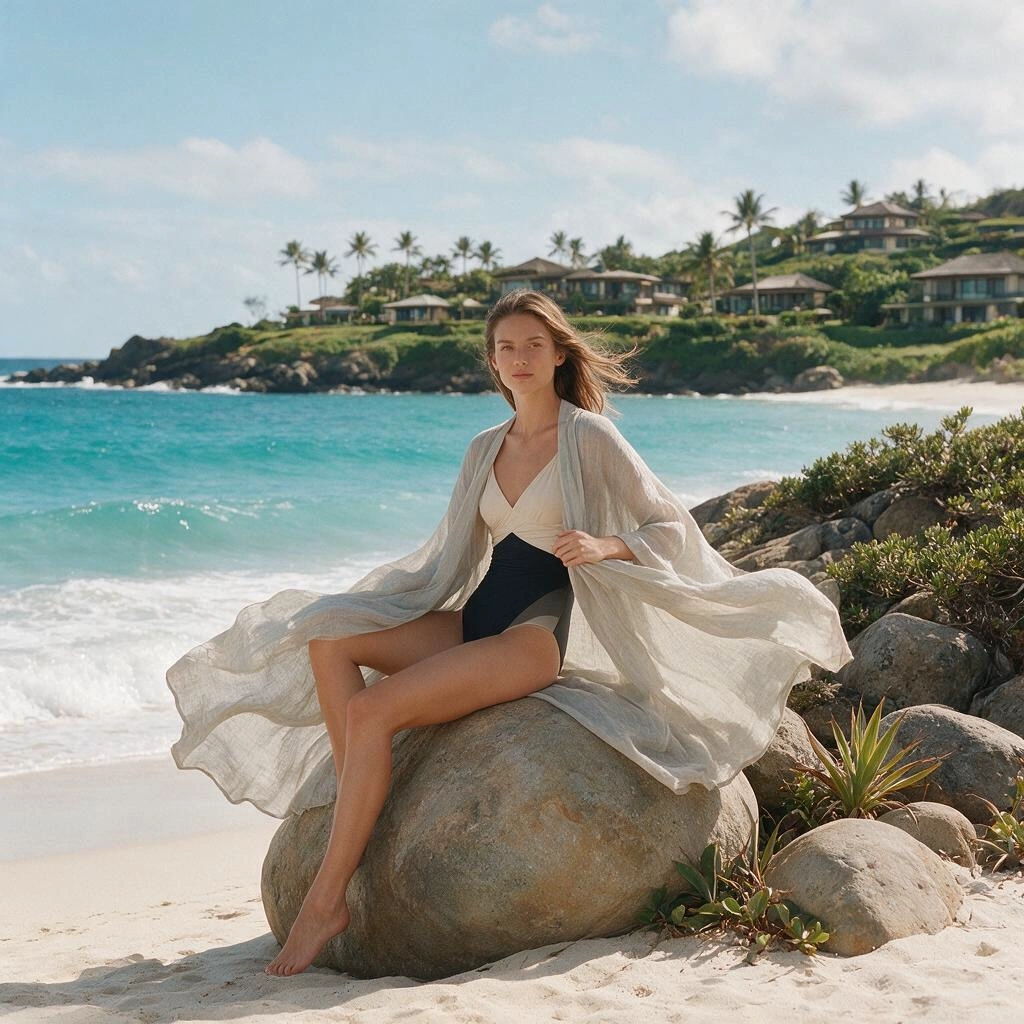
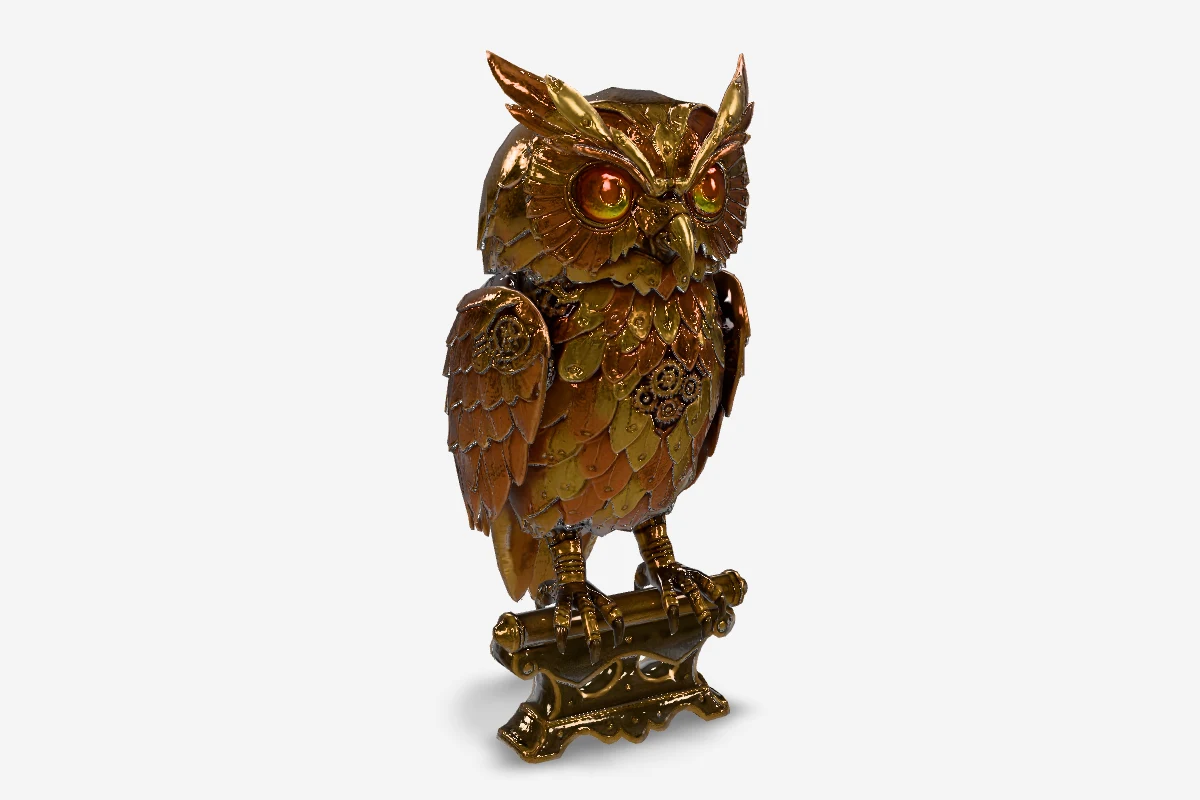
Popular media endpoints
Live prices per run. Open one for its schema and examples, or try it in the browser.
Language models
Chat with any LLM
Swap the base URL. Keep your OpenAI client. Closed and open models on one key.
POSThttps://llm.wavespeed.ai/v1/chat/completions
curl https://llm.wavespeed.ai/v1/chat/completions \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6-astra",
    "messages": [{"role": "user", "content": "Hello!"}]
  }'
import os
from openai import OpenAI
client = OpenAI(base_url="https://llm.wavespeed.ai/v1", api_key=os.environ["WAVESPEED_API_KEY"])
reply = client.chat.completions.create(
model="openai/gpt-6-astra",
messages=[{"role": "user", "content": "Hello!"}],
)
print(reply.choices[0].message.content)import OpenAI from 'openai'
const client = new OpenAI({ baseURL: 'https://llm.wavespeed.ai/v1', apiKey: process.env.WAVESPEED_API_KEY })
const reply = await client.chat.completions.create({
model: 'openai/gpt-6-astra',
messages: [{ role: 'user', content: 'Hello!' }],
})
console.log(reply.choices[0].message.content)Media models
Generate images and video
The same key calls every media model: submit, then poll the result or receive a webhook.
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedream-v5.0-pro
curl -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedream-v5.0-pro" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "prompt": "A glass teapot on a sunlit windowsill, soft morning light",
  "aspect_ratio": "4:3",
  "resolution": "2k"
}'

# → {"data": {"id": "<prediction id>", ...}}
curl "https://api.wavespeed.ai/api/v3/predictions/<prediction id>/result" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY"
import os, time, requests
headers = {"Authorization": f"Bearer {os.environ['WAVESPEED_API_KEY']}"}
task = requests.post("https://api.wavespeed.ai/api/v3/bytedance/seedream-v5.0-pro", headers=headers, json={
"prompt": "A glass teapot on a sunlit windowsill, soft morning light",
"aspect_ratio": "4:3",
"resolution": "2k"
}).json()["data"]
while True:
result = requests.get(f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result", headers=headers).json()["data"]
if result["status"] == "completed":
print(result["outputs"])
break
if result["status"] == "failed":
raise RuntimeError(result.get("error"))
time.sleep(2)const headers = { Authorization: `Bearer ${process.env.WAVESPEED_API_KEY}`, 'Content-Type': 'application/json' }
const { data: task } = await fetch('https://api.wavespeed.ai/api/v3/bytedance/seedream-v5.0-pro', {
method: 'POST',
headers,
body: JSON.stringify({
"prompt": "A glass teapot on a sunlit windowsill, soft morning light",
"aspect_ratio": "4:3",
"resolution": "2k"
}),
}).then((r) => r.json())
while (true) {
const { data: result } = await fetch(`https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`, { headers }).then((r) => r.json())
if (result.status === 'completed') { console.log(result.outputs); break }
if (result.status === 'failed') throw new Error(result.error)
await new Promise((r) => setTimeout(r, 2000))
}WaveSpeedAI vs Together AI
| WaveSpeedAI | Together AI | |
|---|---|---|
| Language models | OpenAI- and Anthropic-compatible API for closed and open models | OpenAI-compatible API centered on open-source models |
| Image, video, audio and 3D | A dedicated endpoint for every image, video, audio and 3D model, plus browser studios | Image, video and audio models on its serverless API |
| Billing | Pay as you go: per token for LLMs, a listed price per run for media, no monthly fees | Prepaid credits; serverless models billed per token, image or video; dedicated capacity per GPU hour |
| GPU infrastructure | None to manage: every model is fully hosted | Dedicated endpoints and GPU clusters, billed by the hour |
| Custom models | LoRA trainers for popular image and video models | Fine-tuning for open-source models, billed per training token |
| In the browser | Image, video, audio and 3D studios plus an LLM playground | A web playground |
FAQ
Is WaveSpeedAI a good Together AI alternative?
If you build with language models and also need images, video, audio or 3D, yes. One API key covers an OpenAI-compatible LLM API with closed and open models plus ready-to-call media endpoints, all pay as you go with nothing to deploy.
Can I keep using the OpenAI SDK?
Yes. Point the OpenAI SDK at https://llm.wavespeed.ai/v1 with your WaveSpeedAI API key and pass the model id. Anthropic-compatible and Responses endpoints are there for tools that expect them.
How do I generate images or video?
POST JSON to https://api.wavespeed.ai/api/v3/<model> with your API key. A prediction id comes back instantly. Poll the result endpoint, or pass a webhook and we call you.
How is it billed?
Pay as you go from one balance. Language models bill per token; media models at the listed price per run on each model page. No monthly fees and no GPU hours.
Can I train custom models?
Yes, for images and video. LoRA trainers cover popular image and video models, and LoRA endpoints run what you trained.
Can I try it for free?
Yes. Eligible new accounts get $1 in free credits to start building, with no credit card needed. Some premium models may not be available with trial credits.
One key for every model.
$1 in free credits for eligible new accounts. No card needed.