Kling Image 4.0 Text-to-Image generates photorealistic images from text prompts with strong typography and detailed composition, making it suitable for product visuals, posters, marketing assets, branded content, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.063per run·~15 / $1
ExamplesView all
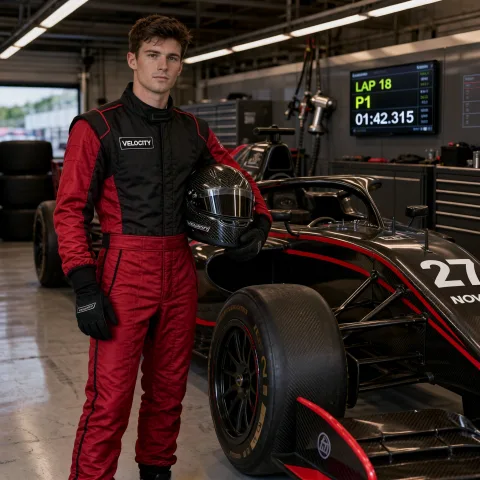
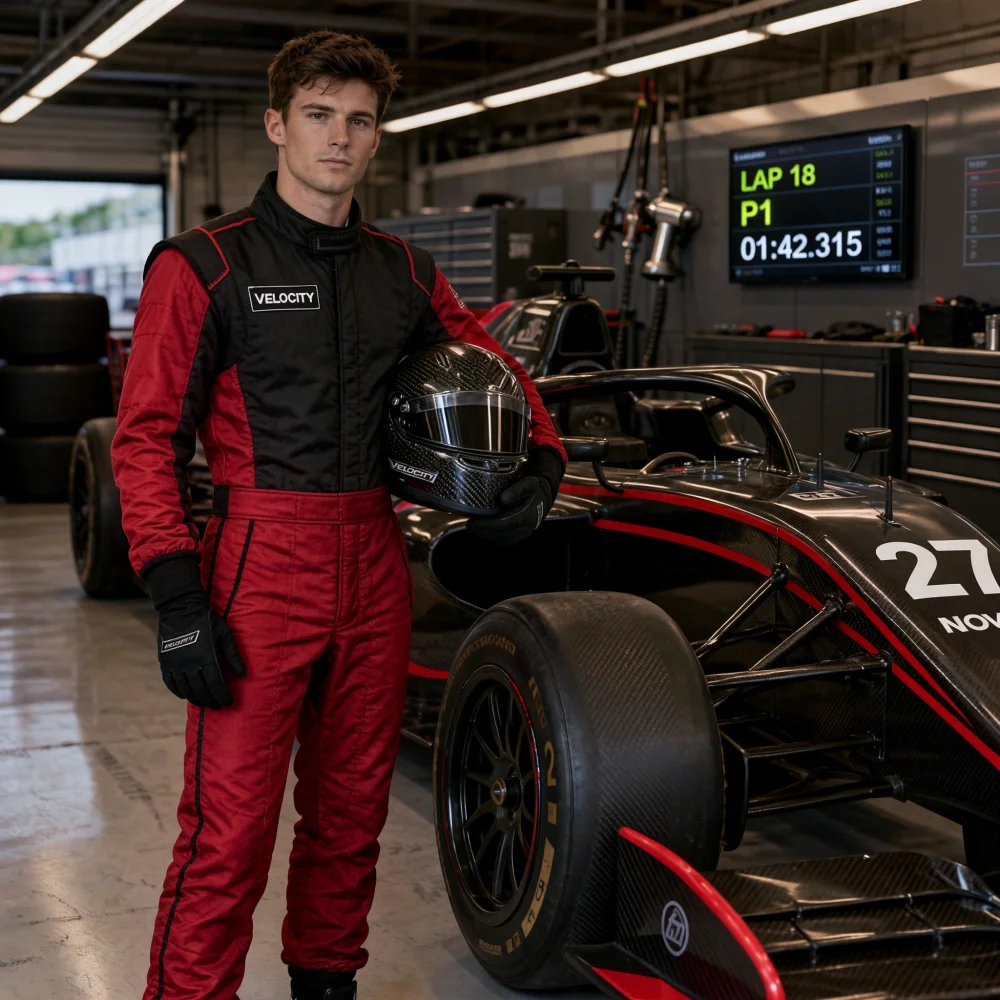
A stylish young UK male racing driver standing beside a sleek race car inside a modern pit garage, wearing a fitted red and black racing suit. The chest patch clearly reads “VELOCITY”. The race car displays the large number “27” and the word “NOVA” on the side. A digital screen behind her clearly reads “LAP 18”, “P1”, and “01:42.315”. Dynamic motorsport editorial photography, sharp technical details, realistic fabric, carbon fiber and lighting, all text and numbers perfectly legible.
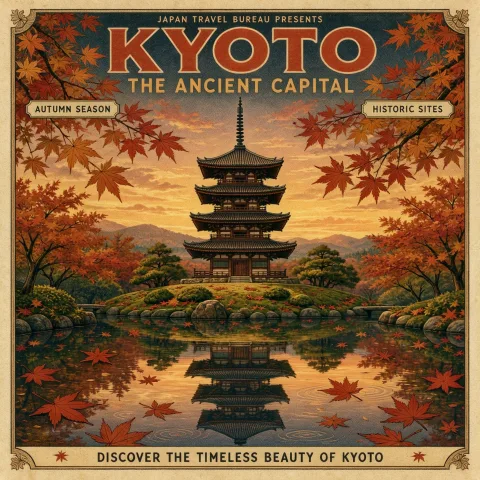
A vintage travel poster of Kyoto in autumn, bold headline text "KYOTO" at the top and "THE ANCIENT CAPITAL" below it, maple leaves framing a five-story pagoda at sunset, reflected in a still pond
Related Models
README
Kling Image 4.0 Text-to-Image
Kling Image 4.0 Text-to-Image generates images from text prompts at 2K, 4K, or 8K. Describe a scene, illustration, poster, or product concept, then choose the aspect ratio and number of images.
Why Choose This?
- Text-guided generation — Describe subjects, composition, lighting, and visual style.
- Resolution options — Choose from 2K, 4K, and 8K output tiers.
- Flexible framing — Select one of eight aspect ratios.
- Batch generation — Request 1–9 independent images per call.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Describe the image, including any text you want to appear. |
| aspect_ratio | No | 1:1, 3:2, 2:3, 3:4, 4:3, 9:16, 16:9, or 21:9. Default: 1:1. |
| resolution | No | Output resolution tier: 2k, 4k, or 8k. Default: 2k. |
| num_images | No | Number of independent output images, from 1 to 9. Default: 1. |
| output_format | No | Output format: png, jpeg, or webp. Default: png. |
How to Use
- Write a prompt — Describe the subject, setting, composition, and style.
- Choose framing and resolution — Select an aspect ratio and the
2k,4k, or8ktier. - Set the image count — Choose how many independent images to generate.
- Select a format and submit — Choose
png,jpeg, orwebp, then review the results.
Pricing
Pricing is based on the selected resolution and num_images.
| Resolution | Price per output image |
|---|---|
| 2K | $0.063 |
| 4K | $0.094 |
| 8K | $0.157 |
Total price = num_images × the selected resolution rate.
Example Costs
| Configuration | Price |
|---|---|
| 1 image at 2K | $0.063 |
| 4 images at 4K | $0.376 |
| 9 images at 8K | $1.413 |
Best Use Cases
- Concept development — Explore scenes, characters, and visual directions.
- Poster layouts — Draft promotional artwork with text instructions.
- Product concepts — Visualize products in different settings.
Pro Tips
- Specify the main subject, camera angle, lighting, and background.
- Put requested wording in quotation marks and describe its placement.
- Use multiple outputs to compare different interpretations of the same prompt.
Notes
promptis required.- Pixel dimensions depend on the selected resolution and aspect ratio.
- Review generated text and fine details before use.
Related Models
- Kling Image 4.0 Edit — Generate images guided by reference images and edit instructions.
- Kling Image 4.0 Image Set — Generate related images in one request.
- Kling Image 4.0 Long Image — Create ecommerce or webpage design images.
Kling Image v4.0 Text To Image API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/kwaivgi/kling-image-v4.0/text-to-image with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Kling Image v4.0 Text To Image below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "2k",
    "num_images": 1,
    "output_format": "png"
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/kwaivgi/kling-image-v4.0/text-to-image" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/kwaivgi/kling-image-v4.0/text-to-image";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "aspect_ratio": "1:1",
        "resolution": "2k",
        "num_images": 1,
        "output_format": "png"
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "1:1",
    "resolution": "2k",
    "num_images": 1,
    "output_format": "png"
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/kwaivgi/kling-image-v4.0/text-to-image", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Kling Image v4.0 Text To Image API — Frequently asked questions
What is the Kling Image v4.0 Text To Image API?
Kling Image v4.0 Text To Image is a Kuaishou model for image generation, exposed as a REST API on WaveSpeedAI. Kling Image 4.0 Text-to-Image generates photorealistic images from text prompts with strong typography and detailed composition, making it suitable for product visuals, posters, marketing assets, branded content, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Kling Image v4.0 Text To Image API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/kwaivgi/kling-image-v4.0/text-to-image.
How much does Kling Image v4.0 Text To Image cost per run or per second?
Kling Image v4.0 Text To Image starts at $0.063 per run or per second. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Kling Image v4.0 Text To Image accept?
Key inputs: `prompt`, `aspect_ratio`, `resolution`, `num_images`, `output_format`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/kwaivgi/kling-image-v4.0/text-to-image.
How do I get started with the Kling Image v4.0 Text To Image API?
Sign up for a free WaveSpeedAI account to claim starter credits, copy your API key from /accesskey, then call the endpoint shown in the API tab of the playground. The playground also auto-generates a code sample in Python, JavaScript, or cURL for the parameters you've set.
Can I use Kling Image v4.0 Text To Image outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (Kuaishou). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from Kuaishou
View all- kwaivgi/kling-effectsVideo Effects
- kwaivgi/kling-elementsVideo Tools
- kwaivgi/kling-elements-advancedVideo Tools
- kwaivgi/kling-image-o1Image Editing
- kwaivgi/kling-image-o3/editImage Editing
- kwaivgi/kling-image-o3/text-to-imageText to Image
- kwaivgi/kling-image-v3/editImage Editing
- kwaivgi/kling-image-v3/text-to-imageText to Image
More Text to Image models
View all- bytedance/seedream-v5.5Text to Image
- bytedance/seedream-v5.0-proText to Image
- google/nano-banana-2.1/text-to-imageText to Image
- google/nano-banana-pro/text-to-imageText to Image
- openai/gpt-image-2.6-sunburst/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- openai/gpt-image-2/text-to-imageText to Image
- openai/gpt-image-2.5-sunburst/text-to-imageText to Image