High-quality anime-style images from Prefect Pony XL with LoRA support for personalized characters and styles. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.02per run·~50 / $1
ExamplesView all
A young woman with iridescent hair that changes colors with light, floating above a swirling vortex of clouds, wearing a flowing crystalline gown, magical particles surrounding her, cinematic fantasy portrait, ultra-detailed.
A young woman with flowing auburn hair, wearing a soft cream-colored dress, standing in a sunlit meadow with floating butterflies, golden hour lighting, dreamy and ethereal atmosphere, ultra-realistic style.
A young woman with glowing holographic tattoos and electric blue hair, wearing a reflective cyberpunk jacket, standing on a neon-lit rooftop, rain falling, cinematic reflections on wet asphalt, ultra-detailed sci-fi portrait.
A man with tousled hair and warm brown eyes, leaning against a blooming cherry tree, petals drifting in the wind, soft pastel light, serene and heartwarming cinematic portrait.
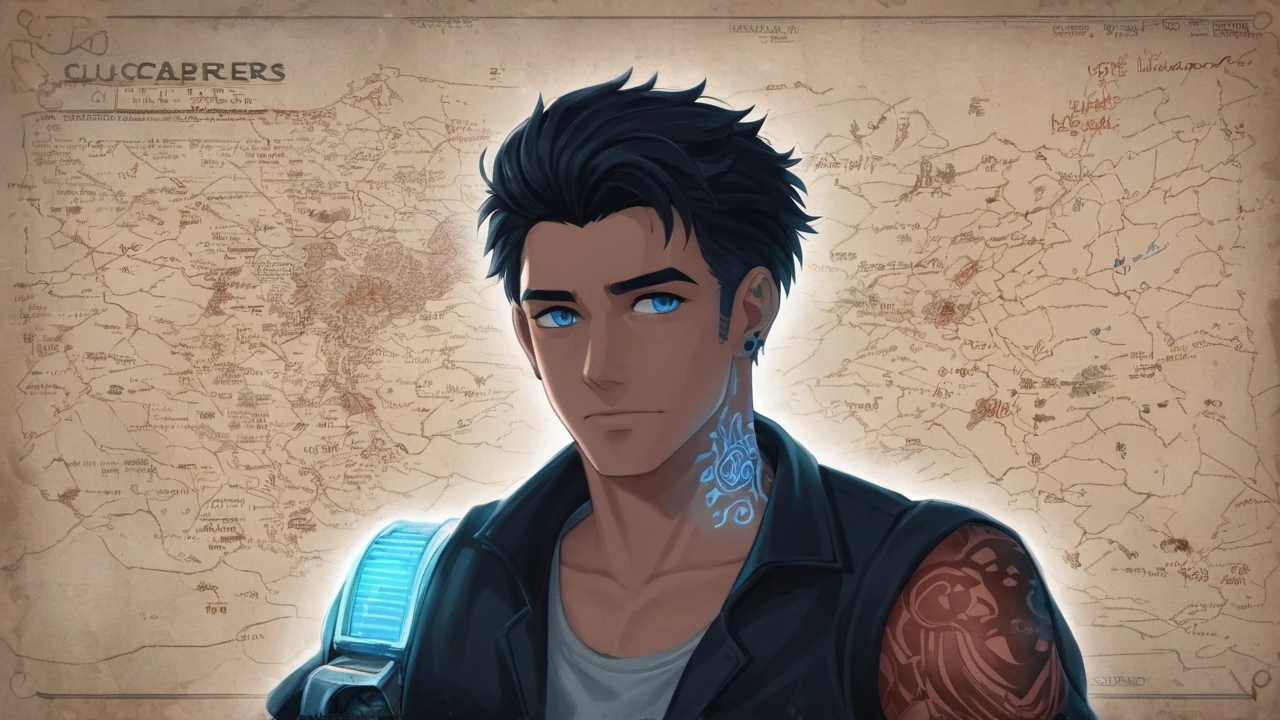
A man with cybernetic arm and glowing tattoos, holding a levitating holographic map, neon skyscrapers behind him, night rain reflections, high-detail cinematic portrait.
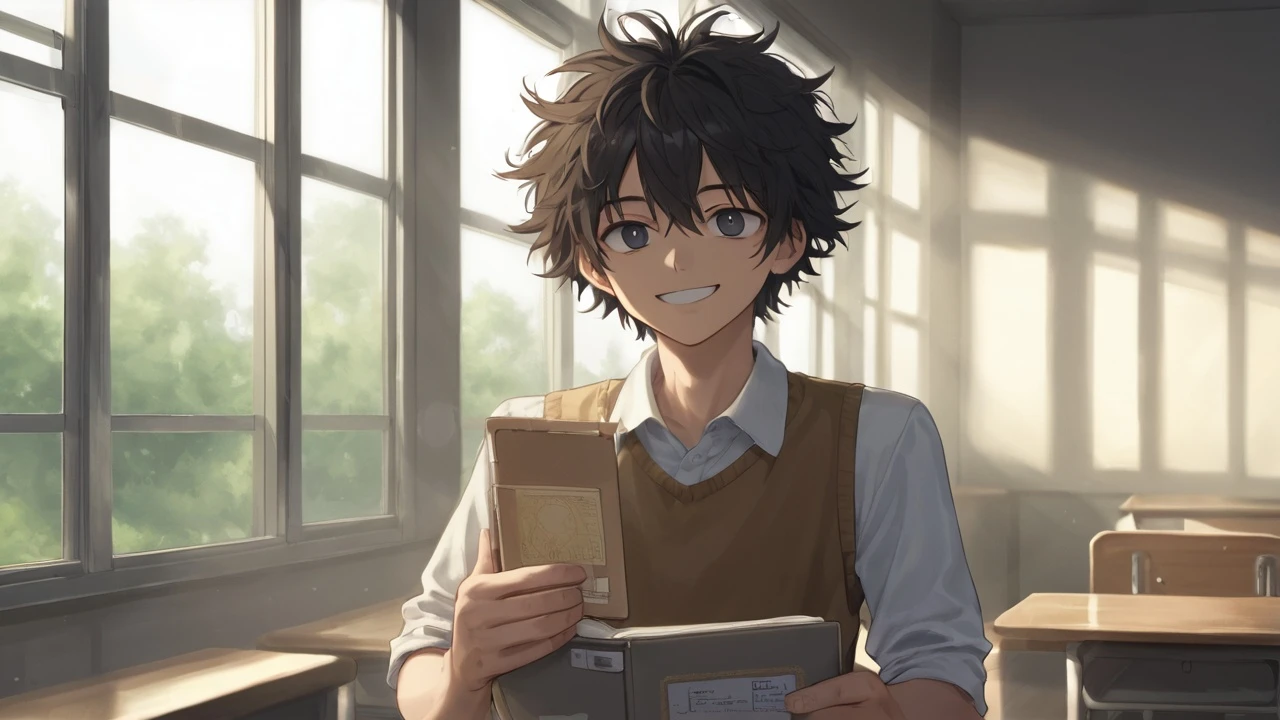
A young man with messy hair and casual school outfit, leaning against a classroom window, holding a notebook, sunlight streaming in, smiling with bright eyes, soft-focus background, authentic youthful vibe.
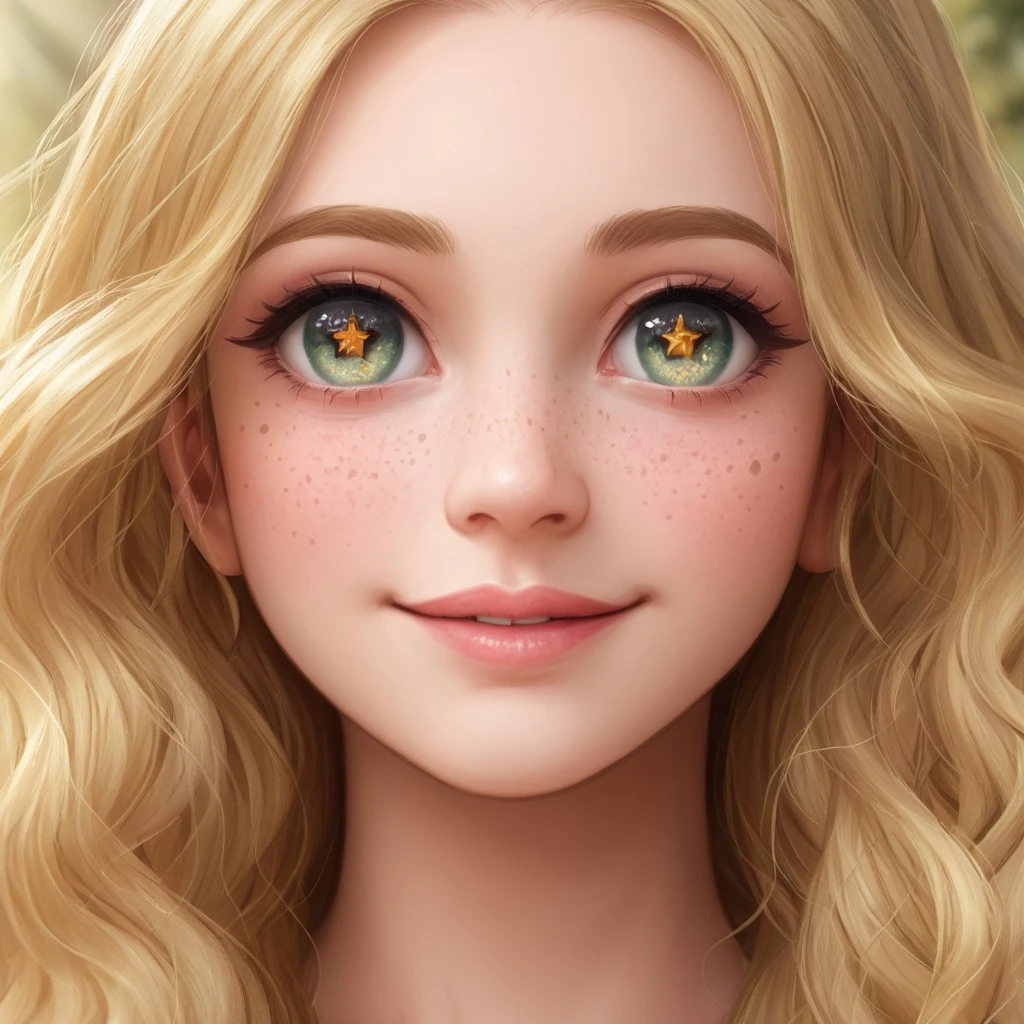
Close-up of a smiling teenage girl with freckles and long flowing hair, sunlight highlighting her face, sparkling bright eyes, natural makeup, soft golden hour glow, dreamy cinematic portrait, ultra-realistic.
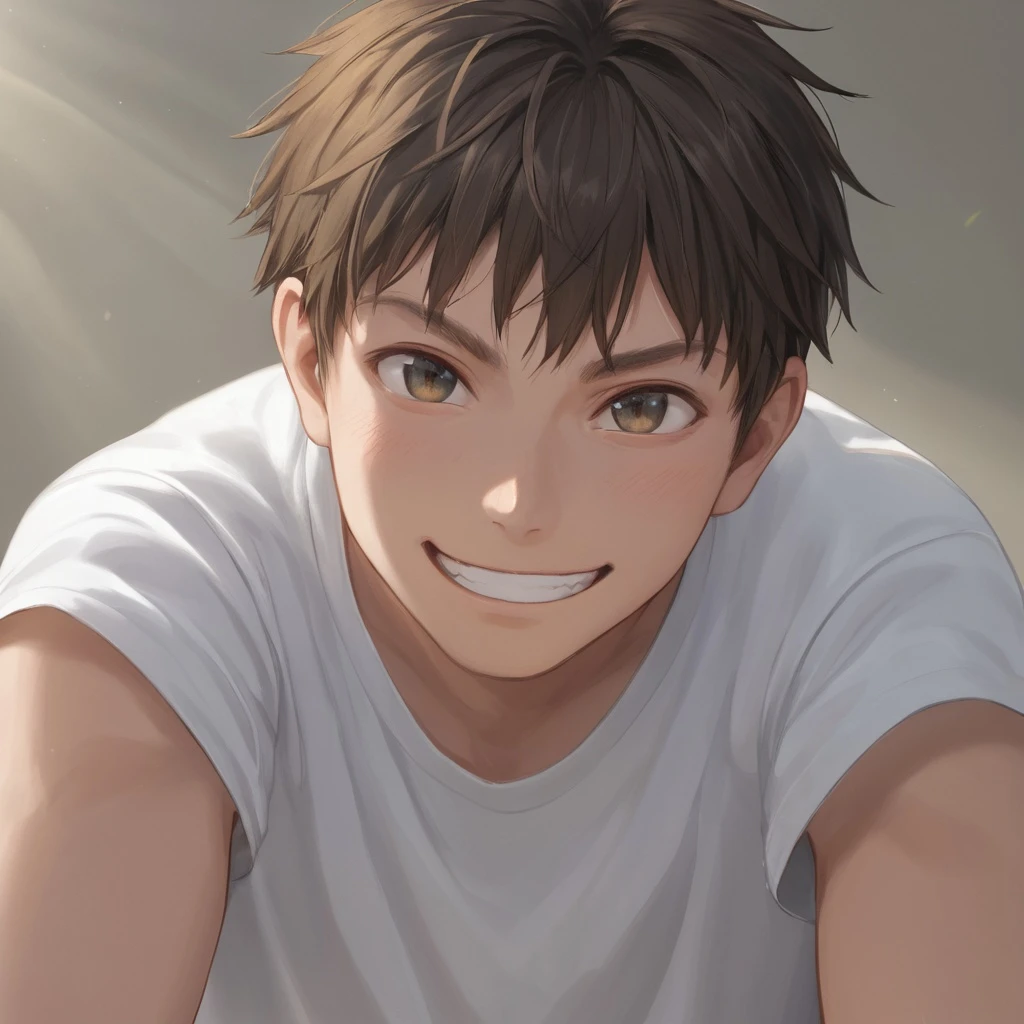
Close-up of a young man with tousled hair, wearing a casual t-shirt, leaning slightly forward, playful grin, sunlight streaming across his face, sharp and lively eyes, warm and energetic mood.
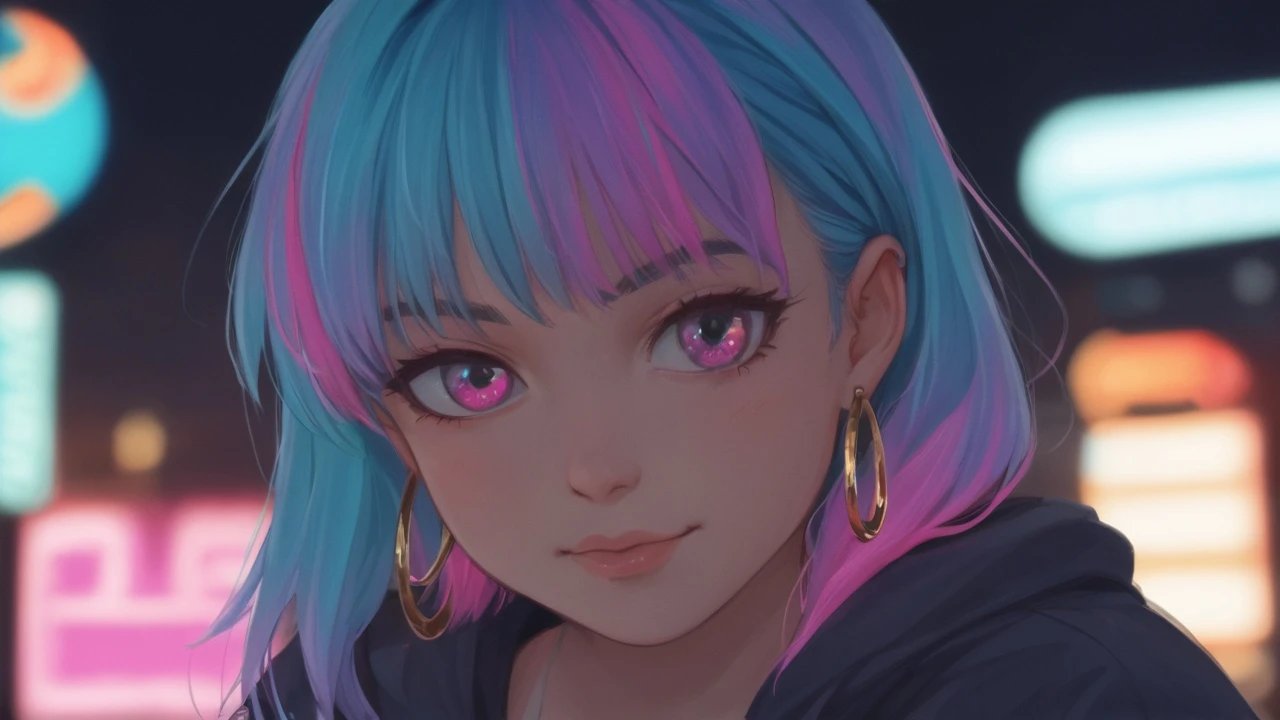
Close-up of a teenage girl with pastel-colored hair and hoop earrings, wearing an oversized hoodie, neon street lights reflecting in her eyes, confident expression, cinematic shallow depth of field, vibrant and striking.
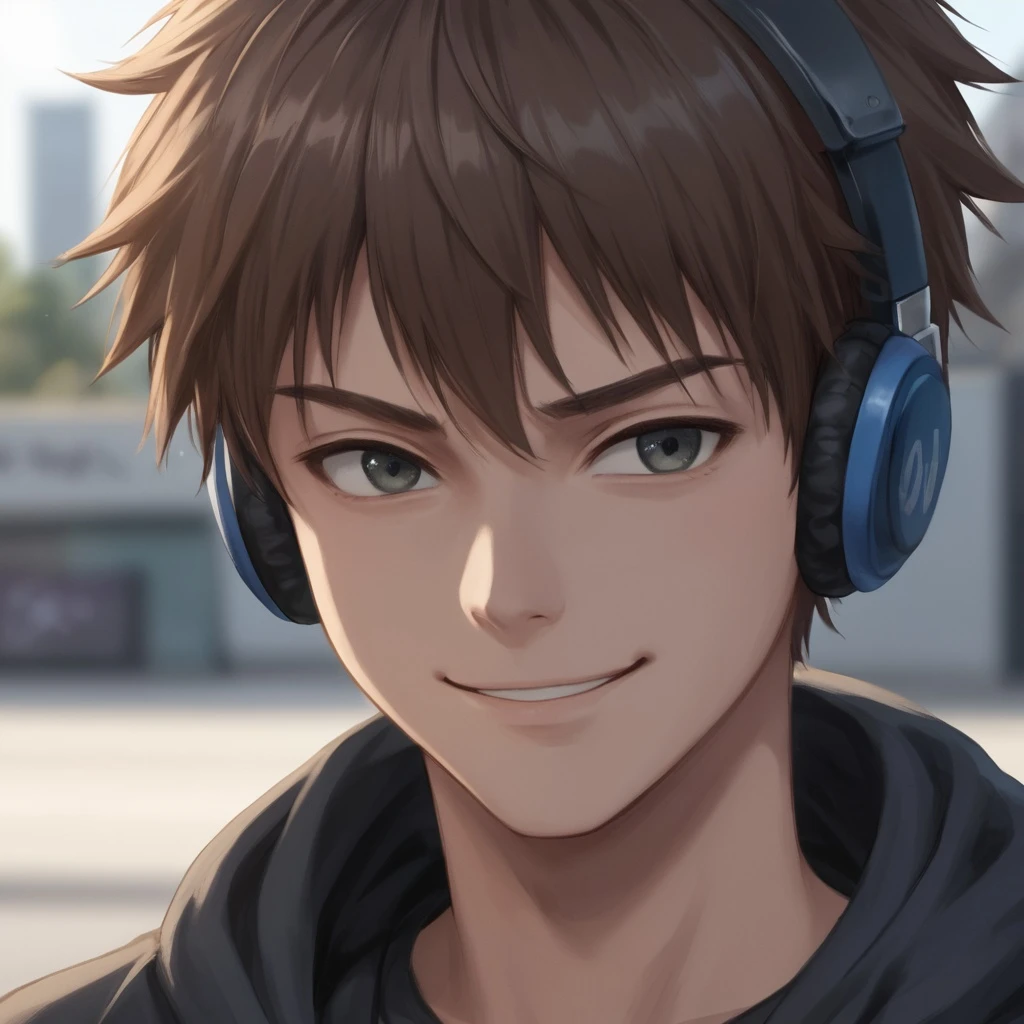
Close-up of a teenage boy with modern haircut, wearing headphones, smirking at the camera, urban graffiti blurred in the background, dramatic soft lighting, youthful and edgy vibe.
Related Models
README
Prefect Pony XL LoRA
Prefect Pony XL LoRA is an anime-focused text-to-image model with on-the-fly LoRA loading. It keeps the vibrant, stylized look of Prefect Pony XL and lets you apply up to 3 LoRAs in a single request for consistent characters, signature art styles, or specific concepts.
Why Choose This?
- Anime and illustration quality: Tuned for character art, expressive faces, clean linework, and bold color.
- LoRA support: Load up to 3 LoRAs per request, each with its own scale, for targeted style and subject control.
- Custom dimensions: Set any width and height to match your target format.
- Prompt adherence control: Adjust
guidance_scaleto trade off between creativity and strict prompt following. - Reproducible results: Fix the seed to recreate an image or explore controlled variations.
- Multiple output formats: Export as JPEG, PNG, or WebP.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Text description of the image you want to generate. |
| size | No | Output dimensions in pixels, as width*height. Default: 1024*1024. |
| loras | No | Up to 3 LoRA objects. Each object uses {path, scale}, where path is a direct .safetensors URL and scale controls LoRA intensity. Scale range: 0–4. Default: 1. |
| guidance_scale | No | How closely the image follows the prompt. Range: 0–20. Default: 3.5. |
| seed | No | Random seed for reproducibility. Use -1 for a random seed. |
| output_format | No | Output file format: jpeg, png, or webp. Default: jpeg. |
How to Use
- Write your prompt — describe the subject, style, colors, and mood. Tag-style prompts work well.
- Set dimensions — choose the width and height for your target format.
- Add LoRAs (optional) — provide up to 3 LoRAs, each with its own
pathandscale. - Adjust guidance scale (optional) — raise it for stricter prompt following, lower it for looser, more creative results.
- Set seed (optional) — use
-1for random, or a fixed number to reproduce a result. - Choose output format — JPEG for smaller files, PNG for lossless quality, WebP for a balance of both.
- Run — submit the request and download your image.
Pricing
Flat rate per image generation. Adding LoRAs does not change the price.
| Output | Cost |
|---|---|
| Per image | $0.02 |
Best Use Cases
- Consistent characters — apply a character LoRA to keep the same look across many images.
- Signature art styles — use a style LoRA to match a specific illustrator look or series aesthetic.
- Anime portraits and key art — generate expressive character portraits, covers, and posters.
- Concept and fan art — explore outfits, poses, and scenes quickly and affordably.
- Stickers and social content — produce eye-catching stylized visuals at volume.
Pro Tips for Best Results
- Use LoRAs trained for Pony-family SDXL models. LoRAs built for other base models will not load correctly.
- Include the LoRA's trigger words in your prompt when the LoRA requires them.
- Start with a LoRA scale around
0.7–1.0. Lower it if the style overpowers your prompt, and raise it if the effect is too subtle. - When stacking multiple LoRAs, reduce each scale slightly so they do not compete.
- Quality tags such as
score_9, score_8_up, score_7_upat the start of the prompt often improve results. - Keep the seed fixed while tuning LoRA scale or guidance so you can compare changes directly.
Notes
- The LoRA
pathmust be a publicly accessible direct download URL to a.safetensorsfile. - Generation time may vary with resolution, the number of LoRAs, and current queue load.
- For generation without LoRAs, see Prefect Pony XL.
Prefect Pony Xl Lora API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/wavespeed-ai/prefect-pony-xl-lora with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Prefect Pony Xl Lora below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "1024*1024",
    "guidance_scale": 3.5,
    "output_format": "jpeg"
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/wavespeed-ai/prefect-pony-xl-lora" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/wavespeed-ai/prefect-pony-xl-lora";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "size": "1024*1024",
        "guidance_scale": 3.5,
        "output_format": "jpeg"
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "1024*1024",
    "guidance_scale": 3.5,
    "output_format": "jpeg"
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/wavespeed-ai/prefect-pony-xl-lora", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Prefect Pony Xl Lora API — Frequently asked questions
What is the Prefect Pony Xl Lora API?
Prefect Pony Xl Lora is a WaveSpeedAI model for image generation, exposed as a REST API on WaveSpeedAI. High-quality anime-style images from Prefect Pony XL with LoRA support for personalized characters and styles. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Prefect Pony Xl Lora API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/wavespeed-ai/prefect-pony-xl-lora.
How much does Prefect Pony Xl Lora cost per run?
Prefect Pony Xl Lora starts at $0.02 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Prefect Pony Xl Lora accept?
Key inputs: `prompt`, `size`, `seed`, `guidance_scale`, `enable_base64_output`, `enable_sync_mode`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/wavespeed-ai/prefect-pony-xl-lora.
How long does Prefect Pony Xl Lora take to generate?
Reported generation time on WaveSpeedAI is around 24 seconds per request. This is an estimate, not a latency guarantee; queue time and input settings can change the total wait. live status is visible in the prediction record.
Can I use Prefect Pony Xl Lora outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (WaveSpeedAI). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.