Higgsfield API Alternative
開發者在 Higgsfield API 中尋找的模型,包括 Seedance 2.5 與 2.0、Kling 3.0 與 O3、Wan 3.0、開放權重的 MiniMax H3 與 Qwen Image 3.0,再加上 Seedream 5.0、Nano Banana 2 與 Pro,以及 GPT Image 2.5 與 2,全都只需一組 WaveSpeedAI API 金鑰。按使用量付費:點數永不過期,沒有會員制或訂閱。
正在評估 Higgsfield API?下方每個端點都已在 WaveSpeedAI 上線,並附有 Playground、範例與目前的單次執行價格。只需儲值一次,點數隨時可用且永不過期,可用於這些模型,以及其他 1,000 多個圖像、影片、音訊、3D 與語言模型。
概覽
關於 Higgsfield API Alternative
若您正在評估 Higgsfield API,以下是您可以在 WaveSpeedAI 上呼叫的內容。
開發者在 Higgsfield API 中尋找的模型,包括 Seedance 2.5 與 2.0、Kling 3.0 與 O3、Wan 3.0、開放權重的 MiniMax H3 與 Qwen Image 3.0,再加上 Seedream 5.0、Nano Banana 2 與 Pro,以及 GPT Image 2.5 與 2,全都只需一組 WaveSpeedAI API 金鑰。按使用量付費:點數永不過期,沒有會員制或訂閱。
正在評估 Higgsfield API?下方每個端點都已在 WaveSpeedAI 上線,並附有 Playground、範例與目前的單次執行價格。只需儲值一次,點數隨時可用且永不過期,可用於這些模型,以及其他 1,000 多個圖像、影片、音訊、3D 與語言模型。
以下是這些模型的 37 個 WaveSpeedAI 即時 REST 端點,涵蓋 Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image 工作流程。每個端點都有各自的 Playground、定價與範例,而且呼叫方式完全相同:POST JSON、取得 prediction id,再輪詢或接收 webhook。
它們與 WaveSpeedAI 上其他 1,000+ 個模型共用同一組 API 金鑰、同一份餘額與同一次整合,涵蓋文字轉圖片、文字轉影片、音訊、3D、放大、編輯與語言模型。
端點
所有 WaveSpeedAI API 端點
WaveSpeedAI 目前提供 37 個端點 — 請選擇符合您工作流程的變體。
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
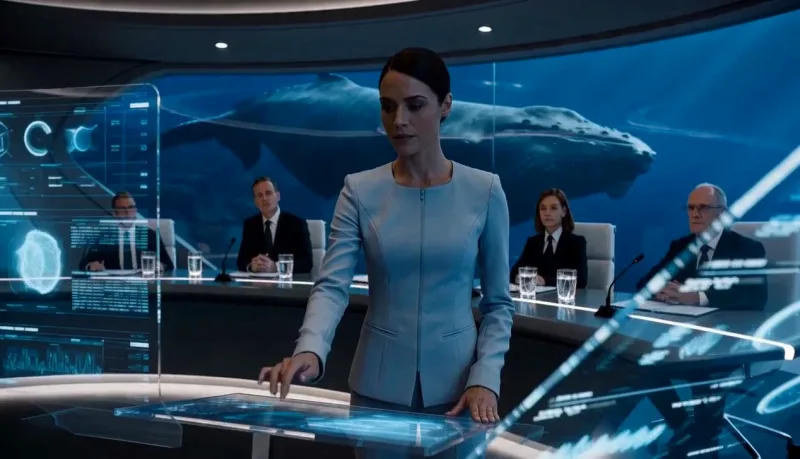
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
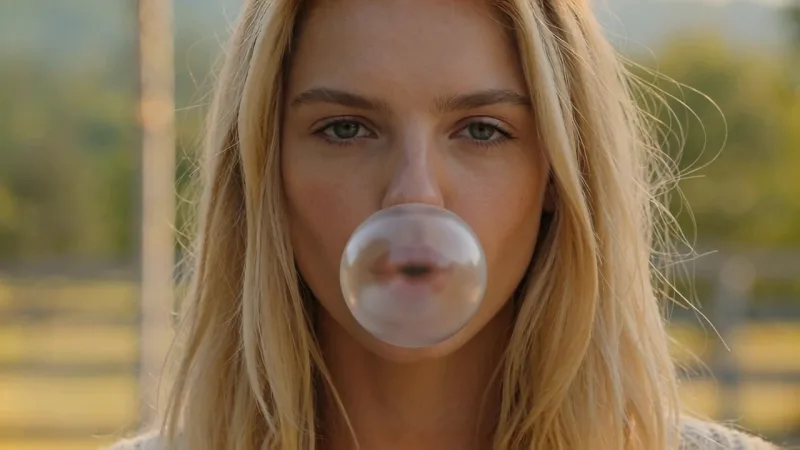
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
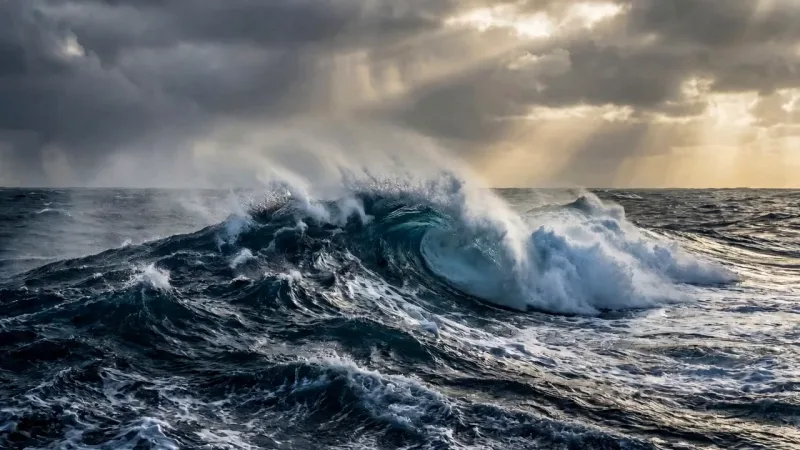
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
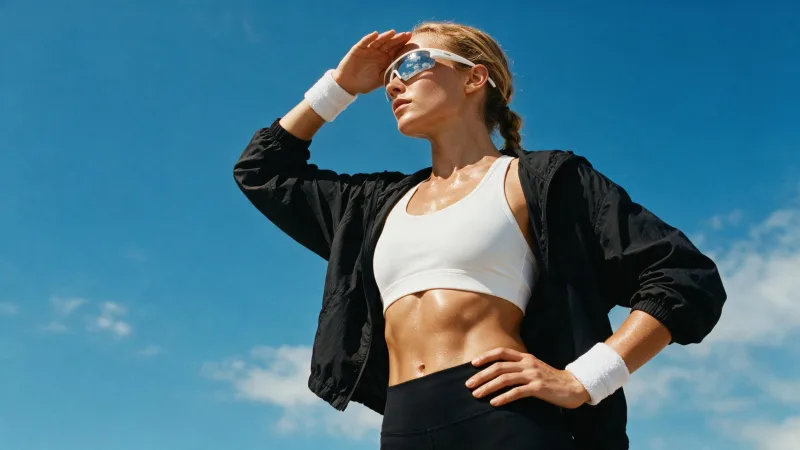
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
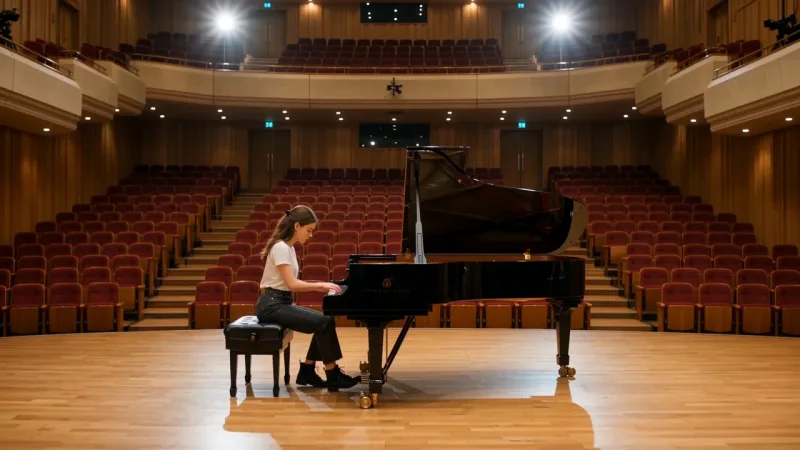
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
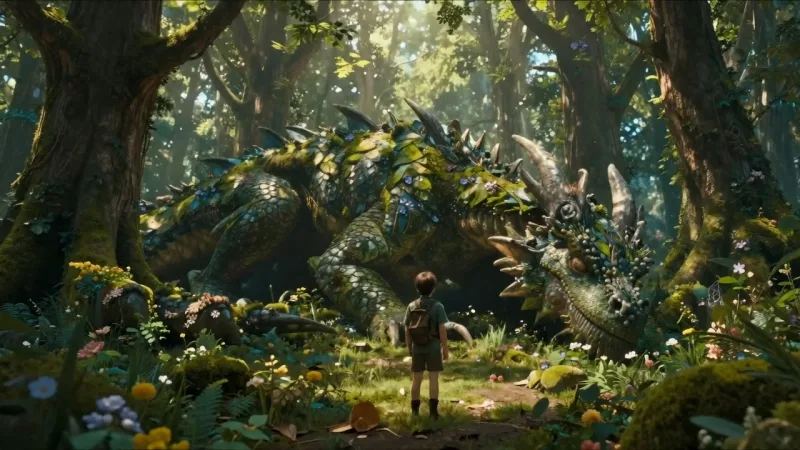
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
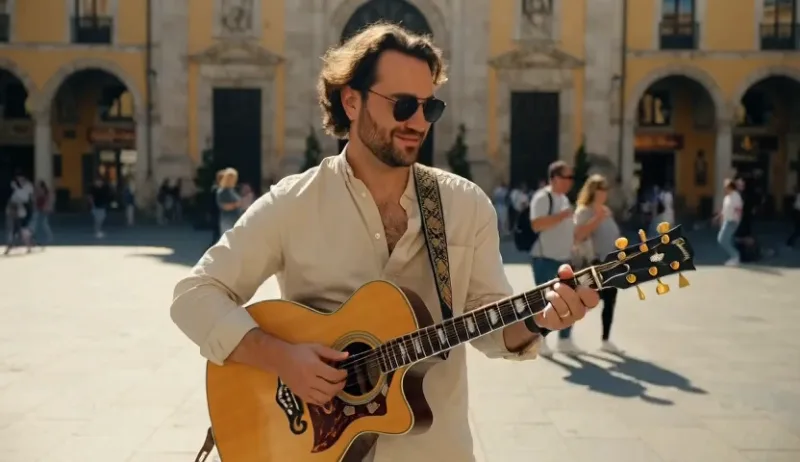
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
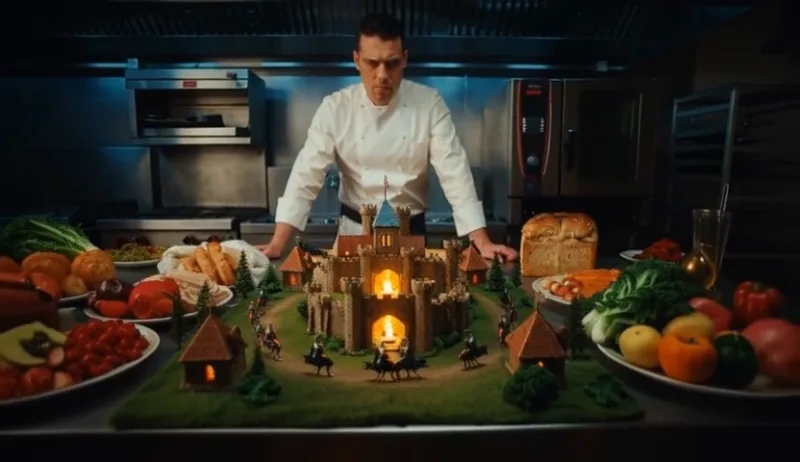
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
範例
看看 WaveSpeedAI 的實際效果
由 WaveSpeedAI API 生成的真實輸出。將滑鼠移到任一影片上即可預覽,點擊可開啟完整尺寸檢視器。
使用方式
如何使用 WaveSpeedAI API
從註冊到完成生成,只要四個步驟。完整的 Python、Node.js 與 cURL 範例請見下方的 API 區段。
- 01
取得 API 金鑰
註冊 WaveSpeedAI 帳號,並從控制台複製您的 API 金鑰。新帳號會獲贈免費入門點數 — 足以在開始計費前執行數十次 Playground。
- 02
提交 prediction
將您的輸入以 JSON 格式 POST 到 https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video。端點會立即回傳 prediction id — 生成是非同步進行的,因此推論期間您不需要保持連線。
- 03
輪詢完成狀態
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result。狀態為 completed 時回傳輸出;狀態為 failed、cancelled、timeout 或 deleted 時停止並回報錯誤;其他狀態則持續輪詢。
- 04
讀取輸出網址
當狀態為 "completed" 時,從 data.outputs[0] 讀取網址。該網址指向 WaveSpeedAI CDN 上您生成的媒體 — 依您呼叫的模型變體,可能是圖片、影片、音訊或 3D 檔案。
應用情境
您可以用這些模型打造什麼
開發者與創作者使用這些 API 的常見工作流程。
一個下午就能遷移 Higgsfield API 的整合
兩邊的 API 都是非同步的:提交 JSON、取得請求 ID,再輪詢或使用 webhook。在 WaveSpeedAI 上,只需以 Bearer API 金鑰 POST 至 /api/v3/<model> 並讀取預測結果,因此移植工作主要是更換基底 URL、驗證標頭與模型路徑。
圖像與影片在同一條管線
以 Nano Banana Pro、Seedream 5.0 或 GPT Image 2.5 生成靜態圖,再用 Seedance 2.5、Kling 3.0 或 Wan 3.0 的圖片轉影片讓它動起來,全程只需一組金鑰與一份餘額。Higgsfield API 公開的目錄並未列出 Nano Banana、Seedream 或 GPT Image。
支援 LoRA 的開放權重 MiniMax H3
WaveSpeedAI 託管開放權重的 MiniMax H3,提供文字轉影片、圖片轉影片、參考轉影片、影片編輯與延伸、用於自訂風格與角色的 LoRA 端點,以及文字轉圖片模式。
長單鏡頭與分級影片
Seedance 2.5 可生成最長 30 秒、帶原生音訊的單鏡頭;Kling 3.0 與 Kling O3 提供 Standard、Pro 與 4K 等級;Wan 3.0 另有 Prime 等級。可在同一套整合中逐鏡頭挑選。
Agent 與批次作業
可透過 Python 或 JavaScript SDK、純 HTTP、CLI 或 MCP 伺服器呼叫所有模型,讓程式開發 Agent 與批次腳本使用與您的應用程式相同的端點與價格。
技巧
這些模型的提示詞技巧
讓這些模型產出更好結果的實用建議 — 整理自在實際生產流程中,影片模型通用的有效做法。
- 01
明確描述運鏡
請使用具體的攝影術語,例如環繞、推軌、推近、左搖、升降鏡頭、手持跟拍。籠統的提示詞會得到靜態或隨機的運鏡;具名的運鏡方式能直接對應模型訓練資料中的動態意圖,大幅提升鏡頭品質。
- 02
以參考圖片鎖定角色身分
若提示詞依賴特定的人物、角色或產品,請在提示詞之外上傳參考圖片。沒有參考的話,身分會在畫格與鏡頭之間飄移,同一個角色每次生成都會長得略有不同。
- 03
描述光線與時段
「黃金時刻,柔和溫暖的定向光」或「陰天漫射光,石板灰的天空」這類光線提示,比含糊的畫質修飾語更能提升畫質與一致性。光線是模型最強的先驗條件之一。
- 04
使用負面提示詞抑制常見失誤
影片常用的負面詞:「畫格閃爍、動態模糊、浮水印、文字瑕疵、變形的手、低解析度、JPEG 壓縮」。負面提示詞不需額外成本,卻能明顯減少原本需要重新生成的次數。
- 05
選擇能涵蓋重點的最短時長
多數提示詞在 5 至 8 秒時效果最好。較長的影片會放大時間上的不一致(主體變形、環境漂移)。若需要 20 秒的片段,請生成三段 6 至 8 秒的影片再剪輯在一起,畫質會比單次生成一段長影片更高。
- 06
預先配合平台設定長寬比
TikTok / Reels / Shorts 用 9:16,橫式動態與 YouTube 用 16:9,貼文版面用 1:1。模型對不同長寬比的訓練略有差異,事後將 16:9 裁切為 9:16 會損失畫質,也失去模型原本設計的構圖。
定價
WaveSpeedAI API 定價
依輸出計費。最終費用會依您在各變體 Playground 中設定的參數(解析度、時長、輸出數量、參考素材)而調整。
API
呼叫 WaveSpeedAI API
請到 wavespeed.ai/accesskey 註冊取得 API 金鑰,然後透過 REST 提交 prediction。Playground 會為任何輸入組合產生可直接貼上的範例。
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)比較
WaveSpeedAI 與 Higgsfield API 比較
WaveSpeedAI 與 Higgsfield API 的差異所在。
WaveSpeedAI vs Higgsfield API: models
Higgsfield API 列出 82 個圖像與影片項目,包括自家的 Soul 與 Cinema Studio 模型,以及 Seedance、Kling、Wan、MiniMax 與 Qwen Image。WaveSpeedAI 涵蓋這些第三方系列,並新增 Nano Banana、Seedream、GPT Image、Veo、音訊、3D 與語言模型,總計 1,000 多個。
WaveSpeedAI vs Higgsfield API: credits
Higgsfield API 的儲值金額在購買一年後到期。WaveSpeedAI 的點數永不過期,也沒有會員制或訂閱:需要時再儲值,依請求付費,各端點的價格列於模型頁面與本頁的價格表。同樣的點數也可用於瀏覽器版工作室。
WaveSpeedAI vs Higgsfield API: open models
兩邊都有 MiniMax H3。在 WaveSpeedAI 上是由 WaveSpeedAI 託管的開放權重模型,除了標準的文字轉影片與圖片轉影片,還有 LoRA、參考轉影片、編輯、延伸與圖像端點。
常見問題
Higgsfield API Alternative — 常見問題
模型、定價、遷移 — 關於從 Higgsfield API 轉移到 WaveSpeedAI 的常見問題。
WaveSpeedAI 是 Higgsfield API 的替代方案嗎?
是的。WaveSpeedAI 以 REST 端點提供 Seedance 2.5 與 2.0、Kling 3.0 與 O3、Wan 3.0、MiniMax H3 與 Qwen Image 3.0,另有 Seedream 5.0、Nano Banana 2 與 Pro,以及 GPT Image 2.5 與 2,只需一組 API 金鑰,並按請求計價。
有哪些模型是 Higgsfield API 沒有列出、但我可以呼叫的?
Higgsfield API 公開的模型目錄不包含 Nano Banana、Seedream、GPT Image、Veo 或音訊模型。在 WaveSpeedAI 上,Nano Banana 2 與 Pro、Seedream 5.0、GPT Image 2.5 與 2、Veo 3.1 以及 ElevenLabs 語音,都與影片模型使用同一組金鑰。
如何從 Higgsfield API 切換過來?
在 /accesskey 建立金鑰,再以 Authorization: Bearer 標頭將輸入內容以 JSON POST 至 https://api.wavespeed.ai/api/v3/<model>。您會取得預測 ID,可輪詢 https://api.wavespeed.ai/api/v3/predictions/<id>/result,或傳入 webhook。請依本頁的端點清單,將各模型對應到 WaveSpeedAI 的路徑。
WaveSpeedAI 上的 MiniMax H3 是開放權重模型嗎?
是的。wavespeed-ai/minimax-h3 端點在 WaveSpeedAI 上執行開放權重的 MiniMax H3,包含用於自訂風格與角色的 LoRA 版本、參考轉影片、影片編輯與延伸,以及文字轉圖片模式。
需要會員或訂閱嗎?點數會過期嗎?
不需要會員,也沒有訂閱。WaveSpeedAI 採按使用量付費:需要時再儲值點數,並依各模型頁面與上方價格表所示的價格按請求付費。點數永不過期。符合資格的新帳號可獲得免費的入門點數。
如何呼叫這些 API?
註冊 WaveSpeedAI 帳號,從 /accesskey 複製您的 API 金鑰,然後將您的輸入以 JSON 格式 POST 到 https://api.wavespeed.ai/api/v3/<model>,例如 https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video。端點會回傳 prediction id。您可以輪詢結果端點,或傳入 webhook。Python / Node.js / cURL 範例見上方。
這些 API 的費用是多少?
本頁的端點每次執行 $0.02 起;各模型的價格見上方定價表與其模型頁面。實際費用會依您設定的參數(解析度、時長、輸出數量、參考素材)而調整,Playground 會在您提交前顯示。