Higgsfield API Alternative
开发者在 Higgsfield API 中寻找的模型——Seedance 2.5 与 2.0、Kling 3.0 与 O3、Wan 3.0、开放权重的 MiniMax H3 和 Qwen Image 3.0——以及 Seedream 5.0、Nano Banana 2 与 Pro、GPT Image 2.5 与 2,全部通过一个 WaveSpeedAI API 密钥调用。按量付费:积分永不过期,没有会员或订阅。
正在评估 Higgsfield API?下方每个端点都已在 WaveSpeedAI 上线,并提供 Playground、示例和当前的单次调用价格。一次充值,随时使用——积分永不过期——可调用这些模型以及 1,000+ 个其他图像、视频、音频、3D 和语言模型。
概览
关于 Higgsfield API Alternative
如果你正在评估Higgsfield API,这里是你在 WaveSpeedAI 上可以调用的内容。
开发者在 Higgsfield API 中寻找的模型——Seedance 2.5 与 2.0、Kling 3.0 与 O3、Wan 3.0、开放权重的 MiniMax H3 和 Qwen Image 3.0——以及 Seedream 5.0、Nano Banana 2 与 Pro、GPT Image 2.5 与 2,全部通过一个 WaveSpeedAI API 密钥调用。按量付费:积分永不过期,没有会员或订阅。
正在评估 Higgsfield API?下方每个端点都已在 WaveSpeedAI 上线,并提供 Playground、示例和当前的单次调用价格。一次充值,随时使用——积分永不过期——可调用这些模型以及 1,000+ 个其他图像、视频、音频、3D 和语言模型。
下方是这些模型在 WaveSpeedAI 上的 37 个在线 REST 端点,涵盖 Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image 工作流。每个端点都有自己的 Playground、定价和示例,调用方式完全一致:POST JSON,拿到预测 ID,然后轮询或接收 webhook。
它们与 WaveSpeedAI 上其他 1,000 多个模型共用同一个 API 密钥、同一份余额和同一次集成,涵盖文生图、文生视频、音频、3D、放大、编辑以及语言模型。
端点
全部 WaveSpeedAI API 端点
WaveSpeedAI 现已提供 37 个端点——请选择适合你工作流的变体。
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
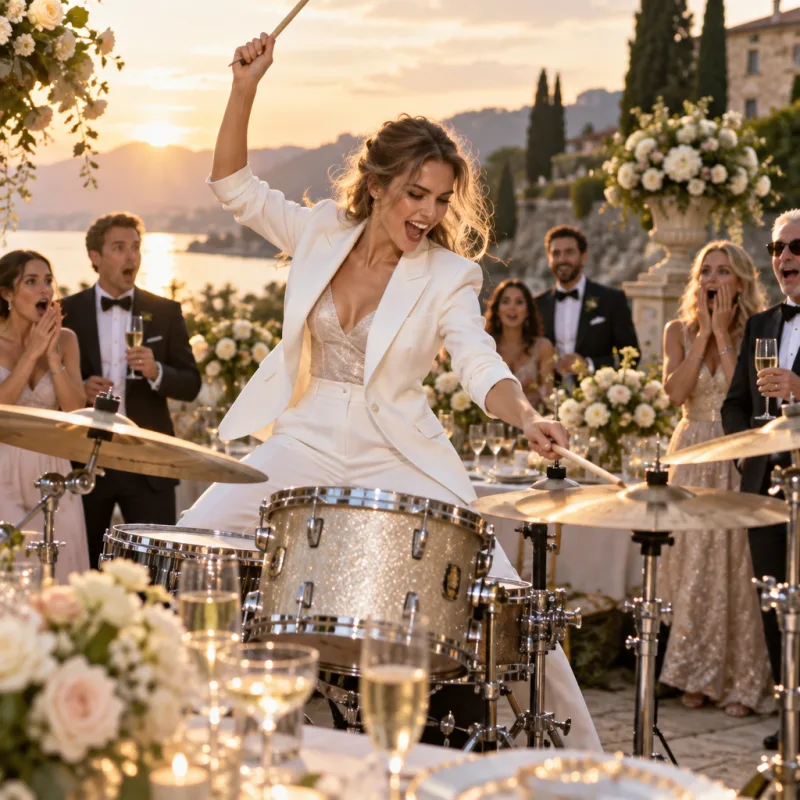
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
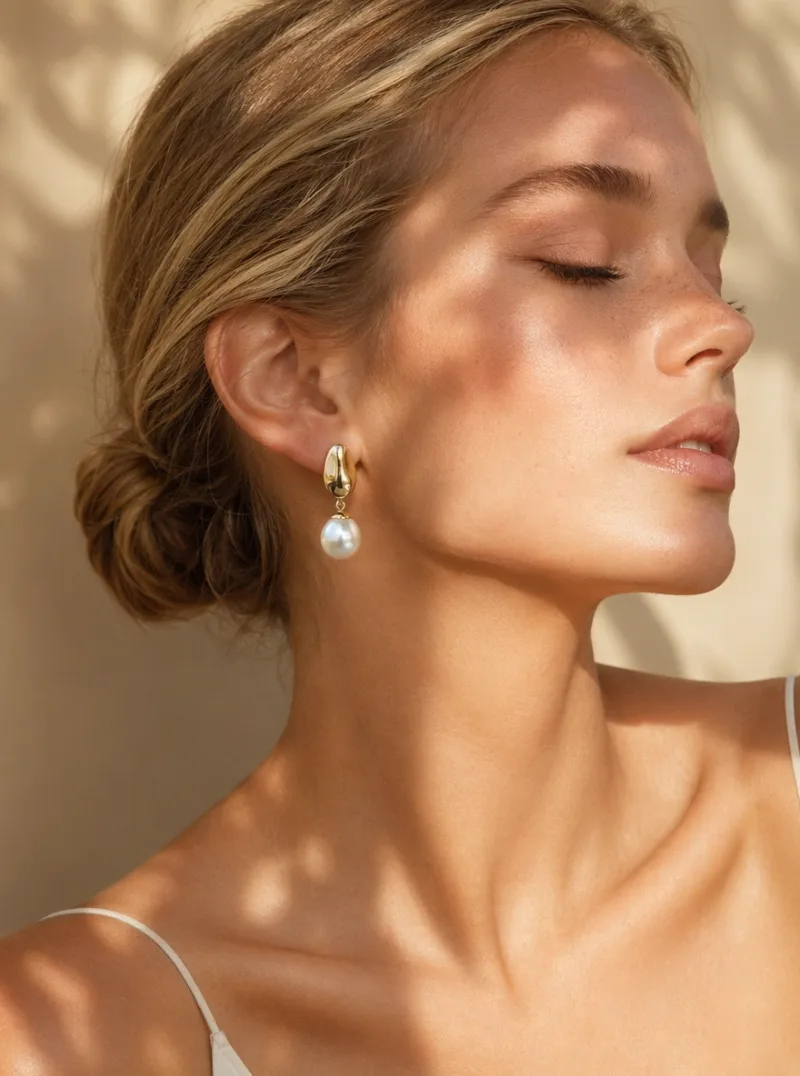
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
示例
看看 WaveSpeedAI 的实际效果
由 WaveSpeedAI API 生成的真实输出。悬停在任意视频上即可预览,点击可打开全尺寸查看器。
使用方法
如何使用 WaveSpeedAI API
从注册到完成一次生成,只需四步。完整的 Python、Node.js 和 cURL 示例见下方的 API 部分。
- 01
获取 API 密钥
注册 WaveSpeedAI 账号,并从控制台复制你的 API 密钥。新账号附带免费体验额度——足够在开始计费前把 Playground 运行几十次。
- 02
提交预测
把你的输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video。端点会立即返回预测 ID——生成是异步的,因此推理期间你无需保持连接。
- 03
轮询完成状态
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result。状态为 completed 时返回输出;状态为 failed、cancelled、timeout 或 deleted 时以错误终止;其他任何状态都继续轮询。
- 04
读取输出 URL
状态变为 "completed" 后,从 data.outputs[0] 读取 URL。该 URL 指向 WaveSpeedAI CDN 上你生成的媒体——具体是图片、视频、音频还是 3D 文件,取决于你调用的模型变体。
应用场景
用这些模型可以构建什么
开发者和创作者使用这些 API 的常见工作流。
一个下午即可迁移 Higgsfield API 集成
两种 API 都是异步的:提交 JSON,获得请求 ID,然后轮询或接收 Webhook。在 WaveSpeedAI 上,您使用 Bearer API 密钥向 /api/v3/<model> 发送 POST 请求并读取预测结果,因此迁移基本只需更换基础 URL、认证请求头和模型路径。
图像与视频在同一条流水线中完成
先用 Nano Banana Pro、Seedream 5.0 或 GPT Image 2.5 生成静态图,再用 Seedance 2.5、Kling 3.0 或 Wan 3.0 图生视频让它动起来,全程使用同一个密钥和同一份余额。Higgsfield API 公开的模型目录中没有列出 Nano Banana、Seedream 或 GPT Image。
支持 LoRA 的开放权重 MiniMax H3
WaveSpeedAI 托管开放权重的 MiniMax H3,提供文生视频、图生视频、参考生视频、视频编辑与延长、用于自定义风格和角色的 LoRA 端点,以及文生图模式。
长单镜头与分档视频
Seedance 2.5 可渲染最长 30 秒、自带原生音频的单镜头;Kling 3.0 和 Kling O3 提供 Standard、Pro 和 4K 档位;Wan 3.0 增加了 Prime 档位。同一套集成中可按镜头自由选择。
智能体与批量任务
可通过 Python 或 JavaScript SDK、普通 HTTP、CLI 或 MCP 服务器调用每个模型,让编码智能体和批处理脚本使用与您的应用相同的端点和价格。
技巧
这些模型的提示词技巧
让这些模型输出更好结果的实用建议——总结自生产流水线中各类视频模型都适用的做法。
- 01
明确说明运镜方式
使用具体的摄影术语——orbit、dolly-in、push-in、pan-left、crane shot、handheld follow。笼统的提示词会产生静止或随意的镜头选择;命名的运镜方式能直接对应到模型训练数据中的运动意图,大幅提升镜头质量。
- 02
用参考图像锚定角色身份
如果提示词依赖特定的人物、角色或产品,请在提示词之外上传参考图像。没有参考时,身份会在帧与帧之间、镜头与镜头之间漂移——同一个角色每次生成看起来都像略有不同的人。
- 03
描述光线和时间
「黄金时刻,柔和温暖的定向光」或「阴天漫射光,石板灰的天空」这类光线提示,比含糊的画质修饰词更能提升质量和一致性。光线是模型所依据的最强先验之一。
- 04
用负面提示词抑制常见的失败模式
视频常用的负面提示词:「帧闪烁、运动模糊、水印、文字伪影、变形的手、低分辨率、JPEG 压缩」。负面提示词不花一分钱,却能明显降低您原本需要重新抽取的生成比例。
- 05
选择能涵盖该节拍的最短时长
大多数提示词在 5-8 秒时效果最好。更长的片段会放大时间上的不一致(主体变形、环境漂移)。如果需要 20 秒的序列,请生成三段 6-8 秒的片段再剪辑在一起——质量比一次长生成更高。
- 06
预先让画幅比例匹配平台
TikTok / Reels / Shorts 用 9:16,横屏信息流和 YouTube 用 16:9,帖子宫格用 1:1。模型对每种画幅比例的训练略有不同——事后把 16:9 裁成 9:16,会同时损失保真度和模型原本设计的构图。
定价
WaveSpeedAI API 定价
按输出计费。最终费用会随你在各变体 Playground 中设置的参数(分辨率、时长、输出数量、参考素材)而变化。
API
调用 WaveSpeedAI API
在 wavespeed.ai/accesskey 注册并获取 API 密钥,然后通过 REST 提交预测。Playground 可以为任意输入组合生成可直接粘贴的示例代码。
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)对比
WaveSpeedAI 与Higgsfield API对比
WaveSpeedAI 与Higgsfield API的差异所在。
WaveSpeedAI 对比 Higgsfield API: models
Higgsfield API 列出 82 个图像和视频条目,包括其自有的 Soul 和 Cinema Studio 模型,以及 Seedance、Kling、Wan、MiniMax 和 Qwen Image。WaveSpeedAI 涵盖这些第三方模型系列,并增加了 Nano Banana、Seedream、GPT Image、Veo、音频、3D 和语言模型,总计 1,000+ 个。
WaveSpeedAI 对比 Higgsfield API: credits
Higgsfield API 的余额在购买一年后过期。WaveSpeedAI 的积分永不过期,没有会员或订阅:需要时充值,按请求付费,每个端点的价格见其模型页面和本页的价格表。同样的积分也可用于浏览器端的创作工作室。
WaveSpeedAI 对比 Higgsfield API: open models
两者都提供 MiniMax H3。在 WaveSpeedAI 上,它是由 WaveSpeedAI 托管的开放权重模型,除标准的文生视频和图生视频外,还提供 LoRA、参考生视频、编辑、延长和图像端点。
常见问题
Higgsfield API Alternative — 常见问题
模型、定价、迁移——关于从Higgsfield API迁移到 WaveSpeedAI 的常见问题。
WaveSpeedAI 可以替代 Higgsfield API 吗?
可以。WaveSpeedAI 以 REST 端点提供 Seedance 2.5 与 2.0、Kling 3.0 与 O3、Wan 3.0、MiniMax H3 和 Qwen Image 3.0,另有 Seedream 5.0、Nano Banana 2 与 Pro、GPT Image 2.5 与 2,只需一个 API 密钥,按请求付费。
有哪些模型 Higgsfield API 未列出,但我可以调用?
Higgsfield API 公开的模型目录不包含 Nano Banana、Seedream、GPT Image、Veo 或音频模型。在 WaveSpeedAI 上,Nano Banana 2 与 Pro、Seedream 5.0、GPT Image 2.5 与 2、Veo 3.1 以及 ElevenLabs 语音,与视频模型使用同一个密钥。
如何从 Higgsfield API 迁移过来?
在 /accesskey 创建密钥,然后携带 Authorization: Bearer 请求头,将输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/<model>。您会收到一个预测 ID;轮询 https://api.wavespeed.ai/api/v3/predictions/<id>/result 或传入 Webhook 即可。请根据本页的端点列表,把每个模型映射到对应的 WaveSpeedAI 路径。
WaveSpeedAI 上的 MiniMax H3 是开放权重模型吗?
是的。wavespeed-ai/minimax-h3 端点在 WaveSpeedAI 上运行开放权重的 MiniMax H3,包括用于自定义风格和角色的 LoRA 变体、参考生视频、视频编辑与延长,以及文生图模式。
需要会员或订阅吗?积分会过期吗?
无需会员,也没有订阅。WaveSpeedAI 按量付费:需要时充值积分,按请求付费,价格见各模型页面和上方的价格表。积分永不过期。符合条件的新账户可获赠免费体验积分。
如何调用这些 API?
注册 WaveSpeedAI 账号,从 /accesskey 复制你的 API 密钥,然后把输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/<model>,例如 https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video。端点会返回预测 ID。轮询结果端点,或传入 webhook。上方有 Python / Node.js / cURL 示例。
这些 API 的费用是多少?
本页的端点每次调用 $0.02 起;各模型的价格见上方的定价表及其模型页面。实际费用会随你设置的参数(分辨率、时长、输出数量、参考素材)而变化,Playground 会在你提交前显示费用。