Higgsfield API Alternative
Những mô hình mà nhà phát triển tìm kiếm ở Higgsfield API — Seedance 2.5 và 2.0, Kling 3.0 và O3, Wan 3.0, MiniMax H3 mã nguồn mở trọng số và Qwen Image 3.0 — cùng Seedream 5.0, Nano Banana 2 và Pro, GPT Image 2.5 và 2, tất cả trên một API key WaveSpeedAI. Trả tiền theo mức dùng: credit không bao giờ hết hạn, không cần gói thành viên hay thuê bao.
Đang cân nhắc Higgsfield API? Mọi endpoint bên dưới đều đã hoạt động trên WaveSpeedAI, kèm playground, ví dụ và giá hiện hành cho mỗi lượt chạy. Nạp tiền một lần và dùng credit bất cứ khi nào bạn muốn — credit không bao giờ hết hạn — cho các mô hình này và hơn 1.000 mô hình ảnh, video, âm thanh, 3D và ngôn ngữ khác.
Tổng quan
Giới thiệu về Higgsfield API Alternative
Những gì bạn có thể gọi trên WaveSpeedAI nếu đang cân nhắc Higgsfield API.
Những mô hình mà nhà phát triển tìm kiếm ở Higgsfield API — Seedance 2.5 và 2.0, Kling 3.0 và O3, Wan 3.0, MiniMax H3 mã nguồn mở trọng số và Qwen Image 3.0 — cùng Seedream 5.0, Nano Banana 2 và Pro, GPT Image 2.5 và 2, tất cả trên một API key WaveSpeedAI. Trả tiền theo mức dùng: credit không bao giờ hết hạn, không cần gói thành viên hay thuê bao.
Đang cân nhắc Higgsfield API? Mọi endpoint bên dưới đều đã hoạt động trên WaveSpeedAI, kèm playground, ví dụ và giá hiện hành cho mỗi lượt chạy. Nạp tiền một lần và dùng credit bất cứ khi nào bạn muốn — credit không bao giờ hết hạn — cho các mô hình này và hơn 1.000 mô hình ảnh, video, âm thanh, 3D và ngôn ngữ khác.
Các endpoint bên dưới là 37 endpoint REST WaveSpeedAI đang hoạt động cho các mô hình này, bao gồm các quy trình Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image. Mỗi endpoint có playground, giá và ví dụ riêng, và tất cả đều được gọi theo cùng một cách: POST JSON, nhận lại prediction id, rồi poll hoặc nhận webhook.
Chúng dùng chung một API key, một số dư và một lần tích hợp với hơn 1.000 mô hình khác trên WaveSpeedAI, từ text-to-image và text-to-video đến âm thanh, 3D, nâng cấp, chỉnh sửa và mô hình ngôn ngữ.
Endpoint
Tất cả endpoint API WaveSpeedAI
37 endpoint hiện có sẵn trên WaveSpeedAI — hãy chọn biến thể phù hợp với quy trình của bạn.
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
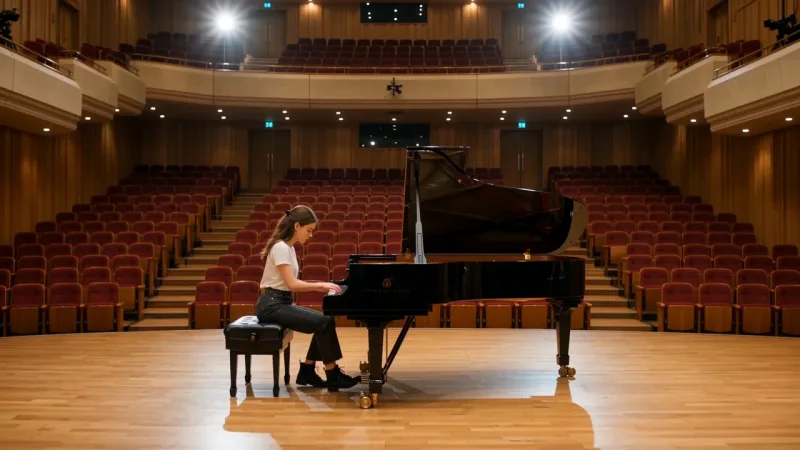
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
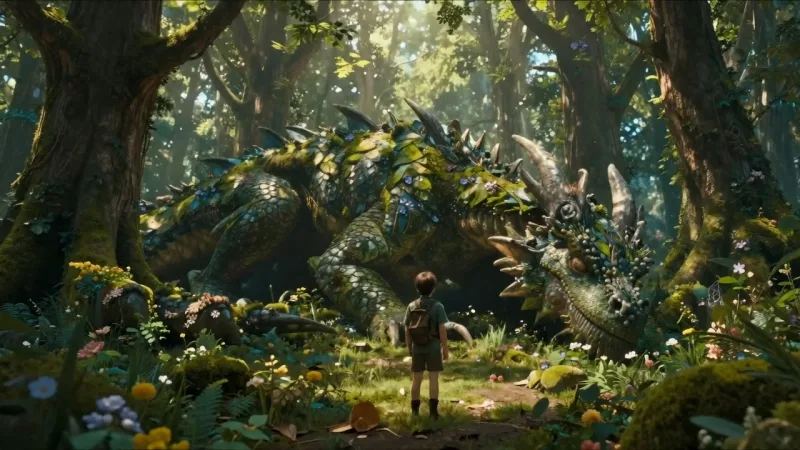
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
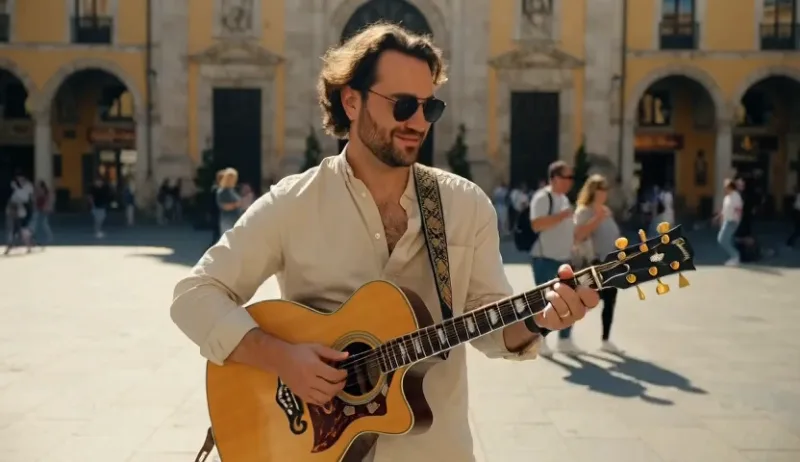
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
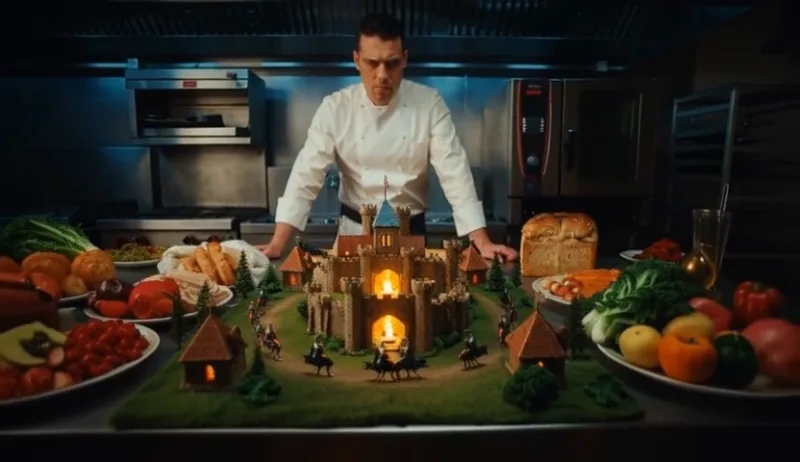
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
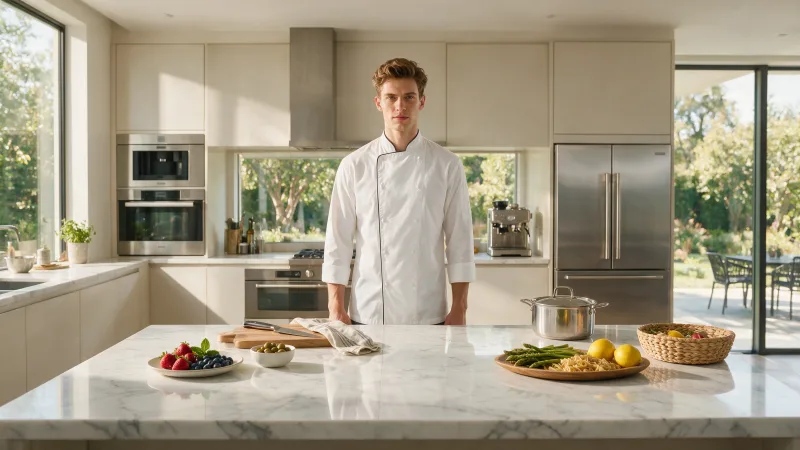
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
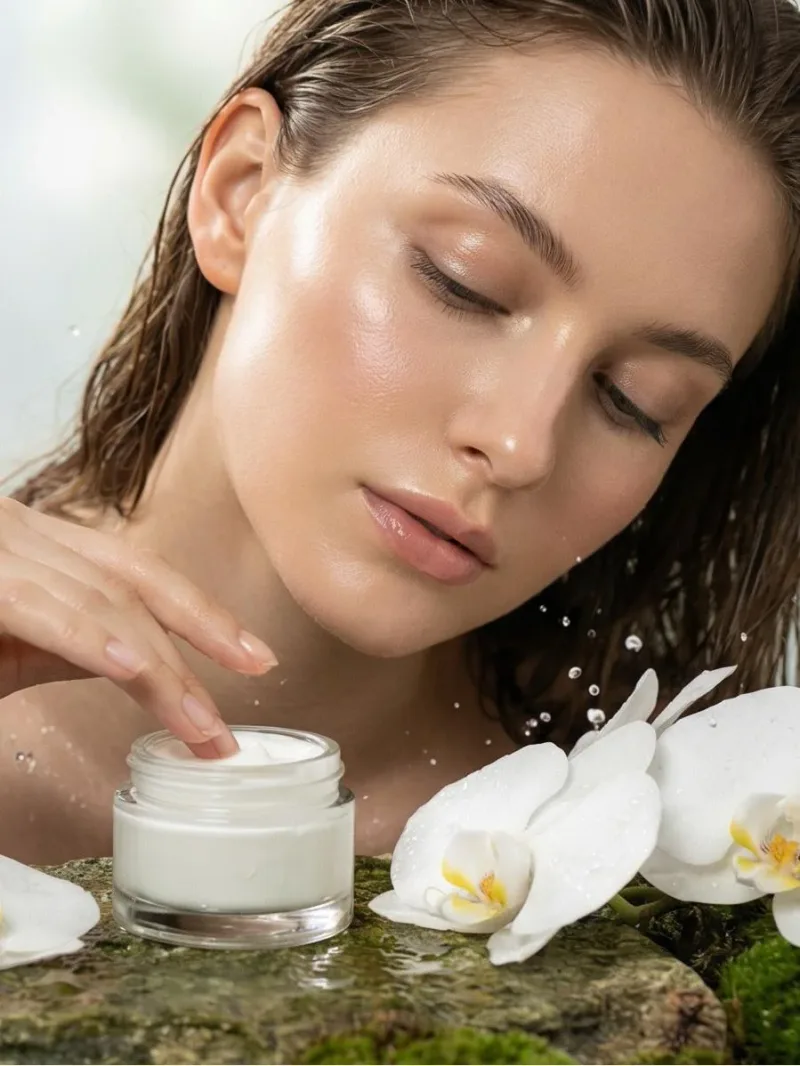
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
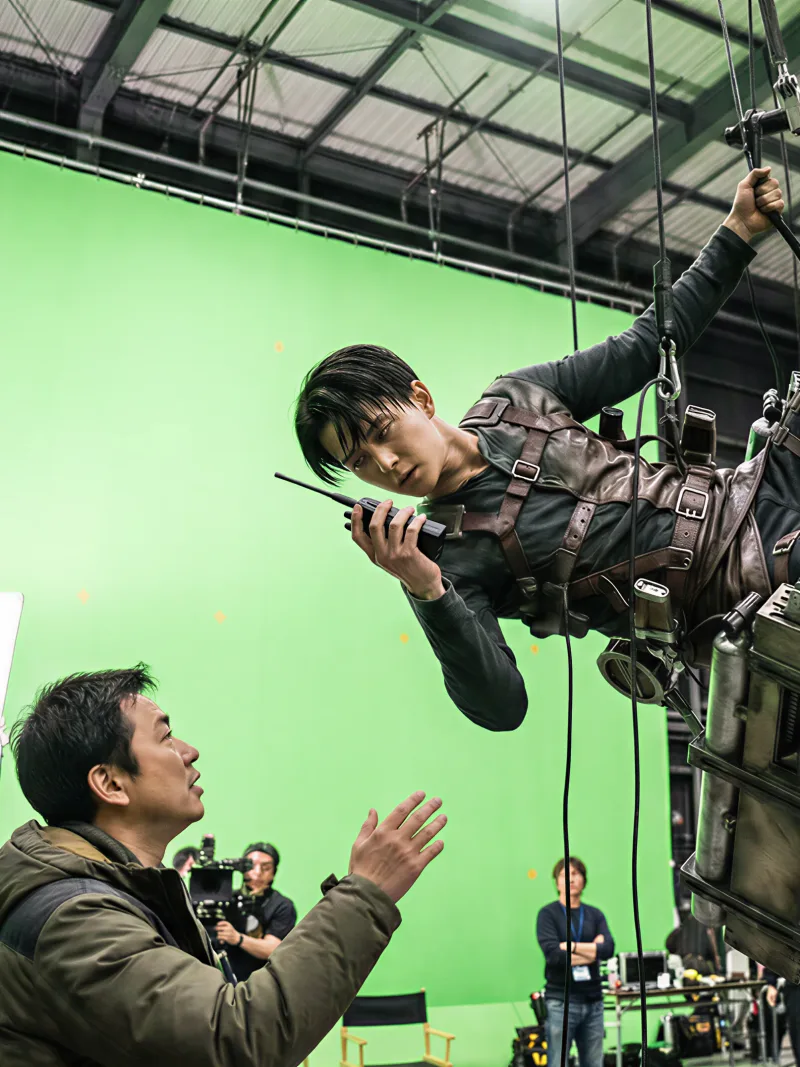
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
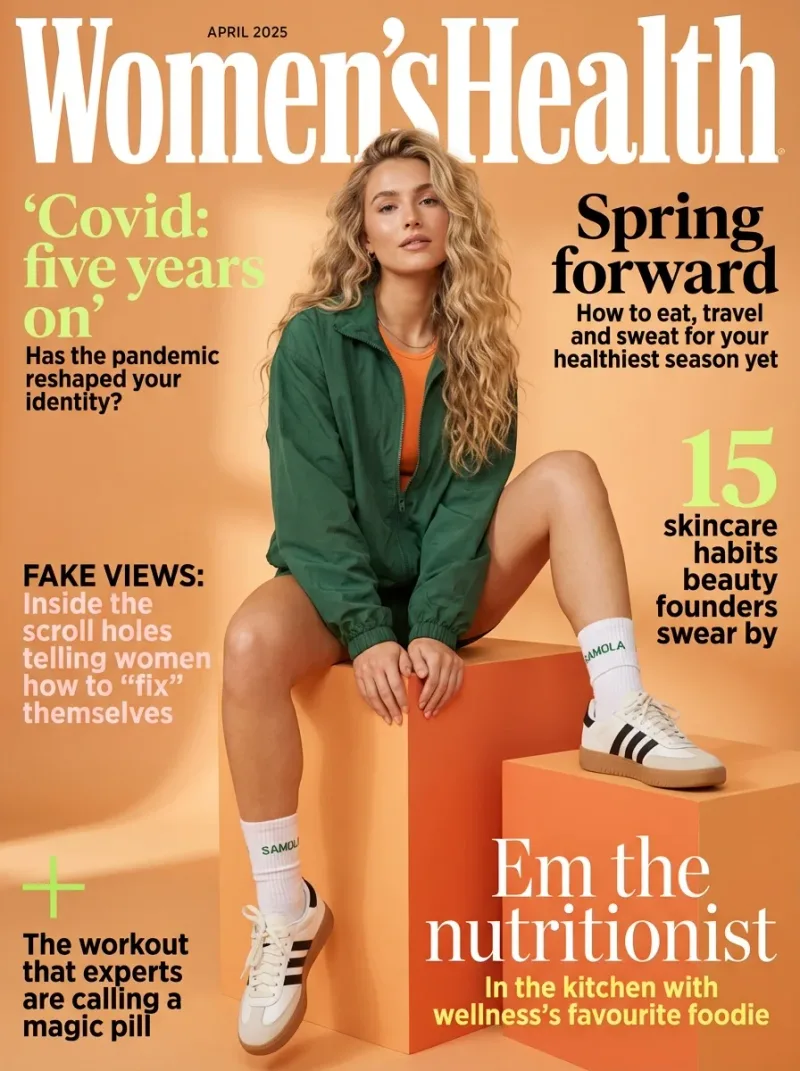
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Ví dụ
Xem WaveSpeedAI hoạt động
Kết quả thật do API WaveSpeedAI tạo ra. Rê chuột lên video để xem trước, nhấp để mở trình xem kích thước đầy đủ.
Hướng dẫn
Cách dùng API WaveSpeedAI
Bốn bước từ đăng ký đến khi có kết quả. Ví dụ đầy đủ bằng Python, Node.js và cURL nằm ở phần API bên dưới.
- 01
Lấy API key
Đăng ký tài khoản WaveSpeedAI và sao chép API key từ bảng điều khiển. Tài khoản mới được tặng credit dùng thử miễn phí — đủ để chạy playground vài chục lần trước khi bắt đầu tính phí.
- 02
Gửi một prediction
POST đầu vào của bạn dưới dạng JSON tới https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video. Endpoint trả về prediction id ngay lập tức — việc tạo là bất đồng bộ nên bạn không phải giữ kết nối mở trong lúc suy luận.
- 03
Poll để chờ hoàn tất
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result. Trả về kết quả khi completed; dừng và báo lỗi khi failed, cancelled, timeout hoặc deleted; tiếp tục poll với mọi trạng thái khác.
- 04
Đọc URL kết quả
Khi status là "completed", đọc URL từ data.outputs[0]. URL trỏ tới media bạn đã tạo trên CDN của WaveSpeedAI — ảnh, video, âm thanh hoặc tệp 3D tùy biến thể mô hình bạn đã gọi.
Trường hợp sử dụng
Bạn có thể xây dựng gì với các mô hình này
Các quy trình phổ biến mà nhà phát triển và người sáng tạo dùng các API này cho.
Chuyển tích hợp Higgsfield API chỉ trong một buổi chiều
Cả hai API đều bất đồng bộ: gửi JSON, nhận về request id, rồi polling hoặc nhận webhook. Trên WaveSpeedAI, bạn POST tới /api/v3/<model> với Bearer API key và đọc kết quả prediction, nên việc chuyển đổi chủ yếu là đổi base URL, header xác thực và đường dẫn mô hình.
Ảnh và video trong một pipeline
Tạo ảnh tĩnh bằng Nano Banana Pro, Seedream 5.0 hoặc GPT Image 2.5, rồi tạo chuyển động bằng Seedance 2.5, Kling 3.0 hoặc Wan 3.0 image-to-video, với một key và một số dư. Danh mục công bố của Higgsfield API không liệt kê Nano Banana, Seedream hay GPT Image.
MiniMax H3 mã nguồn mở trọng số với LoRA
WaveSpeedAI lưu trữ MiniMax H3 mã nguồn mở trọng số với text-to-video, image-to-video, reference-to-video, chỉnh sửa và kéo dài video, endpoint LoRA cho phong cách và nhân vật tùy chỉnh, cùng chế độ text-to-image.
Cảnh quay đơn dài và video theo phân khúc
Seedance 2.5 render cảnh quay đơn dài tới 30 giây với âm thanh gốc; Kling 3.0 và Kling O3 có các phân khúc Standard, Pro và 4K; Wan 3.0 có thêm phân khúc Prime. Chọn theo từng cảnh quay trong cùng một tích hợp.
Agent và tác vụ hàng loạt
Gọi mọi mô hình từ SDK Python hoặc JavaScript, HTTP thuần, CLI hoặc MCP server, để các coding agent và script hàng loạt dùng cùng endpoint và mức giá với ứng dụng của bạn.
Mẹo
Mẹo viết prompt cho các mô hình này
Lời khuyên thực tế để có kết quả tốt hơn từ các mô hình này — rút ra từ các mẫu hiệu quả trên các mô hình video trong các pipeline sản xuất.
- 01
Nêu cụ thể các động tác máy quay
Hãy dùng từ vựng quay phim cụ thể — orbit, dolly-in, push-in, pan-left, crane shot, handheld follow. Prompt chung chung cho ra góc máy tĩnh hoặc tùy tiện; các động tác máy quay có tên gọi ánh xạ trực tiếp tới ý đồ chuyển động trong dữ liệu huấn luyện của mô hình và cải thiện rõ rệt chất lượng cảnh quay.
- 02
Neo danh tính nhân vật bằng ảnh tham chiếu
Nếu prompt phụ thuộc vào một người, nhân vật hoặc sản phẩm cụ thể, hãy tải lên ảnh tham chiếu cùng prompt. Không có tham chiếu, danh tính sẽ trôi giữa các khung hình và các cảnh quay — cùng một nhân vật trông hơi khác đi sau mỗi lần tạo.
- 03
Mô tả ánh sáng và thời điểm trong ngày
Gợi ý ánh sáng như 'golden hour, soft warm directional light' hoặc 'overcast diffused light, slate-grey sky' cải thiện chất lượng và tính nhất quán hơn nhiều so với các từ bổ nghĩa chất lượng mơ hồ. Ánh sáng là một trong những tiên nghiệm mạnh nhất mà mô hình dựa vào.
- 04
Dùng negative prompt để hạn chế các lỗi thường gặp
Negative hữu ích cho video: 'frame flicker, motion blur, watermark, text artifacts, distorted hands, low resolution, jpeg compression'. Negative prompt không tốn gì và giảm đáng kể số lần bạn phải tạo lại.
- 05
Chọn thời lượng ngắn nhất đủ diễn đạt nhịp của bạn
Hầu hết prompt hiệu quả nhất ở 5-8 giây. Clip dài hơn khuếch đại sự thiếu nhất quán theo thời gian (chủ thể biến dạng, môi trường trôi). Nếu cần chuỗi 20 giây, hãy tạo ba clip 6-8 giây rồi ghép lại — chất lượng vẫn cao hơn một lần tạo dài.
- 06
Chọn tỷ lệ khung hình phù hợp nền tảng ngay từ đầu
9:16 cho TikTok / Reels / Shorts, 16:9 cho feed ngang và YouTube, 1:1 cho lưới bài đăng. Mô hình được huấn luyện hơi khác nhau theo từng tỷ lệ — cắt 16:9 thành 9:16 sau đó làm mất cả độ trung thực lẫn bố cục mà mô hình định tạo.
Giá
Giá API WaveSpeedAI
Giá tính theo từng kết quả đầu ra. Khoản phí cuối cùng thay đổi theo các tham số bạn đặt trong playground của từng biến thể (độ phân giải, thời lượng, số kết quả, tham chiếu).
API
Gọi API WaveSpeedAI
Đăng ký API key tại wavespeed.ai/accesskey, rồi gửi prediction qua REST. Playground tạo sẵn mã mẫu có thể dán ngay cho mọi tổ hợp đầu vào.
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)So sánh
WaveSpeedAI so với Higgsfield API
Những điểm khác nhau giữa WaveSpeedAI và Higgsfield API.
WaveSpeedAI so với Higgsfield API: models
Higgsfield API liệt kê 82 mục ảnh và video, gồm các mô hình Soul và Cinema Studio của riêng họ cùng Seedance, Kling, Wan, MiniMax và Qwen Image. WaveSpeedAI bao phủ các dòng mô hình bên thứ ba đó và bổ sung Nano Banana, Seedream, GPT Image, Veo, âm thanh, 3D và mô hình ngôn ngữ: tổng cộng hơn 1.000.
WaveSpeedAI so với Higgsfield API: credits
Số dư Higgsfield API hết hạn sau một năm kể từ khi mua. Credit WaveSpeedAI không bao giờ hết hạn và không có gói thành viên hay thuê bao: nạp tiền khi cần và trả theo từng yêu cầu, giá mỗi endpoint có trên trang mô hình và trong bảng giá ở trang này. Cùng số credit đó cũng dùng được cho các studio trên trình duyệt.
WaveSpeedAI so với Higgsfield API: open models
Cả hai đều có MiniMax H3. Trên WaveSpeedAI, đó là mô hình mã nguồn mở trọng số do WaveSpeedAI lưu trữ, với endpoint LoRA, reference-to-video, chỉnh sửa, kéo dài và ảnh bên cạnh text-to-video và image-to-video tiêu chuẩn.
Câu hỏi thường gặp
Higgsfield API Alternative — Câu hỏi thường gặp
Mô hình, giá, di chuyển — những câu hỏi phổ biến về việc chuyển từ Higgsfield API sang WaveSpeedAI.
WaveSpeedAI có phải là giải pháp thay thế Higgsfield API không?
Có. WaveSpeedAI cung cấp Seedance 2.5 và 2.0, Kling 3.0 và O3, Wan 3.0, MiniMax H3 và Qwen Image 3.0 dưới dạng endpoint REST, cùng Seedream 5.0, Nano Banana 2 và Pro, GPT Image 2.5 và 2, với một API key và giá trả theo từng yêu cầu.
Tôi có thể gọi những mô hình nào mà Higgsfield API không liệt kê?
Danh mục mô hình công bố của Higgsfield API không có Nano Banana, Seedream, GPT Image, Veo hay mô hình âm thanh. Trên WaveSpeedAI, Nano Banana 2 và Pro, Seedream 5.0, GPT Image 2.5 và 2, Veo 3.1 và giọng đọc ElevenLabs đều dùng chung một key với các mô hình video.
Làm thế nào để chuyển từ Higgsfield API sang?
Tạo key tại /accesskey, rồi POST dữ liệu đầu vào dạng JSON tới https://api.wavespeed.ai/api/v3/<model> kèm header Authorization: Bearer. Bạn sẽ nhận về một prediction id; hãy polling https://api.wavespeed.ai/api/v3/predictions/<id>/result hoặc truyền webhook. Ánh xạ từng mô hình sang đường dẫn WaveSpeedAI của nó theo danh sách endpoint trên trang này.
MiniMax H3 trên WaveSpeedAI có phải là mô hình mã nguồn mở trọng số không?
Có. Các endpoint wavespeed-ai/minimax-h3 chạy MiniMax H3 mã nguồn mở trọng số trên WaveSpeedAI, gồm các biến thể LoRA cho phong cách và nhân vật tùy chỉnh, reference-to-video, chỉnh sửa và kéo dài video, cùng chế độ text-to-image.
Tôi có cần gói thành viên hay thuê bao không, và credit có hết hạn không?
Không cần gói thành viên hay thuê bao. WaveSpeedAI tính phí theo mức dùng: nạp credit khi cần và trả theo từng yêu cầu với giá hiển thị trên trang mô hình và trong bảng giá phía trên. Credit không bao giờ hết hạn. Tài khoản mới đủ điều kiện sẽ nhận credit khởi đầu miễn phí.
Làm sao để gọi các API này?
Đăng ký tài khoản WaveSpeedAI, sao chép API key từ /accesskey, rồi POST đầu vào dưới dạng JSON tới https://api.wavespeed.ai/api/v3/<model>, ví dụ https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video. Endpoint trả về prediction id. Hãy poll endpoint kết quả hoặc truyền webhook. Ví dụ Python / Node.js / cURL ở phía trên.
Các API này có giá bao nhiêu?
Các endpoint trên trang này bắt đầu từ $0.02 mỗi lượt chạy; giá của từng mô hình có trong bảng giá phía trên và trên trang mô hình của nó. Chi phí chính xác thay đổi theo các tham số bạn đặt (độ phân giải, thời lượng, số kết quả, tham chiếu), và playground hiển thị trước khi bạn gửi.
Bắt đầu xây dựng trên WaveSpeedAI
Tặng credit dùng thử miễn phí khi đăng ký. Một API key cho hơn 1.000 mô hình AI từ mọi nhà cung cấp lớn.