Higgsfield API Alternative
Geliştiricilerin Higgsfield API'de aradığı modeller — Seedance 2.5 ve 2.0, Kling 3.0 ve O3, Wan 3.0, açık ağırlıklı MiniMax H3 ve Qwen Image 3.0 — ayrıca Seedream 5.0, Nano Banana 2 ve Pro ile GPT Image 2.5 ve 2, tek bir WaveSpeedAI API anahtarıyla. Kullandıkça öde: kredilerin süresi dolmaz, üyelik veya abonelik yoktur.
Higgsfield API'yi mi değerlendiriyorsunuz? Aşağıdaki her uç nokta bugün WaveSpeedAI'da yayında; playground, örnekler ve güncel çalıştırma başı fiyatıyla birlikte. Bir kez bakiye yükleyin ve kredilerinizi istediğiniz zaman — süreleri dolmaz — bu modellerde ve 1.000'den fazla diğer görsel, video, ses, 3D ve dil modelinde kullanın.
Genel Bakış
Higgsfield API Alternative Hakkında
Higgsfield API modellerini değerlendiriyorsanız WaveSpeedAI'da neleri çağırabileceğiniz.
Geliştiricilerin Higgsfield API'de aradığı modeller — Seedance 2.5 ve 2.0, Kling 3.0 ve O3, Wan 3.0, açık ağırlıklı MiniMax H3 ve Qwen Image 3.0 — ayrıca Seedream 5.0, Nano Banana 2 ve Pro ile GPT Image 2.5 ve 2, tek bir WaveSpeedAI API anahtarıyla. Kullandıkça öde: kredilerin süresi dolmaz, üyelik veya abonelik yoktur.
Higgsfield API'yi mi değerlendiriyorsunuz? Aşağıdaki her uç nokta bugün WaveSpeedAI'da yayında; playground, örnekler ve güncel çalıştırma başı fiyatıyla birlikte. Bir kez bakiye yükleyin ve kredilerinizi istediğiniz zaman — süreleri dolmaz — bu modellerde ve 1.000'den fazla diğer görsel, video, ses, 3D ve dil modelinde kullanın.
Aşağıdaki uç noktalar bu modeller için 37 canlı WaveSpeedAI REST uç noktasıdır, Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image iş akışlarını kapsar. Her birinin kendi playground'u, fiyatı ve örnekleri vardır ve hepsi aynı şekilde çağrılır: JSON'u POST edin, bir tahmin kimliği alın, sonucu yoklayın veya webhook ile alın.
Hepsi, WaveSpeedAI'daki diğer 1.000+ modelle — metinden görsele ve metinden videoya, sese, 3D'ye, büyütmeye, düzenlemeye ve dil modellerine kadar — tek bir API anahtarını, tek bir bakiyeyi ve tek bir entegrasyonu paylaşır.
Uç Noktalar
Tüm WaveSpeedAI API uç noktaları
WaveSpeedAI'da şu anda 37 uç nokta kullanılabilir — iş akışınıza uyan varyantı seçin.
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
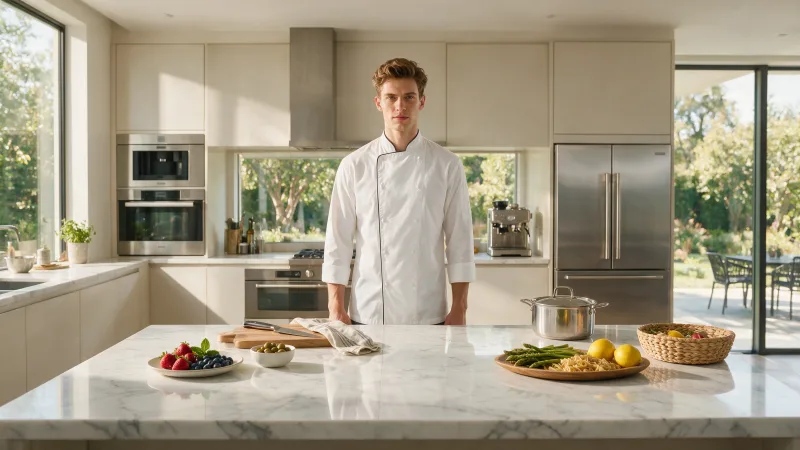
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
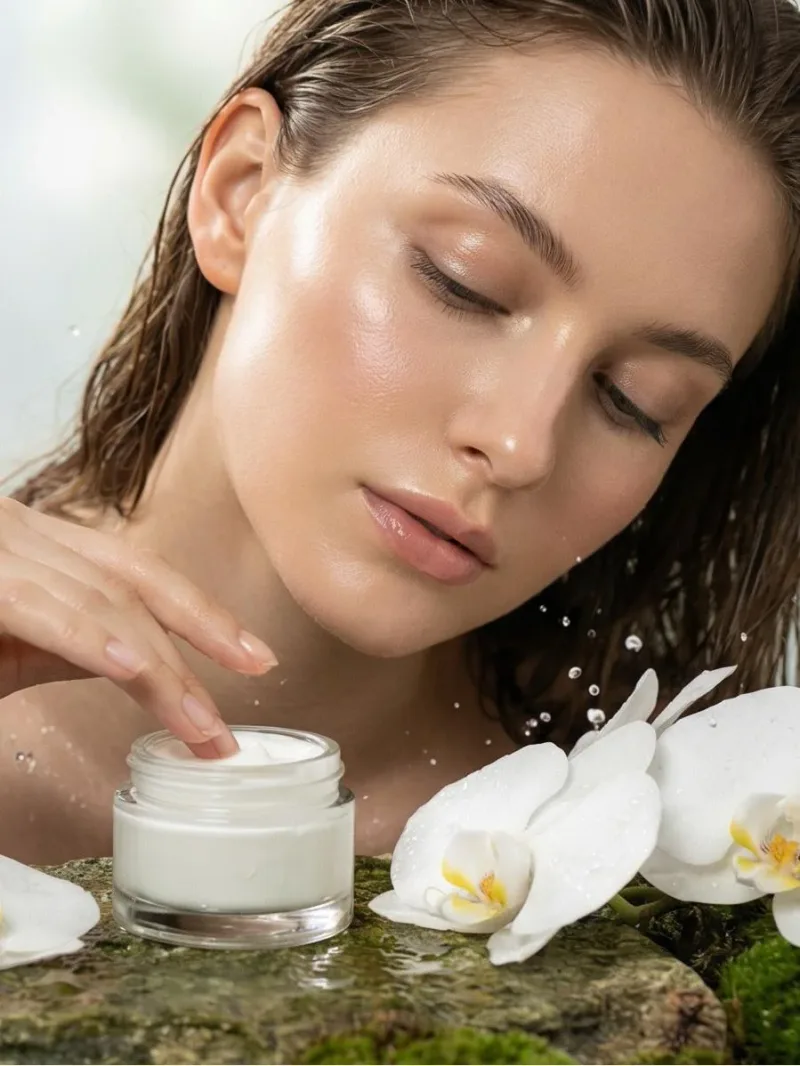
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
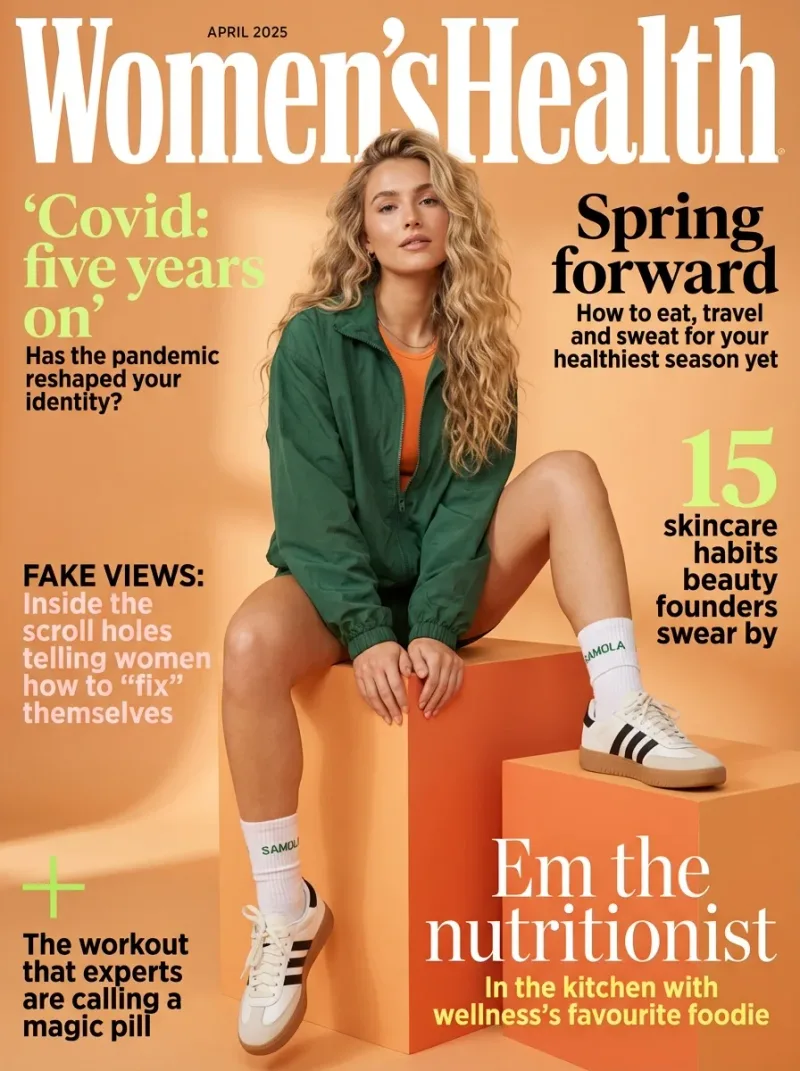
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
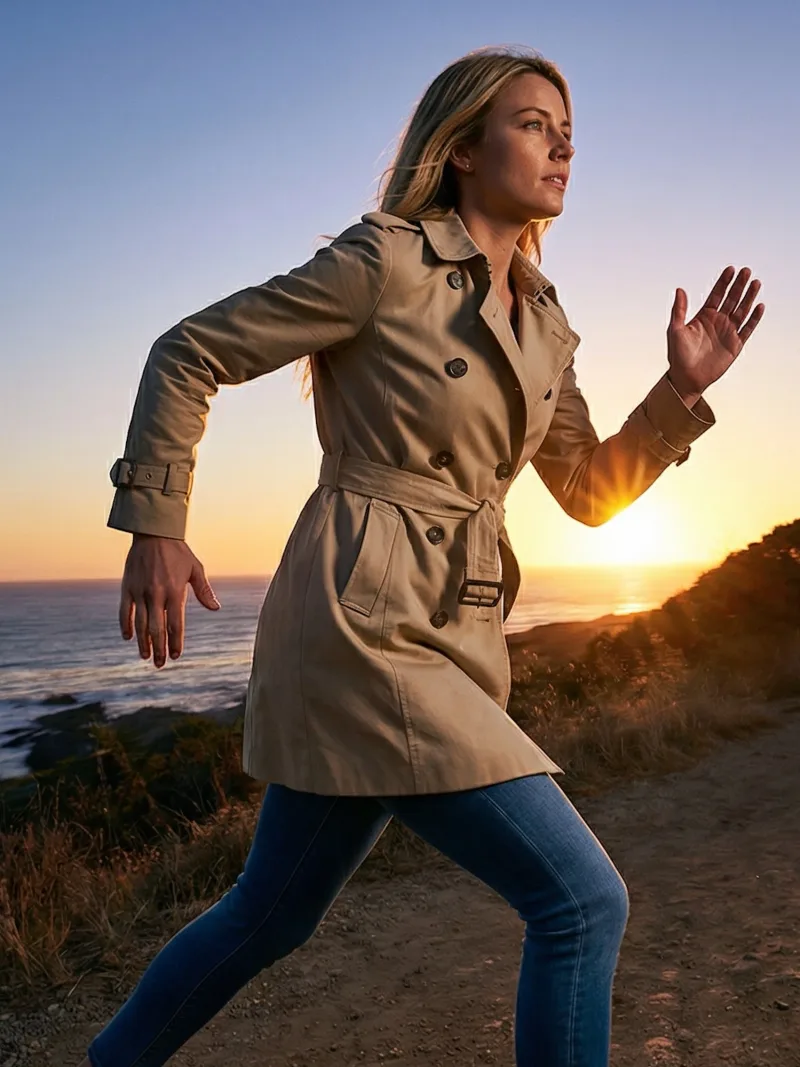
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
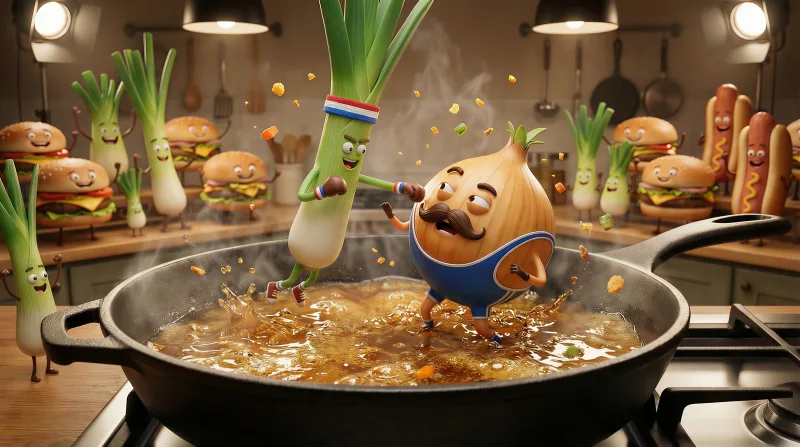
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
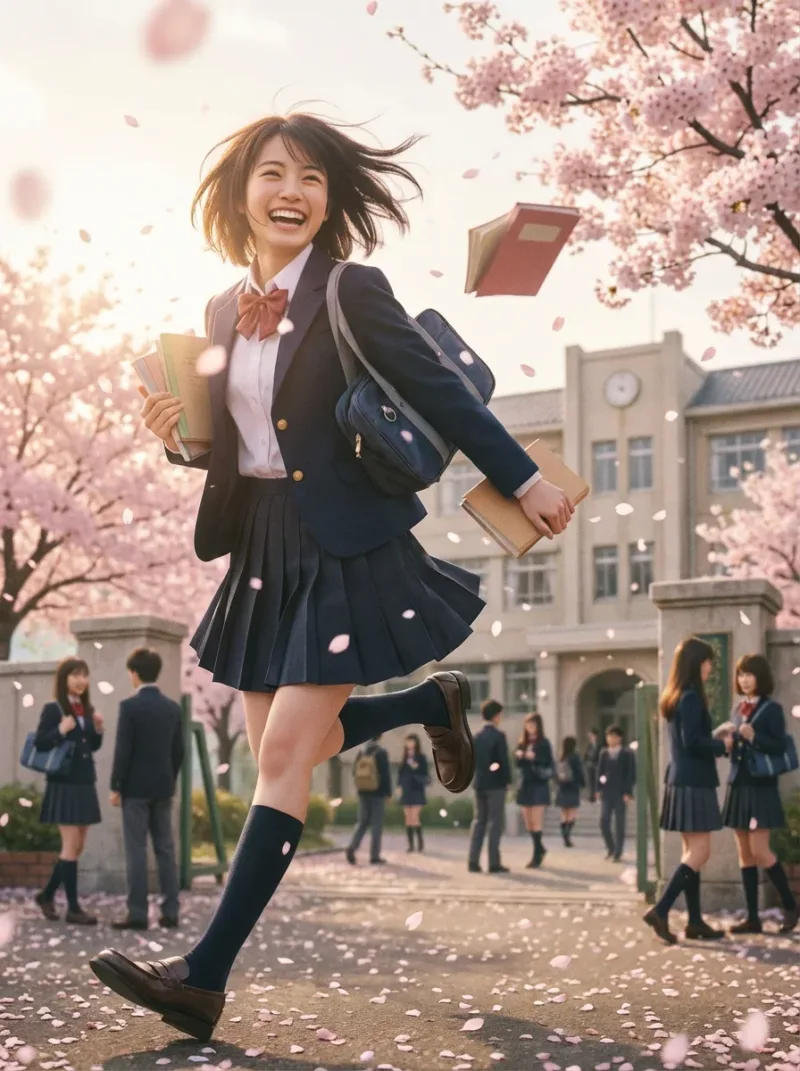
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
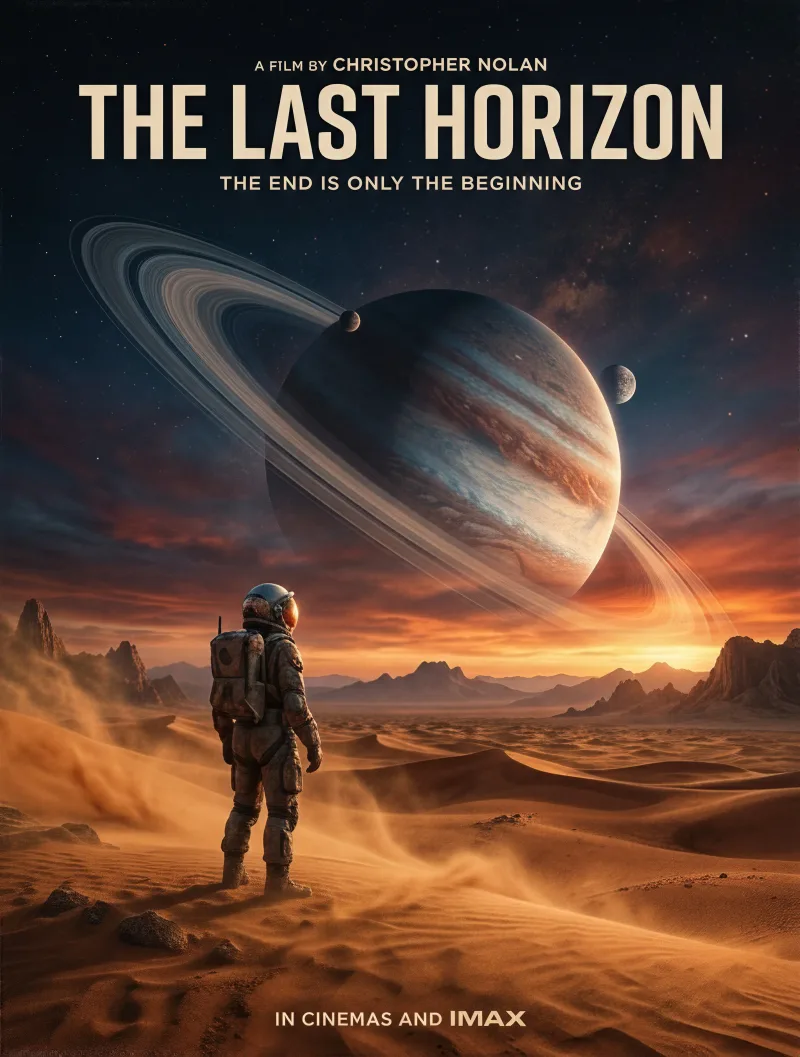
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
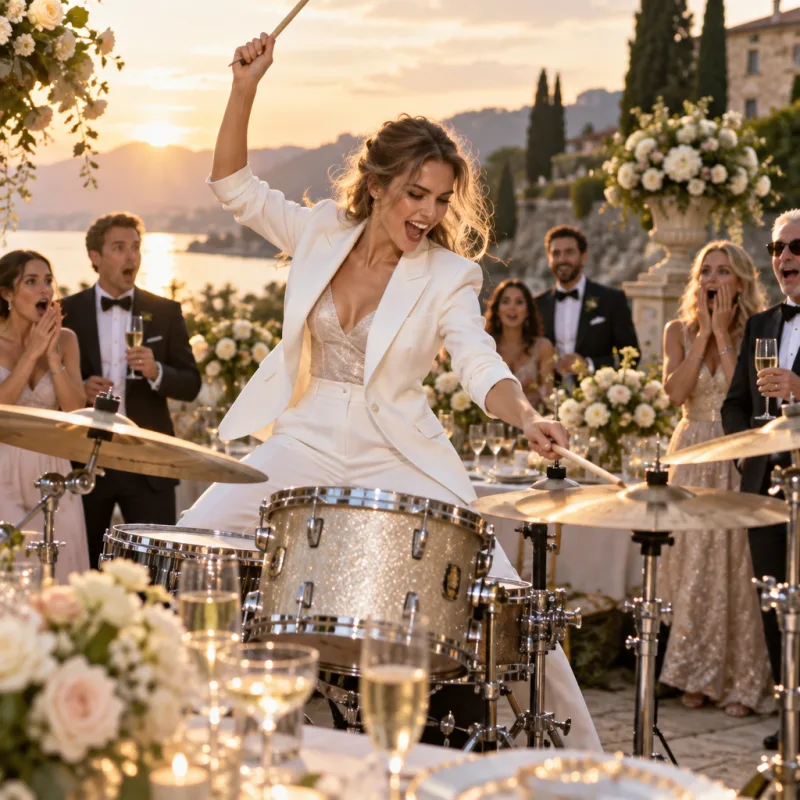
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
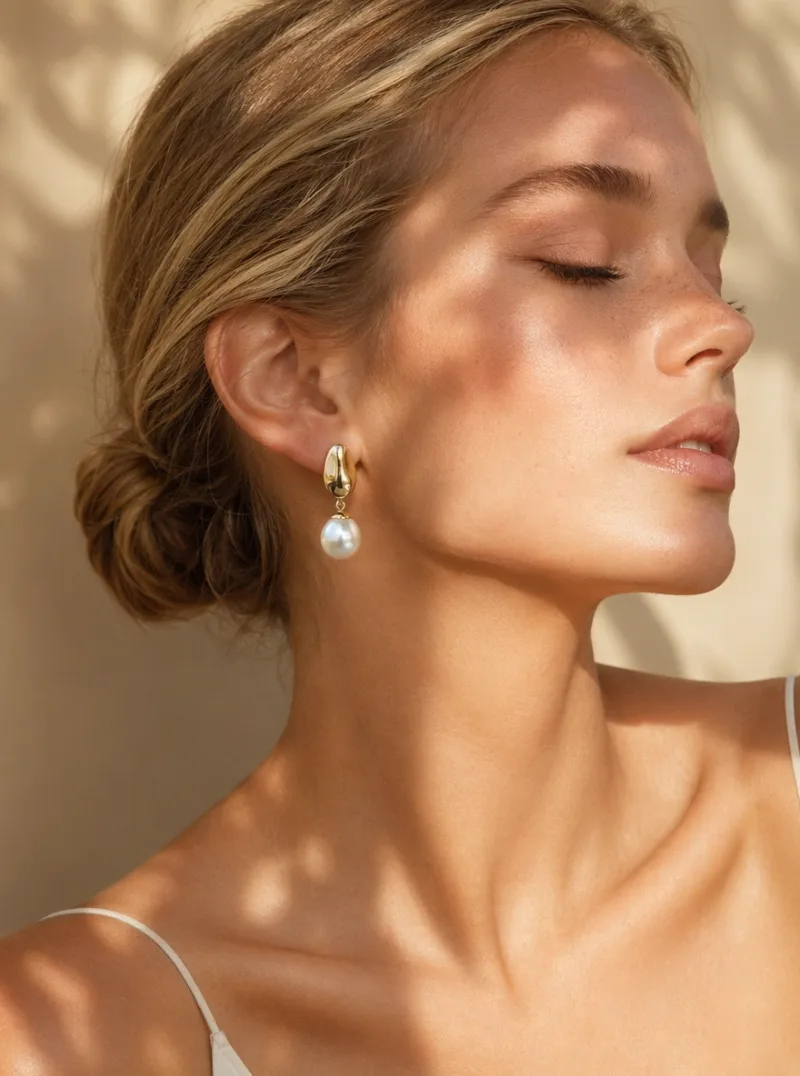
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
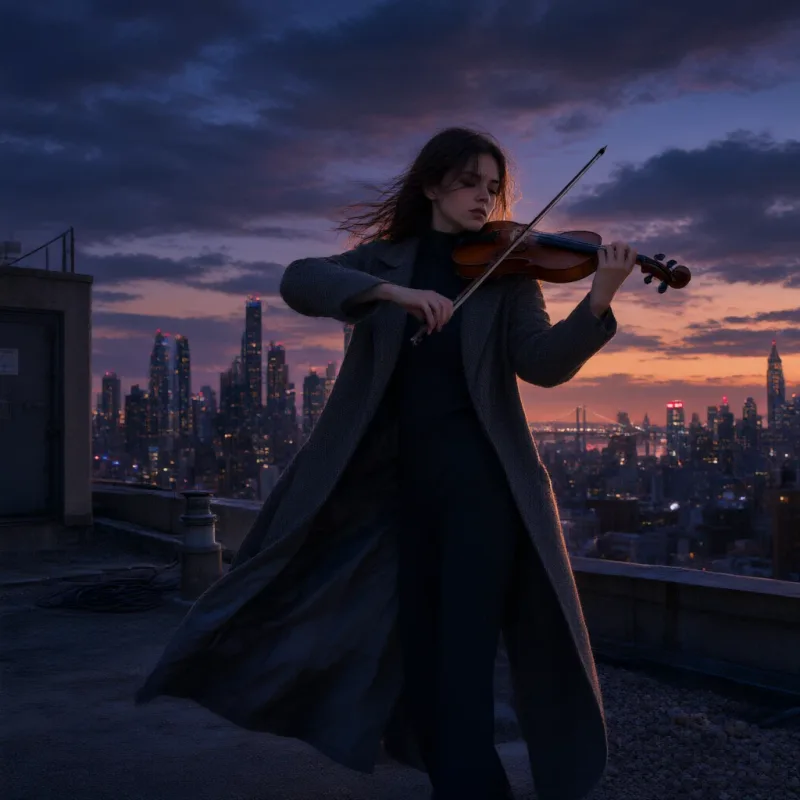
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Örnekler
WaveSpeedAI iş başında
WaveSpeedAI API'siyle üretilmiş gerçek çıktılar. Önizlemek için bir videonun üzerine gelin, tam boyutlu görüntüleyiciyi açmak için tıklayın.
Nasıl Kullanılır
WaveSpeedAI API'si nasıl kullanılır
Kayıttan tamamlanmış bir üretime dört adım. Python, Node.js ve cURL örneklerinin tamamı aşağıdaki API bölümünde.
- 01
API anahtarı alın
Bir WaveSpeedAI hesabı oluşturun ve API anahtarınızı kontrol panelinden kopyalayın. Yeni hesaplar ücretsiz başlangıç kredisiyle gelir — faturalandırma başlamadan önce playground'u birkaç düzine kez çalıştırmaya yeter.
- 02
Tahmin gönderin
Girdinizi JSON olarak https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video adresine POST edin. Uç nokta hemen bir tahmin kimliği döndürür — üretimler asenkrondur, bu yüzden çıkarım sırasında açık bir bağlantı tutmanız gerekmez.
- 03
Tamamlanmayı yoklayın
https://api.wavespeed.ai/api/v3/predictions/{request_id}/result adresine GET isteği gönderin. completed durumunda çıktıları alın; failed, cancelled, timeout veya deleted durumunda hata ile durun; diğer tüm durumlarda yoklamaya devam edin.
- 04
Çıktı URL'sini okuyun
Durum "completed" olduğunda URL'yi data.outputs[0] alanından okuyun. URL, WaveSpeedAI CDN'indeki üretilmiş medyanıza işaret eder — çağırdığınız model varyantına göre görsel, video, ses veya 3D dosyası.
Kullanım Alanları
Bu modellerle neler geliştirebilirsiniz
Geliştiricilerin ve içerik üreticilerin bu API'leri kullandığı yaygın iş akışları.
Higgsfield API entegrasyonunu bir öğleden sonrada taşıyın
Her iki API de asenkrondur: JSON gönderin, bir istek kimliği alın, ardından yoklayın veya bir webhook alın. WaveSpeedAI'da bir Bearer API anahtarıyla /api/v3/<model> adresine POST eder ve tahmin sonucunu okursunuz; yani taşıma çoğunlukla temel URL, kimlik doğrulama başlığı ve model yolunun değişmesinden ibarettir.
Tek iş hattında görsel ve video
Nano Banana Pro, Seedream 5.0 veya GPT Image 2.5 ile sabit görseller üretin, ardından Seedance 2.5, Kling 3.0 veya Wan 3.0 görselden videoya ile canlandırın; tek anahtar ve tek bakiyeyle. Higgsfield API'nin yayımlanmış kataloğu Nano Banana, Seedream veya GPT Image'ı listelemez.
LoRA'lı açık ağırlıklı MiniMax H3
WaveSpeedAI, açık ağırlıklı MiniMax H3'ü metinden videoya, görselden videoya, referanstan videoya, video düzenleme ve uzatma, özel stiller ile karakterler için LoRA uç noktaları ve bir metinden görsele moduyla barındırır.
Uzun tek çekimler ve kademeli video
Seedance 2.5, yerel sesle 30 saniyeye kadar tek çekimler işler; Kling 3.0 ve Kling O3 Standard, Pro ve 4K katmanlarıyla gelir; Wan 3.0 bir Prime katmanı ekler. Aynı entegrasyondan çekim başına seçin.
Ajanlar ve toplu işler
Her modeli Python veya JavaScript SDK'ları, düz HTTP, CLI veya bir MCP sunucusu üzerinden çağırın; böylece kodlama ajanları ve toplu betikler uygulamanızla aynı uç noktaları ve fiyatları kullanır.
İpuçları
Bu modeller için istem yazma ipuçları
Bu modellerle daha iyi çıktı almak için pratik öneriler — üretim hatlarında video modelleri genelinde işe yarayan yöntemlerden derlendi.
- 01
Kamera hareketleri konusunda net olun
Somut sinematografi sözcüklerini kullanın — orbit, dolly-in, push-in, pan-left, crane shot, handheld follow. Genel istemler statik veya rastgele kamera seçimleri üretir; adlandırılmış kamera hareketleri modelin eğitim verisinde hareket niyetiyle doğrudan eşleşir ve çekim kalitesini önemli ölçüde artırır.
- 02
Karakter kimliğini referans görsellerle sabitleyin
İsteminiz belirli bir kişiye, karaktere veya ürüne bağlıysa, istemin yanına bir referans görsel yükleyin. Referans olmadan kimlik, kareler ve çekimler arasında kayar — aynı karakter her üretimde biraz farklı bir kişiye benzer.
- 03
Işığı ve günün saatini tarif edin
'Altın saat, yumuşak sıcak yönlü ışık' veya 'bulutlu dağınık ışık, arduvaz grisi gökyüzü' gibi ışık ipuçları, belirsiz kalite niteleyicilerinden çok daha fazla kalite ve tutarlılık sağlar. Işık, modelin koşullandığı en güçlü önsel bilgilerden biridir.
- 04
Yaygın hata kiplerini bastırmak için negatif istemleri kullanın
Video için yararlı negatifler: 'kare titremesi, hareket bulanıklığı, filigran, metin artefaktları, bozuk eller, düşük çözünürlük, jpeg sıkıştırma'. Negatif istemler hiçbir şeye mal olmaz ve aksi halde yeniden çevireceğiniz üretimlerin oranını gözle görülür ölçüde azaltır.
- 05
Vuruşunuzu yakalayan en kısa süreyi seçin
Çoğu istem 5-8 saniyede en iyi çalışır. Daha uzun klipler zamansal tutarsızlıkları (öznenin biçim değiştirmesi, ortam kayması) büyütür. 20 saniyelik bir diziye ihtiyacınız varsa, üç adet 6-8 saniyelik klip üretip birlikte kurgulayın — kalite tek bir uzun üretimden yüksek kalır.
- 06
En-boy oranını baştan platforma uydurun
TikTok / Reels / Shorts için 9:16, yatay akışlar ve YouTube için 16:9, gönderi ızgaraları için 1:1. Modeller en-boy oranına göre biraz farklı eğitilir — 16:9'u sonradan 9:16'ya kırpmak hem doğruluğu hem de modelin amaçladığı kompozisyonu kaybettirir.
Fiyatlandırma
WaveSpeedAI API fiyatlandırması
Fiyatlandırma çıktı başınadır. Nihai ücret, her varyantın playground'unda belirlediğiniz parametrelere (çözünürlük, süre, çıktı sayısı, referanslar) göre değişir.
API
WaveSpeedAI API'sini çağırın
wavespeed.ai/accesskey adresinden bir API anahtarı alın, ardından REST ile bir tahmin gönderin. Playground, girdilerin her kombinasyonu için yapıştırmaya hazır örnekler üretir.
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)Karşılaştır
WaveSpeedAI ve Higgsfield API
WaveSpeedAI ile Higgsfield API arasındaki farklar.
WaveSpeedAI ve Higgsfield API: models
Higgsfield API, kendi Soul ve Cinema Studio modelleri ile Seedance, Kling, Wan, MiniMax ve Qwen Image dahil 82 görsel ve video girdisi listeler. WaveSpeedAI bu üçüncü taraf ailelerini kapsar ve Nano Banana, Seedream, GPT Image, Veo, ses, 3D ve dil modellerini ekler: toplamda 1.000'den fazla.
WaveSpeedAI ve Higgsfield API: credits
Higgsfield API bakiyesi satın almadan bir yıl sonra sona erer. WaveSpeedAI kredilerinin süresi dolmaz; üyelik veya abonelik yoktur: ihtiyaç duyduğunuzda bakiye yükleyin ve istek başına ödeyin; her uç noktanın fiyatı model sayfasında ve bu sayfadaki fiyat tablosunda yer alır. Aynı krediler tarayıcı stüdyolarının ücretini de karşılar.
WaveSpeedAI ve Higgsfield API: open models
İkisi de MiniMax H3'ü listeler. WaveSpeedAI'da bu, WaveSpeedAI tarafından barındırılan açık ağırlıklı modeldir; standart metinden videoya ve görselden videoya yanında LoRA, referanstan video, düzenleme, uzatma ve görsel uç noktaları da bulunur.
SSS
Higgsfield API Alternative — Sıkça sorulan sorular
Modeller, fiyatlandırma, geçiş — Higgsfield API yerine WaveSpeedAI'ya geçmeye dair sık sorulan sorular.
WaveSpeedAI, Higgsfield API'ye bir alternatif mi?
Evet. WaveSpeedAI; Seedance 2.5 ve 2.0, Kling 3.0 ve O3, Wan 3.0, MiniMax H3 ve Qwen Image 3.0'ı REST uç noktaları olarak, ayrıca Seedream 5.0, Nano Banana 2 ve Pro ile GPT Image 2.5 ve 2'yi tek bir API anahtarı ve istek başına ödeme fiyatlandırmasıyla sunar.
Higgsfield API'nin listelemediği hangi modelleri çağırabilirim?
Higgsfield API'nin yayımlanmış model kataloğu Nano Banana, Seedream, GPT Image, Veo veya ses modellerini içermez. WaveSpeedAI'da Nano Banana 2 ve Pro, Seedream 5.0, GPT Image 2.5 ve 2, Veo 3.1 ve ElevenLabs sesleri, video modelleriyle aynı anahtarın arkasındadır.
Higgsfield API'den nasıl geçiş yaparım?
/accesskey sayfasında bir anahtar oluşturun, ardından girdinizi JSON olarak Authorization: Bearer başlığıyla https://api.wavespeed.ai/api/v3/<model> adresine POST edin. Bir tahmin kimliği alırsınız; https://api.wavespeed.ai/api/v3/predictions/<id>/result adresini yoklayın veya bir webhook verin. Her modeli, bu sayfadaki uç nokta listesinden WaveSpeedAI yoluyla eşleştirin.
WaveSpeedAI'daki MiniMax H3 açık ağırlıklı model mi?
Evet. wavespeed-ai/minimax-h3 uç noktaları, açık ağırlıklı MiniMax H3'ü WaveSpeedAI üzerinde çalıştırır; özel stiller ve karakterler için LoRA varyantları, referanstan video, video düzenleme ve uzatma ile bir metinden görsele modu dahildir.
Üyelik veya aboneliğe ihtiyacım var mı ve kredilerin süresi doluyor mu?
Üyelik yok, abonelik yok. WaveSpeedAI kullandıkça öde esasına dayanır: ihtiyaç duyduğunuzda kredi yükleyin ve her model sayfasında ve yukarıdaki fiyat tablosunda gösterilen fiyattan istek başına ödeyin. Kredilerin süresi dolmaz. Uygun yeni hesaplar ücretsiz başlangıç kredisi alır.
Bu API'leri nasıl çağırırım?
Bir WaveSpeedAI hesabı oluşturun, API anahtarınızı /accesskey sayfasından kopyalayın, ardından girdinizi JSON olarak https://api.wavespeed.ai/api/v3/<model> adresine POST edin; örneğin https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video. Uç nokta bir tahmin kimliği döndürür. Sonuç uç noktasını yoklayın veya bir webhook verin. Python / Node.js / cURL örnekleri yukarıda.
Bu API'lerin maliyeti nedir?
Bu sayfadaki uç noktalar çalıştırma başına $0.02'dan başlar; her modelin fiyatı yukarıdaki fiyat tablosunda ve kendi model sayfasında yer alır. Kesin maliyet, belirlediğiniz parametrelere (çözünürlük, süre, çıktı sayısı, referanslar) göre değişir ve playground göndermeden önce bunu gösterir.
WaveSpeedAI'da geliştirmeye başlayın
Kayıt olunca ücretsiz başlangıç kredisi. Tüm büyük sağlayıcılardan 1.000+ AI modeli için tek API anahtarı.