Higgsfield API Alternative
โมเดลที่นักพัฒนามองหาใน Higgsfield API — Seedance 2.5 และ 2.0, Kling 3.0 และ O3, Wan 3.0, MiniMax H3 แบบ open-weights และ Qwen Image 3.0 — รวมถึง Seedream 5.0, Nano Banana 2 และ Pro, และ GPT Image 2.5 และ 2 ภายใต้ WaveSpeedAI API key เดียว จ่ายตามการใช้งาน: เครดิตไม่มีวันหมดอายุ และไม่มีสมาชิกหรือการสมัครรายเดือน
กำลังประเมิน Higgsfield API อยู่ใช่ไหม ทุก endpoint ด้านล่างเปิดใช้งานบน WaveSpeedAI แล้ววันนี้ พร้อม playground ตัวอย่าง และราคาต่อการรันปัจจุบัน เติมเงินครั้งเดียวแล้วใช้เครดิตเมื่อไหร่ก็ได้ — เครดิตไม่มีวันหมดอายุ — กับโมเดลเหล่านี้และโมเดลภาพ วิดีโอ เสียง 3D และภาษาอื่นๆ อีกกว่า 1,000 รายการ
ภาพรวม
เกี่ยวกับ Higgsfield API Alternative
สิ่งที่คุณเรียกใช้ได้บน WaveSpeedAI หากกำลังประเมินHiggsfield API
โมเดลที่นักพัฒนามองหาใน Higgsfield API — Seedance 2.5 และ 2.0, Kling 3.0 และ O3, Wan 3.0, MiniMax H3 แบบ open-weights และ Qwen Image 3.0 — รวมถึง Seedream 5.0, Nano Banana 2 และ Pro, และ GPT Image 2.5 และ 2 ภายใต้ WaveSpeedAI API key เดียว จ่ายตามการใช้งาน: เครดิตไม่มีวันหมดอายุ และไม่มีสมาชิกหรือการสมัครรายเดือน
กำลังประเมิน Higgsfield API อยู่ใช่ไหม ทุก endpoint ด้านล่างเปิดใช้งานบน WaveSpeedAI แล้ววันนี้ พร้อม playground ตัวอย่าง และราคาต่อการรันปัจจุบัน เติมเงินครั้งเดียวแล้วใช้เครดิตเมื่อไหร่ก็ได้ — เครดิตไม่มีวันหมดอายุ — กับโมเดลเหล่านี้และโมเดลภาพ วิดีโอ เสียง 3D และภาษาอื่นๆ อีกกว่า 1,000 รายการ
endpoint ด้านล่างคือ REST endpoint ของ WaveSpeedAI ที่ใช้งานได้จริง 37 รายการสำหรับโมเดลเหล่านี้, ครอบคลุมเวิร์กโฟลว์ Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image แต่ละรายการมี playground ราคา และตัวอย่างของตัวเอง และเรียกใช้ด้วยวิธีเดียวกันทั้งหมด: POST JSON รับ prediction id กลับมา แล้ว poll หรือรับ webhook
ใช้ API key เดียว ยอดคงเหลือเดียว และการเชื่อมต่อเดียวร่วมกับโมเดลอื่นกว่า 1,000 รายการบน WaveSpeedAI ตั้งแต่ข้อความเป็นภาพและข้อความเป็นวิดีโอ ไปจนถึงเสียง 3D การอัปสเกล การแก้ไข และโมเดลภาษา
Endpoint
API endpoint ของ WaveSpeedAI ทั้งหมด
37 endpoint พร้อมใช้งานบน WaveSpeedAI แล้ว — เลือกแบบที่ตรงกับเวิร์กโฟลว์ของคุณ
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
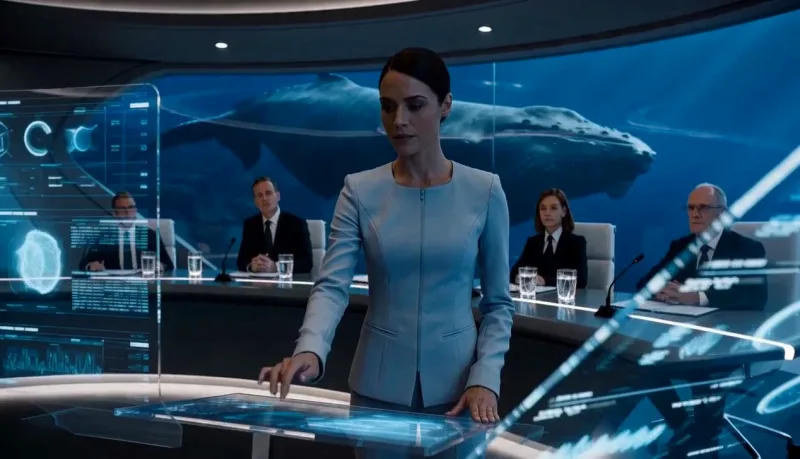
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
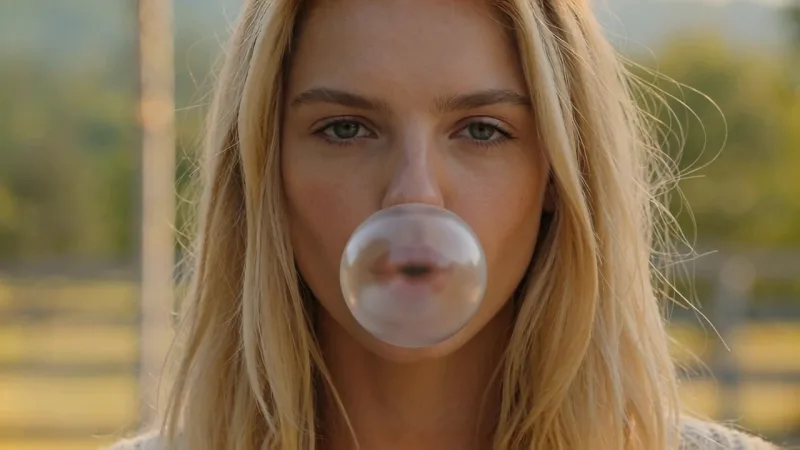
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
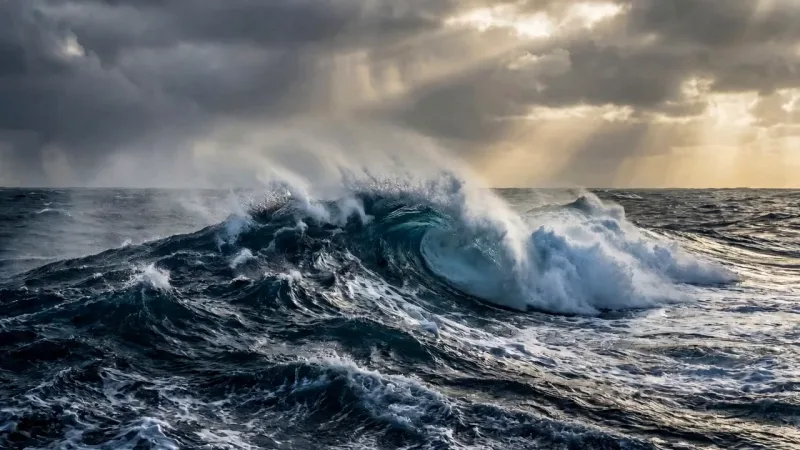
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
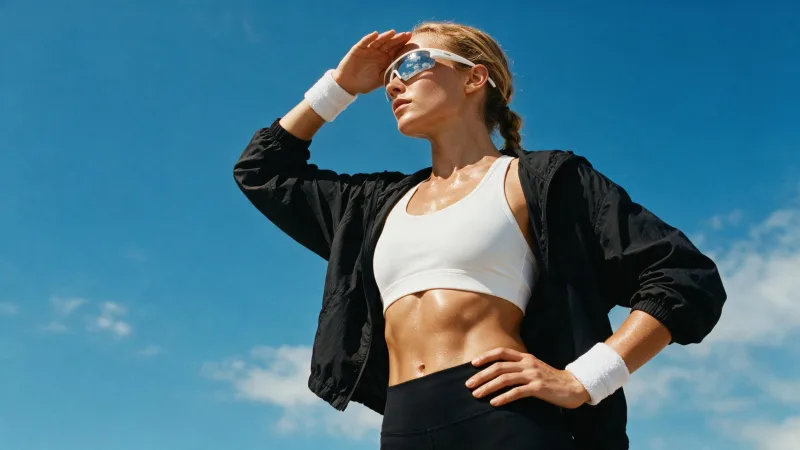
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
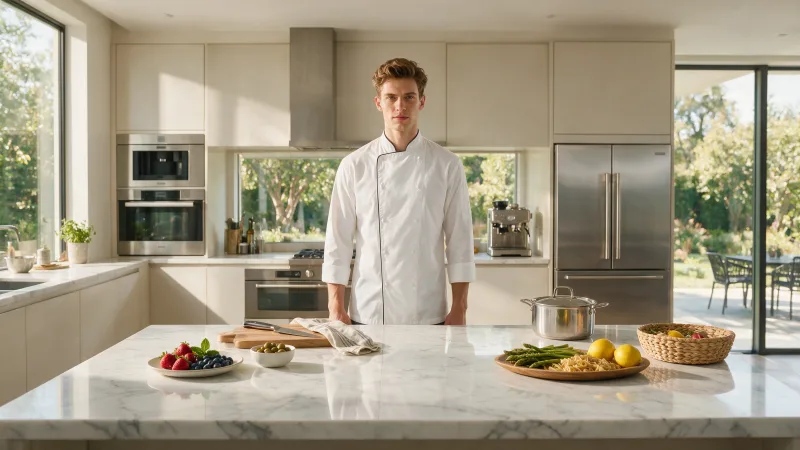
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
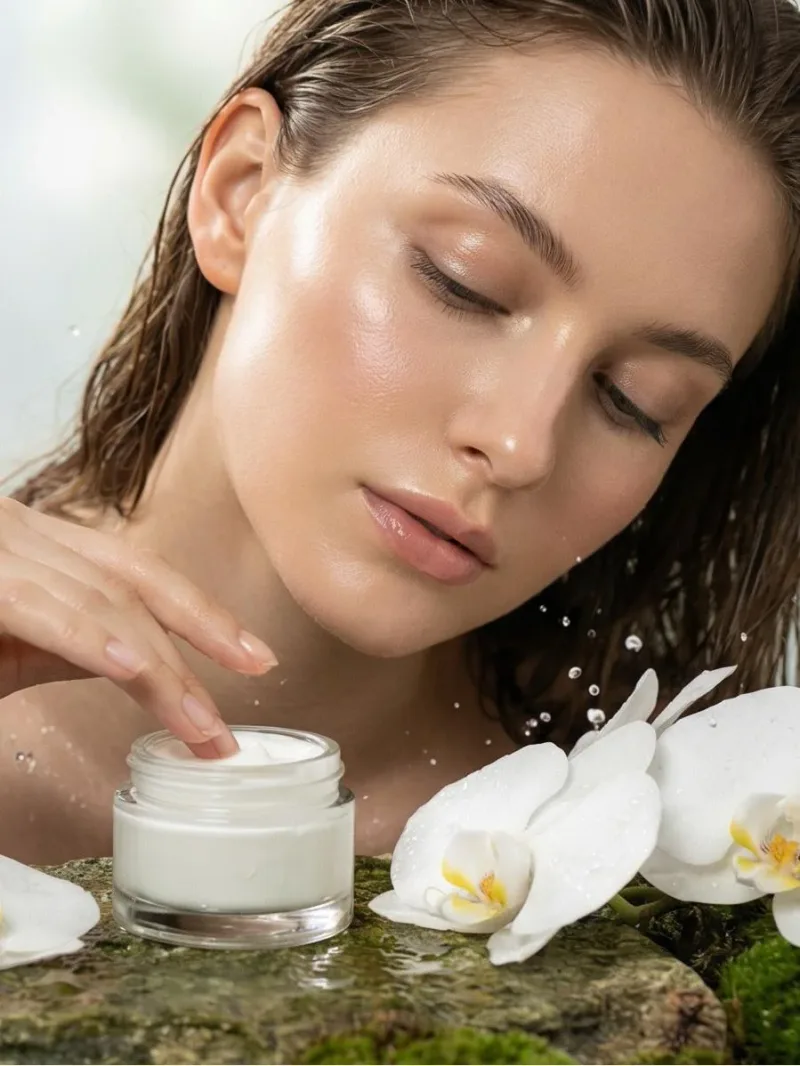
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
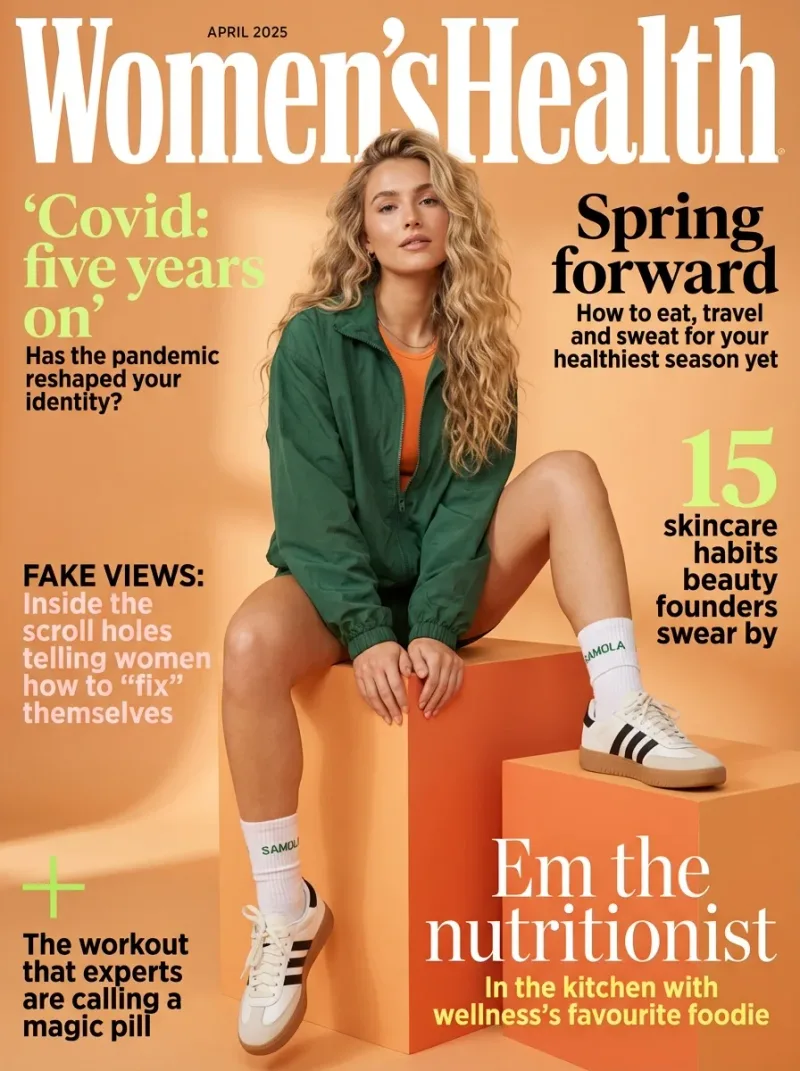
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
ตัวอย่าง
ดู WaveSpeedAI ทำงานจริง
ผลลัพธ์จริงที่สร้างโดย WaveSpeedAI API วางเมาส์บนวิดีโอเพื่อดูตัวอย่าง คลิกเพื่อเปิดตัวดูขนาดเต็ม
วิธีใช้
วิธีใช้ WaveSpeedAI API
สี่ขั้นตอนจากการสมัครไปจนถึงผลลัพธ์ที่เสร็จสมบูรณ์ ตัวอย่าง Python, Node.js และ cURL แบบเต็มอยู่ในส่วน API ด้านล่าง
- 01
รับ API key
สมัครบัญชี WaveSpeedAI แล้วคัดลอก API key จากแดชบอร์ด บัญชีใหม่มาพร้อมเครดิตเริ่มต้นฟรี เพียงพอให้ลองใช้ playground ได้หลายสิบครั้งก่อนเริ่มเรียกเก็บเงิน
- 02
ส่ง prediction
POST อินพุตของคุณเป็น JSON ไปที่ https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video endpoint จะส่ง prediction id กลับมาทันที การสร้างทำงานแบบอะซิงโครนัส คุณจึงไม่ต้องเปิดการเชื่อมต่อค้างไว้ระหว่างประมวลผล
- 03
poll เพื่อรอให้เสร็จ
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result เมื่อสถานะเป็น completed ให้นำผลลัพธ์ไปใช้ เมื่อเป็น failed, cancelled, timeout หรือ deleted ให้หยุดพร้อมแจ้งข้อผิดพลาด และ poll ต่อไปสำหรับสถานะอื่นทั้งหมด
- 04
อ่าน URL ของผลลัพธ์
เมื่อสถานะเป็น "completed" ให้อ่าน URL จาก data.outputs[0] URL ชี้ไปยังสื่อที่สร้างขึ้นของคุณบน CDN ของ WaveSpeedAI ซึ่งเป็นภาพ วิดีโอ เสียง หรือไฟล์ 3D ตามแบบของโมเดลที่คุณเรียกใช้
กรณีการใช้งาน
สิ่งที่คุณสร้างได้ด้วยโมเดลเหล่านี้
เวิร์กโฟลว์ทั่วไปที่นักพัฒนาและครีเอเตอร์ใช้ API เหล่านี้
ย้ายการเชื่อมต่อ Higgsfield API ได้ภายในครึ่งวัน
ทั้งสอง API ทำงานแบบอะซิงโครนัส: ส่ง JSON รับ request id แล้วโพลล์หรือรับ webhook บน WaveSpeedAI คุณส่ง POST ไปที่ /api/v3/<model> ด้วย Bearer API key และอ่านผลลัพธ์ prediction ดังนั้นการย้ายส่วนใหญ่คือการเปลี่ยน base URL, auth header และเส้นทางโมเดล
ภาพและวิดีโอในไปป์ไลน์เดียว
สร้างภาพนิ่งด้วย Nano Banana Pro, Seedream 5.0 หรือ GPT Image 2.5 แล้วทำให้เคลื่อนไหวด้วย Seedance 2.5, Kling 3.0 หรือ Wan 3.0 image-to-video ภายใต้คีย์เดียวและยอดคงเหลือเดียว แค็ตตาล็อกที่เผยแพร่ของ Higgsfield API ไม่มี Nano Banana, Seedream หรือ GPT Image
MiniMax H3 แบบ open-weights พร้อม LoRA
WaveSpeedAI โฮสต์ MiniMax H3 แบบ open-weights พร้อมข้อความเป็นวิดีโอ ภาพเป็นวิดีโอ reference-to-video แก้ไขและต่อวิดีโอ endpoint LoRA สำหรับสไตล์และตัวละครแบบกำหนดเอง และโหมดข้อความเป็นภาพ
ช็อตเดี่ยวยาวและวิดีโอแบบแบ่งระดับ
Seedance 2.5 เรนเดอร์ช็อตเดี่ยวยาวสูงสุด 30 วินาทีพร้อมเสียงในตัว Kling 3.0 และ Kling O3 มีระดับ Standard, Pro และ 4K Wan 3.0 เพิ่มระดับ Prime เลือกต่อช็อตได้จากการเชื่อมต่อเดียวกัน
เอเจนต์และงานแบตช์
เรียกทุกโมเดลจาก Python หรือ JavaScript SDK, HTTP ธรรมดา, CLI หรือเซิร์ฟเวอร์ MCP เพื่อให้เอเจนต์เขียนโค้ดและสคริปต์แบตช์ใช้ endpoint และราคาเดียวกับแอปของคุณ
เคล็ดลับ
เคล็ดลับการเขียนพรอมต์สำหรับโมเดลเหล่านี้
คำแนะนำเชิงปฏิบัติเพื่อให้ได้ผลลัพธ์ที่ดีขึ้นจากโมเดลเหล่านี้ — มาจากรูปแบบที่ได้ผลกับโมเดลวิดีโอในไปป์ไลน์การผลิตจริง
- 01
ระบุการเคลื่อนกล้องให้เฉพาะเจาะจง
ใช้ศัพท์ภาพยนตร์ที่เป็นรูปธรรม — orbit, dolly-in, push-in, pan-left, crane shot, handheld follow พรอมต์ทั่วไปให้ช็อตนิ่งหรือการเลือกกล้องแบบสุ่ม ส่วนการเคลื่อนกล้องที่ระบุชื่อแมปไปยังเจตนาการเคลื่อนไหวในข้อมูลเทรนของโมเดลโดยตรงและช่วยยกระดับคุณภาพช็อตอย่างมาก
- 02
ยึดตัวตนของตัวละครด้วยภาพอ้างอิง
หากพรอมต์ของคุณขึ้นกับบุคคล ตัวละคร หรือสินค้าเฉพาะ ให้อัปโหลดภาพอ้างอิงควบคู่กับพรอมต์ หากไม่มีอ้างอิง ตัวตนจะเพี้ยนข้ามเฟรมและข้ามช็อต — ตัวละครเดียวกันดูเป็นคนละคนเล็กน้อยในแต่ละการสร้าง
- 03
อธิบายแสงและช่วงเวลาของวัน
คำบอกแสงอย่าง 'golden hour, soft warm directional light' หรือ 'overcast diffused light, slate-grey sky' ช่วยคุณภาพและความสม่ำเสมอได้มากกว่าตัวขยายคุณภาพแบบคลุมเครืออย่างมาก แสงเป็นหนึ่งในความรู้พื้นฐานที่โมเดลใช้กำกับแข็งแกร่งที่สุด
- 04
ใช้ negative prompt เพื่อกดข้อผิดพลาดที่พบบ่อย
negative ที่มีประโยชน์สำหรับวิดีโอ: 'frame flicker, motion blur, watermark, text artifacts, distorted hands, low resolution, jpeg compression' negative prompt ไม่มีค่าใช้จ่ายและลดอัตราการสร้างที่คุณต้องสุ่มใหม่ได้อย่างเห็นได้ชัด
- 05
เลือกความยาวที่สั้นที่สุดที่จับจังหวะของคุณได้
พรอมต์ส่วนใหญ่ทำงานได้ดีที่สุดที่ 5-8 วินาที คลิปที่ยาวขึ้นขยายความไม่สอดคล้องด้านเวลา (วัตถุเปลี่ยนรูป สภาพแวดล้อมเลื่อนไหล) หากต้องการซีเควนซ์ 20 วินาที ให้สร้างสามคลิป 6-8 วินาทีแล้วตัดต่อรวมกัน — คุณภาพยังสูงกว่าการสร้างยาวครั้งเดียว
- 06
จับคู่อัตราส่วนภาพกับแพลตฟอร์มตั้งแต่ต้น
9:16 สำหรับ TikTok / Reels / Shorts, 16:9 สำหรับฟีดแนวนอนและ YouTube, 1:1 สำหรับกริดโพสต์ โมเดลเทรนแตกต่างกันเล็กน้อยตามอัตราส่วนภาพ — การครอป 16:9 เป็น 9:16 ภายหลังสูญเสียทั้งความเที่ยงตรงและองค์ประกอบที่โมเดลตั้งใจ
ราคา
ราคา WaveSpeedAI API
คิดราคาตามผลลัพธ์ ค่าใช้จ่ายสุดท้ายขึ้นอยู่กับพารามิเตอร์ที่คุณตั้งใน playground ของแต่ละแบบ (ความละเอียด ความยาว จำนวนผลลัพธ์ ภาพอ้างอิง)
API
เรียกใช้ WaveSpeedAI API
สมัครรับ API key ที่ wavespeed.ai/accesskey แล้วส่ง prediction ผ่าน REST playground สร้างตัวอย่างพร้อมวางได้สำหรับอินพุตทุกแบบ
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)เปรียบเทียบ
WaveSpeedAI เทียบกับ Higgsfield API
จุดที่ WaveSpeedAI และHiggsfield APIแตกต่างกัน
WaveSpeedAI เทียบกับ Higgsfield API: models
Higgsfield API มีรายการภาพและวิดีโอ 82 รายการ รวมโมเดล Soul และ Cinema Studio ของตัวเอง พร้อม Seedance, Kling, Wan, MiniMax และ Qwen Image WaveSpeedAI ครอบคลุมตระกูลของบุคคลที่สามเหล่านั้น และเพิ่ม Nano Banana, Seedream, GPT Image, Veo รวมถึงโมเดลเสียง 3D และภาษา: กว่า 1,000 รายการทั้งหมด
WaveSpeedAI เทียบกับ Higgsfield API: credits
เงินใน Higgsfield API หมดอายุหนึ่งปีหลังซื้อ ส่วนเครดิต WaveSpeedAI ไม่มีวันหมดอายุ และไม่มีสมาชิกหรือการสมัครรายเดือน: เติมเมื่อต้องการและจ่ายต่อคำขอ ราคาของแต่ละ endpoint อยู่ในหน้าโมเดลและในตารางราคาของหน้านี้ เครดิตเดียวกันยังใช้จ่ายสำหรับสตูดิโอบนเบราว์เซอร์ได้ด้วย
WaveSpeedAI เทียบกับ Higgsfield API: open models
ทั้งสองมี MiniMax H3 บน WaveSpeedAI เป็นโมเดล open-weights ที่ WaveSpeedAI โฮสต์ พร้อม LoRA, reference-to-video, แก้ไข, ต่อวิดีโอ และ endpoint ภาพ ควบคู่กับข้อความเป็นวิดีโอและภาพเป็นวิดีโอมาตรฐาน
คำถามที่พบบ่อย
Higgsfield API Alternative — คำถามที่พบบ่อย
โมเดล ราคา การย้าย — คำถามที่พบบ่อยเกี่ยวกับการย้ายจากHiggsfield APIมา WaveSpeedAI
WaveSpeedAI เป็นทางเลือกแทน Higgsfield API หรือไม่
ใช่ WaveSpeedAI ให้บริการ Seedance 2.5 และ 2.0, Kling 3.0 และ O3, Wan 3.0, MiniMax H3 และ Qwen Image 3.0 เป็น REST endpoint รวมถึง Seedream 5.0, Nano Banana 2 และ Pro, และ GPT Image 2.5 และ 2 ด้วย API key เดียวและราคาแบบจ่ายต่อคำขอ
โมเดลไหนที่ฉันเรียกได้ซึ่ง Higgsfield API ไม่มี
แค็ตตาล็อกโมเดลที่เผยแพร่ของ Higgsfield API ไม่มี Nano Banana, Seedream, GPT Image, Veo หรือโมเดลเสียง บน WaveSpeedAI Nano Banana 2 และ Pro, Seedream 5.0, GPT Image 2.5 และ 2, Veo 3.1 และเสียง ElevenLabs อยู่ภายใต้คีย์เดียวกับโมเดลวิดีโอ
ย้ายจาก Higgsfield API อย่างไร
สร้างคีย์ที่ /accesskey จากนั้นส่ง POST อินพุตของคุณเป็น JSON ไปที่ https://api.wavespeed.ai/api/v3/<model> พร้อม Authorization: Bearer header คุณจะได้ prediction id กลับมา โพลล์ https://api.wavespeed.ai/api/v3/predictions/<id>/result หรือส่ง webhook จับคู่แต่ละโมเดลกับเส้นทาง WaveSpeedAI จากรายการ endpoint ในหน้านี้
MiniMax H3 บน WaveSpeedAI เป็นโมเดล open-weights หรือไม่
ใช่ endpoint wavespeed-ai/minimax-h3 รัน MiniMax H3 แบบ open-weights บน WaveSpeedAI รวมถึงตัวเลือก LoRA สำหรับสไตล์และตัวละครแบบกำหนดเอง reference-to-video แก้ไขและต่อวิดีโอ และโหมดข้อความเป็นภาพ
ต้องมีสมาชิกหรือการสมัครรายเดือนไหม และเครดิตหมดอายุหรือไม่
ไม่มีสมาชิกและไม่มีการสมัครรายเดือน WaveSpeedAI เป็นแบบจ่ายตามการใช้งาน: เติมเครดิตเมื่อต้องการและจ่ายต่อคำขอตามราคาที่แสดงในหน้าโมเดลแต่ละรายการและในตารางราคาด้านบน เครดิตไม่มีวันหมดอายุ บัญชีใหม่ที่มีสิทธิ์จะได้รับเครดิตเริ่มต้นฟรี
เรียกใช้ API เหล่านี้อย่างไร
สมัครบัญชี WaveSpeedAI คัดลอก API key จาก /accesskey แล้ว POST อินพุตของคุณเป็น JSON ไปที่ https://api.wavespeed.ai/api/v3/<model> เช่น https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video endpoint จะส่ง prediction id กลับมา poll endpoint ผลลัพธ์หรือส่ง webhook ตัวอย่าง Python / Node.js / cURL อยู่ด้านบน
API เหล่านี้มีค่าใช้จ่ายเท่าไร
endpoint ในหน้านี้เริ่มต้นที่ $0.02 ต่อครั้ง ราคาของแต่ละโมเดลอยู่ในตารางราคาด้านบนและในหน้าโมเดลของตัวเอง ค่าใช้จ่ายจริงขึ้นอยู่กับพารามิเตอร์ที่คุณตั้ง (ความละเอียด ความยาว จำนวนผลลัพธ์ ภาพอ้างอิง) และ playground จะแสดงให้เห็นก่อนที่คุณจะส่ง
เริ่มสร้างบน WaveSpeedAI
รับเครดิตเริ่มต้นฟรีเมื่อสมัคร API key เดียวใช้ได้กับโมเดล AI กว่า 1,000 รายการจากผู้ให้บริการชั้นนำทุกราย