Ideogram V4.5 Text-to-Image generates high-quality images from text prompts with flexible quality, strong typography, and composition controls for posters, logos, marketing visuals, brand assets, and creative production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Idle
$0.06per run·~16 / $1
ExamplesView all
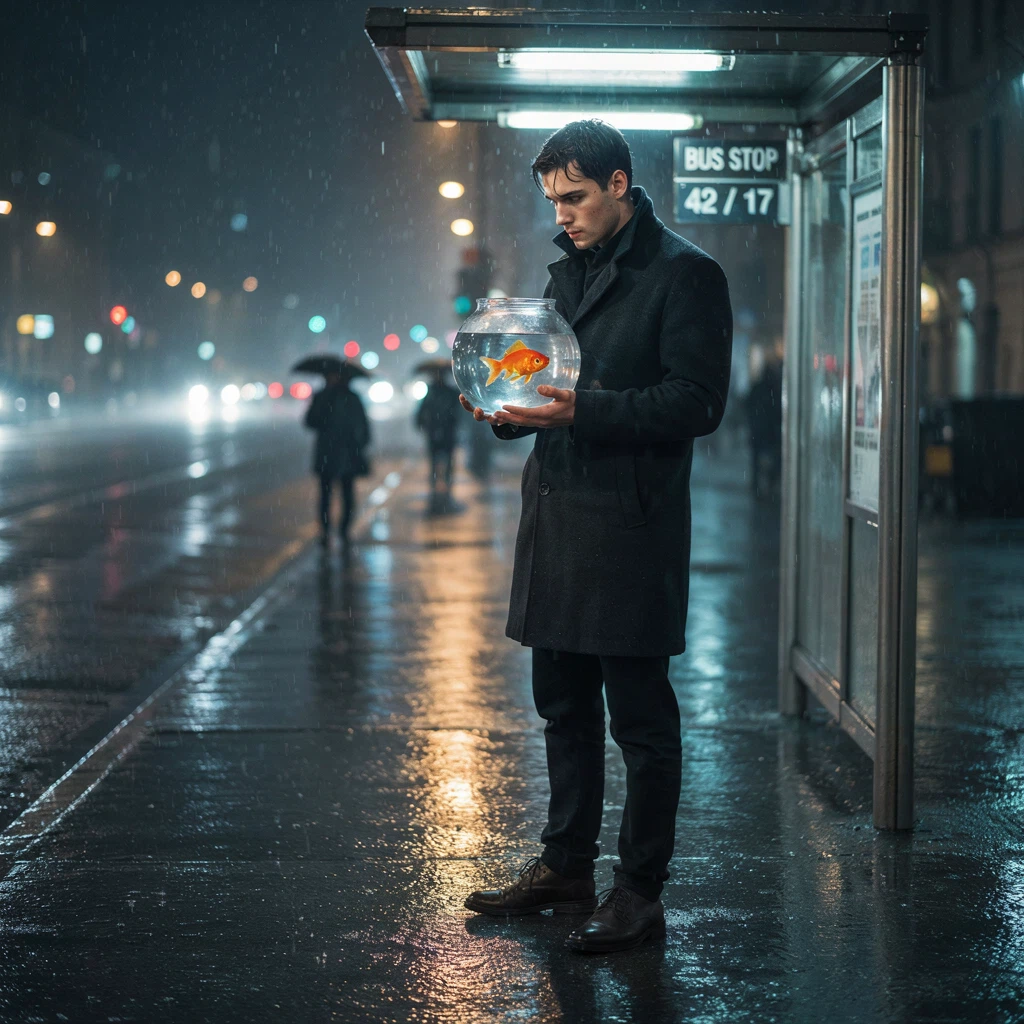
A handsome young man standing alone at a rainy city bus stop at night, wearing a dark wool coat and holding a round glass fishbowl with a bright orange goldfish inside. The bus stop light reflects on the wet pavement, and passing car lights streak softly in the background. His expression is thoughtful and slightly melancholic, while the goldfish seems to be staring out at the city. Cinematic urban realism, beautiful reflections, emotional atmosphere, highly detailed.
Related Models
README
Ideogram V4.5
Ideogram V4.5 generates high-quality images from text descriptions with strong typography, composition, and prompt adherence. It is especially useful for posters, packaging concepts, advertising creatives, branded graphics, editorial artwork, and other designs where layout and readable text matter.
Choose between 1K and 2K output, multiple aspect ratios, and three quality tiers depending on your workflow and budget.
Why Choose This?
-
Typography-focused generation
Create images containing signs, headlines, labels, packaging text, and other designed typography. -
Strong prompt adherence
Guide subjects, layout, lighting, visual style, and text placement directly through natural-language prompts. -
Flexible framing
Choose from square, landscape, portrait, and widescreen aspect ratios. -
1K and 2K output
Select the resolution that fits rapid iteration or higher-resolution production. -
Three quality tiers
Chooselow,medium, orhighdepending on the desired balance of cost and output quality. -
Prompt expansion
Enable automatic prompt expansion to give the model additional interpretation of the original prompt.
Parameters
| Parameter | Required | Description |
|---|---|---|
| prompt | Yes | Text description of the image to generate. Supports 1–10000 characters. |
| resolution | No | Output resolution: 1k or 2k. Default: 1k. |
| aspect_ratio | No | Output aspect ratio: 1:1, 4:3, 3:4, 3:2, 2:3, 16:9, or 9:16. Default: 1:1. |
| quality | No | Generation quality: low, medium, or high. Default: medium. |
| enable_prompt_expansion | No | Expand the prompt before generation. Default: true. |
How to Use
- Write a prompt — Describe the subject, composition, lighting, visual style, and any text that should appear in the image.
- Choose resolution — Select
1kor2k. - Choose aspect ratio — Pick the layout that fits your target composition.
- Choose quality — Use
low,medium, orhighdepending on your quality and cost requirements. - Configure prompt expansion optional — Keep it enabled for automatic prompt enhancement or disable it when you want to preserve the original prompt more directly.
- Submit — Generate and retrieve the final image.
Pricing
Pricing is based only on the selected quality tier.
| Quality | Price per Image |
|---|---|
| Low | $0.03 |
| Medium | $0.06 |
| High | $0.22 |
The default medium quality request costs $0.06 per image.
resolution, aspect_ratio, and enable_prompt_expansion do not add separate charges.
Best Use Cases
- Advertising creatives — Generate campaign concepts, promotional artwork, and branded visual assets.
- Packaging concepts — Create product packaging designs with integrated typography.
- Poster design — Generate compositions where headlines and visual hierarchy are important.
- Editorial illustrations — Produce magazine-style artwork, covers, and supporting visuals.
- Social media graphics — Create campaign and promotional content for different layouts.
- Typography-heavy concepts — Generate visuals containing signs, labels, titles, and other readable text.
Pro Tips
- Put exact text that should appear in the image inside quotation marks.
- Describe where text should appear relative to the subject and other design elements.
- Specify composition, lighting, color palette, and visual hierarchy when layout matters.
- Use
lowquality for rapid concept exploration before moving to higher-quality output. - Use
2kwhen additional output detail or larger final dimensions are needed. - Disable prompt expansion when you want the model to follow the original wording more directly.
- Check spelling and small text details before publishing generated artwork.
Notes
promptis required.resolutiondefaults to1k.aspect_ratiodefaults to1:1.qualitydefaults tomedium.enable_prompt_expansiondefaults totrue.- This endpoint generates images from text; use the edit model when modifying an existing image.
Related Models
- Ideogram V4.5 — Generate images from text with typography, composition, and prompt control.
- Ideogram V4.5 Edit — Edit existing images with natural-language instructions.
Ideogram v4.5 API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/ideogram-ai/ideogram-v4.5 with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Ideogram v4.5 below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "resolution": "1k",
    "aspect_ratio": "1:1",
    "quality": "medium",
    "enable_prompt_expansion": true
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/ideogram-ai/ideogram-v4.5" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/ideogram-ai/ideogram-v4.5";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "resolution": "1k",
        "aspect_ratio": "1:1",
        "quality": "medium",
        "enable_prompt_expansion": true
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "resolution": "1k",
    "aspect_ratio": "1:1",
    "quality": "medium",
    "enable_prompt_expansion": True
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/ideogram-ai/ideogram-v4.5", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Ideogram v4.5 API — Frequently asked questions
What is the Ideogram v4.5 API?
Ideogram v4.5 is a Ideogram model for image generation, exposed as a REST API on WaveSpeedAI. Ideogram V4.5 Text-to-Image generates high-quality images from text prompts with flexible quality, strong typography, and composition controls for posters, logos, marketing visuals, brand assets, and creative production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Ideogram v4.5 API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/ideogram-ai/ideogram-ai-ideogram-v4.5.
How much does Ideogram v4.5 cost per run?
Ideogram v4.5 starts at $0.06 per run. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Ideogram v4.5 accept?
Key inputs: `prompt`, `aspect_ratio`, `resolution`, `enable_prompt_expansion`, `quality`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/ideogram-ai/ideogram-ai-ideogram-v4.5.
How do I get started with the Ideogram v4.5 API?
Sign up for a free WaveSpeedAI account to claim starter credits, copy your API key from /accesskey, then call the endpoint shown in the API tab of the playground. The playground also auto-generates a code sample in Python, JavaScript, or cURL for the parameters you've set.
Can I use Ideogram v4.5 outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (Ideogram). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from Ideogram
View all- ideogram-ai/ideogram-characterImage to Image
- ideogram-ai/ideogram-v2Text to Image
- ideogram-ai/ideogram-v2-turboText to Image
- ideogram-ai/ideogram-v2aText to Image
- ideogram-ai/ideogram-v2a-turboText to Image
- ideogram-ai/ideogram-v3-balancedText to Image
- ideogram-ai/ideogram-v3-qualityText to Image
- ideogram-ai/ideogram-v3-turboText to Image
More Text to Image models
View all- bytedance/seedream-v5.0-proText to Image
- openai/gpt-image-2/text-to-imageText to Image
- google/nano-banana-pro/text-to-imageText to Image
- google/nano-banana-2/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- bytedance/seedream-v4.5Text to Image
- alibaba/wan-2.7/text-to-imageText to Image
- alibaba/qwen-image-3.0/text-to-imageText to Image