Higgsfield API Alternative
वे मॉडल जो डेवलपर Higgsfield API में खोजते हैं — Seedance 2.5 और 2.0, Kling 3.0 और O3, Wan 3.0, ओपन-वेट्स MiniMax H3 और Qwen Image 3.0 — साथ में Seedream 5.0, Nano Banana 2 और Pro, तथा GPT Image 2.5 और 2, एक ही WaveSpeedAI API key पर। जितना इस्तेमाल, उतना भुगतान: क्रेडिट कभी एक्सपायर नहीं होते, और कोई मेंबरशिप या सब्सक्रिप्शन नहीं है।
Higgsfield API को परख रहे हैं? नीचे दिया हर एंडपॉइंट आज WaveSpeedAI पर लाइव है, प्लेग्राउंड, उदाहरण और प्रति-रन मौजूदा कीमत के साथ। एक बार रिचार्ज करें और अपने क्रेडिट जब चाहें इस्तेमाल करें — वे कभी एक्सपायर नहीं होते — इन मॉडल पर और 1,000+ अन्य इमेज, वीडियो, ऑडियो, 3D और भाषा मॉडल पर।
अवलोकन
Higgsfield API Alternative के बारे में
यदि आप Higgsfield API का मूल्यांकन कर रहे हैं, तो WaveSpeedAI पर आप क्या कॉल कर सकते हैं।
वे मॉडल जो डेवलपर Higgsfield API में खोजते हैं — Seedance 2.5 और 2.0, Kling 3.0 और O3, Wan 3.0, ओपन-वेट्स MiniMax H3 और Qwen Image 3.0 — साथ में Seedream 5.0, Nano Banana 2 और Pro, तथा GPT Image 2.5 और 2, एक ही WaveSpeedAI API key पर। जितना इस्तेमाल, उतना भुगतान: क्रेडिट कभी एक्सपायर नहीं होते, और कोई मेंबरशिप या सब्सक्रिप्शन नहीं है।
Higgsfield API को परख रहे हैं? नीचे दिया हर एंडपॉइंट आज WaveSpeedAI पर लाइव है, प्लेग्राउंड, उदाहरण और प्रति-रन मौजूदा कीमत के साथ। एक बार रिचार्ज करें और अपने क्रेडिट जब चाहें इस्तेमाल करें — वे कभी एक्सपायर नहीं होते — इन मॉडल पर और 1,000+ अन्य इमेज, वीडियो, ऑडियो, 3D और भाषा मॉडल पर।
नीचे दिए गए एंडपॉइंट इन मॉडल के लिए 37 लाइव WaveSpeedAI REST एंडपॉइंट हैं, जो Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image वर्कफ़्लो को कवर करते हैं। हर एक का अपना प्लेग्राउंड, प्राइसिंग और उदाहरण हैं, और सभी को एक ही तरह से कॉल किया जाता है: JSON POST करें, prediction id पाएं, फिर पोल करें या वेबहुक प्राप्त करें।
ये WaveSpeedAI के अन्य 1,000+ मॉडल के साथ एक API कुंजी, एक बैलेंस और एक इंटीग्रेशन साझा करते हैं — टेक्स्ट-टू-इमेज और टेक्स्ट-टू-वीडियो से लेकर ऑडियो, 3D, अपस्केलिंग, एडिटिंग और भाषा मॉडल तक।
एंडपॉइंट
सभी WaveSpeedAI API एंडपॉइंट
WaveSpeedAI पर अभी 37 एंडपॉइंट उपलब्ध हैं — अपने वर्कफ़्लो के अनुकूल वेरिएंट चुनें।
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
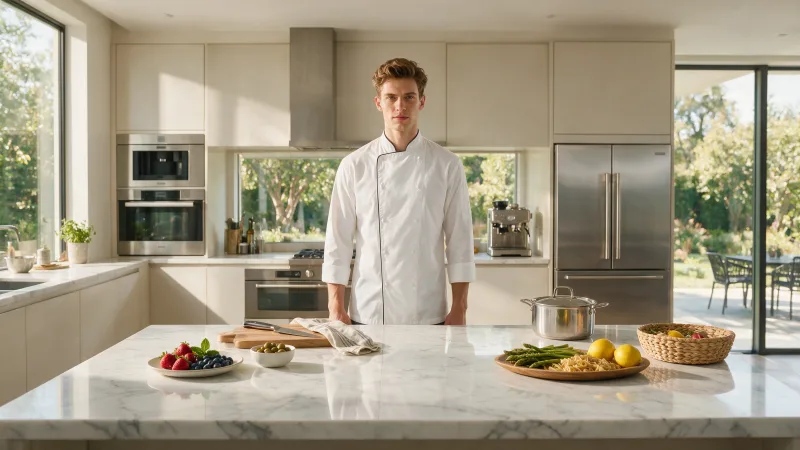
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
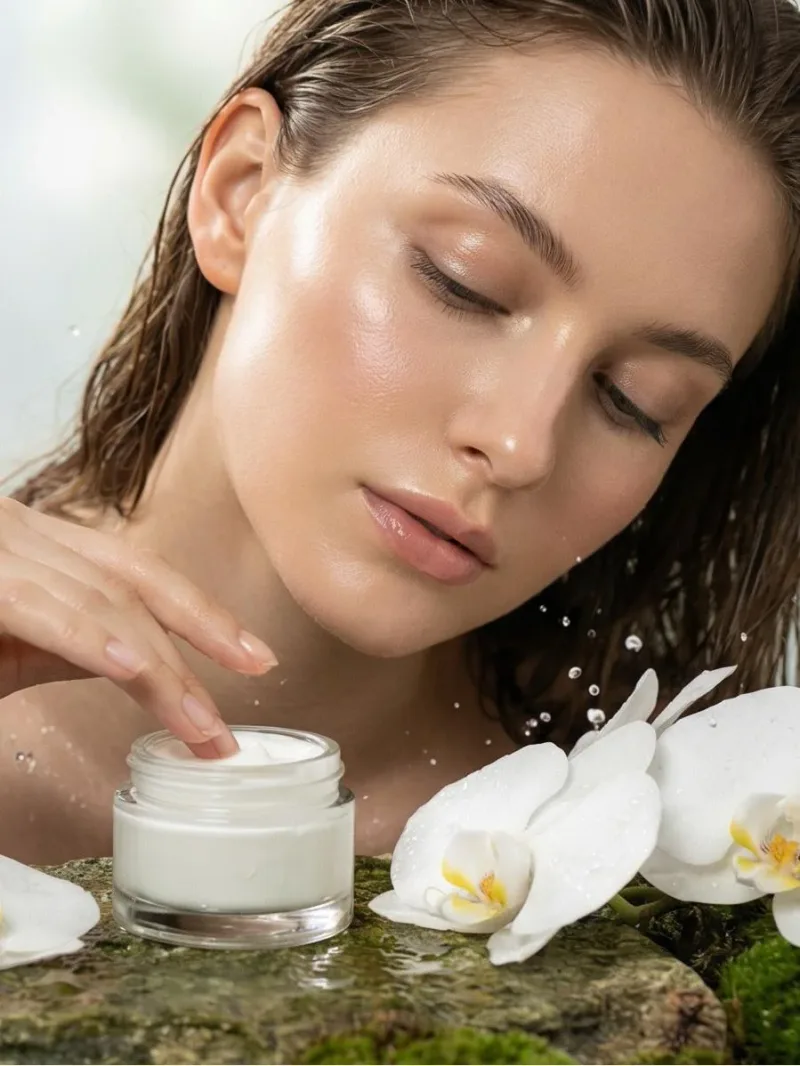
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
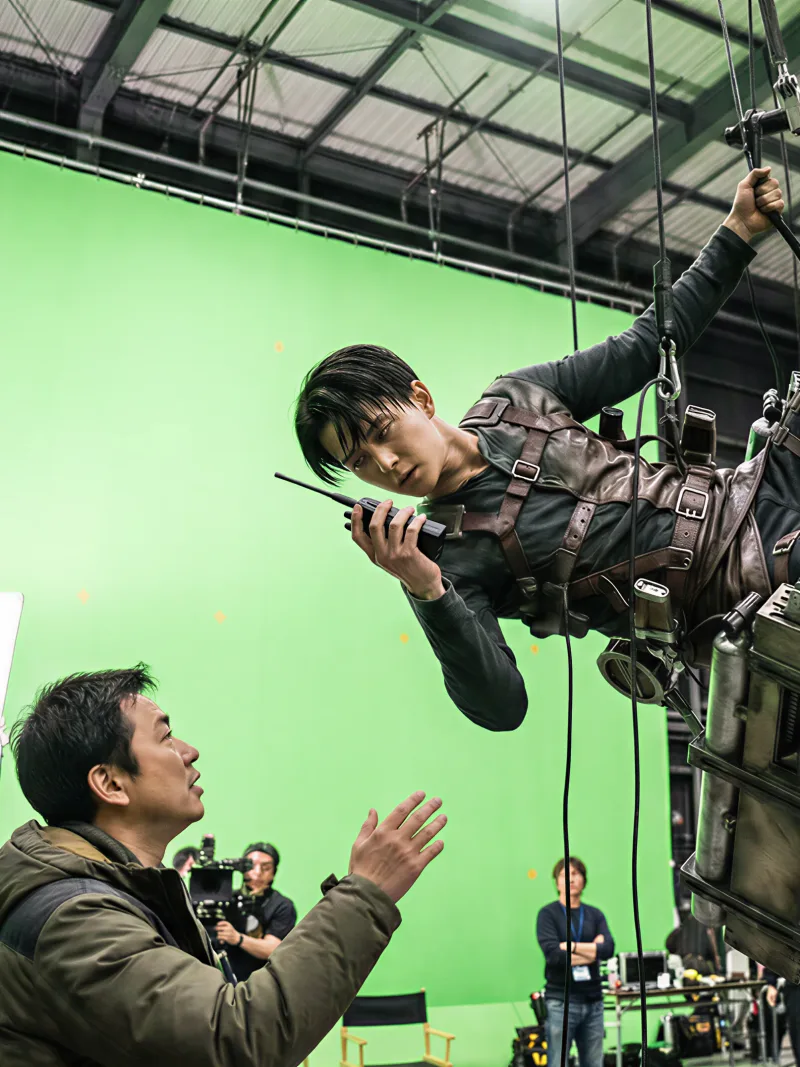
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
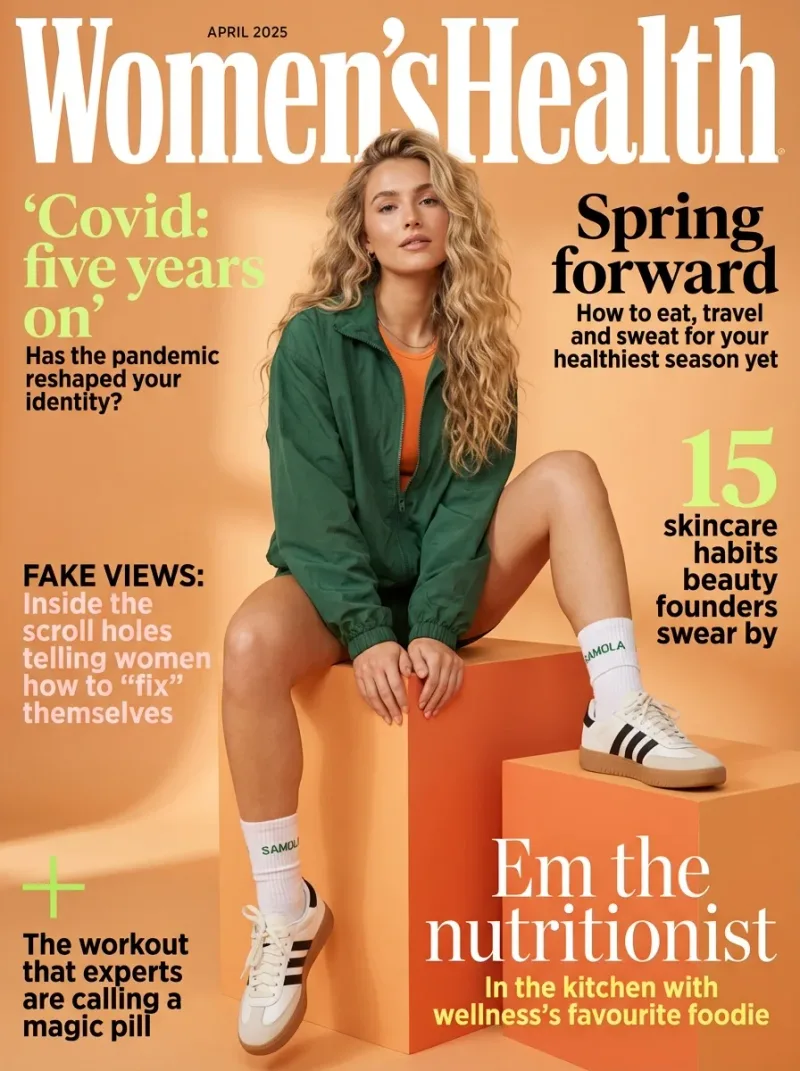
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
उदाहरण
WaveSpeedAI को काम करते देखें
WaveSpeedAI API से बनाए गए असली आउटपुट। किसी भी वीडियो पर होवर करके प्रीव्यू देखें, पूर्ण आकार का व्यूअर खोलने के लिए क्लिक करें।
कैसे करें
WaveSpeedAI API का उपयोग कैसे करें
साइनअप से तैयार जनरेशन तक चार चरण। पूरे Python, Node.js और cURL उदाहरण नीचे API सेक्शन में हैं।
- 01
API कुंजी प्राप्त करें
WaveSpeedAI अकाउंट बनाएं और डैशबोर्ड से अपनी API कुंजी कॉपी करें। नए अकाउंट के साथ मुफ़्त शुरुआती क्रेडिट मिलते हैं — बिलिंग शुरू होने से पहले प्लेग्राउंड को कई दर्जन बार चलाने के लिए पर्याप्त।
- 02
prediction सबमिट करें
अपना इनपुट JSON के रूप में https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video पर POST करें। एंडपॉइंट तुरंत एक prediction id लौटाता है — जनरेशन असिंक्रोनस होते हैं, इसलिए इनफ़रेंस के दौरान आपको कनेक्शन खुला नहीं रखना पड़ता।
- 03
पूर्ण होने तक पोल करें
https://api.wavespeed.ai/api/v3/predictions/{request_id}/result पर GET करें। completed पर आउटपुट लौटाएं; failed, cancelled, timeout या deleted पर त्रुटि के साथ रुकें; बाकी हर status पर पोलिंग जारी रखें।
- 04
आउटपुट URL पढ़ें
status "completed" होने पर data.outputs[0] से URL पढ़ें। यह URL WaveSpeedAI CDN पर आपके बनाए मीडिया की ओर इशारा करता है — आपके कॉल किए गए मॉडल वेरिएंट के अनुसार इमेज, वीडियो, ऑडियो या 3D फ़ाइल।
उपयोग के मामले
इन मॉडल से आप क्या बना सकते हैं
आम वर्कफ़्लो जिनके लिए डेवलपर और क्रिएटर इन API का उपयोग करते हैं।
Higgsfield API इंटीग्रेशन को एक दोपहर में माइग्रेट करें
दोनों API एसिंक्रोनस हैं: JSON सबमिट करें, रिक्वेस्ट id पाएं, फिर पोल करें या वेबहुक लें। WaveSpeedAI पर आप Bearer API key के साथ /api/v3/<model> पर POST करते हैं और प्रेडिक्शन रिज़ल्ट पढ़ते हैं, इसलिए पोर्टिंग ज़्यादातर बेस URL, ऑथ हेडर और मॉडल पाथ बदलने भर की है।
एक पाइपलाइन में इमेज और वीडियो
Nano Banana Pro, Seedream 5.0 या GPT Image 2.5 से स्टिल बनाएं, फिर Seedance 2.5, Kling 3.0 या Wan 3.0 image-to-video से उन्हें एनिमेट करें, एक key और एक बैलेंस पर। Higgsfield API के प्रकाशित कैटलॉग में Nano Banana, Seedream या GPT Image सूचीबद्ध नहीं हैं।
LoRA के साथ ओपन-वेट्स MiniMax H3
WaveSpeedAI ओपन-वेट्स MiniMax H3 होस्ट करता है, जिसमें text-to-video, image-to-video, reference-to-video, वीडियो एडिट और एक्सटेंड, कस्टम स्टाइल व कैरेक्टर के लिए LoRA एंडपॉइंट, और text-to-image मोड शामिल हैं।
लंबे सिंगल शॉट और टियर वाला वीडियो
Seedance 2.5 नेटिव ऑडियो के साथ 30 सेकंड तक के सिंगल शॉट रेंडर करता है; Kling 3.0 और Kling O3 Standard, Pro और 4K टियर में आते हैं; Wan 3.0 Prime टियर जोड़ता है। एक ही इंटीग्रेशन से हर शॉट के लिए चुनें।
एजेंट और बैच जॉब
हर मॉडल को Python या JavaScript SDK, सादे HTTP, CLI या MCP सर्वर से कॉल करें, ताकि कोडिंग एजेंट और बैच स्क्रिप्ट आपके ऐप जैसे ही एंडपॉइंट और कीमतें इस्तेमाल करें।
सुझाव
इन मॉडल के लिए प्रॉम्प्ट लिखने के सुझाव
इन मॉडल से बेहतर आउटपुट पाने के व्यावहारिक सुझाव — प्रोडक्शन पाइपलाइन में वीडियो मॉडल पर काम करने वाले पैटर्न से लिए गए।
- 01
कैमरा मूव के बारे में विशिष्ट रहें
सिनेमैटोग्राफ़ी की ठोस शब्दावली का उल्लेख करें — ऑर्बिट, डॉली-इन, पुश-इन, पैन-लेफ़्ट, क्रेन शॉट, हैंडहेल्ड फ़ॉलो। सामान्य प्रॉम्प्ट स्थिर या मनमाने कैमरा विकल्प देते हैं; नामित कैमरा मूव मॉडल के ट्रेनिंग डेटा में मोशन के इरादे से सीधे जुड़ते हैं और शॉट की क्वालिटी काफ़ी सुधारते हैं।
- 02
रेफ़रेंस इमेज से कैरेक्टर की पहचान टिकाएं
अगर आपका प्रॉम्प्ट किसी खास व्यक्ति, कैरेक्टर या प्रोडक्ट पर निर्भर है, तो प्रॉम्प्ट के साथ रेफ़रेंस इमेज अपलोड करें। रेफ़रेंस के बिना पहचान फ़्रेमों और शॉट्स में भटकती है — हर जनरेशन में वही कैरेक्टर थोड़े अलग व्यक्ति जैसा दिखने लगता है।
- 03
लाइटिंग और दिन का समय बताएं
'golden hour, soft warm directional light' या 'overcast diffused light, slate-grey sky' जैसे लाइटिंग संकेत अस्पष्ट क्वालिटी मॉडिफ़ायर से कहीं ज़्यादा क्वालिटी और निरंतरता सुधारते हैं। लाइटिंग उन सबसे मज़बूत प्रायर में से है जिन पर मॉडल कंडीशन करता है।
- 04
आम विफलताओं को दबाने के लिए नेगेटिव प्रॉम्प्ट इस्तेमाल करें
वीडियो के लिए उपयोगी नेगेटिव: 'frame flicker, motion blur, watermark, text artifacts, distorted hands, low resolution, jpeg compression'। नेगेटिव प्रॉम्प्ट की कोई लागत नहीं और ये उन जनरेशन की दर घटाते हैं जिन्हें आपको वरना दोबारा रोल करना पड़ता।
- 05
अपनी बीट को समेटने वाली सबसे छोटी अवधि चुनें
ज़्यादातर प्रॉम्प्ट 5-8 सेकंड पर सबसे अच्छे काम करते हैं। लंबी क्लिप टेम्पोरल असंगतियां (विषय का रूप बदलना, परिवेश का खिसकना) बढ़ा देती हैं। अगर 20 सेकंड का सीक्वेंस चाहिए, तो तीन 6-8 सेकंड की क्लिप बनाकर उन्हें एडिट में जोड़ें — एक लंबे जनरेशन से क्वालिटी ऊंची रहती है।
- 06
आस्पेक्ट रेशियो पहले से प्लेटफ़ॉर्म के अनुसार तय करें
TikTok / Reels / Shorts के लिए 9:16, लैंडस्केप फ़ीड और YouTube के लिए 16:9, पोस्ट ग्रिड के लिए 1:1। मॉडल हर आस्पेक्ट रेशियो पर थोड़ा अलग ट्रेन होते हैं — 16:9 को बाद में 9:16 में क्रॉप करने से फ़िडेलिटी और मॉडल द्वारा सोची गई कंपोज़िशन दोनों खो जाती हैं।
प्राइसिंग
WaveSpeedAI API प्राइसिंग
प्राइसिंग प्रति आउटपुट है। अंतिम शुल्क उन पैरामीटर के अनुसार बदलता है जो आप हर वेरिएंट के प्लेग्राउंड में सेट करते हैं (रिज़ॉल्यूशन, अवधि, आउटपुट संख्या, रेफरेंस)।
API
WaveSpeedAI API कॉल करें
wavespeed.ai/accesskey पर API कुंजी बनाएं, फिर REST के ज़रिए prediction सबमिट करें। प्लेग्राउंड इनपुट के किसी भी संयोजन के लिए सीधे पेस्ट करने योग्य नमूने तैयार करता है।
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)तुलना
WaveSpeedAI बनाम Higgsfield API
WaveSpeedAI और Higgsfield API में अंतर कहाँ है।
WaveSpeedAI बनाम Higgsfield API: models
Higgsfield API में 82 इमेज और वीडियो एंट्री सूचीबद्ध हैं, जिनमें इसके अपने Soul और Cinema Studio मॉडल के साथ Seedance, Kling, Wan, MiniMax और Qwen Image शामिल हैं। WaveSpeedAI उन थर्ड-पार्टी फ़ैमिली को कवर करता है और Nano Banana, Seedream, GPT Image, Veo, ऑडियो, 3D और भाषा मॉडल जोड़ता है: कुल 1,000+।
WaveSpeedAI बनाम Higgsfield API: credits
Higgsfield API की राशि खरीद के एक साल बाद एक्सपायर हो जाती है। WaveSpeedAI क्रेडिट कभी एक्सपायर नहीं होते, और कोई मेंबरशिप या सब्सक्रिप्शन नहीं है: ज़रूरत पड़ने पर रिचार्ज करें और प्रति रिक्वेस्ट भुगतान करें, हर एंडपॉइंट की कीमत उसके मॉडल पेज और इस पेज की प्राइसिंग टेबल में है। वही क्रेडिट ब्राउज़र स्टूडियो के लिए भी चलते हैं।
WaveSpeedAI बनाम Higgsfield API: open models
दोनों MiniMax H3 सूचीबद्ध करते हैं। WaveSpeedAI पर यह WaveSpeedAI द्वारा होस्ट किया गया ओपन-वेट्स मॉडल है, जिसमें स्टैंडर्ड text-to-video और image-to-video के साथ LoRA, reference-to-video, एडिट, एक्सटेंड और इमेज एंडपॉइंट हैं।
FAQ
Higgsfield API Alternative — अक्सर पूछे जाने वाले प्रश्न
मॉडल, प्राइसिंग, माइग्रेशन — Higgsfield API से WaveSpeedAI पर आने के बारे में आम सवाल।
क्या WaveSpeedAI, Higgsfield API का विकल्प है?
हाँ। WaveSpeedAI Seedance 2.5 और 2.0, Kling 3.0 और O3, Wan 3.0, MiniMax H3 और Qwen Image 3.0 को REST एंडपॉइंट के रूप में देता है, साथ में Seedream 5.0, Nano Banana 2 और Pro, तथा GPT Image 2.5 और 2, एक API key और प्रति-रिक्वेस्ट प्राइसिंग के साथ।
मैं कौन-से ऐसे मॉडल कॉल कर सकता हूँ जो Higgsfield API में सूचीबद्ध नहीं हैं?
Higgsfield API के प्रकाशित मॉडल कैटलॉग में Nano Banana, Seedream, GPT Image, Veo या ऑडियो मॉडल नहीं हैं। WaveSpeedAI पर Nano Banana 2 और Pro, Seedream 5.0, GPT Image 2.5 और 2, Veo 3.1 और ElevenLabs आवाज़ें वीडियो मॉडल वाली उसी key के पीछे उपलब्ध हैं।
मैं Higgsfield API से कैसे स्विच करूं?
/accesskey पर एक key बनाएं, फिर Authorization: Bearer हेडर के साथ अपना इनपुट JSON के रूप में https://api.wavespeed.ai/api/v3/<model> पर POST करें। आपको एक प्रेडिक्शन id मिलेगी; https://api.wavespeed.ai/api/v3/predictions/<id>/result को पोल करें या वेबहुक दें। इस पेज की एंडपॉइंट सूची से हर मॉडल को उसके WaveSpeedAI पाथ से मिलाएं।
क्या WaveSpeedAI पर MiniMax H3 ओपन-वेट्स मॉडल है?
हाँ। wavespeed-ai/minimax-h3 एंडपॉइंट WaveSpeedAI पर ओपन-वेट्स MiniMax H3 चलाते हैं, जिसमें कस्टम स्टाइल व कैरेक्टर के लिए LoRA वेरिएंट, reference-to-video, वीडियो एडिट और एक्सटेंड, और text-to-image मोड शामिल हैं।
क्या मुझे मेंबरशिप या सब्सक्रिप्शन चाहिए, और क्या क्रेडिट एक्सपायर होते हैं?
कोई मेंबरशिप नहीं और कोई सब्सक्रिप्शन नहीं। WaveSpeedAI पे-एज़-यू-गो है: ज़रूरत पड़ने पर क्रेडिट रिचार्ज करें और हर मॉडल पेज व ऊपर की प्राइसिंग टेबल में दिखाई गई कीमत पर प्रति रिक्वेस्ट भुगतान करें। क्रेडिट कभी एक्सपायर नहीं होते। पात्र नए अकाउंट को मुफ़्त स्टार्टर क्रेडिट मिलते हैं।
इन API को कैसे कॉल करें?
WaveSpeedAI अकाउंट बनाएं, /accesskey से अपनी API कुंजी कॉपी करें, फिर अपना इनपुट JSON के रूप में https://api.wavespeed.ai/api/v3/<model> पर POST करें, उदाहरण के लिए https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video। एंडपॉइंट एक prediction id लौटाता है। रिज़ल्ट एंडपॉइंट को पोल करें या वेबहुक दें। Python / Node.js / cURL उदाहरण ऊपर हैं।
इन API की कीमत कितनी है?
इस पेज के एंडपॉइंट $0.02 प्रति रन से शुरू होते हैं; हर मॉडल की कीमत ऊपर की प्राइसिंग तालिका और उसके मॉडल पेज पर है। सटीक लागत आपके सेट किए पैरामीटर (रिज़ॉल्यूशन, अवधि, आउटपुट संख्या, रेफरेंस) के अनुसार बदलती है, और प्लेग्राउंड सबमिट करने से पहले इसे दिखाता है।
WaveSpeedAI पर बनाना शुरू करें
साइनअप पर मुफ़्त शुरुआती क्रेडिट। हर प्रमुख प्रदाता के 1,000+ AI मॉडल के लिए एक API कुंजी।