Higgsfield API Alternative
Die Modelle, die Entwickler in der Higgsfield API suchen – Seedance 2.5 und 2.0, Kling 3.0 und O3, Wan 3.0, das Open-Weights-Modell MiniMax H3 und Qwen Image 3.0 – plus Seedream 5.0, Nano Banana 2 und Pro sowie GPT Image 2.5 und 2, mit einem WaveSpeedAI-API-Schlüssel. Nutzungsbasiert: Credits verfallen nie, und es gibt weder Mitgliedschaft noch Abonnement.
Sie prüfen die Higgsfield API? Jeder Endpunkt unten ist auf WaveSpeedAI heute live – mit Playground, Beispielen und dem aktuellen Preis pro Aufruf. Laden Sie einmal auf und nutzen Sie Ihre Credits, wann Sie möchten – sie verfallen nie – für diese Modelle und über 1.000 weitere Modelle für Bild, Video, Audio, 3D und Sprache.
Überblick
Über Higgsfield API Alternative
Was Sie auf WaveSpeedAI aufrufen können, wenn Sie Higgsfield API evaluieren.
Die Modelle, die Entwickler in der Higgsfield API suchen – Seedance 2.5 und 2.0, Kling 3.0 und O3, Wan 3.0, das Open-Weights-Modell MiniMax H3 und Qwen Image 3.0 – plus Seedream 5.0, Nano Banana 2 und Pro sowie GPT Image 2.5 und 2, mit einem WaveSpeedAI-API-Schlüssel. Nutzungsbasiert: Credits verfallen nie, und es gibt weder Mitgliedschaft noch Abonnement.
Sie prüfen die Higgsfield API? Jeder Endpunkt unten ist auf WaveSpeedAI heute live – mit Playground, Beispielen und dem aktuellen Preis pro Aufruf. Laden Sie einmal auf und nutzen Sie Ihre Credits, wann Sie möchten – sie verfallen nie – für diese Modelle und über 1.000 weitere Modelle für Bild, Video, Audio, 3D und Sprache.
Die Endpunkte unten sind 37 aktive WaveSpeedAI-REST-Endpunkte für diese Modelle, die die Workflows Text-To-Video, Image-To-Video, Image-Tools, Text-To-Image, Image-To-Image abdecken. Jeder hat einen eigenen Playground, eigene Preise und Beispiele, und alle werden gleich aufgerufen: JSON per POST senden, eine Prediction-ID erhalten, abfragen oder einen Webhook empfangen.
Sie teilen sich einen API-Schlüssel, ein Guthaben und eine Integration mit den über 1.000 weiteren Modellen auf WaveSpeedAI – von Text-zu-Bild und Text-zu-Video über Audio, 3D, Hochskalierung und Bearbeitung bis zu Sprachmodellen.
Endpunkte
Alle WaveSpeedAI-API-Endpunkte
37 Endpunkte jetzt auf WaveSpeedAI verfügbar – wählen Sie die Variante, die zu Ihrem Workflow passt.
Seedance 2.5 Text To Video Turbo
Seedance 2.5 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Text To Video
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.5 Image To Video Turbo
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 Image To Video
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 Text To Video Turbo
Seedance 2.0 (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Text To Video
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics.
Seedance 2.0 Image To Video Turbo
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.0 Image To Video
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Kling v3.0 Pro Text To Video
Kling 3.0 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling v3.0 Pro Image To Video
Kling 3.0 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling Video O3 Pro Text To Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Kling Video O3 Pro Image To Video
Kling Omni Video O3 Image-to-Video transforms static images into dynamic cinematic videos using MVL (Multi-modal Visual Language) technology. Maintains subject consistency while adding natural motion, physics simulation, and seamless scene dynamics. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
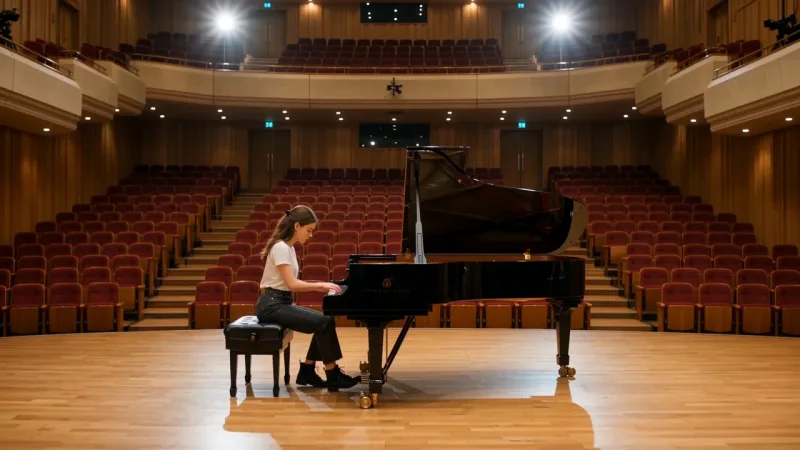
Wan 3.0 Text To Video
Wan 3.0 Text to Video generates cinematic videos from text prompts, with flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
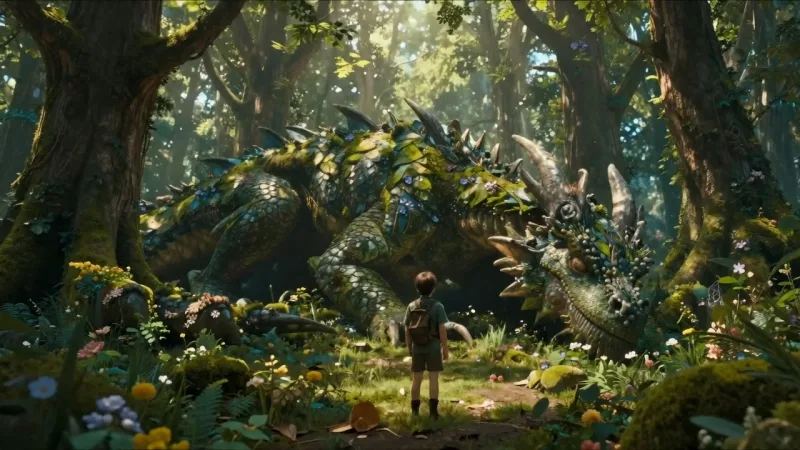
Wan 3.0 Image To Video
Wan 3.0 Image to Video animates a first-frame image into a cinematic video, with optional last-frame guidance, flexible 2-30 second duration, aspect ratio control, optional audio, and deep-thinking controls for high-quality motion and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
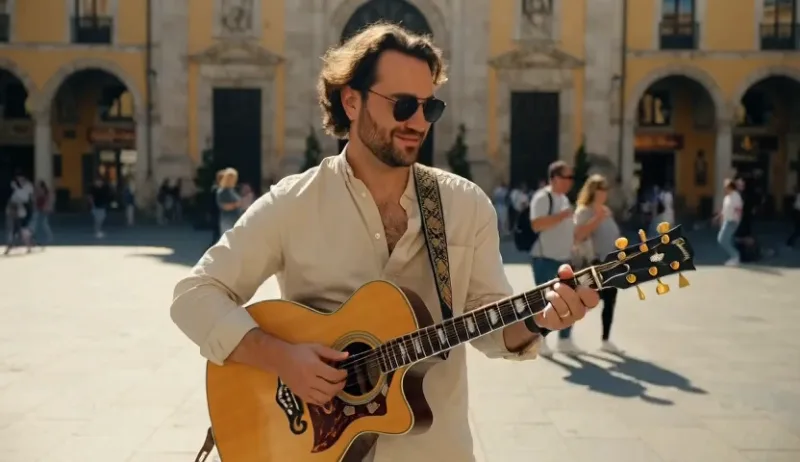
Minimax H3 Text To Video Lora
MiniMax H3 Open Weights Text to Video with custom LoRA support generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
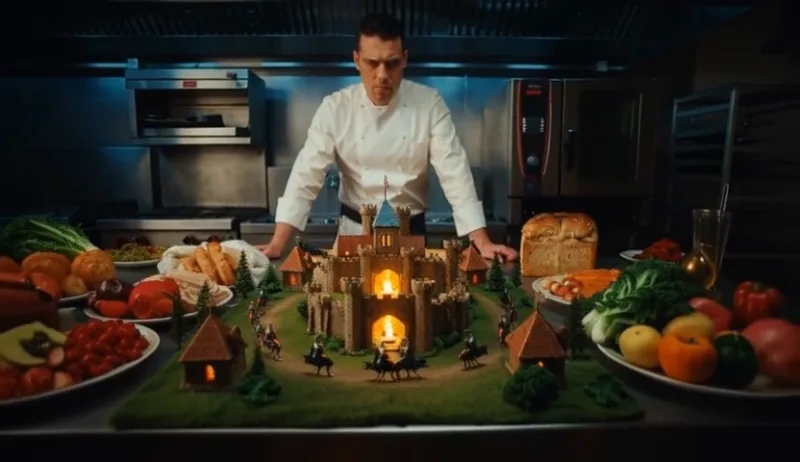
Minimax H3 Text To Video
MiniMax H3 Open Weights Text to Video generates coherent videos from text prompts, with 480P / 540P / 768P output, native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
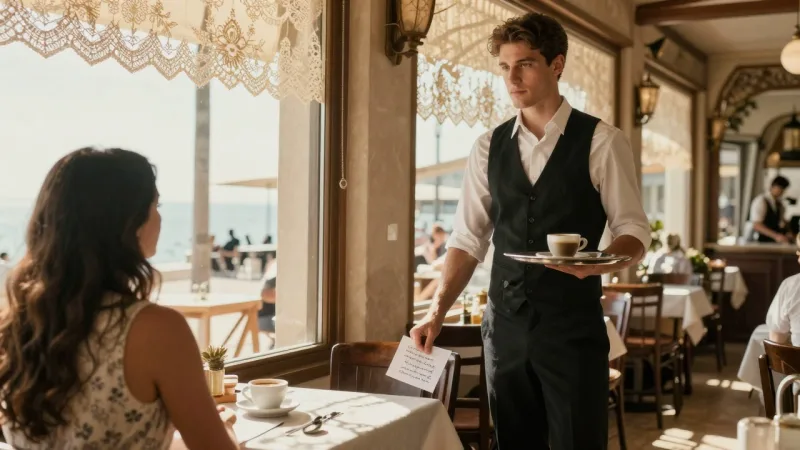
Minimax H3 Image To Video Lora
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
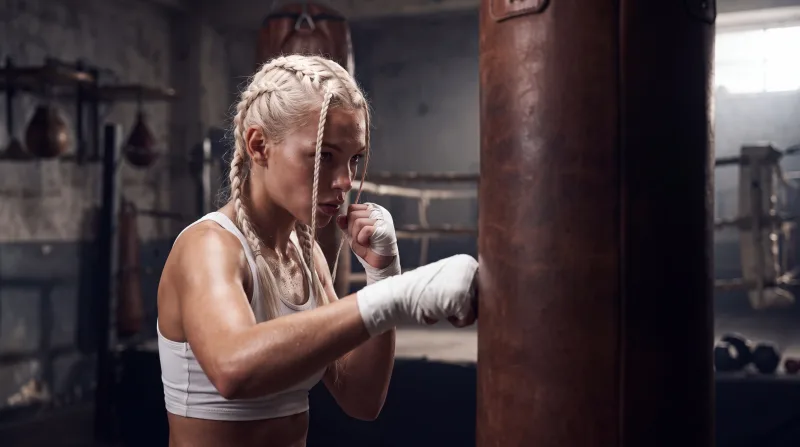
Minimax H3 Image To Video
MiniMax H3 Open Weights Image to Video animates a first-frame image, optionally with last-frame guidance, into coherent 480P / 540P / 768P videos with native stereo audio, 5-15 second duration, flexible aspect ratios, and per-second billing. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedream v5.0 Pro Layer Decomposition
Seedream V5.0 Pro Layer Decomposition separates a single image into a base image and transparent layers, enabling flexible compositing, image editing, asset extraction, and layered design workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
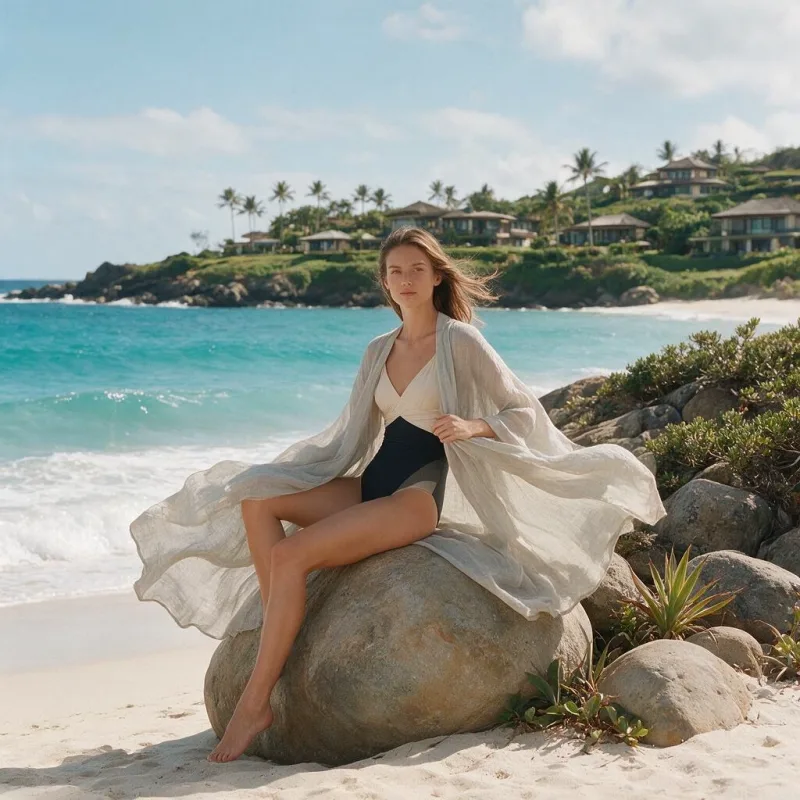
Seedream v5.0 Pro
Seedream V5.0 Pro Text to Image by ByteDance generates high-quality images from text prompts, with aspect ratio selection, strong prompt following, and 1K / 2K output tiers for flexible image creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
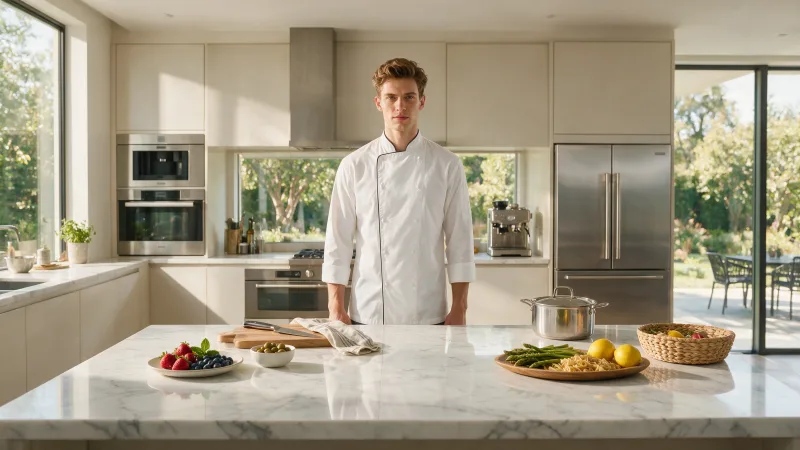
Seedream v5.0 Pro Edit
Seedream V5.0 Pro Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, aspect ratio selection, and 1K / 2K output tiers. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
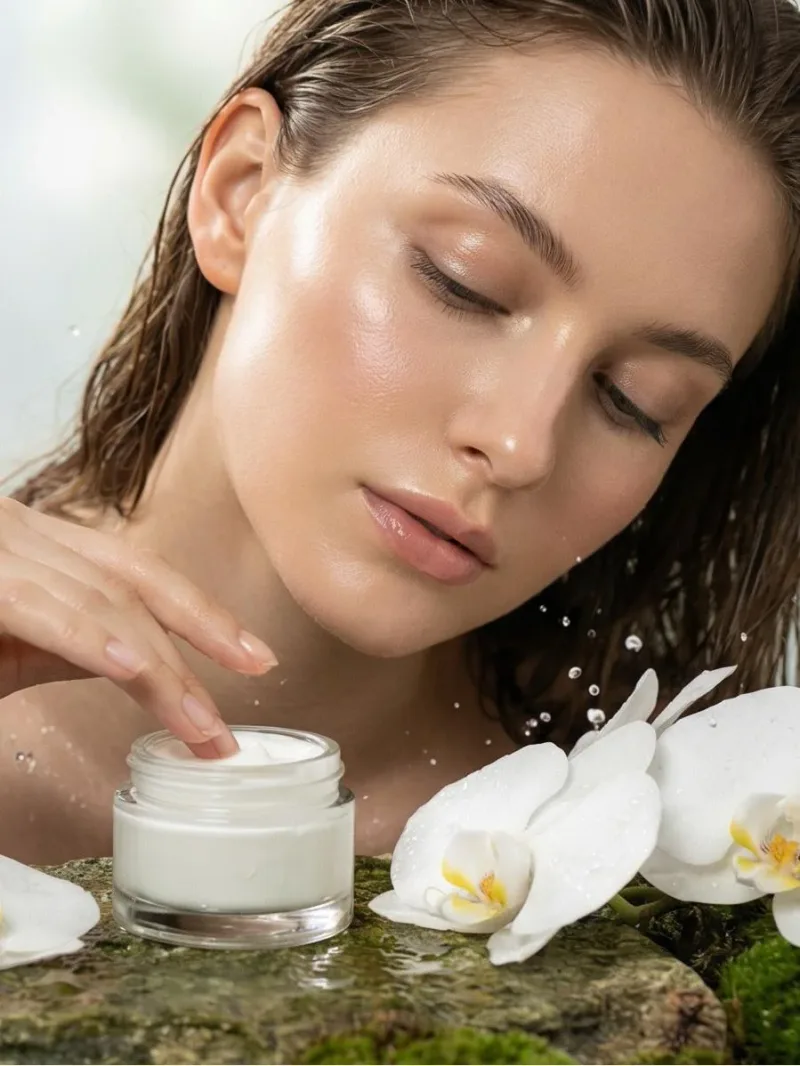
Nano Banana Pro Text To Image Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a next-generation text-to-image model capable of generating multiple high-quality images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
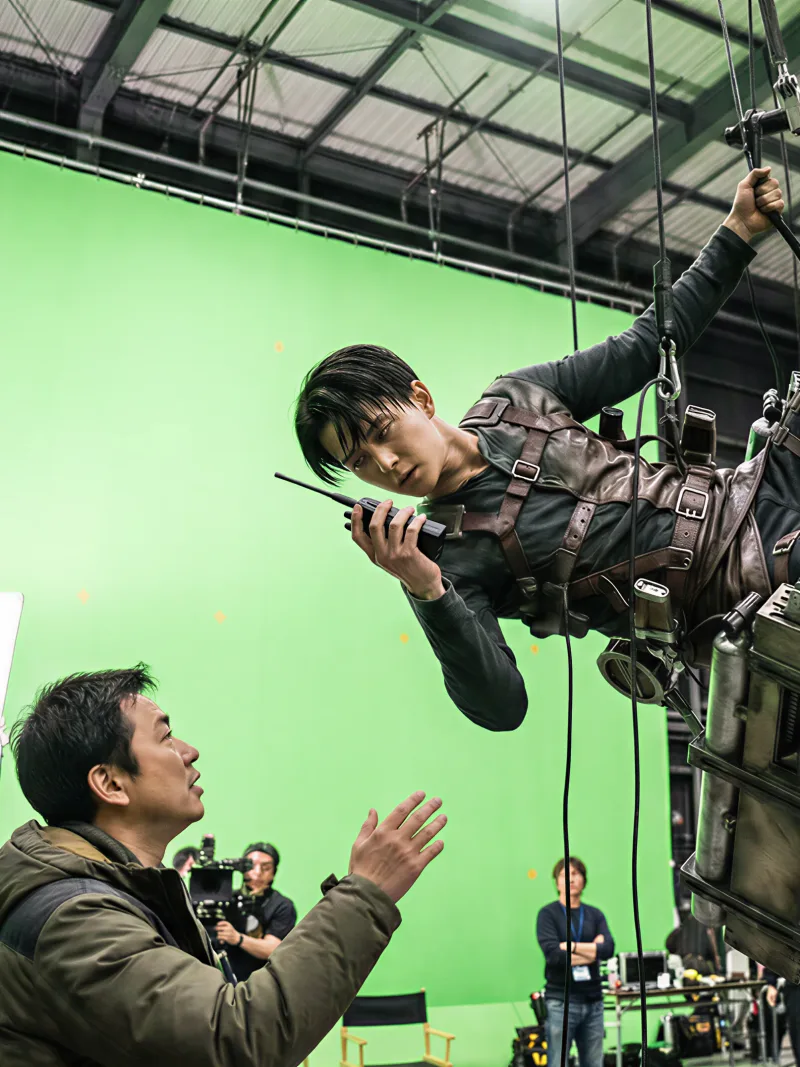
Nano Banana Pro Text To Image Ultra
Google's Nano Banana Pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Text To Image
Google's Nano Banana pro (Gemini 3.0 Pro Image) is a cutting-edge text-to-image model enabling high-res 4K image generation optimized for phones. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Multi
Google's Nano Banana Pro (Gemini 3.0 Pro Image) Edit is a next-generation image editing model capable of generating multiple high-quality edited images in a single run. Extremely low cost — only $0.07 per image. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit Ultra
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with highres output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana Pro Edit
Google Nano Banana Pro (Gemini 3.0 Pro Image) Edit enables image editing with 4K-capable output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image Fast
Google Nano Banana 2 Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 option, starting at just $0.045 per image. Delivers fast text-to-image generation with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Text To Image
Google Nano Banana 2 (Gemini 3.1 Flash Image) delivers Pro-quality image generation at Flash speed with 512px to 4K resolution support. Features include improved text rendering, character consistency for up to 5 characters, and real-world knowledge integration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit Fast
Google Nano Banana 2 Edit Fast (Gemini 3.1 Flash Image) is the cheapest Nano Banana 2 editing option, starting at just $0.045 per image. Enables fast image editing with 2K default output and 4K support. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Nano Banana 2 Edit
Google Nano Banana 2 Edit (Gemini 3.1 Flash Image) enables advanced image editing with 4K-capable output, fast iteration, and precise instruction following. Supports text translation, localization within images, and maintains subject consistency during edits. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gpt Image 2.5 Sunburst Edit
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
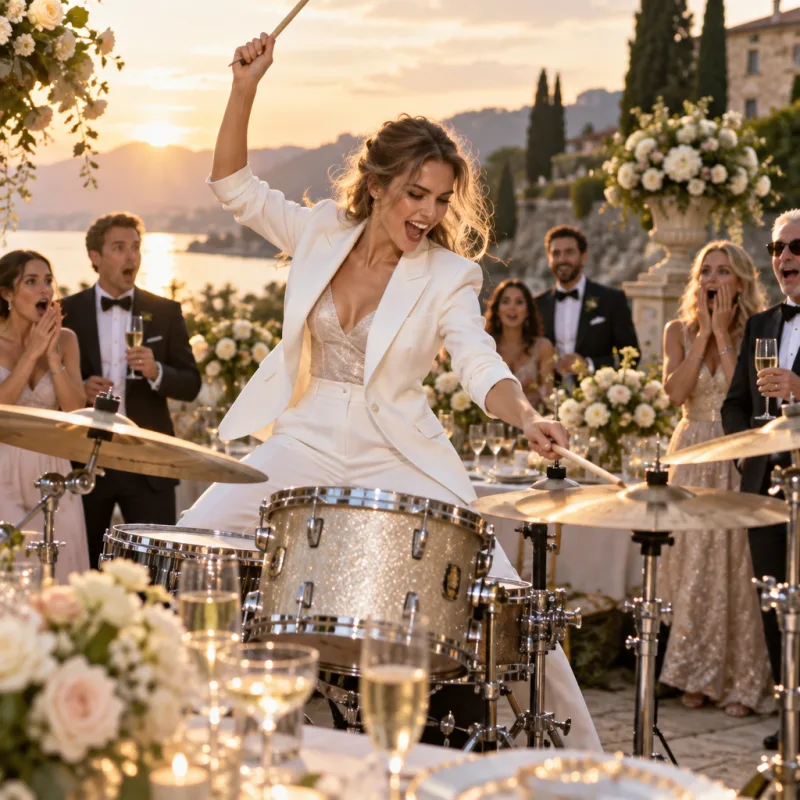
Gpt Image 2.5 Sunburst Text To Image
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
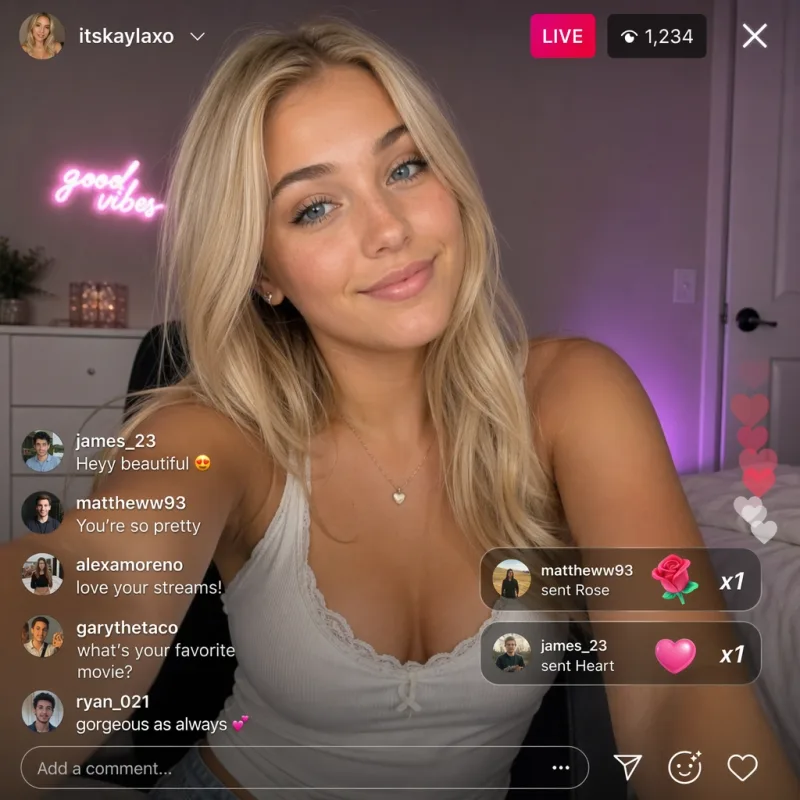
Gpt Image 2 Text To Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
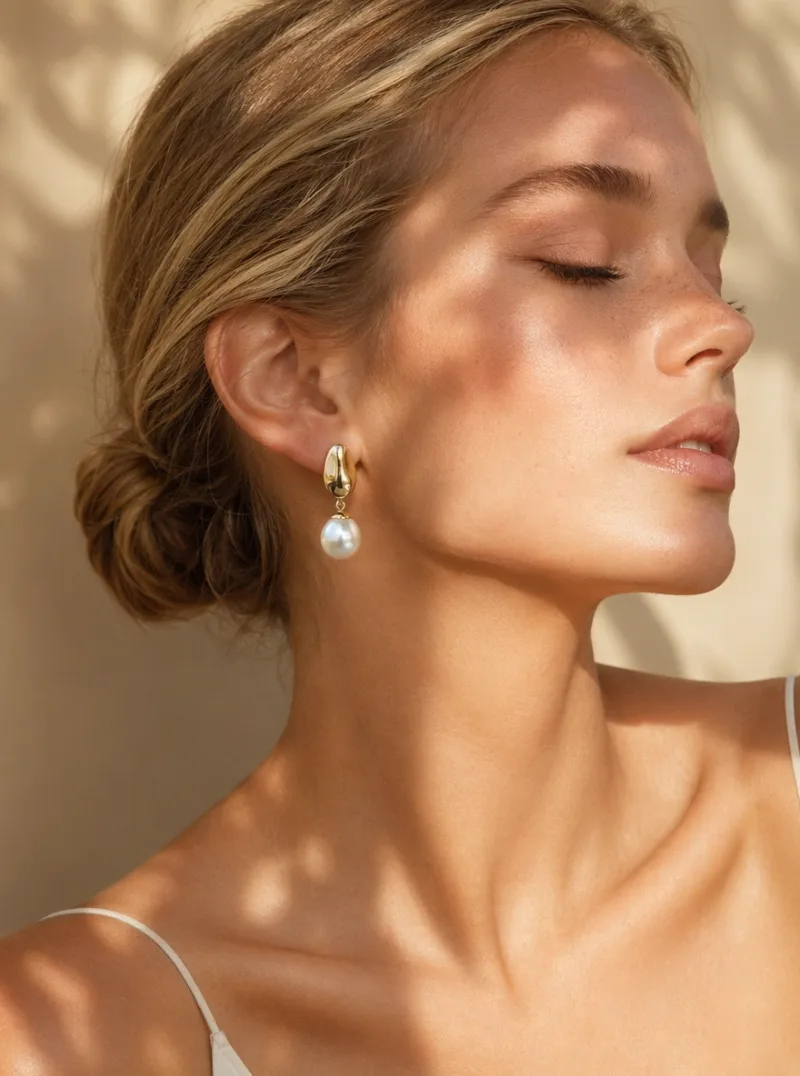
Gpt Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
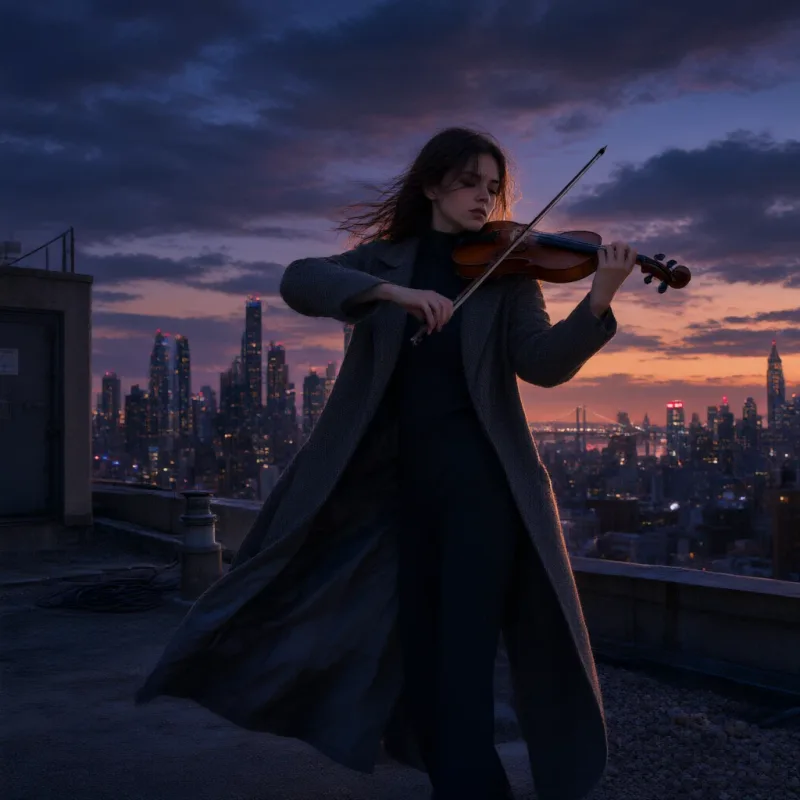
Qwen Image 3.0 Text To Image
Qwen Image 3.0 Text to Image is a high-quality image generation model that creates high-quality images from text prompts, with advanced prompt understanding, strong visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Edit
Qwen Image 3.0 Edit is a high-quality image editing model that transforms existing images with natural-language instructions, delivering advanced instruction understanding, superior visual quality, and up to 2K output for creative and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Beispiele
WaveSpeedAI in Aktion
Echte Ausgaben der WaveSpeedAI-API. Fahren Sie über ein Video für eine Vorschau und klicken Sie, um den Viewer in voller Größe zu öffnen.
Anleitung
So verwenden Sie die WaveSpeedAI-API
Vier Schritte von der Registrierung bis zur fertigen Generierung. Vollständige Beispiele in Python, Node.js und cURL finden Sie unten im Abschnitt „API“.
- 01
API-Schlüssel holen
Registrieren Sie ein WaveSpeedAI-Konto und kopieren Sie Ihren API-Schlüssel aus dem Dashboard. Neue Konten erhalten kostenlose Start-Credits – genug, um den Playground einige Dutzend Mal zu nutzen, bevor die Abrechnung beginnt.
- 02
Prediction senden
Senden Sie Ihre Eingabe als JSON per POST an https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video. Der Endpunkt gibt sofort eine Prediction-ID zurück – Generierungen laufen asynchron, sodass Sie während der Inferenz keine Verbindung offen halten.
- 03
Auf Abschluss prüfen
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result. Geben Sie bei „completed“ die Ausgaben zurück; brechen Sie bei „failed“, „cancelled“, „timeout“ oder „deleted“ mit einem Fehler ab; fragen Sie bei allen anderen Status weiter ab.
- 04
Ausgabe-URL lesen
Sobald der Status „completed“ ist, lesen Sie die URL aus data.outputs[0]. Die URL verweist auf Ihre generierten Medien im WaveSpeedAI-CDN – Bild, Video, Audio oder 3D-Datei, je nach aufgerufener Modellvariante.
Anwendungsfälle
Was Sie mit diesen Modellen bauen können
Gängige Workflows, für die Entwickler und Kreative diese APIs nutzen.
Eine Higgsfield-API-Integration an einem Nachmittag umziehen
Beide APIs arbeiten asynchron: JSON senden, eine Request-ID erhalten, dann abfragen oder einen Webhook nutzen. Auf WaveSpeedAI senden Sie einen POST an /api/v3/<model> mit einem Bearer-API-Schlüssel und lesen das Prediction-Ergebnis – die Portierung besteht also vor allem aus einer anderen Basis-URL, einem anderen Auth-Header und einem anderen Modellpfad.
Bild und Video in einer Pipeline
Erzeugen Sie Standbilder mit Nano Banana Pro, Seedream 5.0 oder GPT Image 2.5 und animieren Sie sie dann mit Seedance 2.5, Kling 3.0 oder Wan 3.0 Image-to-Video – mit einem Schlüssel und einem Guthaben. Der veröffentlichte Katalog der Higgsfield API führt Nano Banana, Seedream und GPT Image nicht auf.
Open-Weights-Modell MiniMax H3 mit LoRA
WaveSpeedAI hostet das Open-Weights-Modell MiniMax H3 mit Text-to-Video, Image-to-Video, Reference-to-Video, Video-Edit und -Extend, LoRA-Endpunkten für eigene Stile und Figuren sowie einem Text-to-Image-Modus.
Lange Einzeleinstellungen und gestuftes Video
Seedance 2.5 rendert Einstellungen bis zu 30 Sekunden mit nativem Audio; Kling 3.0 und Kling O3 gibt es in den Stufen Standard, Pro und 4K; Wan 3.0 ergänzt eine Prime-Stufe. Wählen Sie pro Einstellung aus derselben Integration.
Agenten und Batch-Jobs
Rufen Sie jedes Modell über Python- oder JavaScript-SDKs, reines HTTP, die CLI oder einen MCP-Server auf, sodass Coding-Agenten und Batch-Skripte dieselben Endpunkte und Preise nutzen wie Ihre App.
Tipps
Tipps zum Prompting dieser Modelle
Praktische Ratschläge für bessere Ausgaben dieser Modelle – abgeleitet aus Mustern, die bei Video-Modellen in Produktions-Pipelines funktionieren.
- 01
Kamerabewegungen konkret benennen
Nennen Sie konkrete Kamera-Begriffe – Orbit, Dolly-in, Push-in, Pan-left, Kranfahrt, Handkamera-Verfolgung. Allgemeine Prompts führen zu statischen oder beliebigen Kameraentscheidungen; benannte Kamerabewegungen entsprechen direkt der Bewegungsabsicht in den Trainingsdaten des Modells und verbessern die Qualität der Einstellung erheblich.
- 02
Charakteridentität mit Referenzbildern verankern
Wenn Ihr Prompt von einer bestimmten Person, Figur oder einem Produkt abhängt, laden Sie zusätzlich zum Prompt ein Referenzbild hoch. Ohne Referenz driftet die Identität über Bilder und Einstellungen hinweg – dieselbe Figur sieht bei jeder Generierung wie eine etwas andere Person aus.
- 03
Licht und Tageszeit beschreiben
Lichthinweise wie „goldene Stunde, weiches warmes Richtungslicht“ oder „bedecktes diffuses Licht, schiefergrauer Himmel“ verbessern Qualität und Konsistenz weit stärker als vage Qualitätszusätze. Licht gehört zu den stärksten Priors, auf die das Modell konditioniert.
- 04
Negative Prompts nutzen, um häufige Fehlerbilder zu unterdrücken
Nützliche Negativ-Angaben für Video: „frame flicker, motion blur, watermark, text artifacts, distorted hands, low resolution, jpeg compression“. Negative Prompts kosten nichts und senken spürbar den Anteil der Generierungen, die Sie sonst neu würfeln würden.
- 05
Die kürzeste Dauer wählen, die Ihren Beat trägt
Die meisten Prompts funktionieren am besten bei 5–8 Sekunden. Längere Clips verstärken zeitliche Inkonsistenzen (Motiv verändert sich, Umgebung driftet). Wenn Sie eine Sequenz von 20 Sekunden brauchen, erzeugen Sie drei Clips von 6–8 Sekunden und schneiden Sie sie zusammen – die Qualität bleibt höher als bei einer langen Generierung.
- 06
Das Seitenverhältnis von Anfang an an die Plattform anpassen
9:16 für TikTok / Reels / Shorts, 16:9 für Querformat-Feeds und YouTube, 1:1 für Post-Raster. Modelle trainieren je Seitenverhältnis leicht unterschiedlich – ein nachträgliches Zuschneiden von 16:9 auf 9:16 kostet sowohl Detailtreue als auch die Komposition, die das Modell vorgesehen hatte.
Preise
WaveSpeedAI-API-Preise
Die Abrechnung erfolgt pro Ausgabe. Der Endpreis richtet sich nach den Parametern, die Sie im Playground jeder Variante setzen (Auflösung, Dauer, Anzahl der Ausgaben, Referenzen).
API
Die WaveSpeedAI-API aufrufen
Holen Sie sich unter wavespeed.ai/accesskey einen API-Schlüssel und senden Sie dann eine Prediction per REST. Der Playground erzeugt einfügefertige Beispiele für jede Kombination von Eingaben.
POSThttps://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "aspect_ratio": "16:9",
    "resolution": "720p",
    "duration": 5,
    "generate_audio": true
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": true
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"aspect_ratio": "16:9",
"resolution": "720p",
"duration": 5,
"generate_audio": True
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)Vergleich
WaveSpeedAI im Vergleich zu Higgsfield API
Worin sich WaveSpeedAI und Higgsfield API unterscheiden.
WaveSpeedAI vs. Higgsfield API: models
Die Higgsfield API listet 82 Bild- und Videoeinträge, darunter die eigenen Modelle Soul und Cinema Studio sowie Seedance, Kling, Wan, MiniMax und Qwen Image. WaveSpeedAI deckt diese Drittanbieter-Familien ab und ergänzt Nano Banana, Seedream, GPT Image, Veo, Audio, 3D und Sprachmodelle: insgesamt über 1.000.
WaveSpeedAI vs. Higgsfield API: credits
Guthaben der Higgsfield API verfällt ein Jahr nach dem Kauf. WaveSpeedAI-Credits verfallen nie, und es gibt weder Mitgliedschaft noch Abonnement: Laden Sie auf, wenn Sie es brauchen, und zahlen Sie pro Anfrage – der Preis jedes Endpunkts steht auf seiner Modellseite und in der Preistabelle auf dieser Seite. Dieselben Credits bezahlen auch die Studios im Browser.
WaveSpeedAI vs. Higgsfield API: open models
Beide listen MiniMax H3. Auf WaveSpeedAI ist es das von WaveSpeedAI gehostete Open-Weights-Modell, mit Endpunkten für LoRA, Reference-to-Video, Bearbeitung, Verlängerung und Bild neben dem üblichen Text-to-Video und Image-to-Video.
FAQ
Higgsfield API Alternative — Häufig gestellte Fragen
Modelle, Preise, Migration – häufige Fragen zum Wechsel von Higgsfield API zu WaveSpeedAI.
Ist WaveSpeedAI eine Alternative zur Higgsfield API?
Ja. WaveSpeedAI stellt Seedance 2.5 und 2.0, Kling 3.0 und O3, Wan 3.0, MiniMax H3 und Qwen Image 3.0 als REST-Endpunkte bereit, dazu Seedream 5.0, Nano Banana 2 und Pro sowie GPT Image 2.5 und 2 – mit einem API-Schlüssel und Abrechnung pro Anfrage.
Welche Modelle kann ich aufrufen, die die Higgsfield API nicht listet?
Der veröffentlichte Modellkatalog der Higgsfield API enthält weder Nano Banana, Seedream, GPT Image, Veo noch Audiomodelle. Auf WaveSpeedAI stehen Nano Banana 2 und Pro, Seedream 5.0, GPT Image 2.5 und 2, Veo 3.1 und ElevenLabs-Stimmen hinter demselben Schlüssel wie die Videomodelle.
Wie wechsle ich von der Higgsfield API?
Erstellen Sie unter /accesskey einen Schlüssel und senden Sie Ihre Eingabe als JSON per POST an https://api.wavespeed.ai/api/v3/<model> mit einem Authorization: Bearer-Header. Sie erhalten eine Prediction-ID zurück; fragen Sie https://api.wavespeed.ai/api/v3/predictions/<id>/result ab oder übergeben Sie einen Webhook. Ordnen Sie jedes Modell anhand der Endpunktliste auf dieser Seite seinem WaveSpeedAI-Pfad zu.
Ist MiniMax H3 auf WaveSpeedAI das Open-Weights-Modell?
Ja. Die Endpunkte wavespeed-ai/minimax-h3 betreiben auf WaveSpeedAI das Open-Weights-Modell MiniMax H3, einschließlich LoRA-Varianten für eigene Stile und Figuren, Reference-to-Video, Video-Edit und -Extend sowie einem Text-to-Image-Modus.
Brauche ich eine Mitgliedschaft oder ein Abonnement, und verfallen Credits?
Keine Mitgliedschaft und kein Abonnement. WaveSpeedAI ist nutzungsbasiert: Laden Sie Credits auf, wenn Sie sie brauchen, und zahlen Sie pro Anfrage zu dem Preis, der auf jeder Modellseite und in der Preistabelle oben steht. Credits verfallen nie. Berechtigte neue Konten erhalten kostenlose Start-Credits.
Wie rufe ich diese APIs auf?
Registrieren Sie ein WaveSpeedAI-Konto, kopieren Sie Ihren API-Schlüssel von /accesskey und senden Sie Ihre Eingabe als JSON per POST an https://api.wavespeed.ai/api/v3/<model>, zum Beispiel https://api.wavespeed.ai/api/v3/bytedance/seedance-2.5/text-to-video. Der Endpunkt gibt eine Prediction-ID zurück. Fragen Sie den Ergebnis-Endpunkt ab oder übergeben Sie einen Webhook. Beispiele in Python / Node.js / cURL finden Sie oben.
Was kosten diese APIs?
Die Endpunkte auf dieser Seite beginnen bei $0.02 pro Aufruf; der Preis jedes Modells steht in der Preistabelle oben und auf seiner Modellseite. Die genauen Kosten richten sich nach den Parametern, die Sie setzen (Auflösung, Dauer, Anzahl der Ausgaben, Referenzen), und der Playground zeigt sie vor dem Absenden an.
Starten Sie auf WaveSpeedAI
Kostenlose Start-Credits bei der Registrierung. Ein API-Schlüssel für über 1.000 KI-Modelle aller großen Anbieter.