Batch Generation on WaveSpeed: Run 1,000+ Image Requests Daily with Confidence
Production guide to batch image generation on WaveSpeed. Master queues, retries, concurrency and monitoring to run 1,000+ requests daily without failures.
Hello, folks! I’m Dora. This started with a small annoyance: I needed a few hundred variant images for a test, and my usual single-request loop felt like pushing a grocery cart with a stuck wheel. I kept hearing that Batch Generation on WaveSpeed could handle volume. I didn’t need fireworks. I just wanted the work to feel lighter.
So over a few sessions in late December and again this week, I set up a simple batch pipeline on WaveSpeed and asked it to run more than 1,000 image requests. No heroics, just steady throughput, clear states, and clean retries. Below is the shape that worked for me, the parts that got in the way, and the small choices that kept costs and errors from drifting up while my attention was elsewhere.
Batch Architecture Overview
Producer / Queue / Worker / Storage
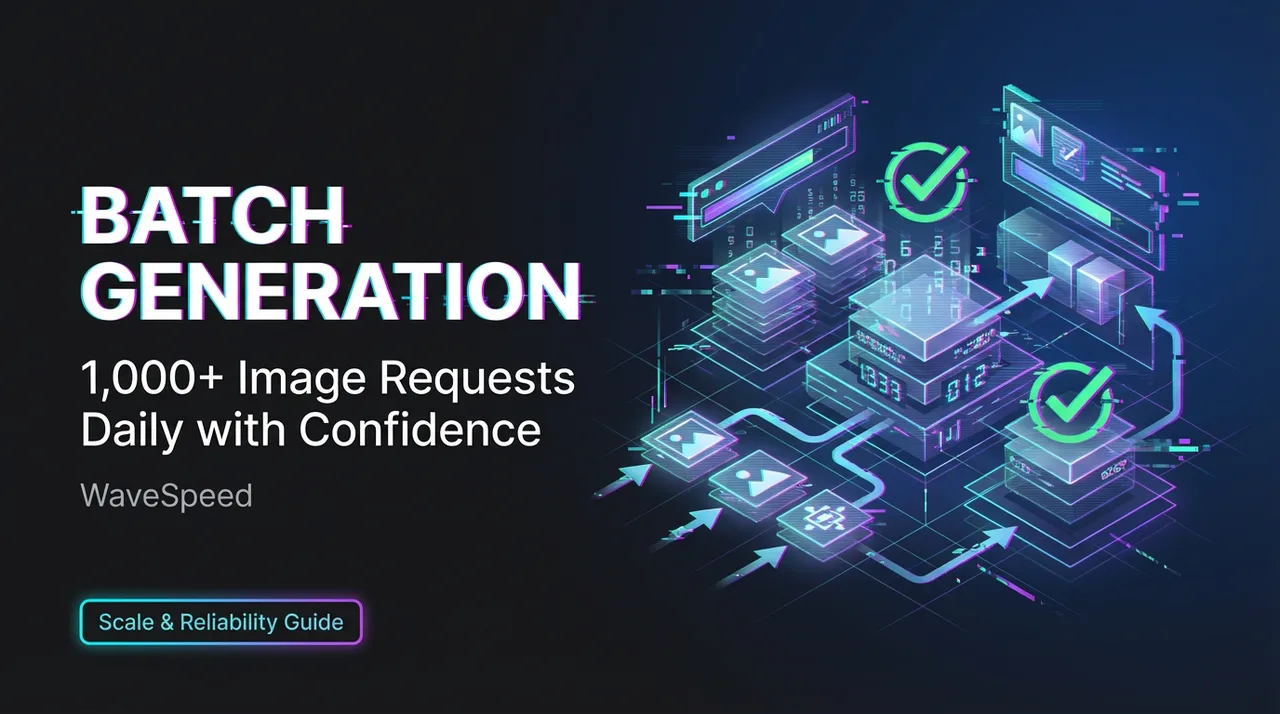
I kept the pieces boring on purpose. A small producer script collects prompts and metadata, a queue holds jobs, stateless workers call the WaveSpeed image API, and storage takes the results. Each part can fail without taking the whole system down.
- Producer: Reads a CSV of prompts and per-image settings (model, size, seed). It writes a job per row into the queue with a stable job ID (a hash of the inputs).
- Queue: I used Redis Streams once and RabbitMQ once. Both worked. If you don’t already run either, Redis is lighter to start with.
- Workers: Containerized processes that pull jobs, call WaveSpeed, write results to object storage (I used S3), and update status. They’re stateless so scaling is a knob, not a rebuild.
- Storage: One bucket for images, one for JSON metadata. Simple folders by date and batch ID keep it tidy.
What surprised me was how little code changed when I scaled from 100 to 1,200 images; most issues were about pacing and guarding against duplicates, not throughput.
Simple Architecture Diagram
Here’s the picture I kept in my head:
Producer → Queue → Workers → WaveSpeed API → Storage
             ↓                      ↑
State DB ←────────→ Metrics/Alerts- The State DB can be the same Redis or a lightweight Postgres table.
- Metrics feed alerts when error rates or costs go weird.
It’s not clever. That’s the point. When the API returns intermittent 429/5xx, the queue soaks it. When a worker dies mid-run, another one picks it up after visibility timeout.
Concurrency Strategy
Safe parallelism levels
On my runs, I started with 5 workers, each doing 2 in-flight requests. That gave me a steady 8–10 images/minute without tripping limits. Bumping to 20 concurrent requests worked briefly, then I saw retries spike. The best setting wasn’t the fastest peak, it was the flattest average.
If you’re trying this: find the smallest number of workers that keeps your queue from growing. Then inch up. Watch p95 latency and error rates for 10–15 minutes before touching anything.
Rate limit awareness
WaveSpeed publishes rate limit guidance in the docs, but limits still vary with model and account. I added two guardrails:
- Client-side token bucket: Each worker acquires a token before calling the API. Tokens refill at the plan’s effective RPS. When I changed models, I adjusted the refill.
- Backoff discipline: A 429 on submit, and transient 429/5xx responses while polling, trigger exponential backoff with jitter, capped at 30 seconds (honor
Retry-Afterwhen present). This prevented stampedes after short outages.
I also tagged each job with model + size so I could set separate concurrency ceilings per model when needed. It’s not fancy, just a small switch statement, but it helped avoid localized hot spots.
Retry & Idempotency
Avoiding duplicate images
My first batch had a quiet bug: a worker crashed after the API call returned, before it wrote to storage. The queue retried the job and I ended up paying for two identical generations. Not fun.
To stop this, I split each job into two steps: submit the task, then wait for it. The submit POST creates a task (and a charge), so the worker saves the returned task ID on the job row immediately. If a job is picked up again and already has a task ID, the worker skips the submit and only polls that task. I also made the storage path deterministic from the job ID, so if a retry finds the image already written, it short-circuits and just marks the job as success. Cheap fix, big relief.
Idempotency key implementation
I used a SHA-256 of the normalized prompt + model + seed + size + guidance. That hash becomes:
- the job ID in the queue
- the storage filename prefix
- the database primary key for the job
This key is my own bookkeeping, not an API feature. WaveSpeed does not de-duplicate submit requests for you: two submit calls create two tasks, and you pay for both. The task ID saved on the job row and the storage-first check are what prevent paying twice.
Failed job recovery
Not every failure deserves another try, and submitting and polling follow different rules:
- Submit: send it once. Retry only when the request was clearly rejected before a task existed, such as a 429 (back off, then send it again). Never retry a 5xx, a timeout, or a dropped connection: the task may already exist. Mark the job
needs_checkinstead and look in History in your WaveSpeed dashboard before deciding to resubmit. - Poll: tolerate transient 429, 500, 502, 503, 504 and network errors with backoff (honor
Retry-After), then keep polling until the task is completed, failed, cancelled, timeout, or deleted. - Don’t retry: 4xx with validation errors, missing params, or obviously bad input
I cap submit retries after a 429 at 5 with exponential backoff. After that, the job lands in a dead-letter queue with the error payload. Once per day, I triage DLQ jobs: some get fixed input and requeued, others are archived with a note. Jobs in needs_check are resolved by hand, and every logged error includes the task ID when there is one. This kept my overall failure rate under 1.5% for a 1,200-image run.
Job State Management
Status: pending/running/success/failed
I tried a few state shapes. The simplest stuck:
- pending: queued, not yet leased by a worker
- running: leased by a worker with a lease expiry
- success: image and metadata written, checks passed
- failed: terminal, with error code, task ID, and last attempt timestamp
- needs_check: the submit outcome is unknown (5xx, timeout, no response), so a task may exist; waits for a manual look
I added a task_id field, which is what makes resuming safe, plus two optional fields that paid off: attempt_count and last_response_code. They made dashboards more legible and debugging less guessy.
Job timeout handling
Two timeouts matter:
- Lease timeout: If a worker dies mid-run, the job should return to pending after N seconds. I used 120s. A re-leased job with a saved task ID resumes polling; one that started a submit but never saved a task ID goes to
needs_check, not to a new submit. - Request timeout: If WaveSpeed doesn’t respond to a single request in N seconds, abort that request. I used 60s per call. For a poll, that is just another transient error to retry. For a submit, it means the outcome is unknown, so the job goes to
needs_check. There is no overall limit on the task itself: some jobs run for a long time, so I keep polling until a terminal status.
When the API is slow, these two can fight. To avoid duplicate work, I only mark running → pending after the lease expires and a worker’s heartbeat stops. Heartbeats were just a Redis hash update every 10 seconds. If the heartbeat is fresh, I extend the lease.
Monitoring & Alerts
Error rate tracking
I watched three numbers during runs:
error_rate_5m: rolling 5-minute proportion of failed attemptsp95_latency: per-model, per-sizeretry_depth: how many jobs are on attempt ≥ 2
If error_rate_5m > 5% for 10 minutes, I cut concurrency in half automatically and send myself a note. Most spikes settled within five minutes without manual fiddling.
Cost spike alerts
Costs can creep. I recorded:
- cost_per_image: reported by WaveSpeed if available, else estimated from plan
- duplicate_prevented: count of jobs resumed from a saved task ID or short-circuited by the storage check
- total_estimated_cost: cumulative
When cost_per_image jumped by more than 30% against the last hour’s average, I paused new job intake and let the queue drain. Twice, this caught unintentional parameter changes (bigger sizes, different model) before the bill drifted. Quiet guardrails like this are worth their few lines of code.
Reference Implementation
Python pseudo code
Below is the shape I used. It’s not full code, just the bones:
# producer.py
for row in csv_rows:
    key = hash_inputs(row)  # stable job ID
    queue.push({"id": key, "inputs": row})

# worker.py
while True:
    job = queue.lease(timeout=120)
    if not job:
        sleep(1)
        continue
    try:
        record_heartbeat(job.id)

        # Step 1: submit once. A saved task ID means the submit already happened.
        if not job.task_id:
            job.task_id = submit_once(job)
            save_task_id(job.id, job.task_id)

        # Step 2: poll until a terminal status.
        resp = poll_until_terminal(job.task_id)

        path = storage_path(job.id, job.inputs)
        if not storage.exists(path):
            storage.write(path, resp.image)
            storage.write(path + ".json", resp.metadata)
        mark_success(job.id)
    except SubmitUnconfirmed as e:  # 5xx, timeout, dropped connection: a task may exist
        mark_needs_check(job.id, e)  # do NOT resubmit
    except Fatal as e:  # rejected input, failed/cancelled task, 429s exhausted
        mark_failed(job.id, e, task_id=job.task_id)
    finally:
        queue.release(job)


def submit_once(job):
    for attempt in range(5):
        try:
            return wavespeed.submit(job.model, job.inputs, timeout=60).task_id  # one POST
        except RateLimited as e:  # 429: rejected, no task was created
            backoff_sleep(attempt, e.retry_after)
        # 5xx / timeout / no response raises SubmitUnconfirmed and is never retried
    raise Fatal("rate limited on submit")


def poll_until_terminal(task_id):
    attempt = 0
    while True:
        try:
            r = wavespeed.get_result(task_id, timeout=60)
        except TransientError as e:  # 429/500/502/503/504 or network error
            attempt += 1
            backoff_sleep(attempt, e.retry_after)
            continue
        if r.status == "completed":
            return r
        if r.status in ("failed", "cancelled", "timeout", "deleted"):
            raise Fatal(f"task {task_id} {r.status}: {r.error}")
        sleep(3)
Node.js pseudo code
// producer.mjs
for (const row of rows) {
    const key = hashInputs(row); // stable job ID
    queue.push({ id: key, inputs: row });
}

// worker.mjs
async function submitOnce(job) {
    for (let attempt = 0; attempt < 5; attempt++) {
        try {
            const resp = await wavespeed.submit(job.model, job.inputs, { timeout: 60000 }); // one POST
            return resp.taskId;
        } catch (e) {
            // 5xx / timeout / no response is a SubmitUnconfirmed error: never retried
            if (!(e instanceof RateLimited)) throw e;
            await backoffSleep(attempt, e.retryAfter); // 429: rejected, no task was created
        }
    }
    throw new Fatal("rate limited on submit");
}

async function pollUntilTerminal(taskId) {
    let attempt = 0;
    while (true) {
        let r;
        try {
            r = await wavespeed.getResult(taskId, { timeout: 60000 });
        } catch (e) {
            if (!(e instanceof TransientError)) throw e; // 429/500/502/503/504 or network error
            await backoffSleep(++attempt, e.retryAfter);
            continue;
        }
        if (r.status === "completed") return r;
        if (["failed", "cancelled", "timeout", "deleted"].includes(r.status)) {
            throw new Fatal(`task ${taskId} ${r.status}: ${r.error}`);
        }
        await delay(3000);
    }
}

while (true) {
    const job = await queue.lease(120); // lease timeout in seconds
    if (!job) {
        await delay(1000);
        continue;
    }

    try {
        await heartbeat(job.id);

        // A saved task ID means the submit already happened.
        if (!job.taskId) {
            job.taskId = await submitOnce(job);
            await saveTaskId(job.id, job.taskId);
        }

        const resp = await pollUntilTerminal(job.taskId);

        const path = makePath(job.id, job.inputs);
        if (!(await storage.exists(path))) {
            await storage.write(path, resp.image);
            await storage.write(path + '.json', resp.metadata);
        }

        await markSuccess(job.id);
    } catch (e) {
        if (e instanceof SubmitUnconfirmed) {
            await markNeedsCheck(job.id, e); // a task may exist: do NOT resubmit
        } else {
            await markFailed(job.id, e, job.taskId);
        }
    } finally {
        await queue.release(job);
    }
}
Config Recommendations
- Start small: 5–10 concurrent requests, then sneak up. Watch
p95anderror_rate_5m, not just throughput. - Separate configs per model: concurrency, timeout, and cost expectations change with model and size.
- Duplicate protection everywhere: a stable job ID, the task ID saved right after submit, a deterministic storage path, and a job table keyed by the same value.
- Heartbeats and leases: they sound fussy, but they save you from phantom duplicates.
- Simple dashboards: 6–8 panels are enough — queue length, successes/min, errors/min, p95, retry depth, and cost.
If you’re already running batch jobs elsewhere, this will feel familiar. WaveSpeed didn’t require a rethink, just a few careful guardrails. That’s what I wanted.
One last note from my runs: the smoothest batches were the ones I barely watched. Not because it was “set and forget,” but because the system told me when it needed attention and stayed quiet when it didn’t. That feels like the right kind of speed.
What about you? Have you been batch processing images with WaveSpeed lately? What’s your sweet spot for concurrency (I’m consistently around 8–10 right now)? Or have you run into any sneaky bugs (like duplicate charges)? Feel free to share your setup, pitfalls, or tips in the comments!