Luma API
Luma API on WaveSpeedAI — Ray 3.2 text-to-video, image-to-video, video edit and video reframing, earlier Ray 2 and Ray 1.6 models, and Uni v1 and Photon image generation and editing, all through one REST API.
Use Luma's Ray 3.2 for cinematic text-to-video and image-to-video with controllable aspect ratio, resolution and duration, re-render or reframe existing footage with video edit and video reframing, and generate or edit images with Uni v1 and Photon. Ray 2 and Ray 1.6 stay available for earlier workflows.
概览
关于 Luma API
Luma 能做什么、它在 Luma AI 模型阵容中的定位,以及团队选择它的原因。
Luma 是 Luma AI 推出的视频生成模型,可通过 WaveSpeedAI REST API 使用。Luma API on WaveSpeedAI — Ray 3.2 text-to-video, image-to-video, video edit and video reframing, earlier Ray 2 and Ray 1.6 models, and Uni v1 and Photon image generation and editing, all through one REST API.
Use Luma's Ray 3.2 for cinematic text-to-video and image-to-video with controllable aspect ratio, resolution and duration, re-render or reframe existing footage with video edit and video reframing, and generate or edit images with Uni v1 and Photon. Ray 2 and Ray 1.6 stay available for earlier workflows.
WaveSpeedAI 上的 Luma 系列提供 6 个 REST 端点,涵盖 Video-To-Video, Image-To-Video, Text-To-Video, Image-To-Image, Text-To-Image 个工作流。每个变体都有各自的定价、参数选项和示例输出——请选择与你的输入模态和生产约束相匹配的那一个,或使用同一个 API 密钥调用多个变体,组合成多步骤流水线。
使用与 WaveSpeedAI 上其他 1,000 多个 AI 模型相同的 API 密钥、账单账户和速率限制来运行 Luma。无需单独对接供应商,无需各家 SDK,也无需应对各家不同的速率限制——一次集成即可覆盖从文生图、文生视频到音频合成、3D 生成、放大和编辑的全部能力。
端点
全部 Luma API 端点
WaveSpeedAI 现已提供 6 个 Luma 端点——请选择适合你工作流的变体。
Ray 3.2 Video Edit
Luma Ray 3.2 Video Edit is a fast AI video-to-video editing model that re-renders an existing source video from a text prompt while preserving the original motion and timing. Ready-to-use REST inference API for video restyling, creative edits, product videos, advertising creatives, social media clips, visual storytelling, and professional video editing workflows with simple integration, no coldstarts, and affordable pricing.
Ray 3.2 Video Reframing
Luma Ray 3.2 Video Reframing is a fast AI video reframing model that changes an existing video’s aspect ratio and fills the newly exposed canvas from a prompt while preserving the source footage. Ready-to-use REST inference API for aspect ratio conversion, social media resizing, cinematic reframing, video outpainting, creator content, advertising creatives, and professional video editing workflows with simple integration, no coldstarts, and affordable pricing.
Ray 3.2 Image To Video
Luma Ray 3.2 Image to Video is a fast AI image-to-video generation model that animates a source image into cinematic video guided by a text prompt, with controllable aspect ratio, resolution, and duration. Ready-to-use REST inference API for image animation, cinematic clips, product videos, social media content, advertising creatives, visual storytelling, and professional image-to-video workflows with simple integration, no coldstarts, and affordable pricing.
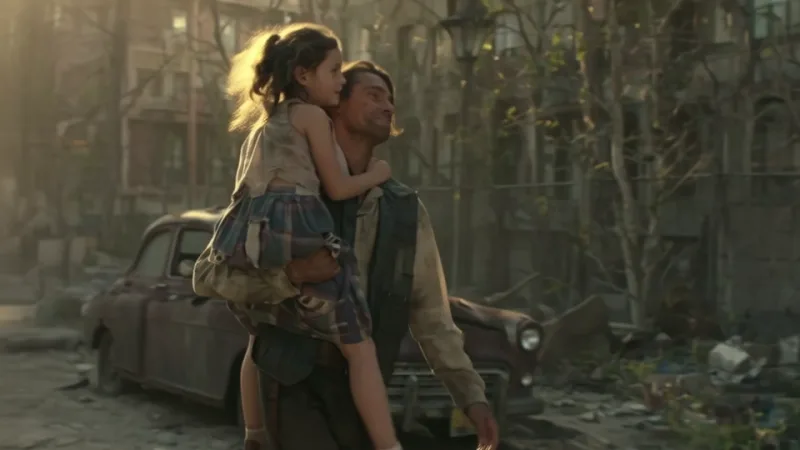
Ray 3.2 Text To Video
Luma Ray 3.2 Text to Video is a fast AI video generation model that creates cinematic videos from text prompts with controllable aspect ratio, resolution, and duration. Ready-to-use REST inference API for cinematic clips, storytelling videos, social media content, advertising creatives, product visuals, concept videos, and professional text-to-video workflows with simple integration, no coldstarts, and affordable pricing.
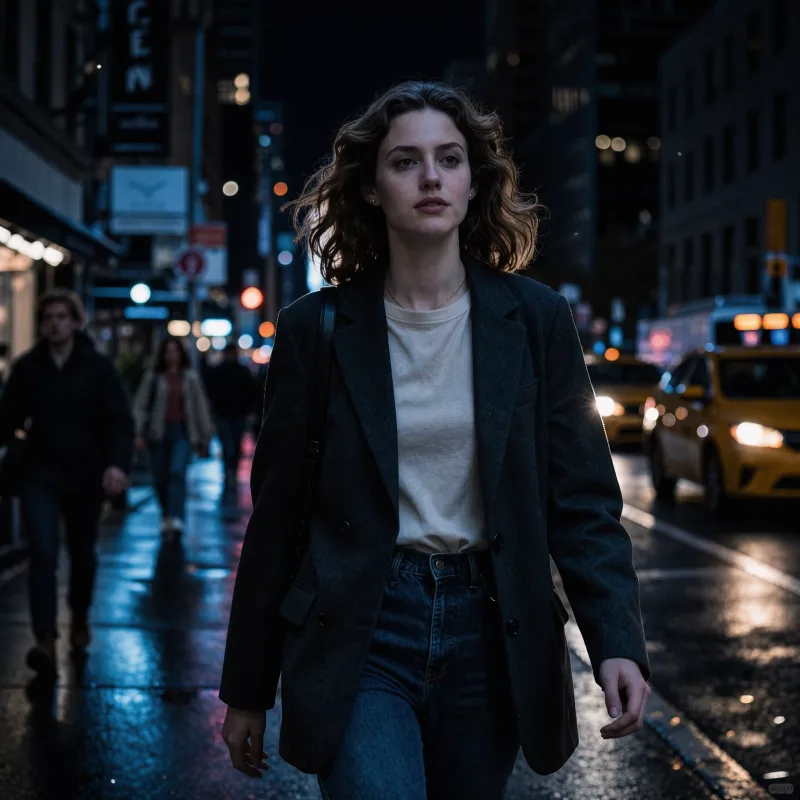
Uni v1 Edit
Luma Uni v1 Edit is a fast AI image editing model that reworks source images from text instructions while preserving composition and supporting optional reference images. Ready-to-use REST inference API for photo editing, product image updates, creative retouching, marketing assets, brand visuals, style changes, and professional image editing workflows with simple integration, no coldstarts, and affordable pricing.
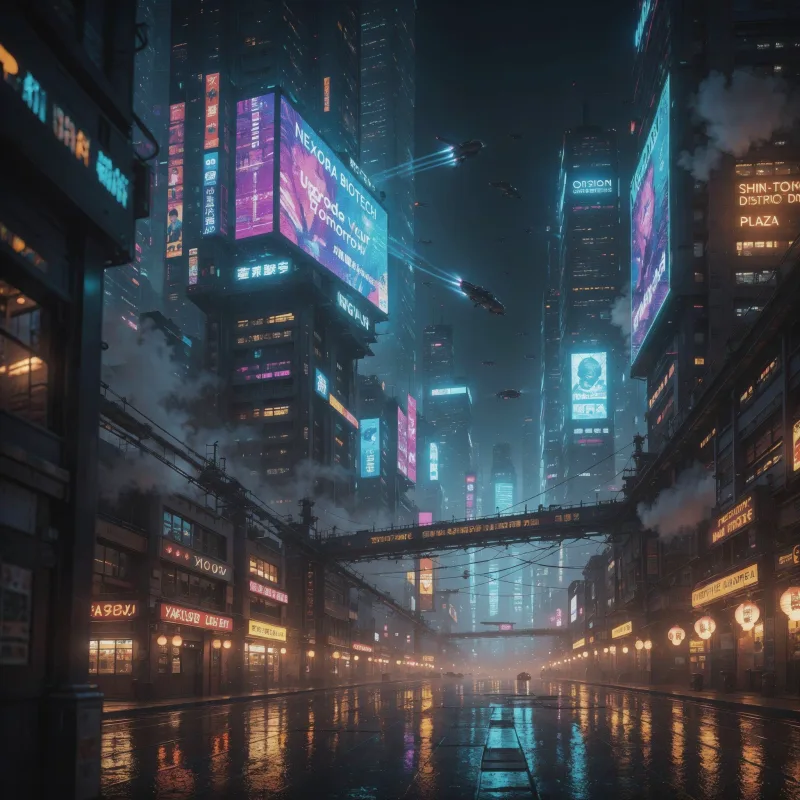
Uni v1 Text To Image
Luma Uni v1 Text to Image is a fast AI image generation model that creates high-fidelity images from prompts with flexible aspect ratios, visual style control, and optional reference-image guidance. Ready-to-use REST inference API for creative design, marketing visuals, product mockups, brand assets, social media content, concept art, and professional text-to-image workflows with simple integration, no coldstarts, and affordable pricing.
示例
看看 Luma 的实际效果
由 Luma API 生成的真实输出。悬停在任意视频上即可预览,点击可打开全尺寸查看器。
使用方法
如何使用 Luma API
从注册到完成一次生成,只需四步。完整的 Python、Node.js 和 cURL 示例见下方的 API 部分。
- 01
获取 API 密钥
注册 WaveSpeedAI 账号,并从控制台复制你的 API 密钥。新账号附带免费体验额度——足够在开始计费前把 Playground 运行几十次。
- 02
提交预测
把你的输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video。端点会立即返回预测 ID——生成是异步的,因此推理期间你无需保持连接。
- 03
轮询完成状态
GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result。状态为 completed 时返回输出;状态为 failed、cancelled、timeout 或 deleted 时以错误终止;其他任何状态都继续轮询。
- 04
读取输出 URL
状态变为 "completed" 后,从 data.outputs[0] 读取 URL。该 URL 指向 WaveSpeedAI CDN 上你生成的媒体——具体是图片、视频、音频还是 3D 文件,取决于你调用的 Luma 变体。
应用场景
用 Luma 可以构建什么
开发者和创作者使用 Luma API 的常见工作流。
Cinematic text-to-video
luma/ray-3.2/text-to-video generates cinematic videos from text prompts with controllable aspect ratio, resolution, duration and optional reference images.
Animate a still image
luma/ray-3.2/image-to-video animates a source image into video guided by a text prompt, with the same aspect ratio, resolution and duration controls.
Restyle footage and keep the motion
luma/ray-3.2/video-edit re-renders an existing source video from a text prompt while preserving the source motion and timing.
Reframe video to a new aspect ratio
luma/ray-3.2/video-reframing changes a video's aspect ratio and fills the newly exposed canvas from a prompt while preserving the source footage.
Image generation and editing
luma/uni-v1/text-to-image generates images with aspect ratio, style, format and reference-image guidance; luma/uni-v1/edit transforms an input image from a text instruction while preserving composition.
技巧
Luma 提示词技巧
让 Luma 输出更好结果的实用建议——总结自生产流水线中各类视频模型都适用的做法。
- 01
明确说明运镜方式
使用具体的摄影术语——orbit、dolly-in、push-in、pan-left、crane shot、handheld follow。笼统的提示词会产生静止或随意的镜头选择;命名的运镜方式能直接对应到模型训练数据中的运动意图,大幅提升镜头质量。
- 02
用参考图像锚定角色身份
如果提示词依赖特定的人物、角色或产品,请在提示词之外上传参考图像。没有参考时,身份会在帧与帧之间、镜头与镜头之间漂移——同一个角色每次生成看起来都像略有不同的人。
- 03
描述光线和时间
「黄金时刻,柔和温暖的定向光」或「阴天漫射光,石板灰的天空」这类光线提示,比含糊的画质修饰词更能提升质量和一致性。光线是模型所依据的最强先验之一。
- 04
用负面提示词抑制常见的失败模式
视频常用的负面提示词:「帧闪烁、运动模糊、水印、文字伪影、变形的手、低分辨率、JPEG 压缩」。负面提示词不花一分钱,却能明显降低您原本需要重新抽取的生成比例。
- 05
选择能涵盖该节拍的最短时长
大多数提示词在 5-8 秒时效果最好。更长的片段会放大时间上的不一致(主体变形、环境漂移)。如果需要 20 秒的序列,请生成三段 6-8 秒的片段再剪辑在一起——质量比一次长生成更高。
- 06
预先让画幅比例匹配平台
TikTok / Reels / Shorts 用 9:16,横屏信息流和 YouTube 用 16:9,帖子宫格用 1:1。模型对每种画幅比例的训练略有不同——事后把 16:9 裁成 9:16,会同时损失保真度和模型原本设计的构图。
定价
Luma API 定价
按输出计费。最终费用会随你在各变体 Playground 中设置的参数(分辨率、时长、输出数量、参考素材)而变化。
| 端点 | 类型 | 起步价 |
|---|---|---|
| luma/ | video-to-video | $0.144 |
| luma/ | video-to-video | $0.06 |
| luma/ | image-to-video | $0.10 |
| luma/ | text-to-video | $0.10 |
| luma/ | image-to-image | $0.042 |
| luma/ | text-to-image | $0.042 |
API
调用 Luma API
在 wavespeed.ai/accesskey 注册并获取 API 密钥,然后通过 REST 提交预测。Playground 可以为任意输入组合生成可直接粘贴的示例代码。
POSThttps://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video
# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d '{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "16:9",
    "resolution": "540p",
    "duration": 5
}')

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
const submitUrl = "https://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');
async function requestJson(url, options = {}) {
const response = await fetch(url, options);
if (!response.ok) throw new Error(await response.text());
return response.json();
}
// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
method: "POST",
headers: {
"Authorization": `Bearer ${apiKey}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"size": "16:9",
"resolution": "540p",
"duration": 5
}),
});
const task = body.data ?? body;
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;
// 2. Poll until the prediction finishes.
while (true) {
const resultBody = await requestJson(resultUrl, {
headers: { "Authorization": `Bearer ${apiKey}` },
});
const result = resultBody.data ?? resultBody;
if (result.status === "completed") {
console.log(result.outputs);
break;
}
if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
await new Promise(resolve => setTimeout(resolve, 2000));
}import json
import os
import time
from urllib.request import Request, urlopen
api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
"prompt": "A cinematic shot of a city at sunset, soft golden light",
"size": "16:9",
"resolution": "540p",
"duration": 5
}
def request_json(url, data=None):
request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
with urlopen(request) as response:
return json.load(response)
# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video", json.dumps(payload).encode())
task = body.get("data", body)
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"
# 2. Poll until the prediction finishes.
while True:
result_body = request_json(result_url)
result = result_body.get("data", result_body)
status = result.get("status")
if status == "completed":
print(result.get("outputs", []))
break
if status in {"failed", "cancelled", "timeout", "deleted"}:
raise RuntimeError(result)
time.sleep(2)对比
Luma 与其他方案对比
在 WaveSpeedAI 上,何时应选择 Luma 而不是同类模型。
Luma 对比 Kling 3.0
Kling 3.0 offers Standard, Pro and 4K tiers with native audio. Luma Ray 3.2 adds video edit and video reframing endpoints for working on existing footage.
Luma 对比 Veo 3.1
Veo 3.1 is Google's video model with synchronized audio. Luma Ray 3.2 is a separate family with optional reference images and footage-level edit and reframing endpoints.
常见问题
Luma API — 常见问题
定价、许可、集成——关于在 WaveSpeedAI 上运行 Luma 的常见问题。
Luma API 是什么?
Luma 是 Luma AI 的视频生成模型,在 WaveSpeedAI 上以 REST API 形式提供。Luma API on WaveSpeedAI — Ray 3.2 text-to-video, image-to-video, video edit and video reframing, earlier Ray 2 and Ray 1.6 models, and Uni v1 and Photon image generation and editing, all through one REST API.你可以通过编程方式调用它,也可以在上方链接的 Playground 中试用。
如何调用 Luma API?
注册 WaveSpeedAI 账号,从 /accesskey 复制你的 API 密钥,然后把输入以 JSON 形式 POST 到 https://api.wavespeed.ai/api/v3/luma/ray-3.2/text-to-video。端点会返回预测 ID。从大约每 2 秒一次开始轮询结果端点,长耗时任务可适当拉长间隔,并在任何终止状态时停止。上方有面向生产环境的 Python / Node.js / cURL 示例。
Luma API 的费用是多少?
Luma $0.042 起。实际费用会随你设置的参数(分辨率、时长、输出数量、参考素材)而变化。Playground 中“生成”按钮旁的实时费用预览会显示你当前输入对应的准确价格。
有哪些 Luma 变体可用?
WaveSpeedAI 托管了 6 个已上线的 Luma 端点:luma/ray-3.2/video-edit, luma/ray-3.2/video-reframing, luma/ray-3.2/image-to-video, luma/ray-3.2/text-to-video, luma/uni-v1/edit, luma/uni-v1/text-to-image。每个变体都有自己的 Playground 页面和定价。
Luma 的输出可以商用吗?
商用权利遵循 Luma AI 的模型许可。大多数 Luma AI 模型允许商用输出;具体许可摘要请查看各模型的 Playground 页面,平台层面的条件请参阅 WaveSpeedAI 的服务条款。
为什么要在 WaveSpeedAI 上使用 Luma,而不是直接对接?
一个 API 密钥、一个账单账户,即可使用 Luma 以及来自其他提供方的 1,000 多个 AI 模型。无需逐家配置 SDK,无需应对各自独立的速率限制,也无需为每家重写集成代码。价格通常与 Luma AI 直接提供的 API 持平或更低。
在 WaveSpeedAI 上用 Luma 开始构建
注册即送免费体验额度。一个 API 密钥,即可使用来自 Luma AI 及其他所有提供方的 1,000 多个 AI 模型。