
Introducing Kuaishou Kling Text To Audio on WaveSpeedAI
Kling Text-to-Audio turns text prompts into custom sound effects for videos, games, and multimedia using KlingAI's audio model. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Introducing Kuaishou Kling V2.6 Pro Image-to-Video on WaveSpeedAI
Kling 2.6 Pro delivers top-tier image-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Introducing Kuaishou Kling V2.6 Pro Motion Control on WaveSpeedAI
Kling 2.6 Pro Motion Control turns reference motion clips (dance, action, gesture) into smooth, realistic animations. Upload a character image (or source video) and a motion video; the model transfers the movement while preserving identity and temporal consistency. Ready-to-use REST API with fast re

Introducing Kuaishou Kling V2.6 Pro Text-to-Video on WaveSpeedAI
Kling 2.6 Pro delivers top-tier text-to-video generation with smooth motion, cinematic visuals, strong prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Introducing Kuaishou Kling V2.1 I2V Pro on WaveSpeedAI
Kling 2.1 Pro converts images to professional cinematic videos with enhanced fidelity, precise camera moves and dynamic motion control. Ready-to-use REST inference API, top performance, no coldstarts, affordable pricing.
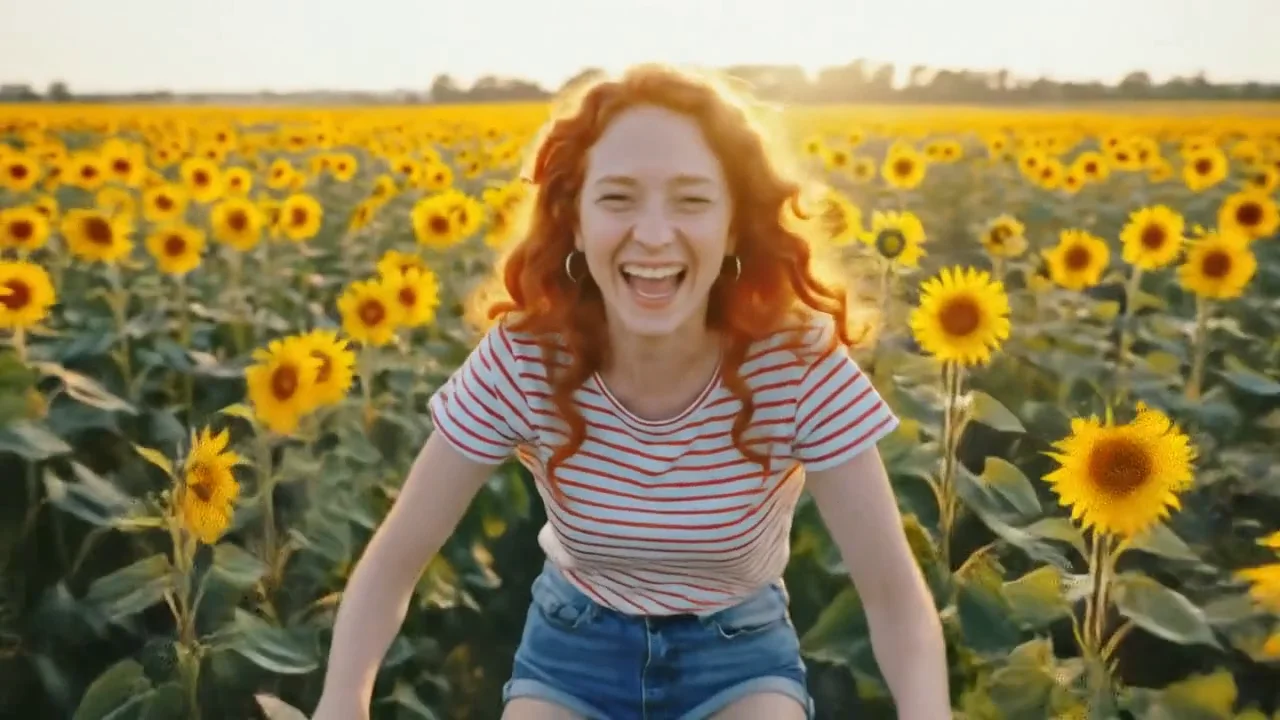
Introducing ByteDance LipSync Audio To Video on WaveSpeedAI
Bytedance LipSync turns audio into lifelike talking videos by generating precise lip movements fully synced to input audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

Introducing ByteDance Seedream V4.5 Sequential on WaveSpeedAI
Seedream 4.5 Sequential generates multi-image sets with consistent characters and objects, unifying palette, lighting, and style across all outputs. Supports up to 4K results for campaigns, storyboards, and product lines. Ready-to-use REST inference API, best performance, no cold starts, affordable
Introducing ByteDance Video Upscaler on WaveSpeedAI
ByteDance Video Upscaler uses AI super-resolution to upscale videos to 4K and recover fine detail in a secure cloud environment. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
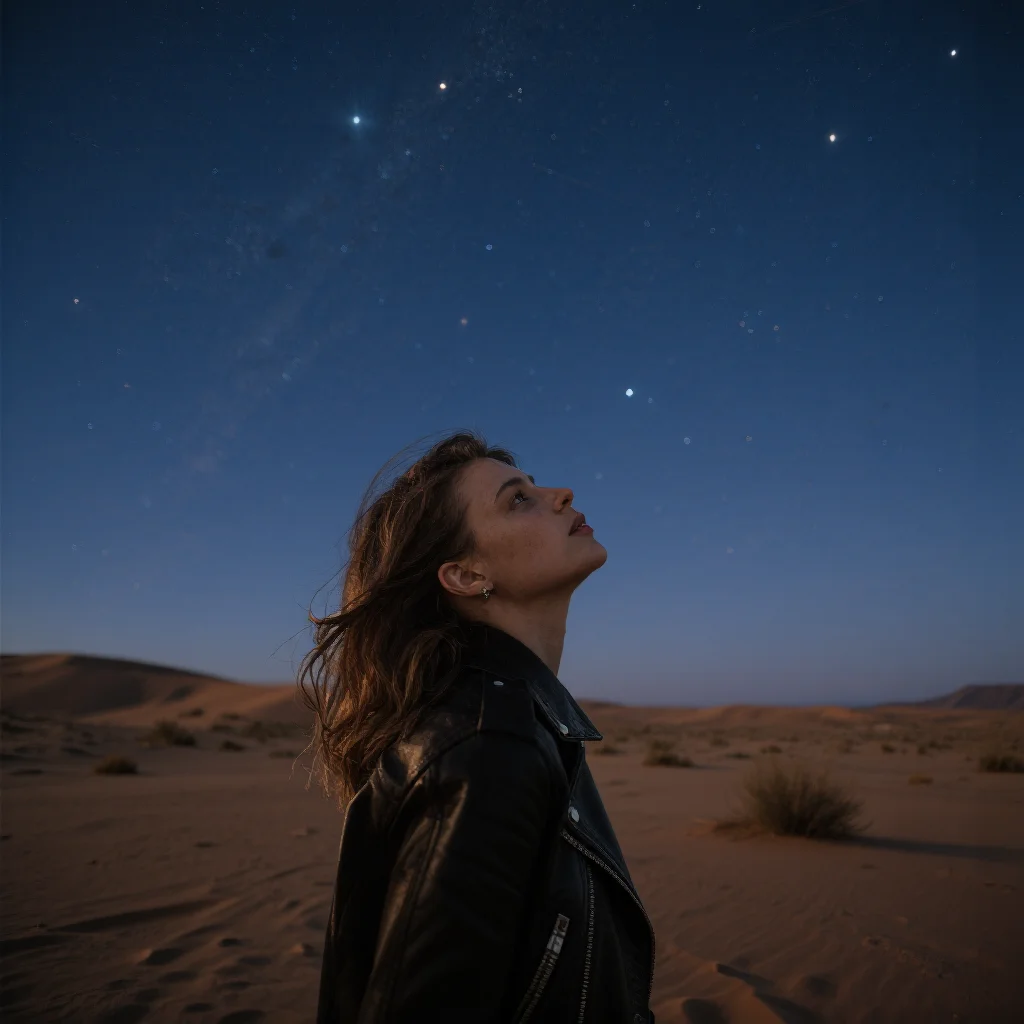
Introducing ByteDance Uso on WaveSpeedAI
USO (Unified Style-Subject Optimized) by ByteDance unifies style-driven and subject-driven generation to produce consistent outputs that blend artistic style with subject fidelity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Introducing ElevenLabs Eleven V3 on WaveSpeedAI
ElevenLabs eleven-v3 is a text-to-speech model available as a hosted endpoint; requests cost $0.1 per 1000 characters. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Introducing ElevenLabs Flash V2.5 on WaveSpeedAI
ElevenLabs Flash V2 is a Text-to-Speech model that converts text into spoken audio using the ElevenLabs Flash V2 engine. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Introducing ElevenLabs Flash V2 on WaveSpeedAI
ElevenLabs Flash V2 is a Text-to-Speech model that converts text into spoken audio using the ElevenLabs Flash V2 engine. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.